Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Loading…
Screen customers, monitor transactions, triage alerts, and manage investigations — all in one platform built for compliance teams who can't afford to miss a signal.
Every action is timestamped and attributed, audit-ready by default.
Transactions are evaluated against your rules the moment they happen.
From screening to STR filing, without switching tools.
Weightages, severity bands, and rules tuned to your own risk policy.
A single platform covering the full anti-money-laundering lifecycle, not a patchwork of point tools.
Match customers against sanctions, PEP, and adverse media lists with configurable, explainable scoring — Watchlist Search for ad-hoc lookups, Batch and Delta Screening for ongoing coverage.
Detect structuring, unusual transfers, and rapid movement with typologies and variables you build, test in Shadow mode, and publish yourself.
Every alert has a clear path to a case, a disposition, and — where needed — a filed STR, with the full lifecycle timestamped for audit.
My Queue and All Alerts give analysts, supervisors, and MLROs exactly the visibility their role needs — nothing more.
Alert Triggered → Investigator Review → Findings Documented → Disposition → MLRO Approval → Audit Record — the same lifecycle, every time.
Agentic Workflows pre-assembles screening history, transaction patterns, and prior cases into a draft summary — the analyst still makes the call.
From the first record ingested to the filed report — and back into tuning. Select any stage to jump to its guide.
Batch Ingestion loads Customers, Accounts and Transactions on a schedule; Watchlist Ingestion keeps LSEG and internal lists current.
Data Ingestion 2Customer 360 holds one profile per customer — KYC level, risk tier, PEP flag, accounts, activity and history.
Customer 360Watchlist Search, Manual, Batch and Delta Screening match customers against sanctions and PEP lists using weighted scoring.
Name Screening 4Typologies built from variables run on schedules — in Shadow first, then Published — to catch structuring and unusual activity.
Transaction MonitoringEvery hit becomes an alert with a severity band, an SLA deadline and an AI summary for a first read.
Alerts 6True Match → STRAlerts merge into a case. Analysts use Timeline & Notes and Case Copilot, then close as False Match or escalate as True Match.
CasesWhere every investigation, alert, and configuration decision lives — matching the real product's own nesting: Cases (with Timeline & Notes and the Case Copilot assistant), Alerts and Alert Details with AI summaries, and Config (Case Creation & Assignment, Alert Assignment, and Agentic Workflows).
ExploreEvery customer's profile in one record — KYC details, risk score, and full screening history. The single source of truth other modules (Case Manager, Name Screening) read from and write back to.
ExploreOne row per filed Suspicious Transaction Report, linking back to the originating case and its transactions — plus the filter, export, and share views supervisors and regulators use on top of the same data.
ExploreFour ways in — Watchlist Search, Manual Screening, scheduled Batch runs, and Delta Screening for ongoing customers — with the matching weightages and severity bands behind every hit set once in its own Configuration area.
ExploreTypologies (rules) built from reusable Variables evaluate every transaction against your thresholds, versioned through Draft, Shadow, and Published states. Group By, Look Back, and Suppression shape exactly when — and how often — an alert should fire.
ExploreEvery detection pattern available for a Typology, in one place — Anomaly Detection, Structuring, Cardinality, Denylist, Graph-Based, and pre-built Fraud/ACH/Check templates — plus recommended rule packs by industry.
ExploreScheduled batch ingestion of Customers, Accounts and Transactions, and the history of LSEG and internal watchlist files — with a clear job history so you can see exactly when data last landed and whether it validated cleanly.
ExplorePlatform-wide settings in one place — your own profile, who can do what (Roles & Permissions), and quick links into every configuration screen.
ExploreThe platform's hierarchy templates — search them, check their status, inspect one, or add a new template to define an organizational structure.
ExploreActivity configurations: each activity's SLA and warning point, approval count, and the maker and checker permissions that control it.
ExploreNo install, no setup wizard — just log in and start where your team already works.
Explore the platform →Your platform URL, your credentials, verified with an OTP step.
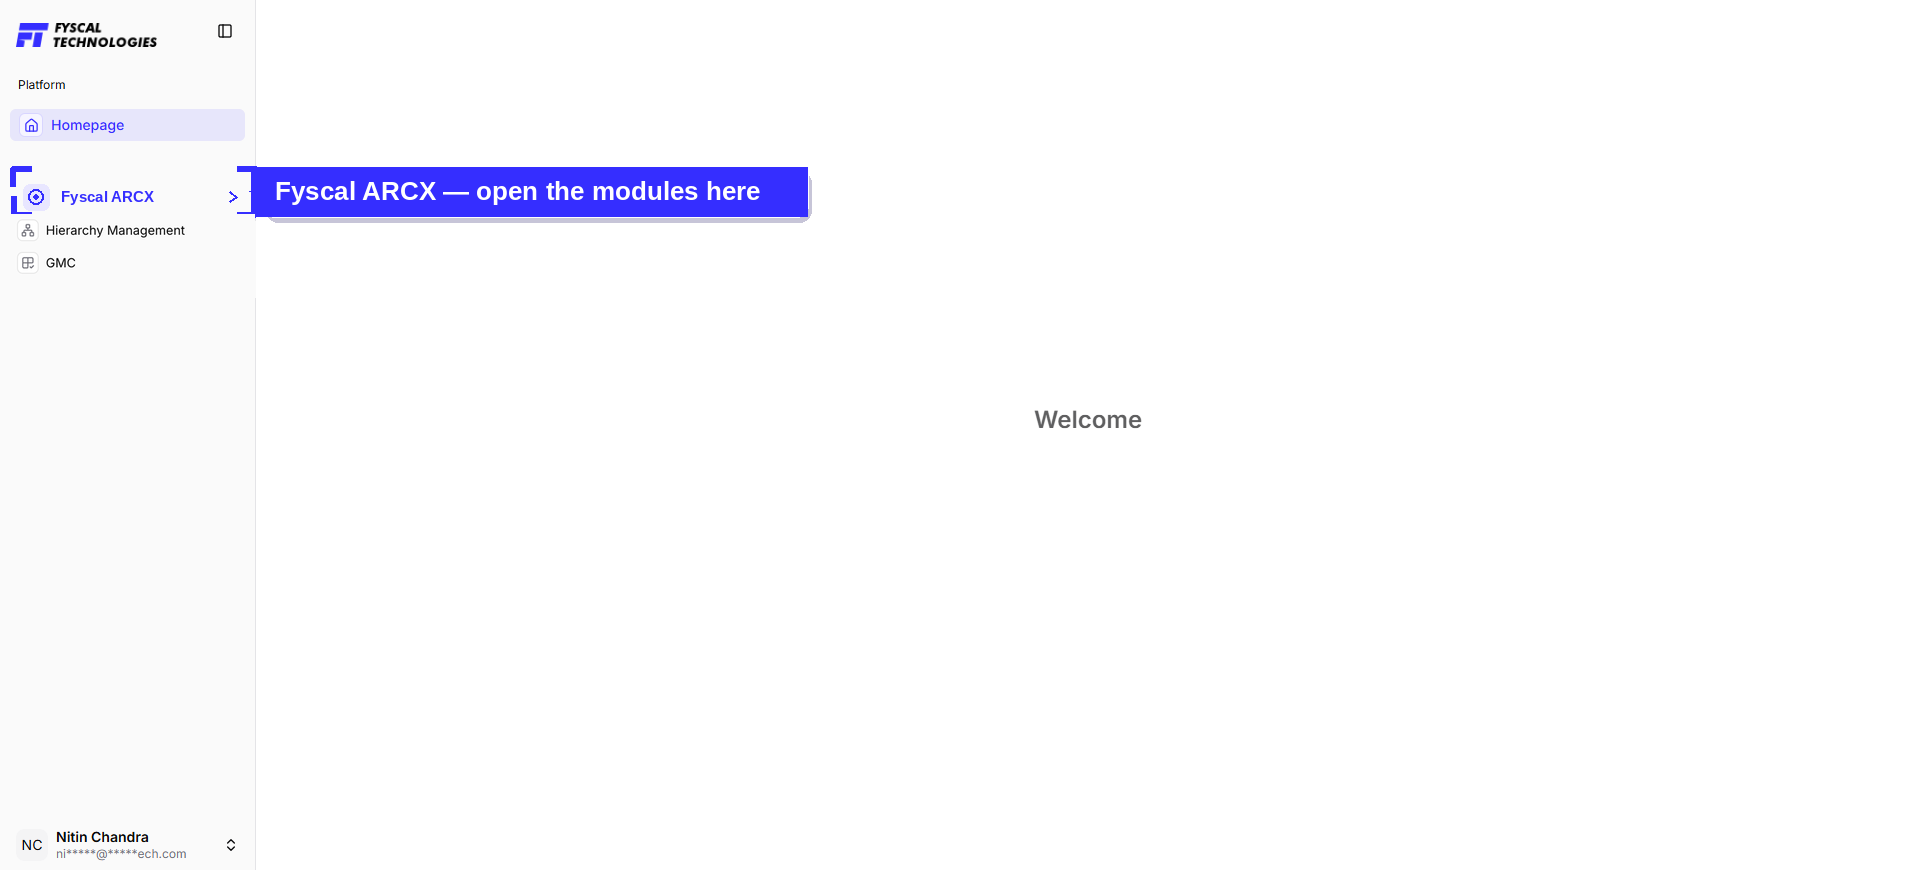
Everything you need is one click away in the sidebar.
Run a screening check or watch alerts arrive from active rules.
Turn a confirmed hit into a case, and close it with a clear disposition.
Every module above, documented step by step.
Fyscal ARCX is an Anti-Money Laundering (AML) platform that helps financial institutions detect suspicious activity, screen customers against regulatory watchlists, monitor transactions, manage investigations, and comply with AML/CTF regulations. This page is the fastest way to get oriented — how the platform fits together, how to log in, and exactly where to go next based on your role.
Every module in this guide is one stage of a single pipeline. Data comes in, customers are screened and transactions monitored, hits become alerts, alerts become cases, and a confirmed case ends in a filed report — while every outcome feeds back into how detection is tuned. Select any stage to jump to its chapter.
Batch Ingestion loads Customers, Accounts and Transactions on a schedule; Watchlist Ingestion keeps LSEG and internal lists current.
Data Ingestion 2Customer 360 holds one profile per customer — KYC level, risk tier, PEP flag, accounts, activity and history.
Customer 360Watchlist Search, Manual, Batch and Delta Screening match customers against sanctions and PEP lists using weighted scoring.
Name Screening 4Typologies built from variables run on schedules — in Shadow first, then Published — to catch structuring and unusual activity.
Transaction MonitoringEvery hit becomes an alert with a severity band, an SLA deadline and an AI summary for a first read.
Alerts 6True Match → STRAlerts merge into a case. Analysts use Timeline & Notes and Case Copilot, then close as False Match or escalate as True Match.
CasesCustomer 360 is the shared record every screening hit and case reads from, and Case Manager → Config is where the rules for turning alerts into cases (and who they are assigned to) are set. Follow the numbered stages to read the guide in the order the platform actually works.
Fyscal ARCX is built around a core set of objectives:
Use Forgot Password if login fails after verifying credentials.
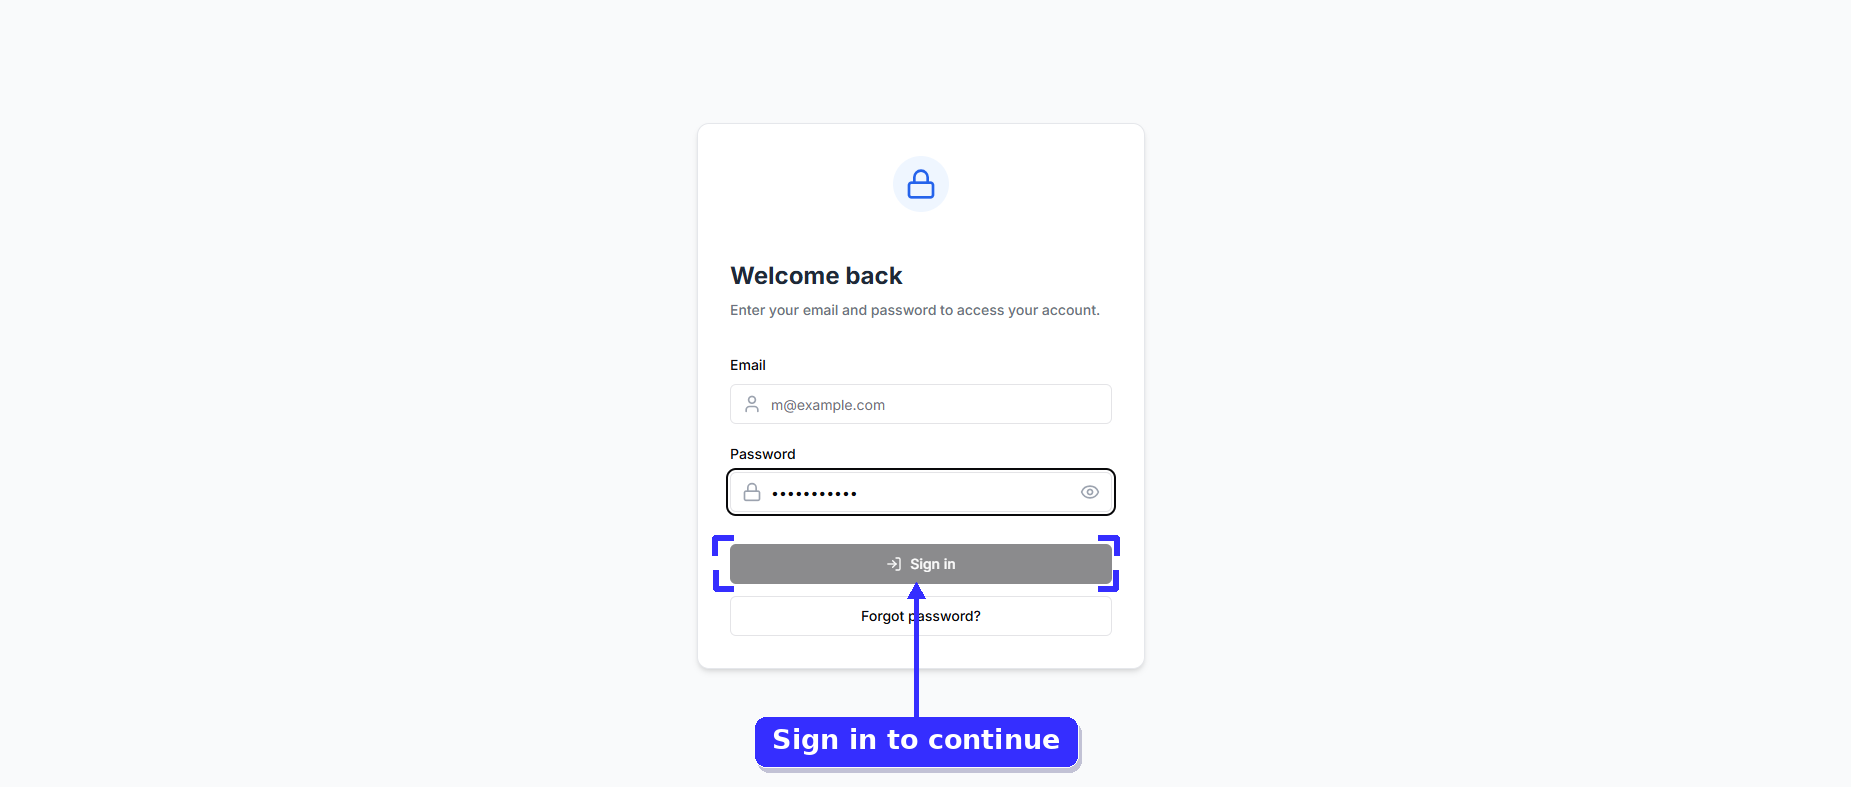
Secure authentication is the first line of defense for sensitive AML data, and every login is tied to a user account — supporting audit requirements by recording who created, modified, or closed an AML investigation.
After entering valid credentials, the user is redirected to the Homepage. This is the central workspace for compliance teams, giving quick access to every AML module from one place and reducing time spent switching between investigations, screening, and monitoring activities.
Every screen in Fyscal ARCX is gated by the logged-in user's role — what a user sees on login, which module tabs they can open, and which actions are available to them all follow directly from the role assigned in Admin → Roles & Permissions.
| Access area | Compliance Analyst | Compliance Officer / MLRO | Configuration Admin | IT / Platform Admin |
|---|---|---|---|---|
| Case Manager — Cases / Alerts, My Queue | Yes | Yes | — | — |
| Case Manager — All Cases / All Alerts | — | Yes | — | — |
| Approve STR filing | — | Yes | — | — |
| Name Screening / Alert Configuration (edit) | — | — | Yes | — |
| Transaction Monitoring rules & variables (edit) | — | — | Yes | — |
| User Management & Data Ingestion schedules | — | — | — | Yes |
The full guide covers every module in depth — but you don't need to read it front to back. Start with the pages that match what you'll actually be doing day to day:
| Your role | Read these first |
|---|---|
| Compliance Analyst | Case Manager → Cases → Alerts → Name Screening → Watchlist Search → Case Lifecycle |
| Compliance Officer / MLRO | Cases (All Cases view) → Case Lifecycle → Filing an STR → STR Listing |
| AML Configuration Admin | Name Screening → Configuration → Transaction Monitoring → Typology → Typology Library → Case Manager → Config |
| IT / Platform Admin | Data Ingestion → Admin → Hierarchy Management |
After logging in, users access every module from the Fyscal ARCX menu in the sidebar. This guide follows that same real nesting — Case Manager is one module covering Cases, Alerts, and Config together, matching how they're actually grouped in the product rather than treating them as separate tools:
Which of these a given user actually sees depends on their assigned role — see Roles & Access above for how access is scoped per module.
The workspace where every investigation lives. When an alert from Name Screening or Transaction Monitoring needs a human look, it becomes a case here — either automatically, per the rules set in Config → Case Creation & Assignment, or manually — and every action taken on it, from first review to final sign-off, is recorded for audit.
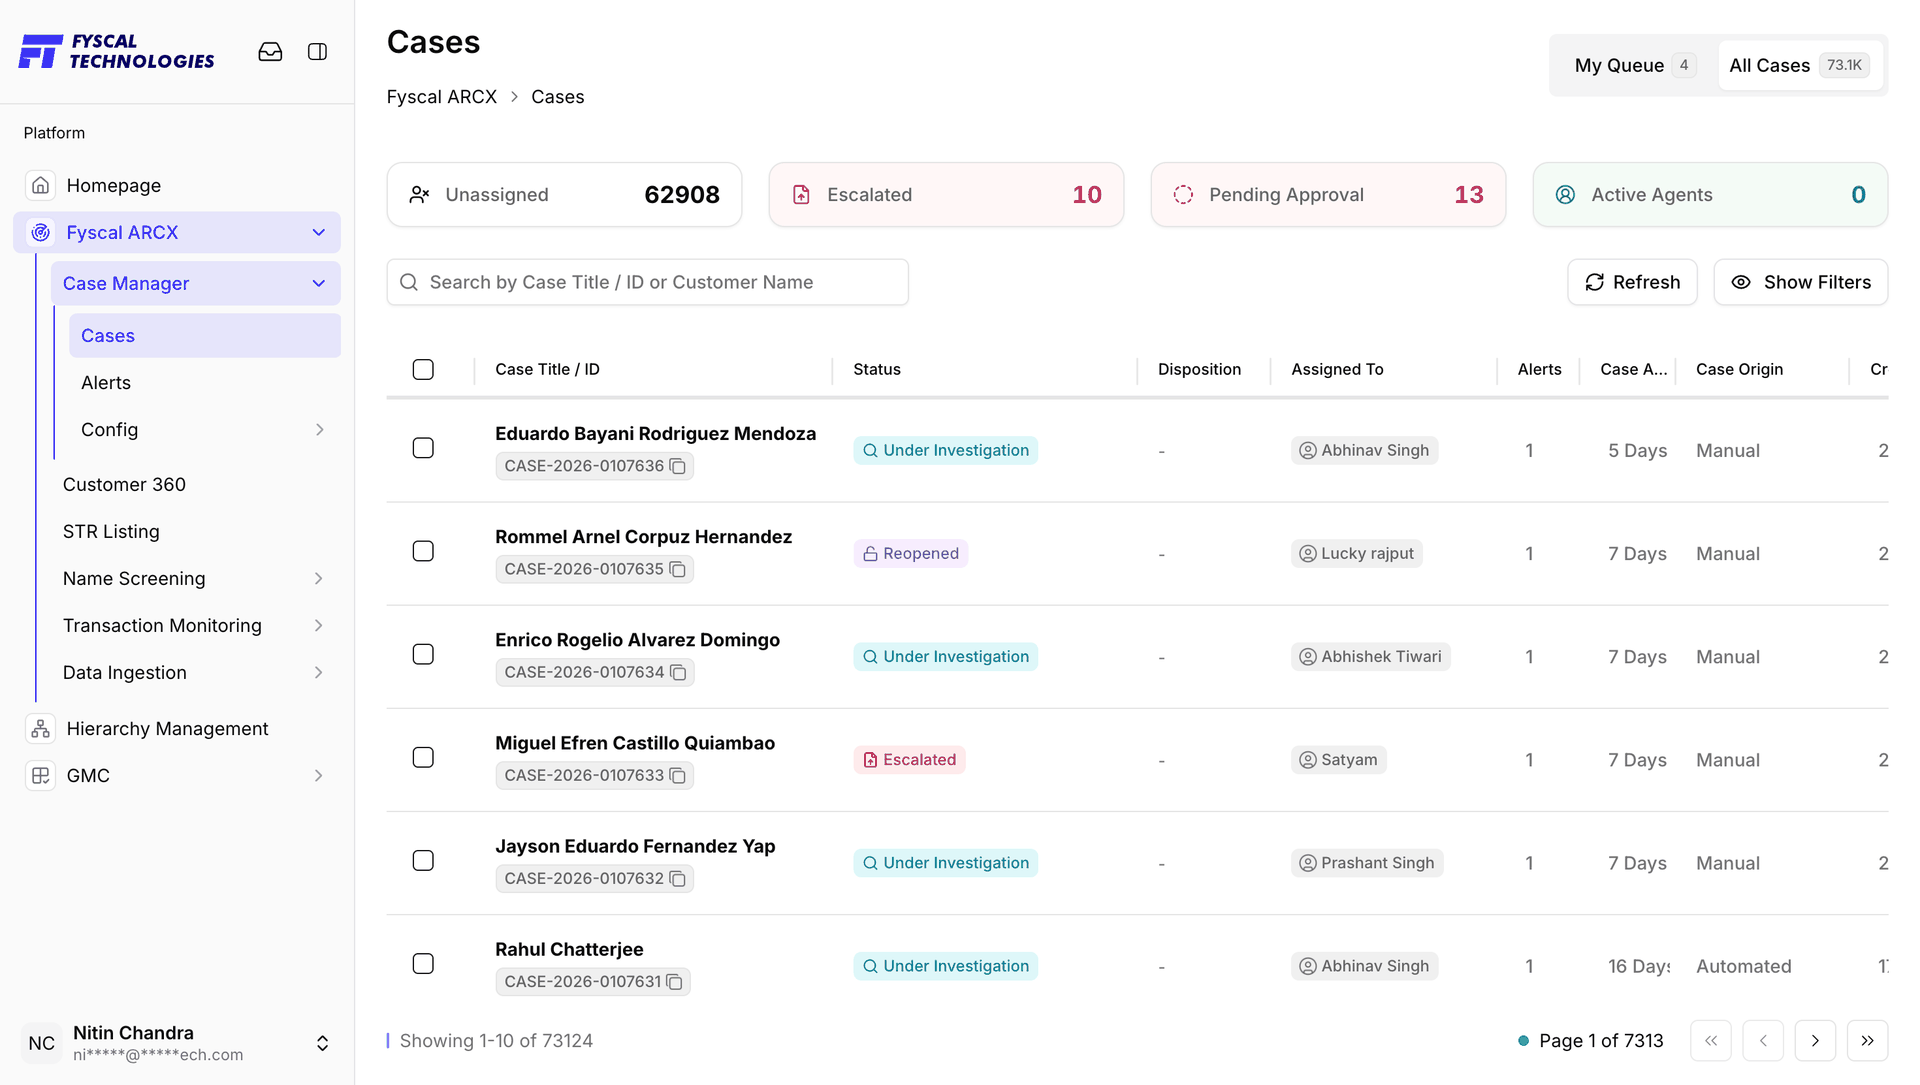
Cases are organized into two views, switchable from tabs at the top of the screen, each with a live count: My Queue (only the cases assigned to the logged-in analyst) and All Cases (every case across the institution, for supervisors and MLROs who need full visibility). Getting from a raw case list to the exact case you need is a matter of combining the right filters — walked through step by step below.
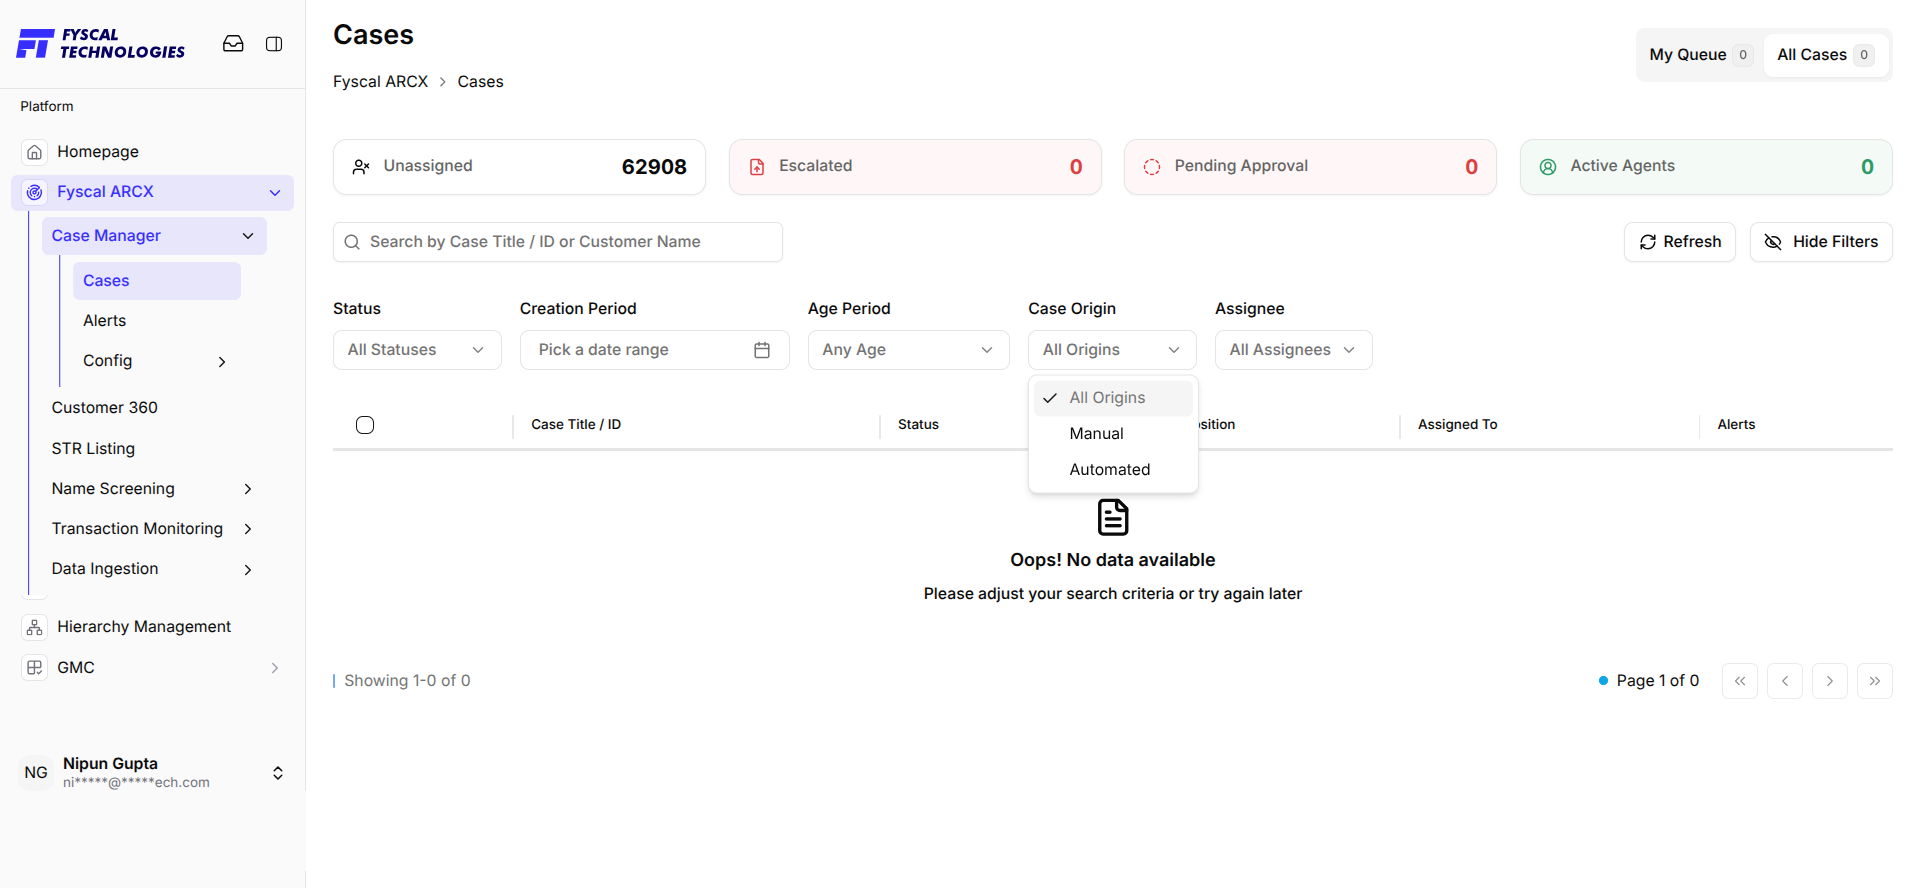
On All Cases, a stats bar above the list shows institution-wide Unassigned, Escalated, Pending Approval and Active Agents counts. Each row shows the Case Title / ID, Status (for example Under Investigation, Reopened or Escalated), Disposition, Assigned To, the number of Alerts, Case Age, Case Origin (Manual or Automated) and when it was created. The checkbox column selects rows, and the search bar finds a case by Case Title, Case ID or Customer Name.
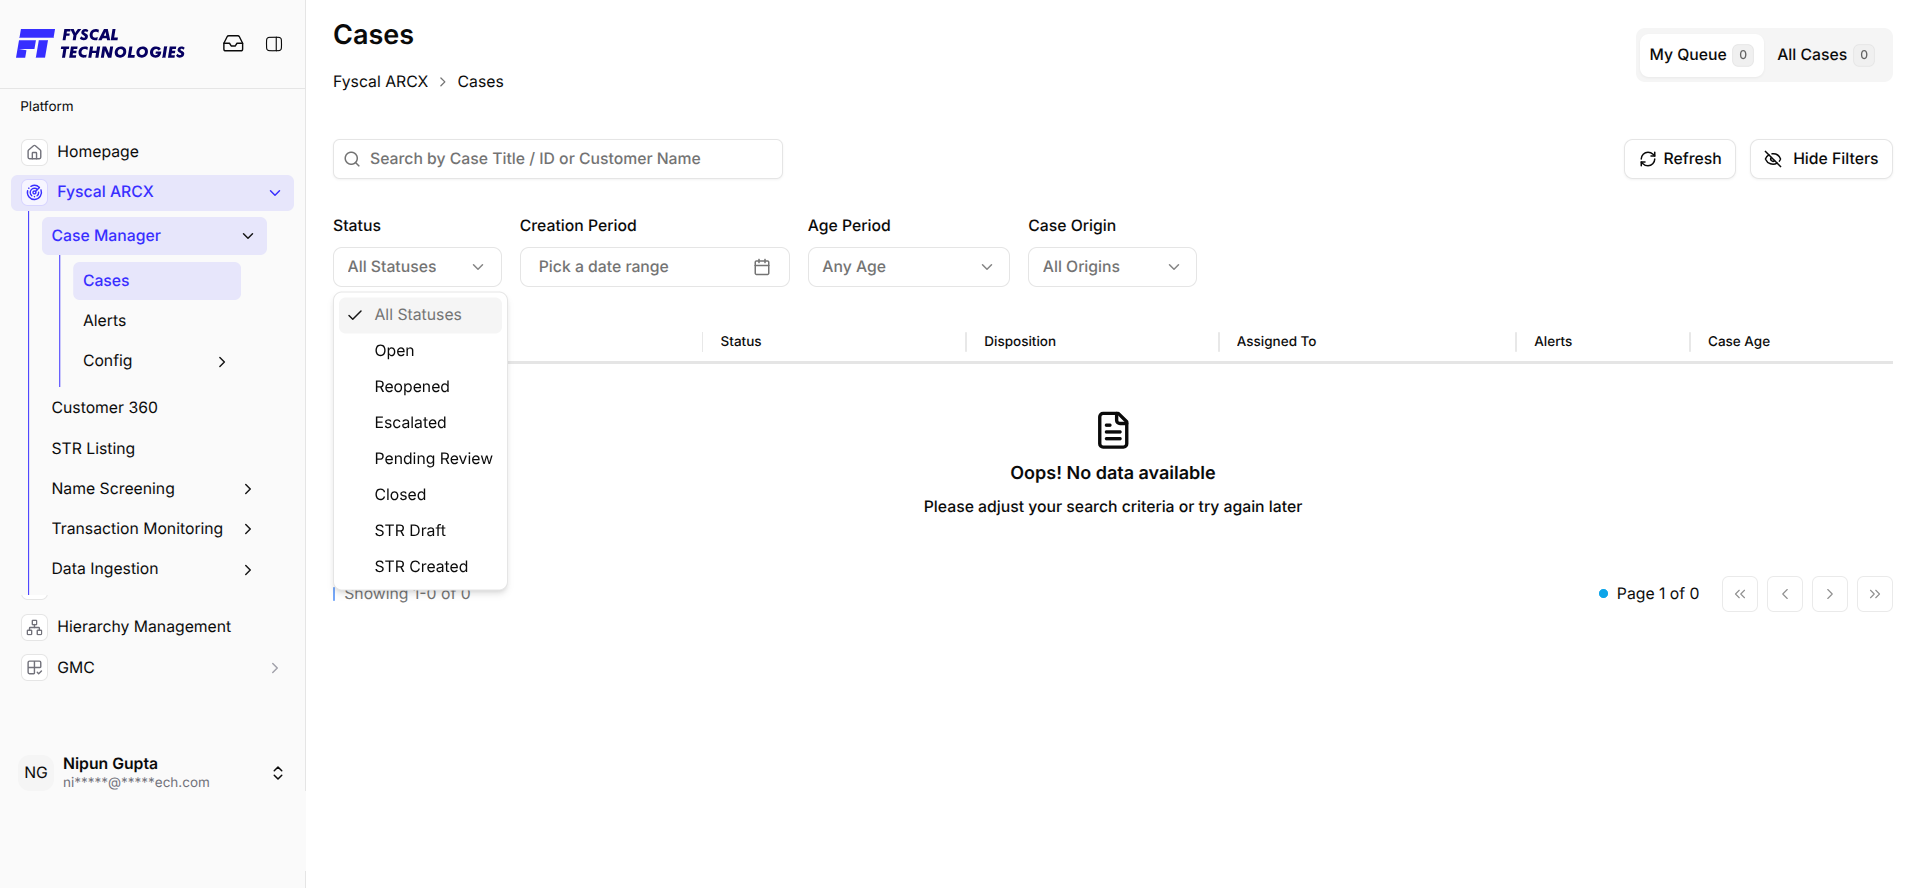
Too many cases to scan? Narrow the list with filters, starting with lifecycle stage.
The Status dropdown narrows the list to a specific stage of the case lifecycle — Open, Reopened, Escalated, Pending Review, Closed, STR Draft, or STR Created. Cases that are actively being worked show as Under Investigation in the list itself.
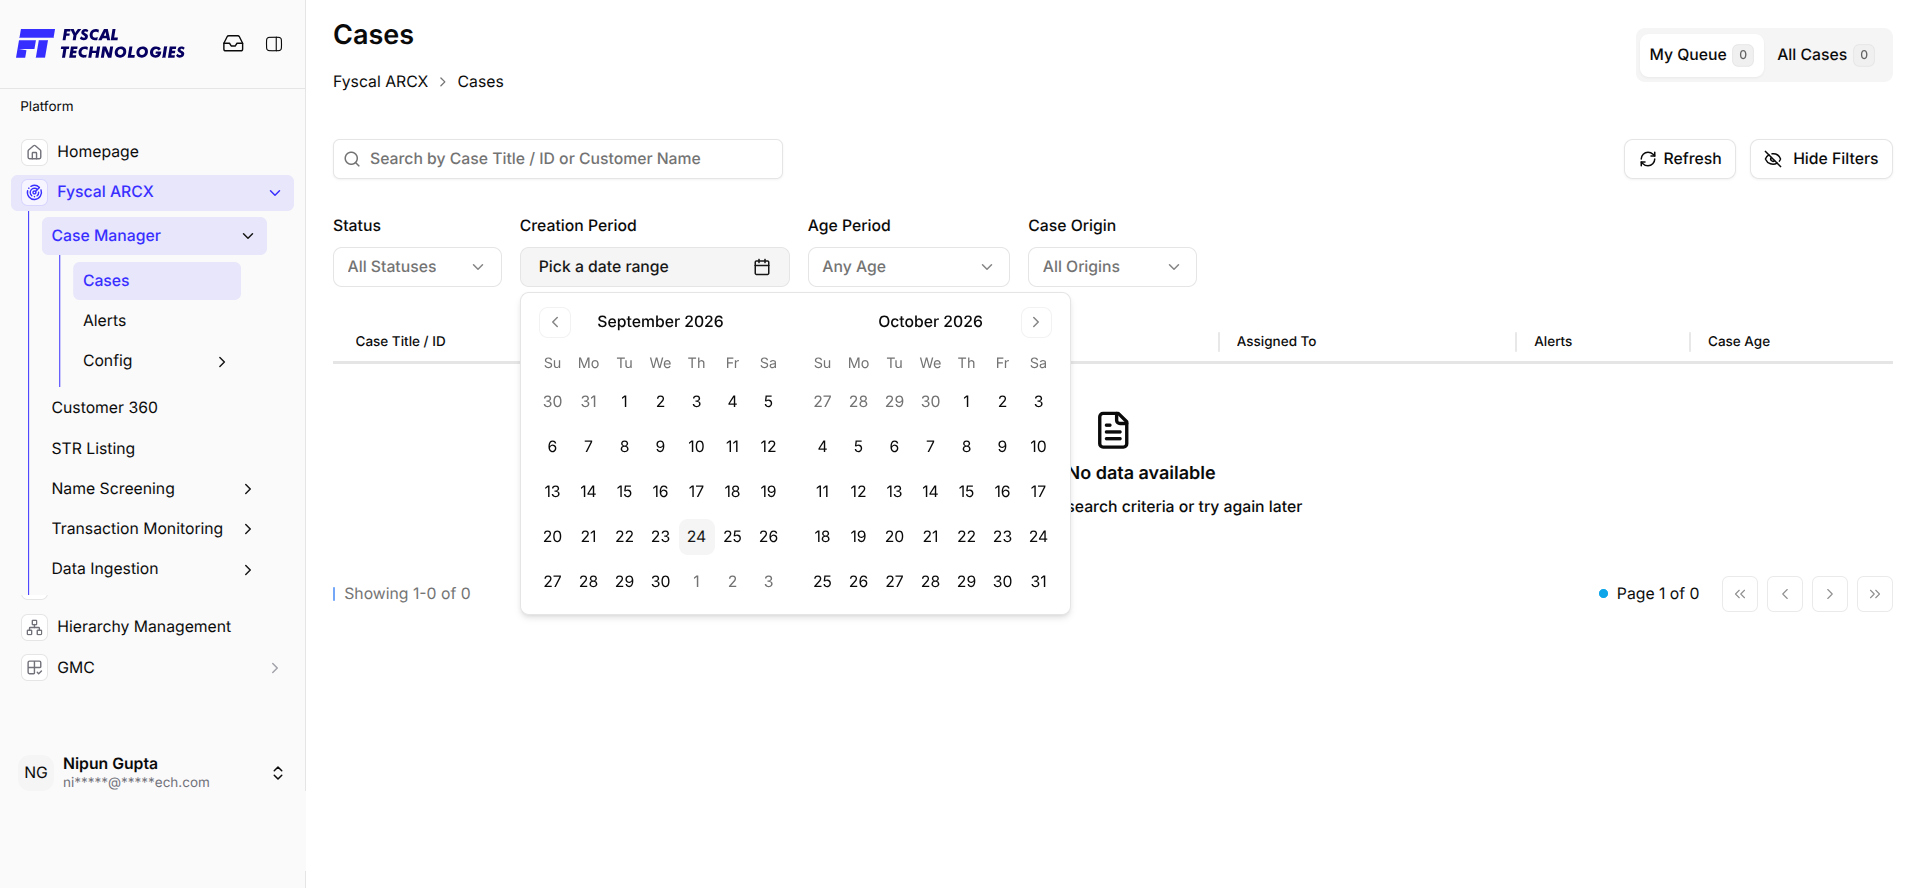
Know roughly when the case was opened instead? Filter by date.
Creation Period opens a two-month calendar picker so you can bound the search to a specific date range, useful for periodic reviews or reconstructing a specific week's activity.
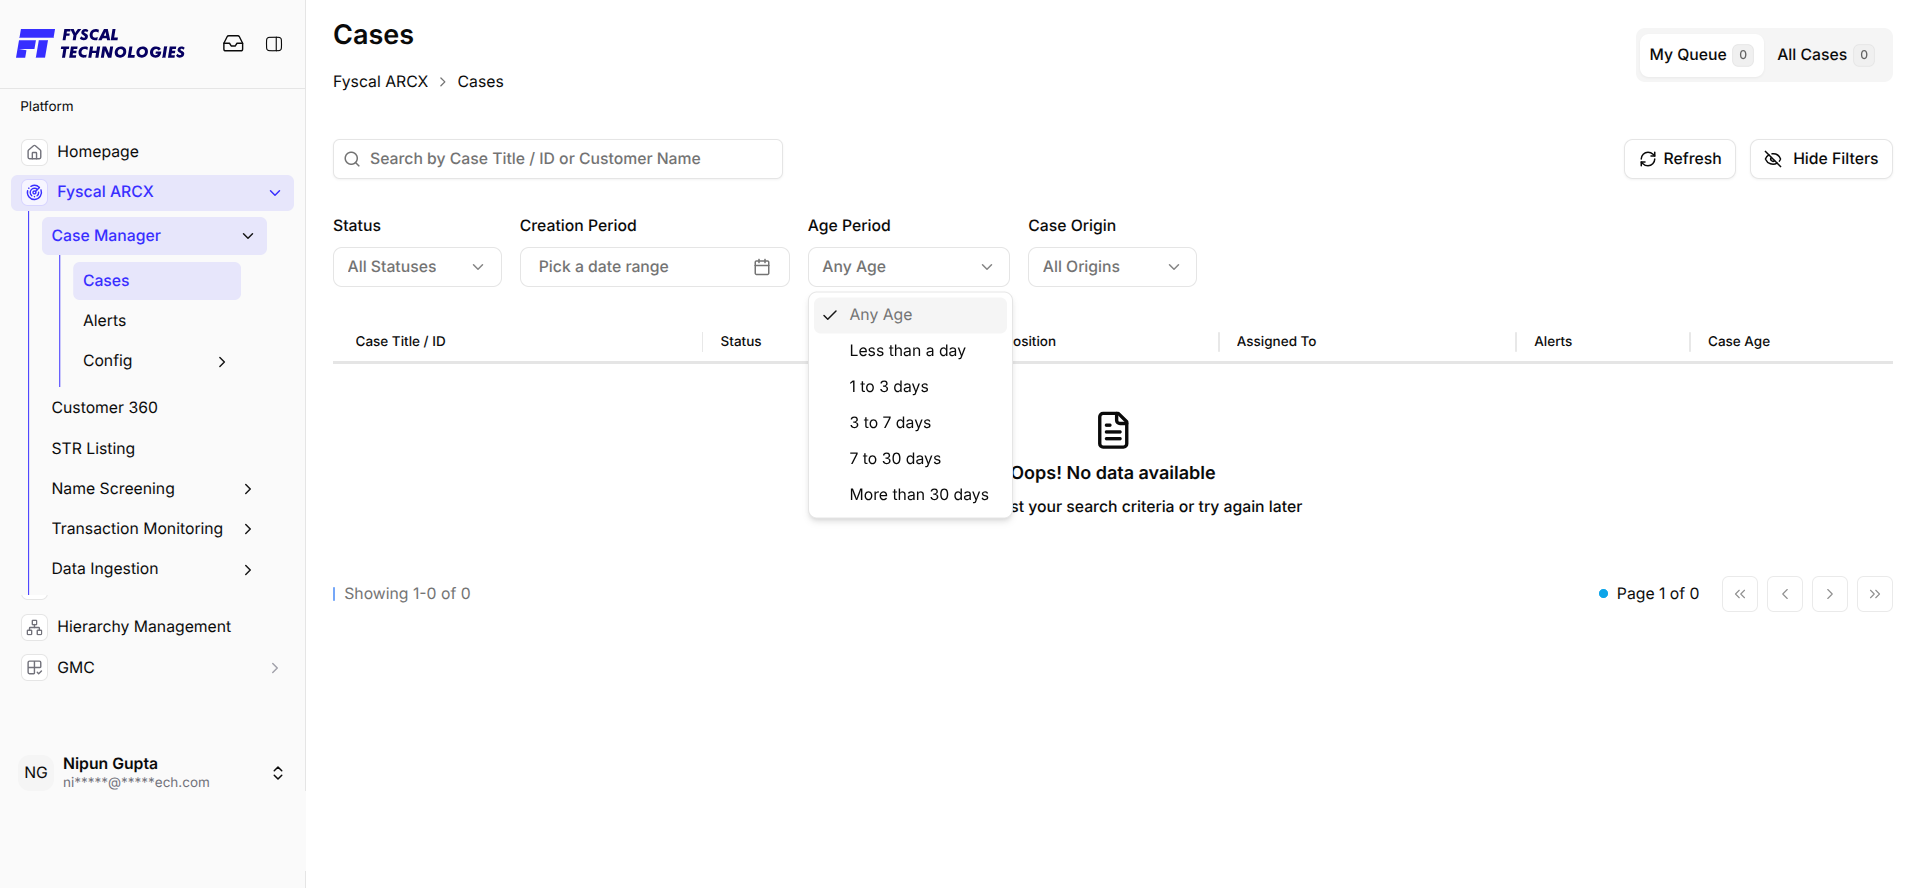
Care more about how long a case has been sitting open than when it started? That's Age Period.
Age Period buckets cases by how long they've been open — Less than a day, 1 to 3 days, 3 to 7, 7 to 30, or More than 30 days — the fastest way to surface cases at risk of breaching SLA.
One more useful split: whether a case was opened by a person or by a rule.
On All Cases, the Case Origin filter isolates cases opened Manually by an analyst versus Automated ones created by Case Creation & Assignment rules, and the Assignee filter shows one analyst's cases.
Filtered down to the case you need? Click its row to open the full investigation workspace.
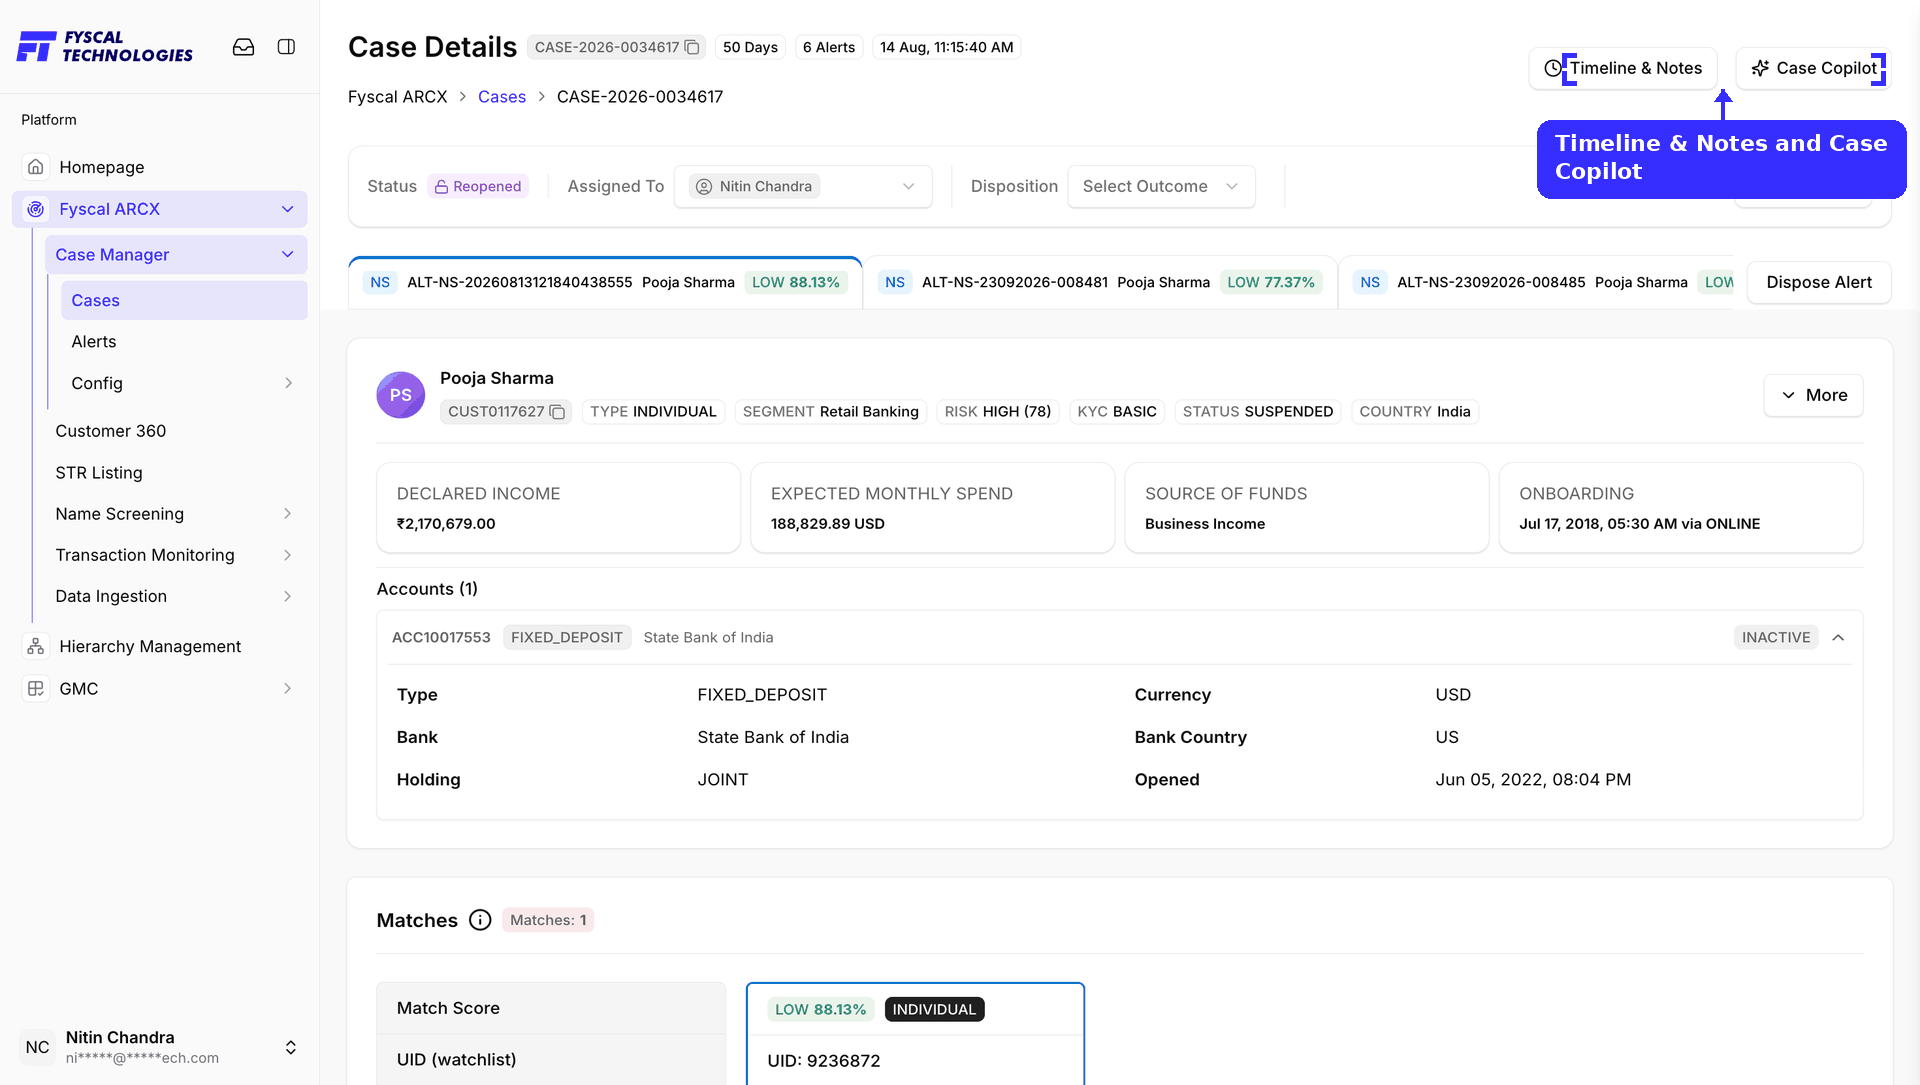
Clicking a row opens the case's dedicated Case Details screen rather than a simple pop-up. The header shows the case ID, how many days it has been open, how many alerts it holds, and when it was created, with two buttons at top right: Timeline & Notes and Case Copilot. Underneath, Status, Assigned To and Disposition sit beside Add Alerts, and each alert on the case appears as a tab in an alert strip — tagged NS (Name Screening) or TM (Transaction Monitoring), with the customer name and score — next to Dispose Alert. Below come the customer's profile and accounts, and a Matches panel comparing the screening hit against the customer field by field. From here an analyst can:
Timeline & Notes opens an Activity Timeline panel for the case. At the top, Add a note takes free text for the investigation, with Attach File for supporting documents. Below it, every event on the case is logged with who did it and when — alerts Linked to Case, a case Reopened, a Disposition Submitted (with the rationale code and rationale recorded), and the case being Created — and event entries expand to show the alert timeline or per-alert dispositions behind them.
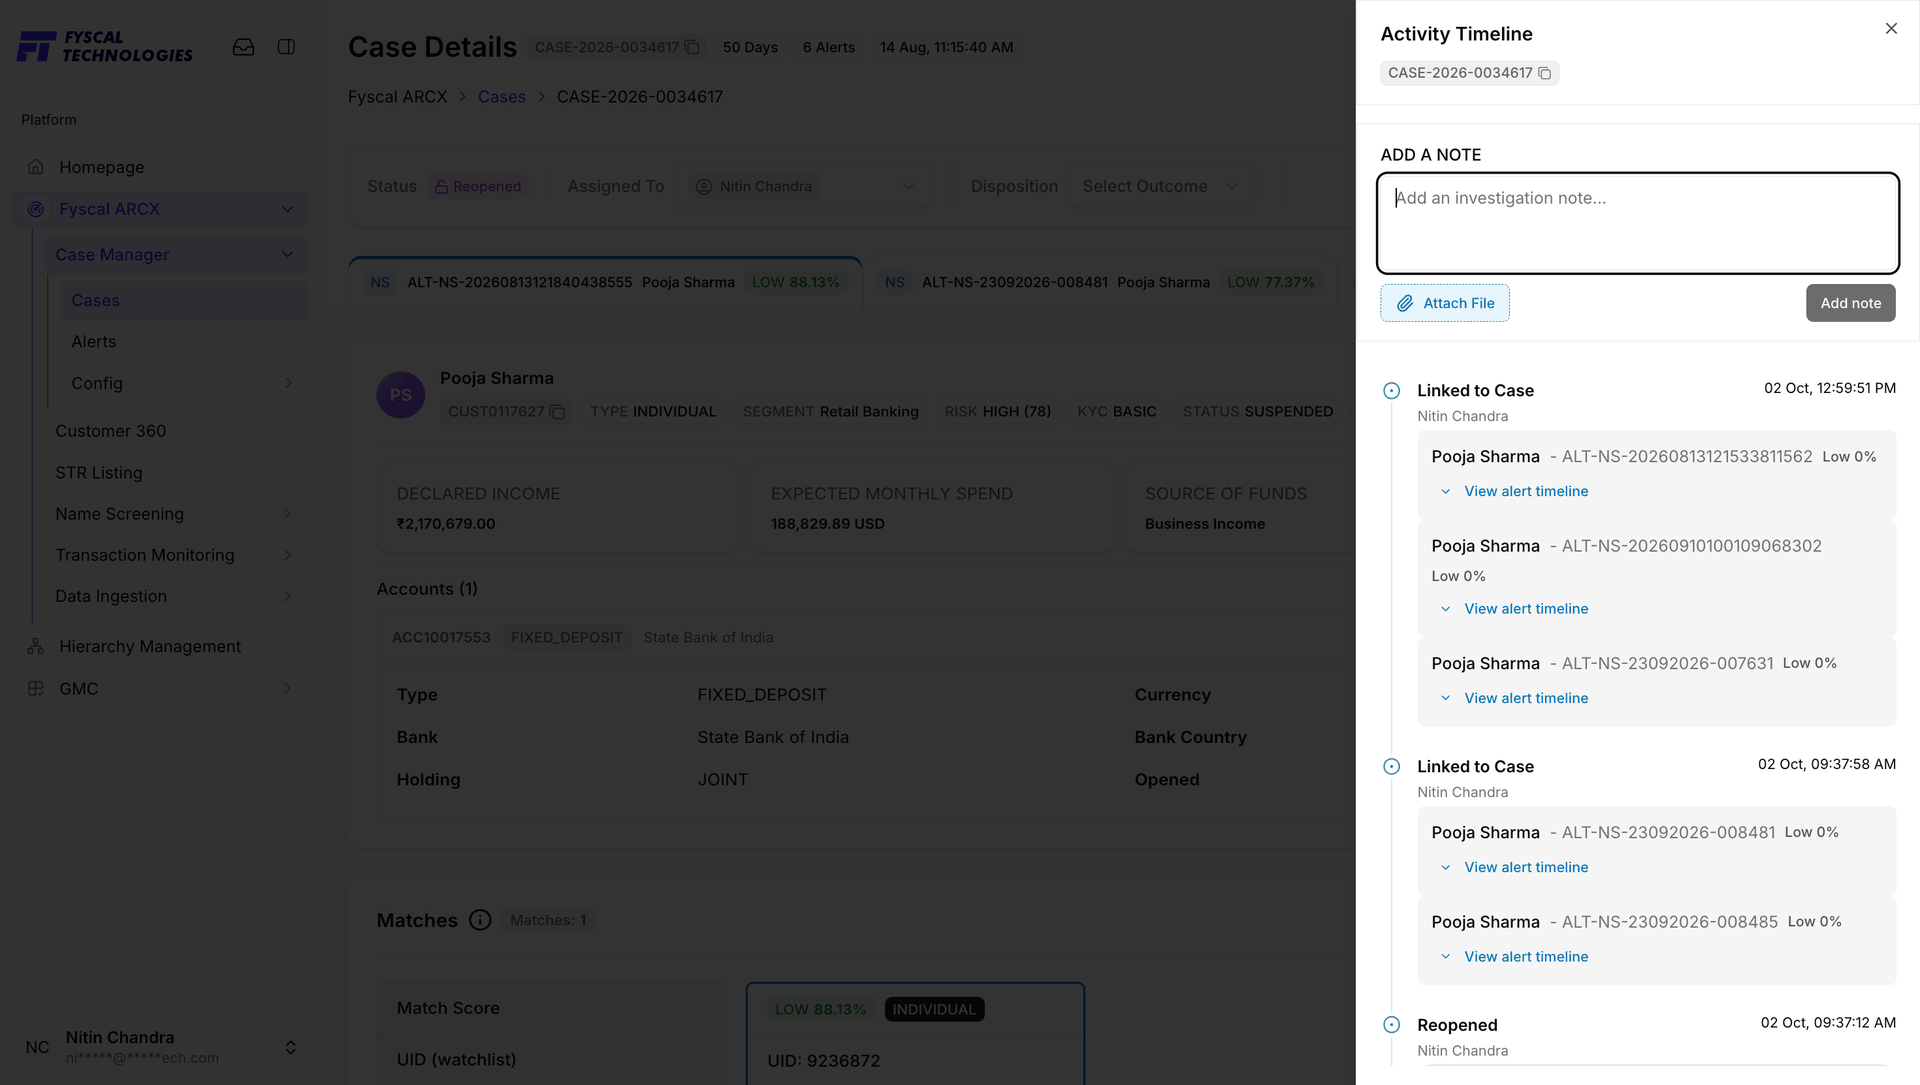
The panel scrolls, and each older event records what happened and why. In the example below, three events are visible:
previous_status the case came from (closed), the rationale typed when it was reopened ("reopen his case"), a count of the alerts that were reopened with it, and a link to each alert.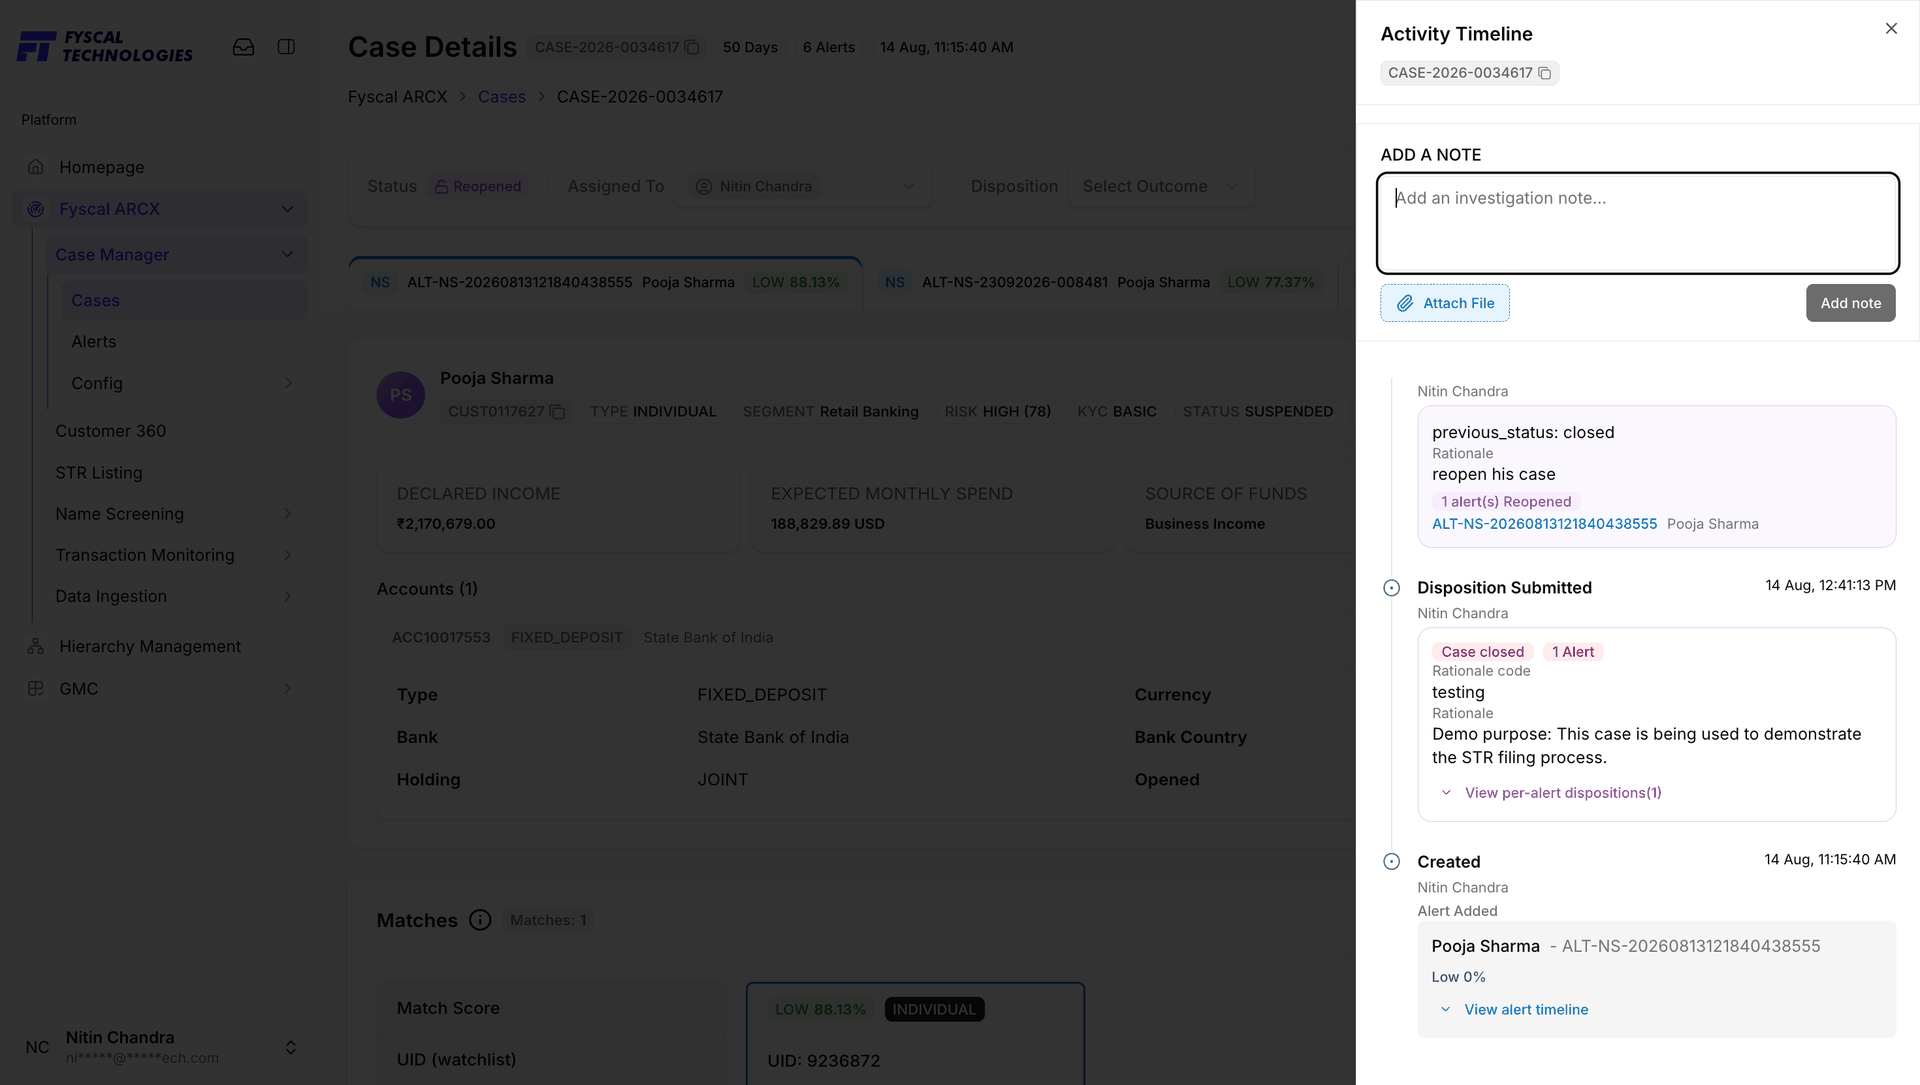
Because every status change, disposition and note lands here with a name and a timestamp, this panel is the quickest way to answer an auditor's question — who decided this, when, and on what basis? — without reopening each alert.
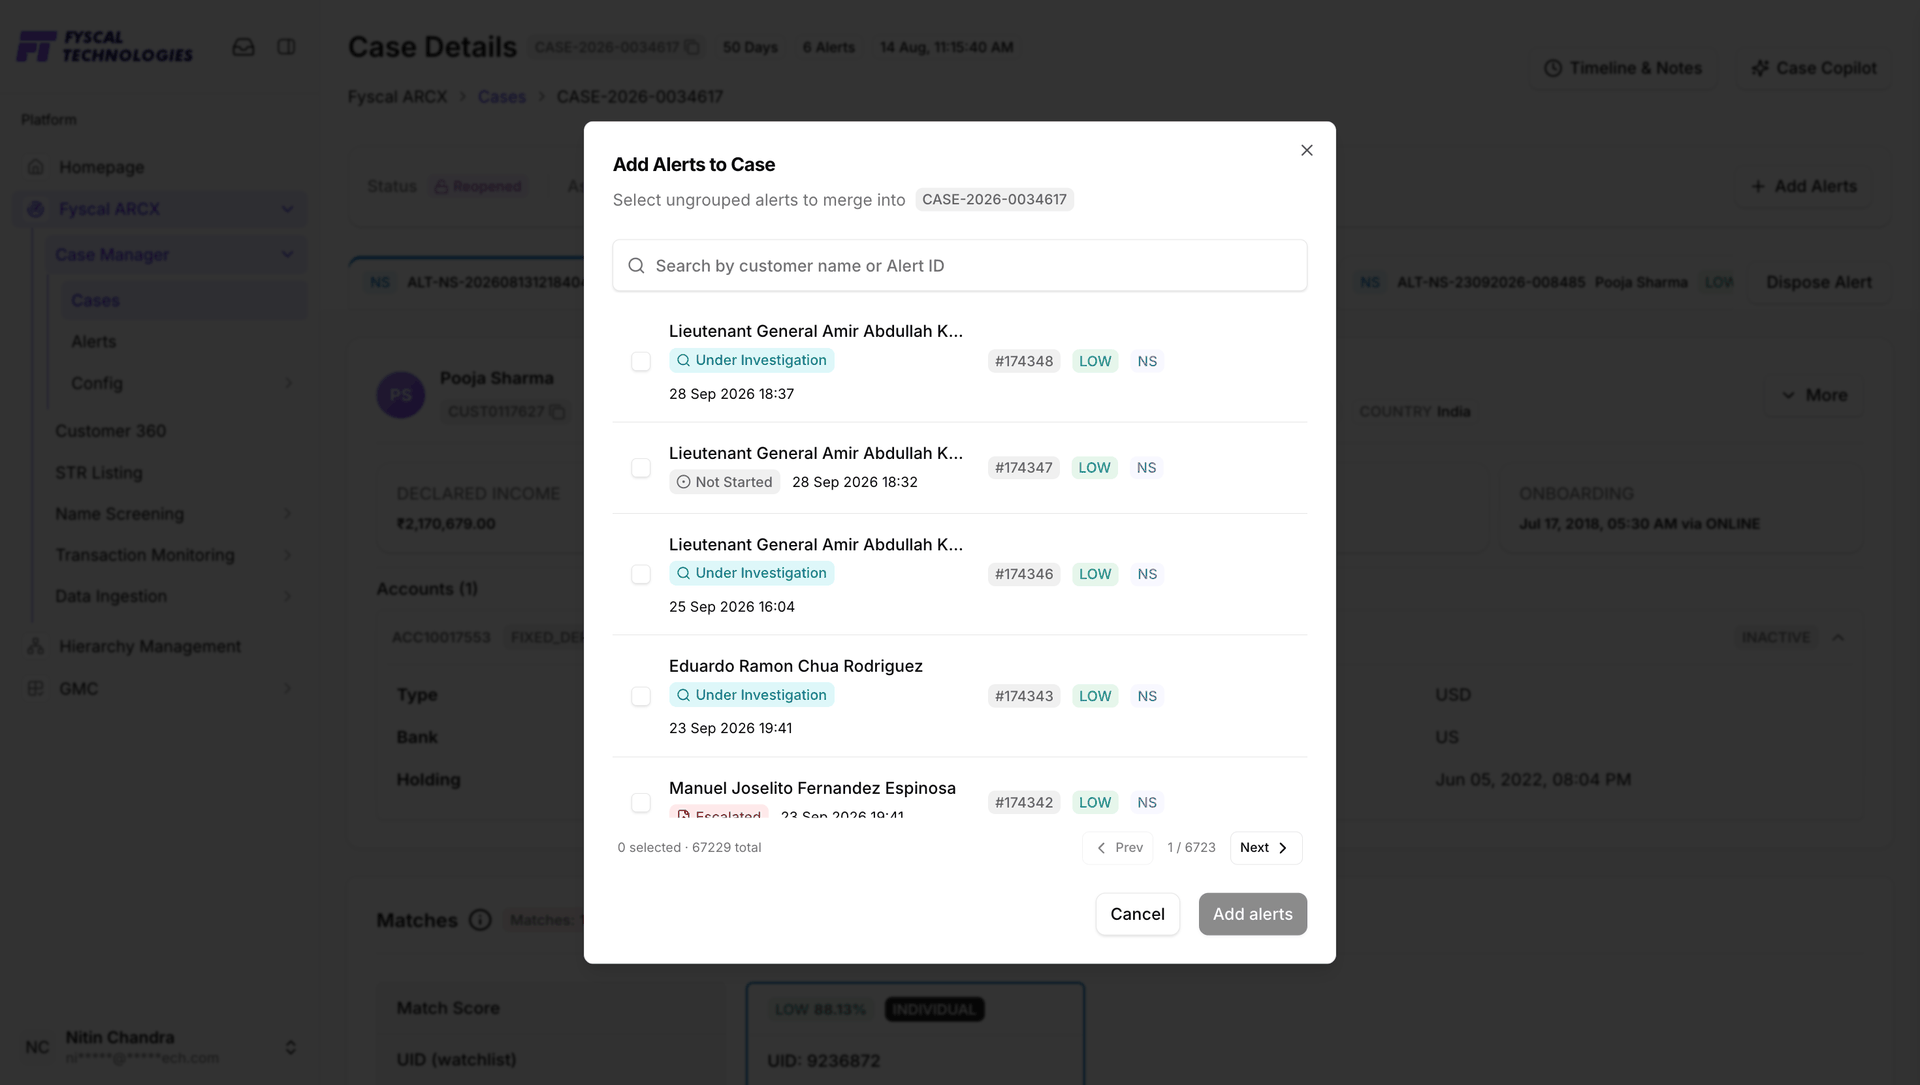
A case can grow to cover more than the alert(s) it opened with. Clicking Add Alerts on the case detail screen lets an analyst merge other ungrouped alerts on the same subject into the current case, rather than investigating each one separately:
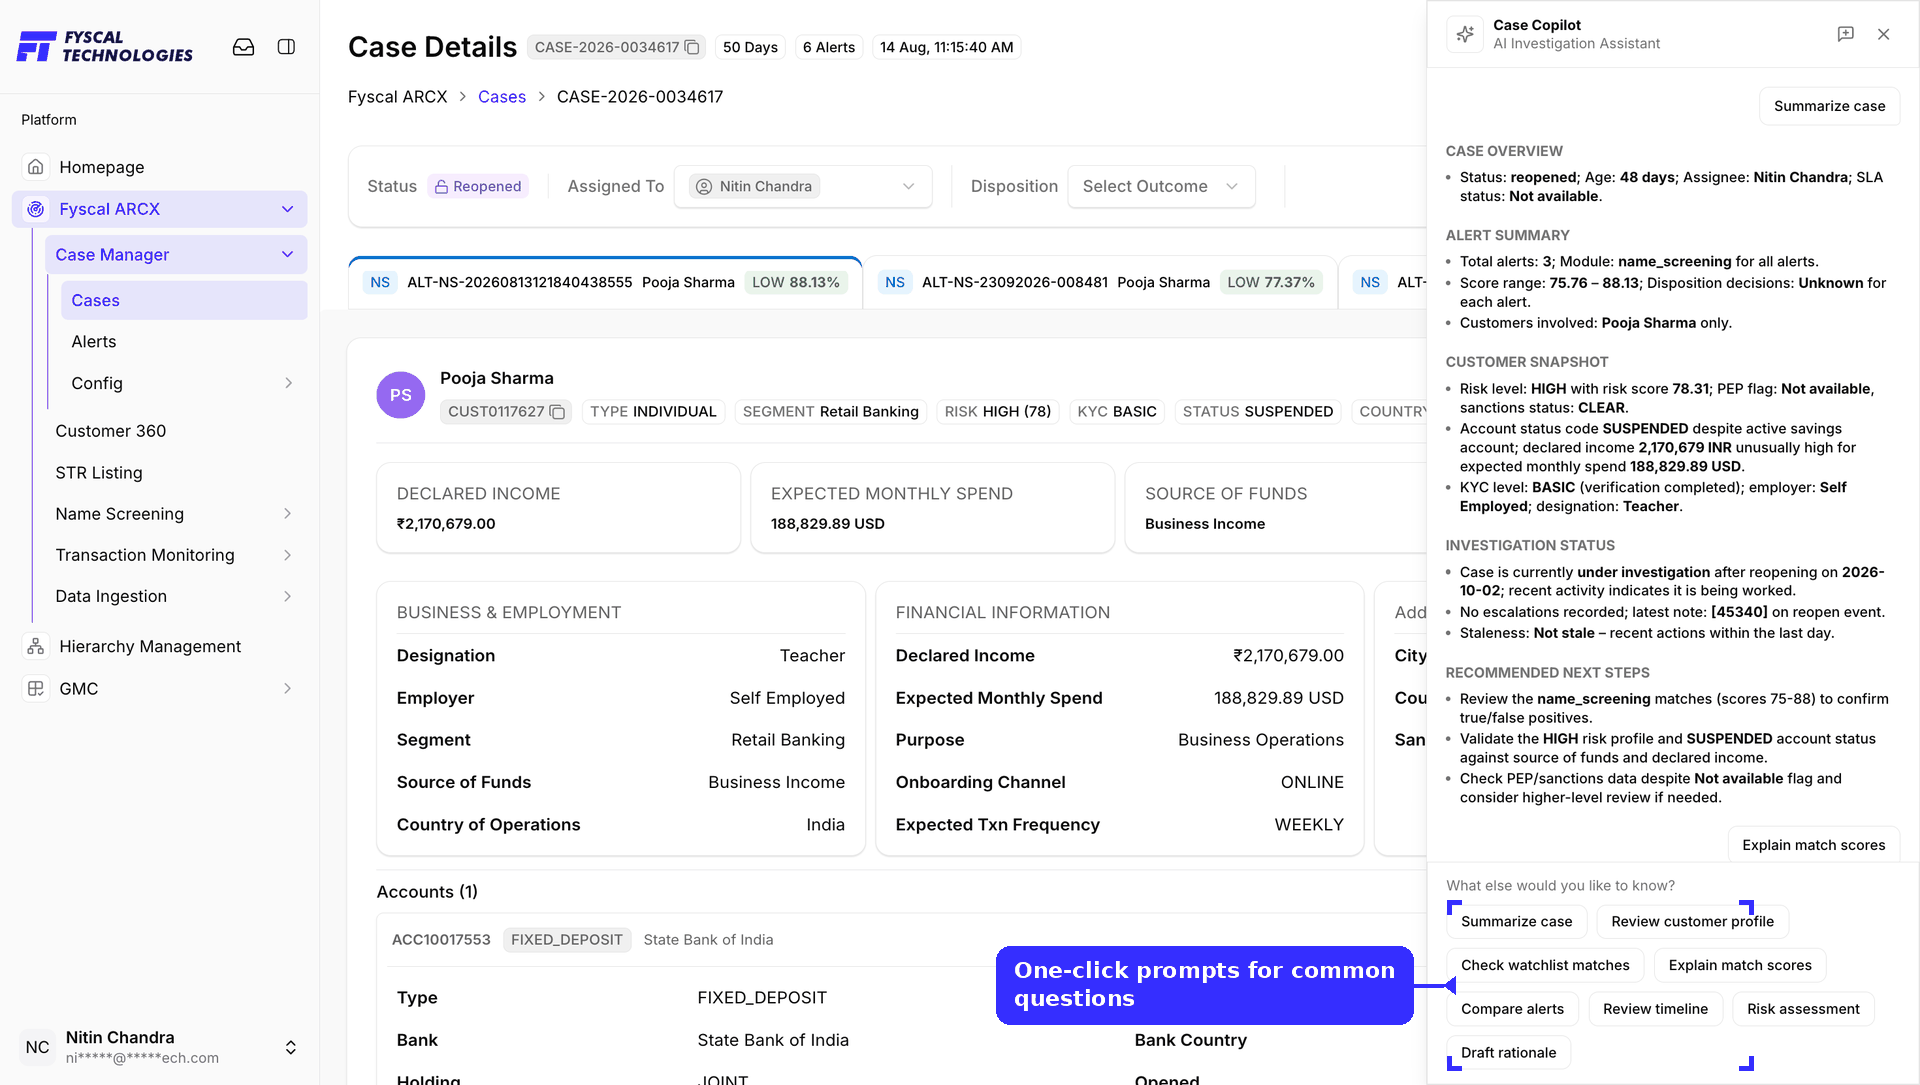
Case Copilot is an AI investigation assistant built into Case Details. Clicking the button opens a panel beside the case; Summarize case produces a structured summary in five sections — Case Overview (status, age, assignee, SLA), Alert Summary (total alerts, modules, score range, dispositions), Customer Snapshot (risk level, PEP flag, account status, KYC), Investigation Status, and Recommended Next Steps. Below the summary, one-click prompts — Review customer profile, Check watchlist matches, Explain match scores, Compare alerts, Review timeline, Risk assessment, Draft rationale — ask a follow-up about the same case.
Below the customer profile, the case detail screen organizes supporting evidence into four tabs:
Every hit generated anywhere in the platform — a name-screening match, a transaction-monitoring rule firing — lands here first, ranked by severity and SLA deadline, before it ever becomes a case. Alerts are organized into two tabs: My Queue (alerts assigned to the logged-in user) and All Alerts (the full institution-wide alert volume — this can run into the hundreds of thousands).
The default view lists the alerts assigned to you — Customer Name and Alert ID, the Module that raised it, its Score, Status, Disposition, SLA Deadline, who it is Assigned To, and when it was created. Filters for Status, Module, SLA and Score sit above the list.
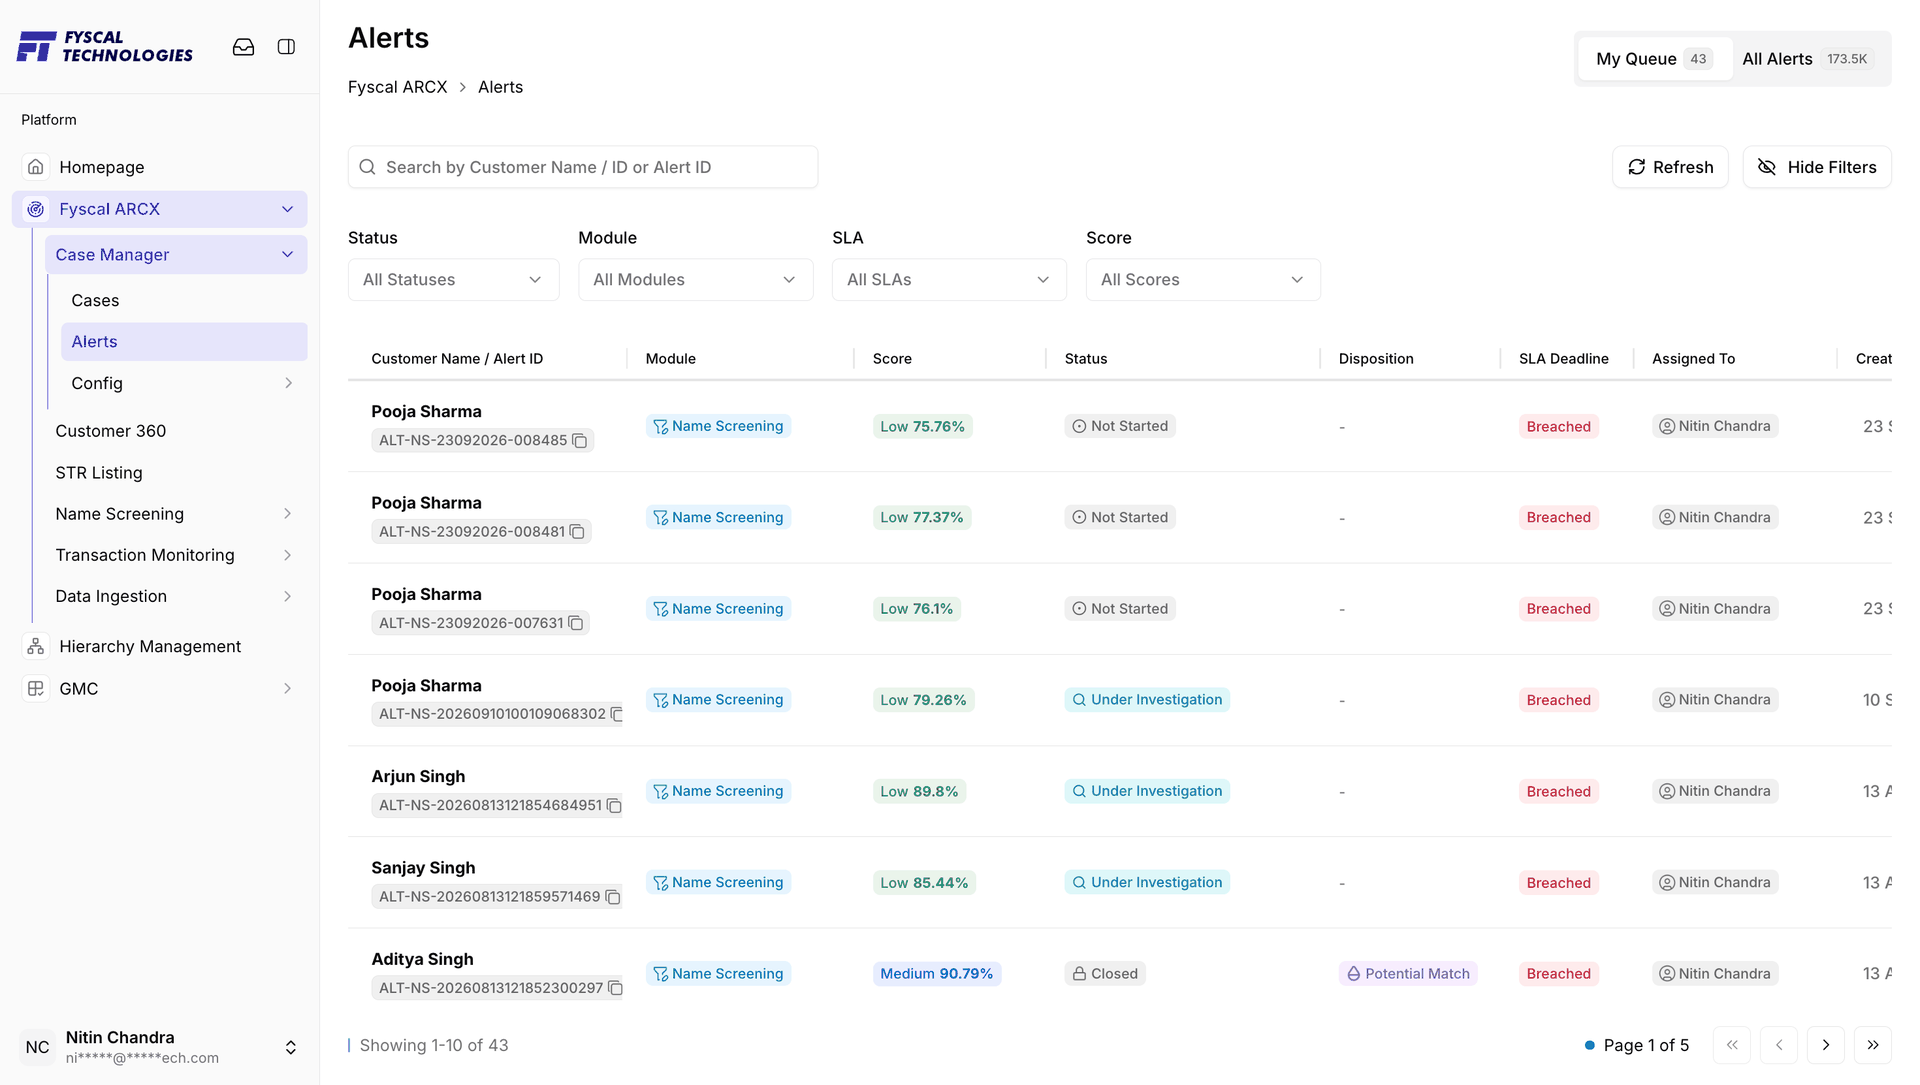
Need the institution-wide picture? Switch to All Alerts.
All Alerts adds a stats bar — Unassigned, Escalated, SLA Breached and Active Agents — and shows every alert, not just yours. Click Show Filters to reveal the filter bar.
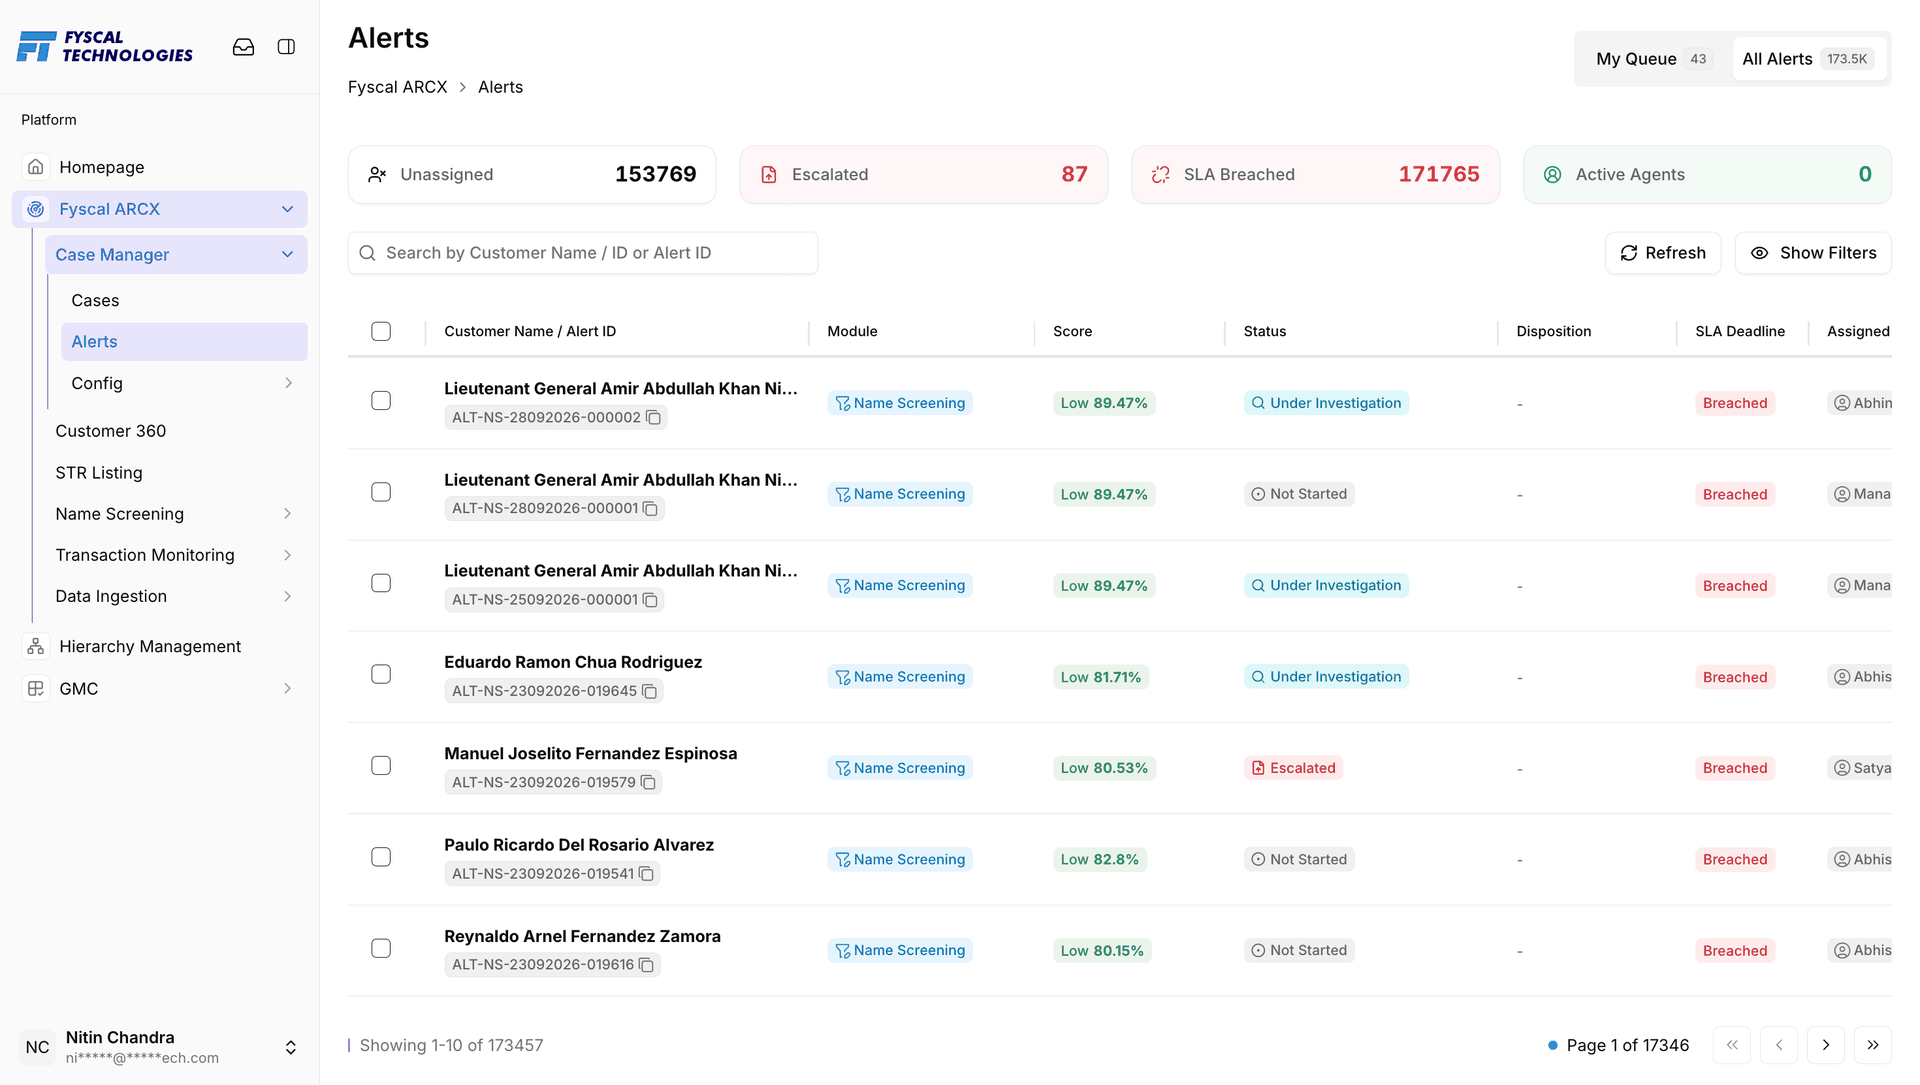
Working a specific type of alert? Filter by which module generated it.
Since alerts arrive from more than one source, the Module filter isolates just Name Screening hits or just Transaction Monitoring hits. The full filter bar also covers Status, SLA and Score (urgency and match strength); on All Alerts it adds Assignee, which finds a specific analyst's alerts, and a Show Hibernated toggle that reveals alerts put to sleep rather than actively worked. Statuses you will see on alerts include Not Started, Under Investigation, Escalated and Closed.
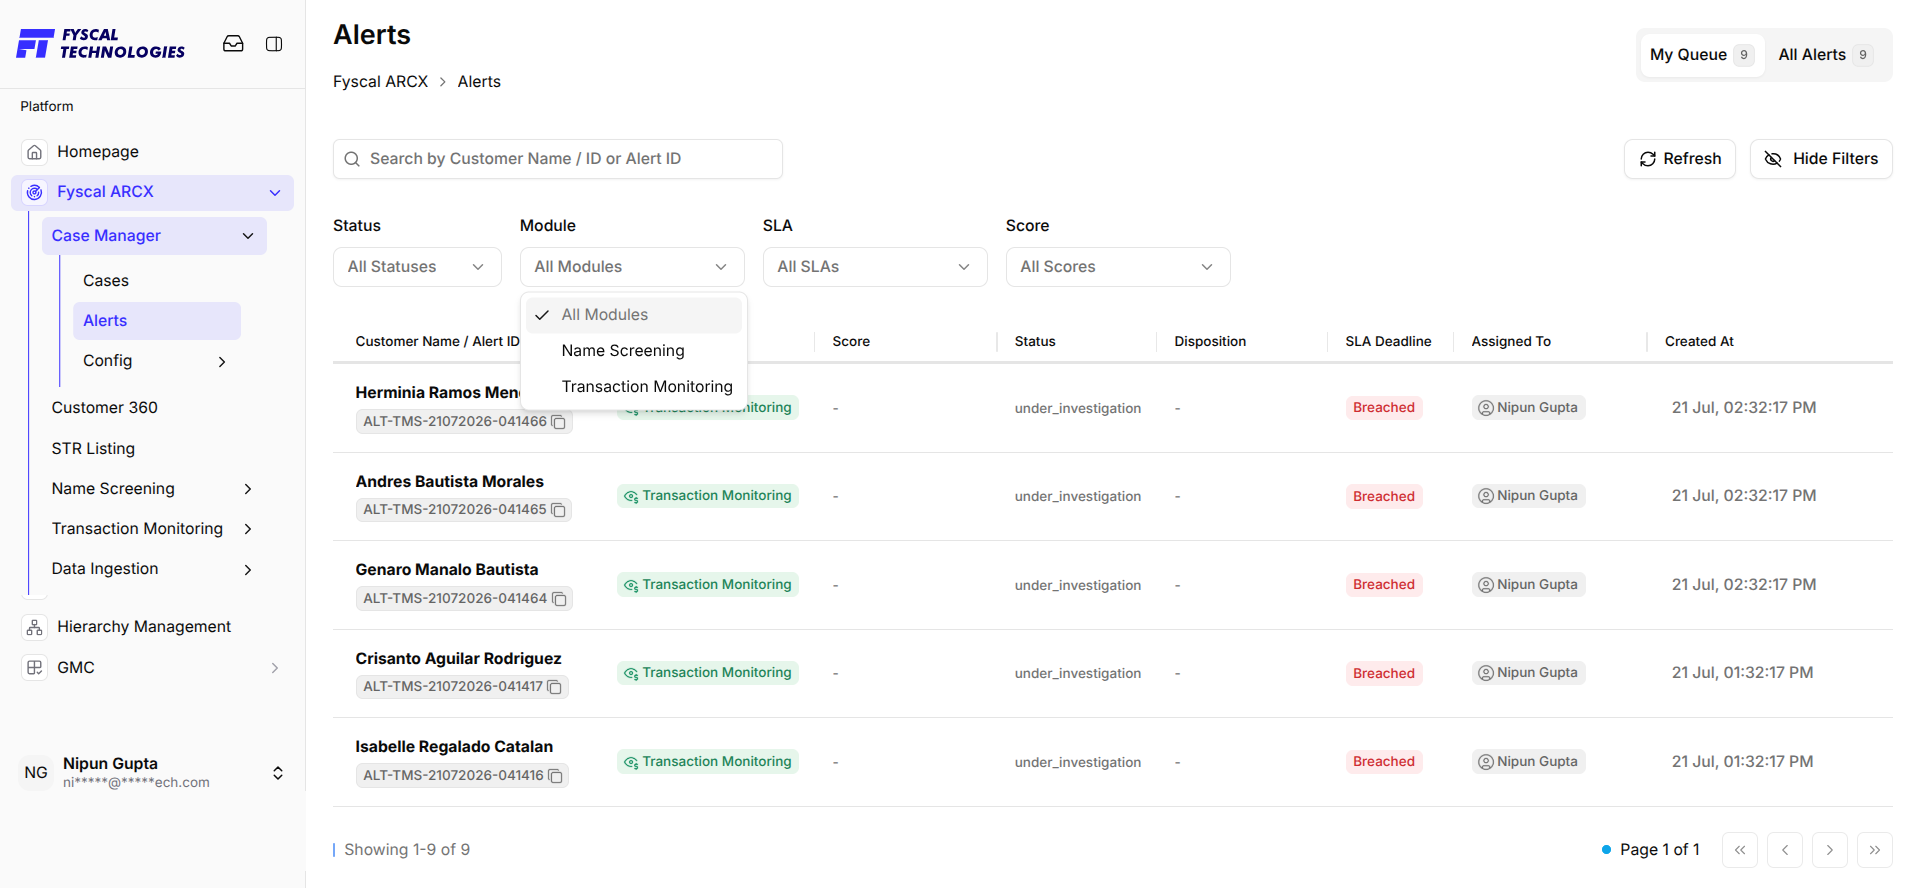
Found the alert you're after? Open it to see the full match detail.
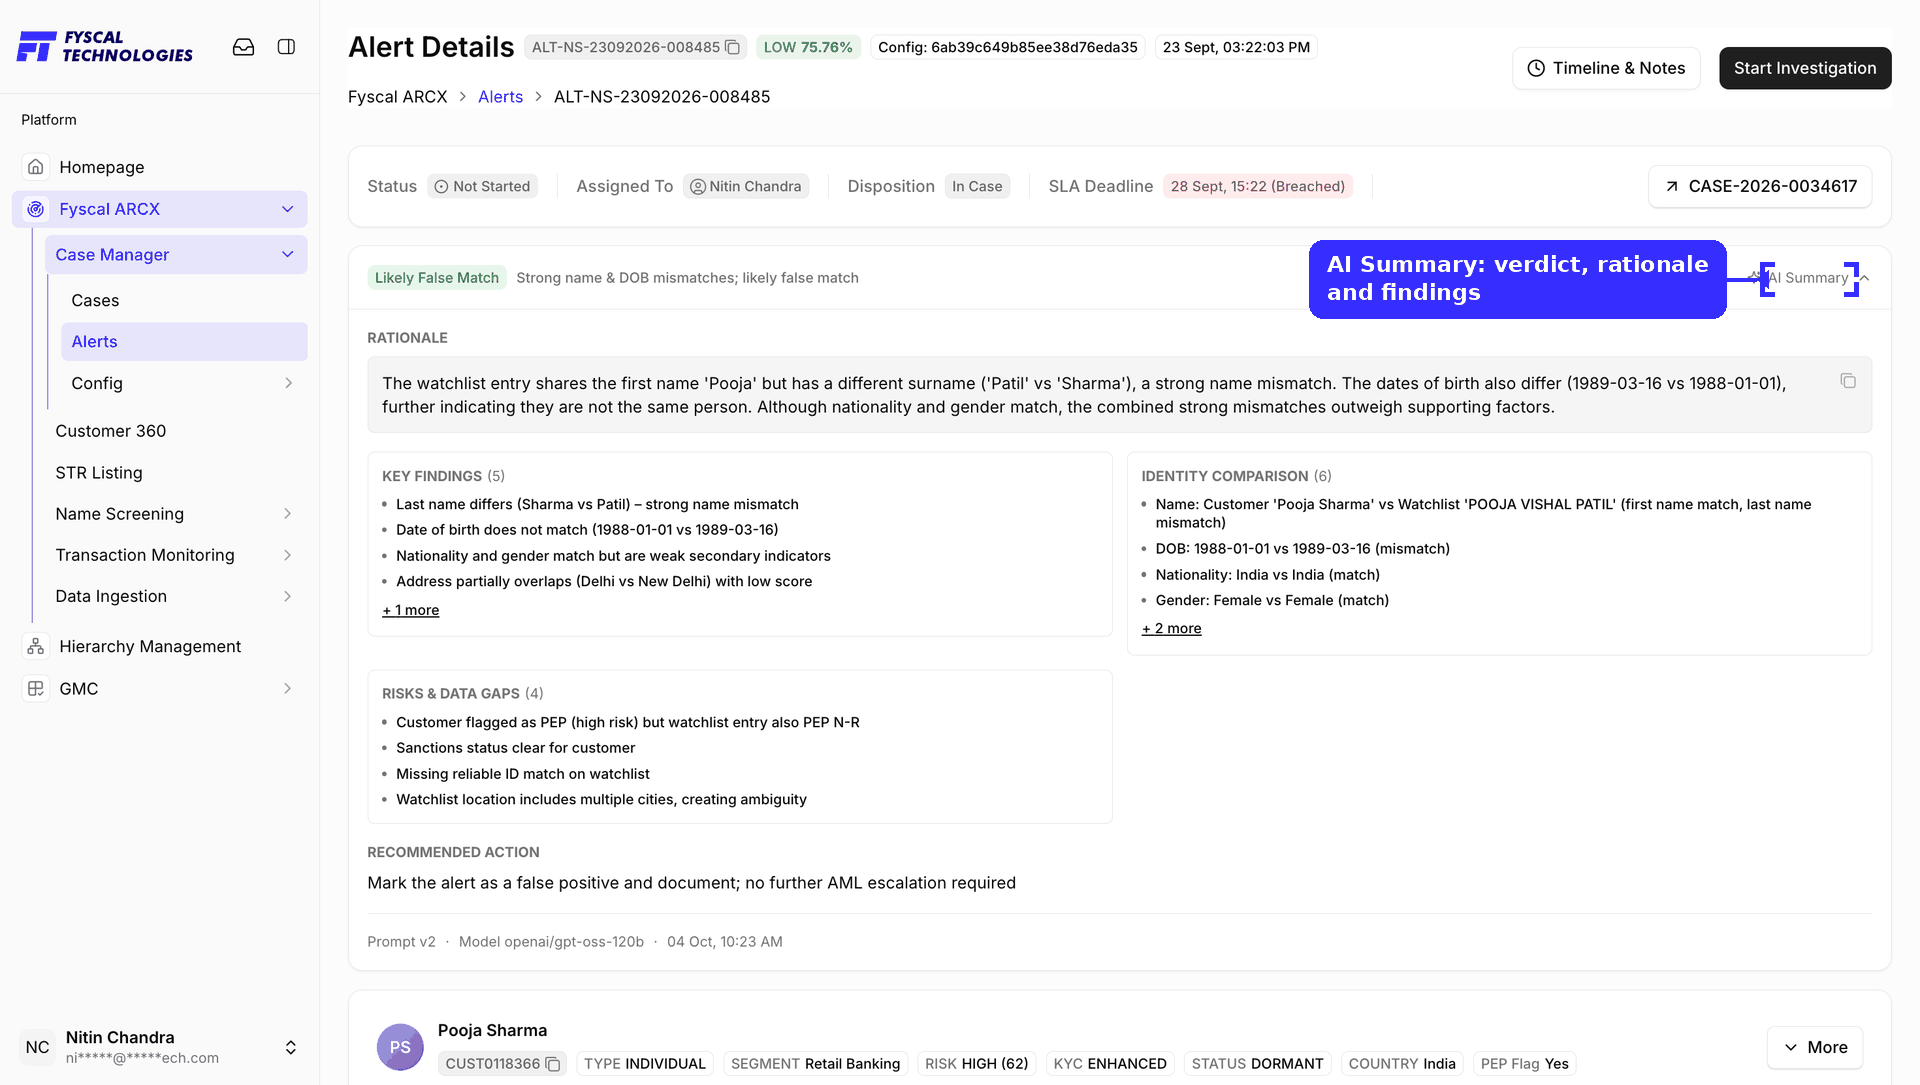
Clicking a row opens Alert Details. The header shows the alert ID, its score band (e.g. LOW 75.76%), the Config version ID of the alert configuration it was scored under, and when it was raised, with Timeline & Notes and Start Investigation buttons. Below are the alert's Status, Assigned To, Disposition (an alert that has been grouped into a case shows In Case), SLA Deadline (flagged Breached once missed) and a button linking straight to the case it belongs to.
The AI Summary card reads the alert for you. It leads with a verdict chip — for example Likely False Match — and a one-line reason, then gives the Rationale, Key Findings, an Identity Comparison (field-by-field match or mismatch), Risks & Data Gaps, and a Recommended Action. Lists show a count and expand with "+ more". A footer states which prompt version and model produced it. The summary is generated by the Name Screening and Transaction Monitoring prompts in Agentic Workflows — it supports the analyst, who still decides.
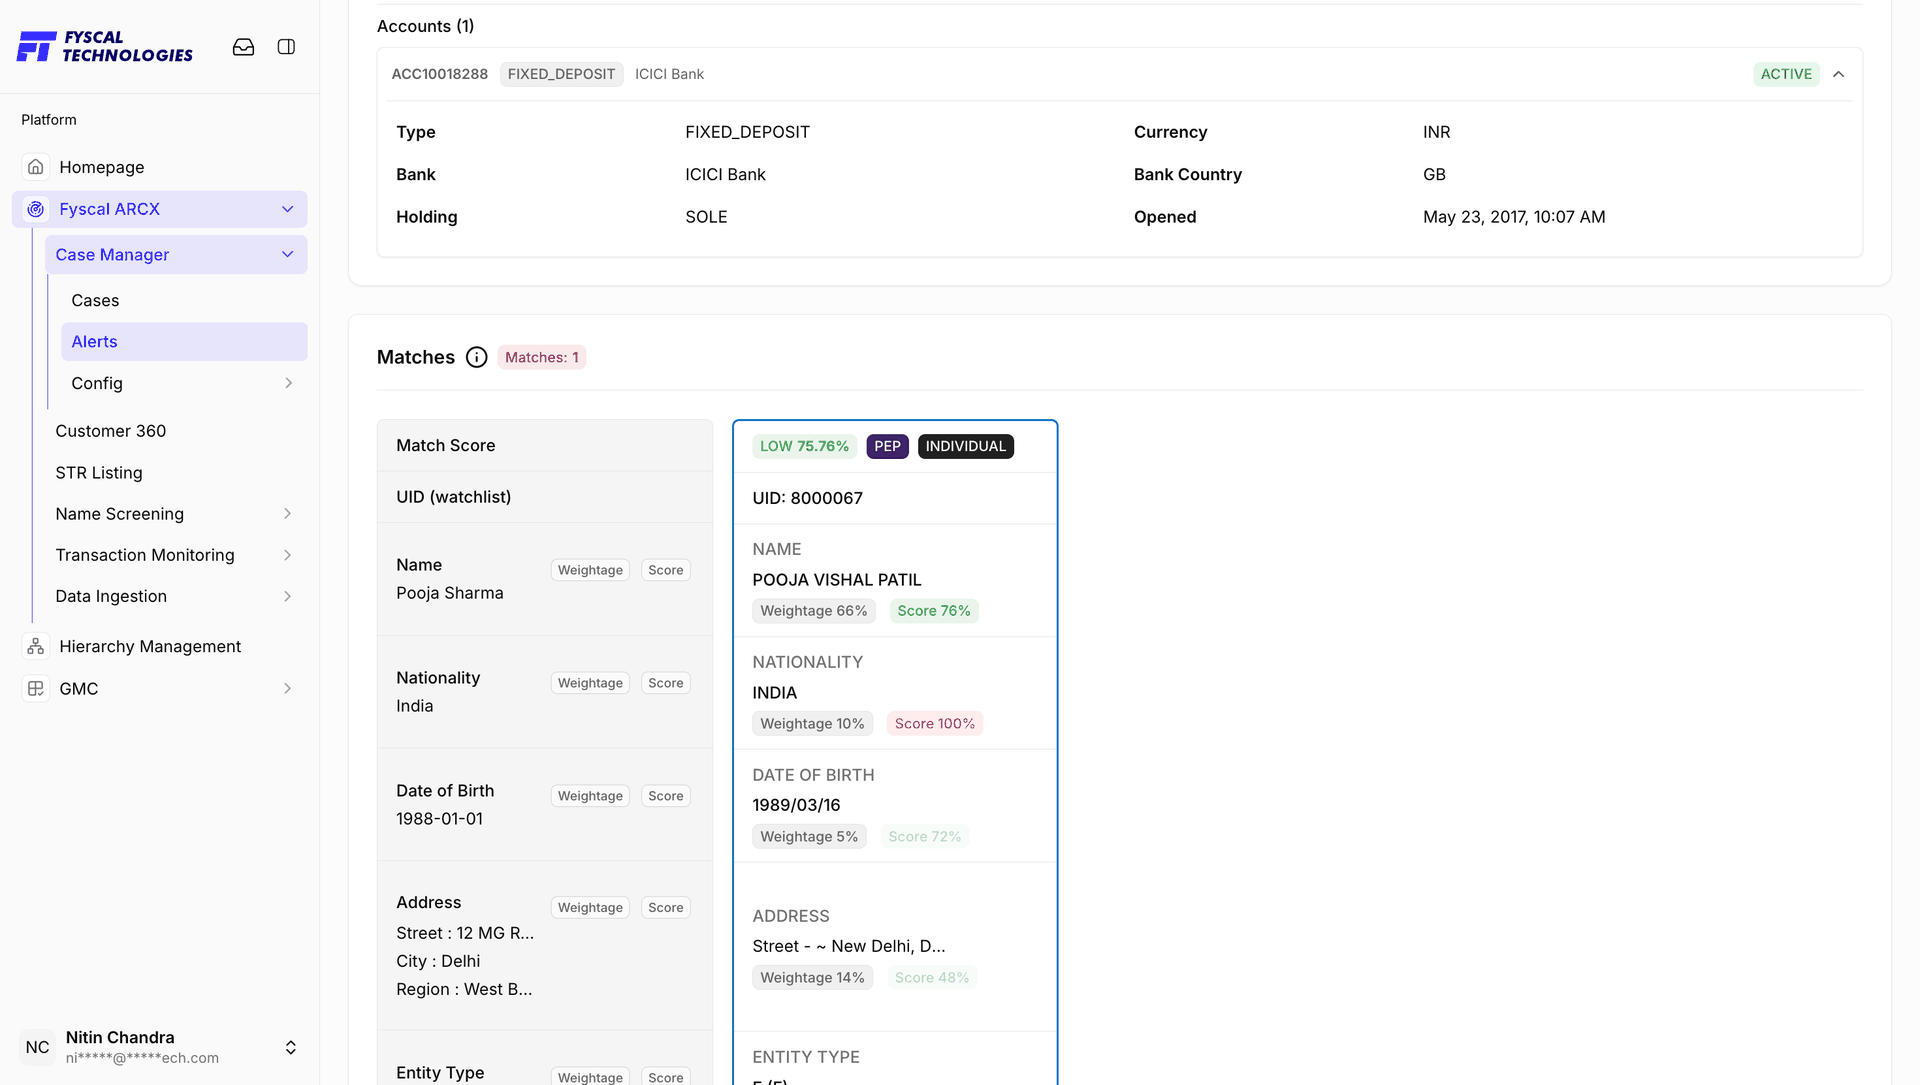
Further down, the customer profile and accounts are repeated for context, followed by Matches. The left column holds the customer's own details (name, nationality, date of birth, address, entity type); each matched watchlist entry sits beside it with its overall score and the Weightage and Score of every field, so you can see exactly what drove the match.
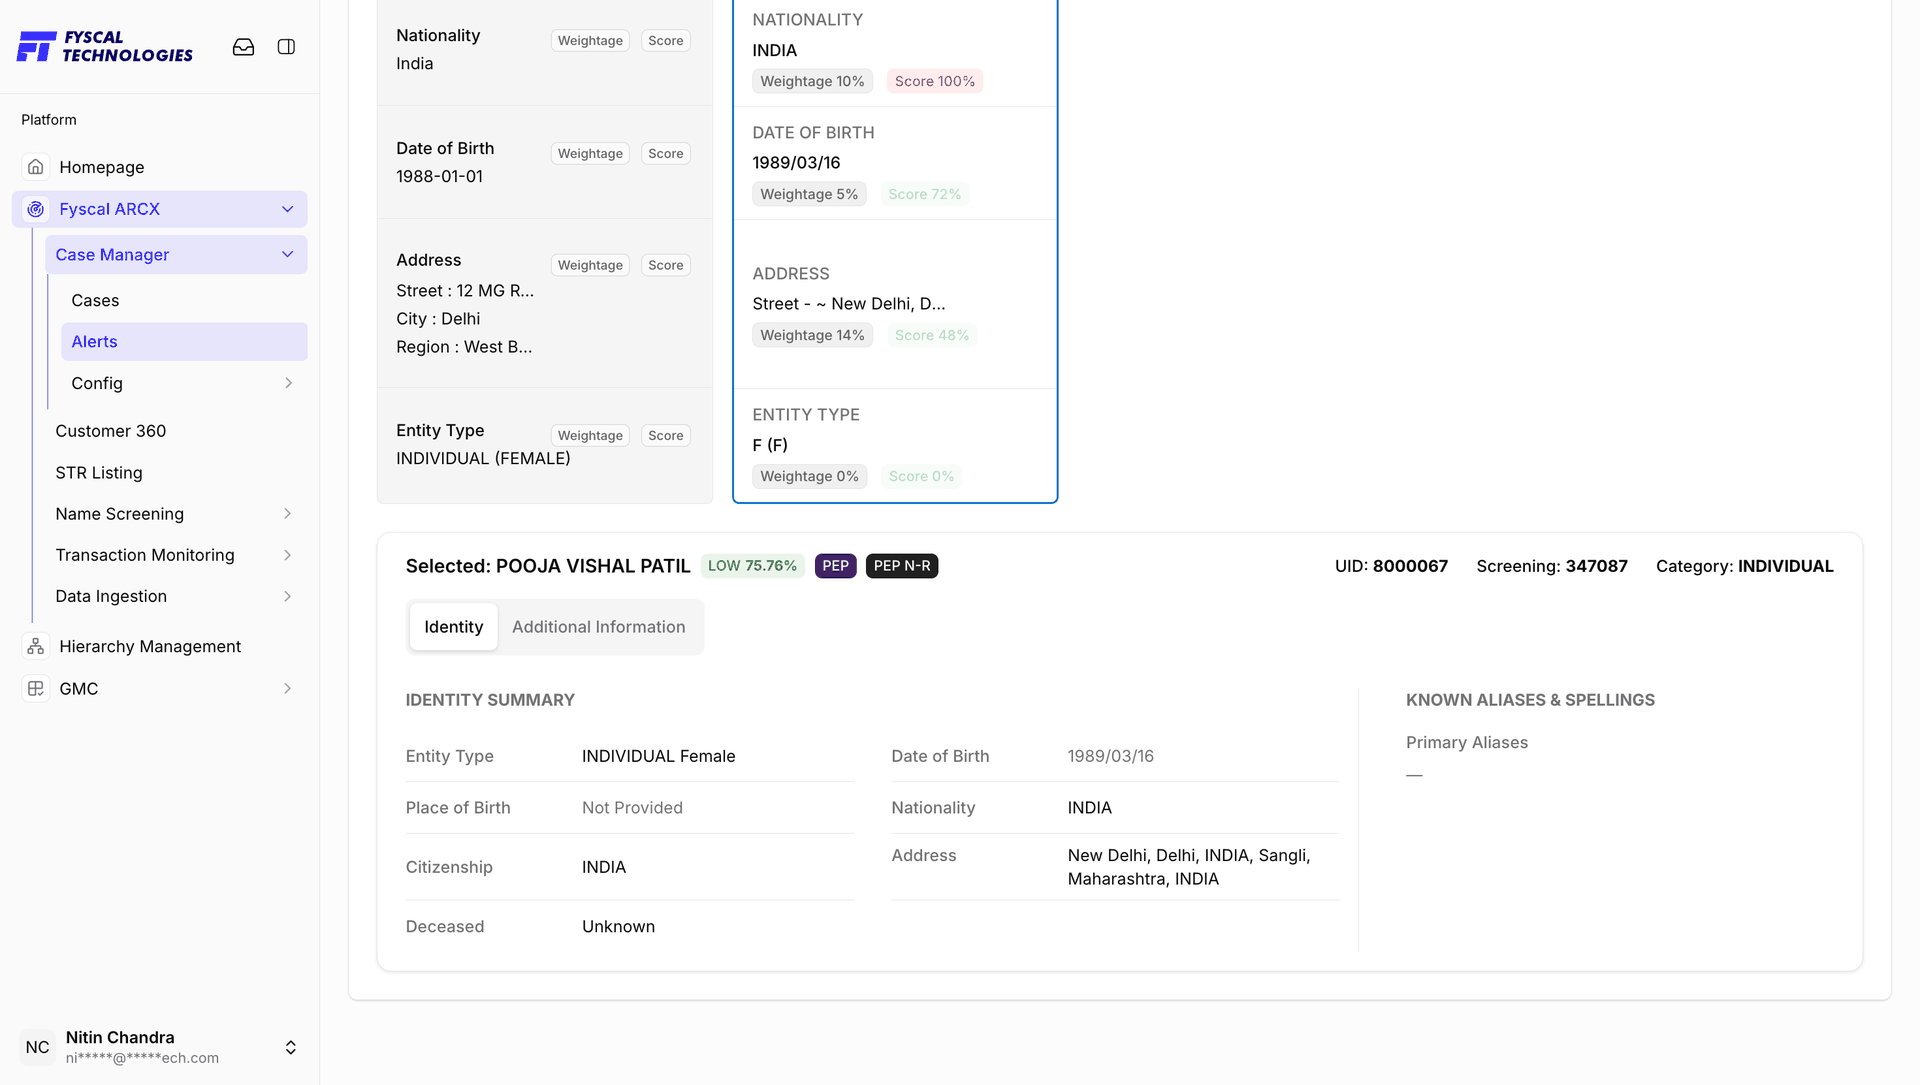
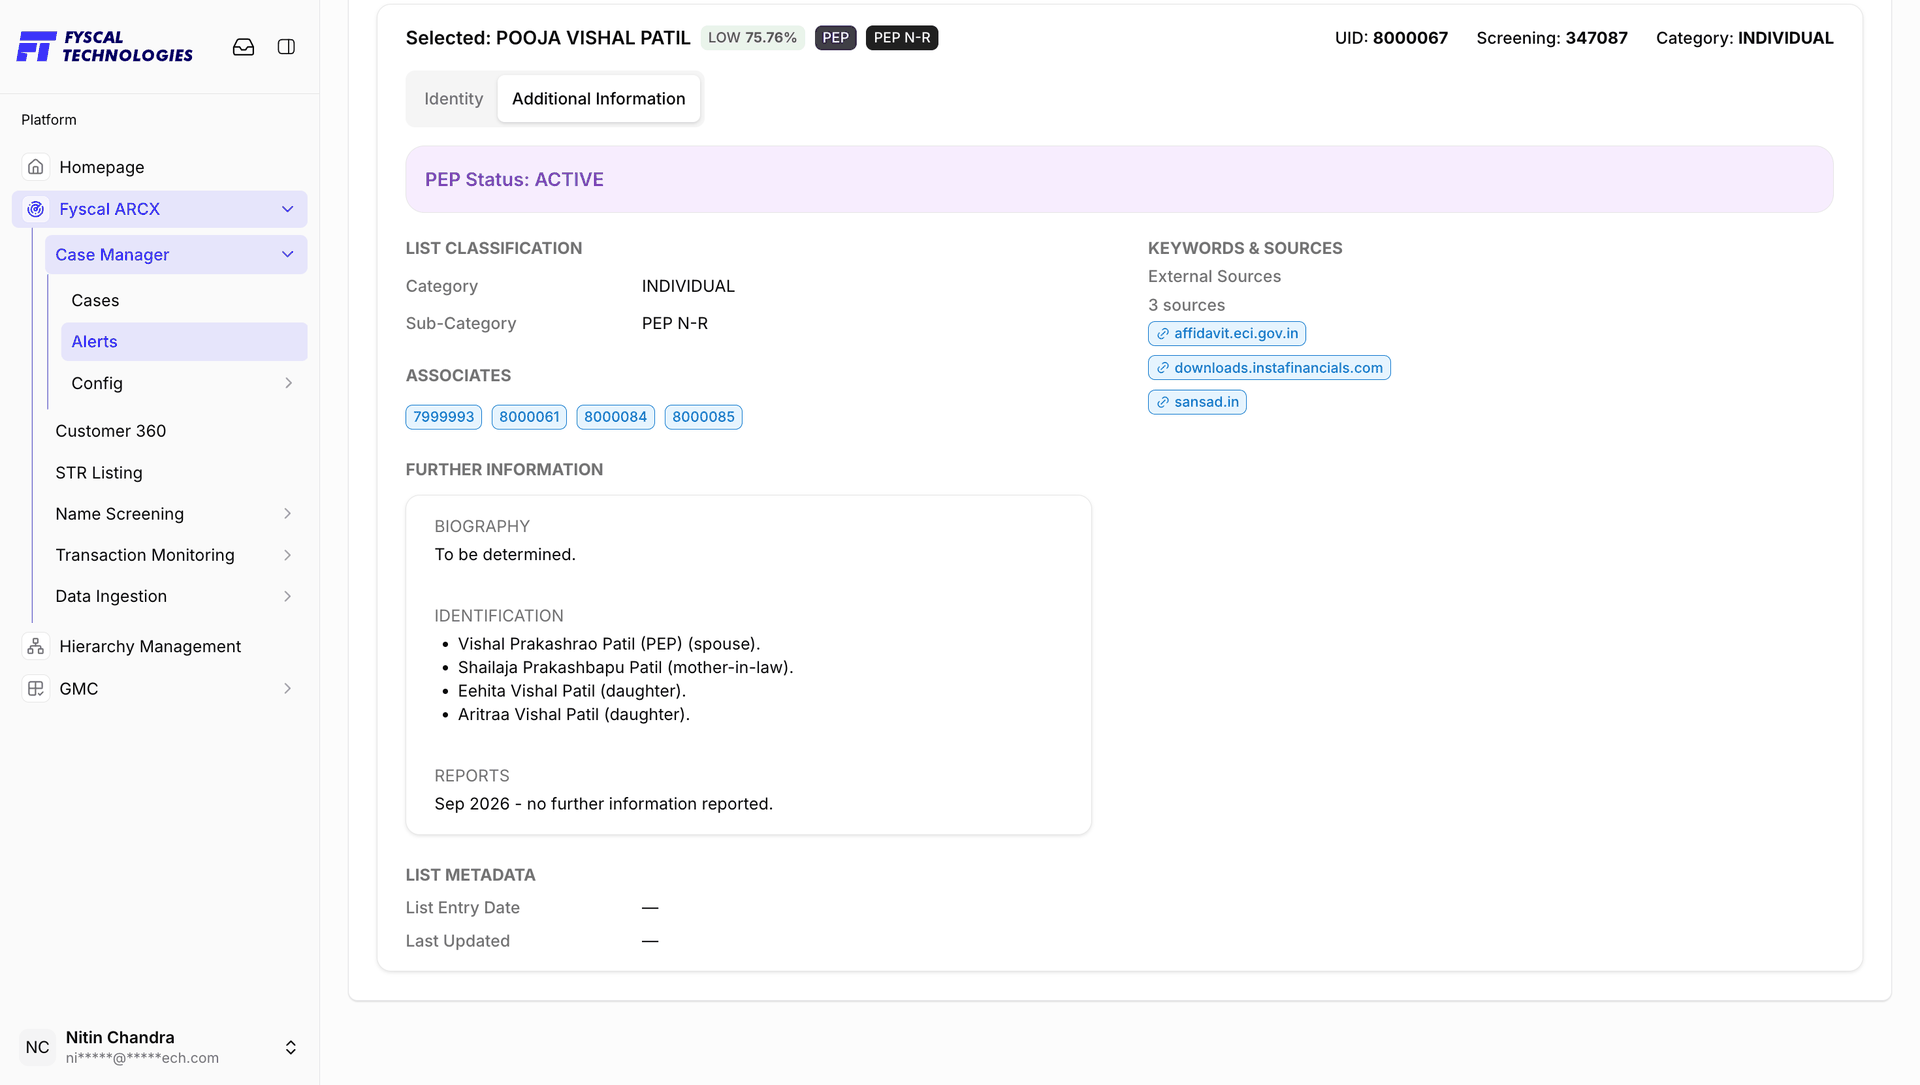
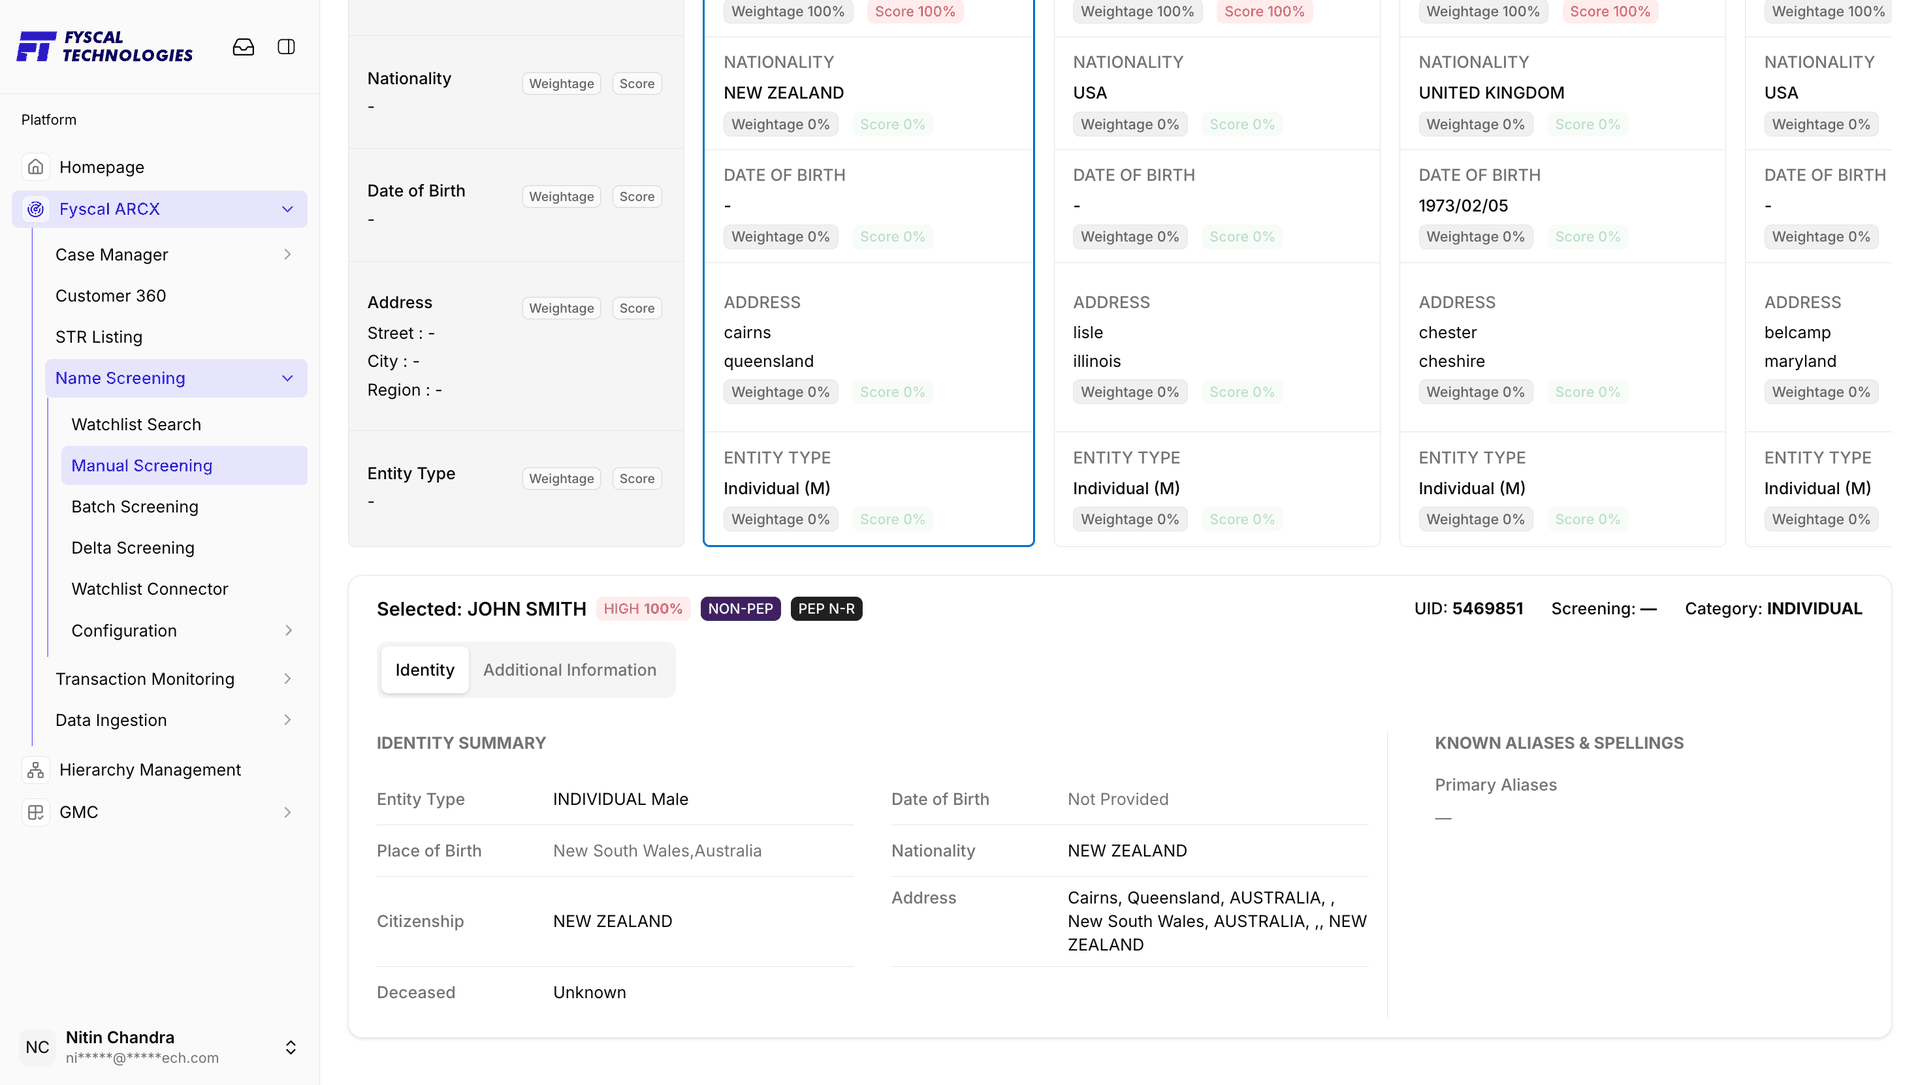
Further down the same page, the field-by-field comparison continues — here the rows for Nationality, Date of Birth, Address and Entity Type — and beneath it a Selected panel opens the full watchlist record for whichever match is highlighted. Its header carries the matched person's name, the score band, any PEP badges, the watchlist UID, the Screening number the match belongs to, and the record's Category. Two tabs sit underneath. Identity holds the Identity Summary — entity type and gender, date and place of birth, citizenship, nationality, address, and whether the person is known to be deceased — and the Known Aliases & Spellings on file.
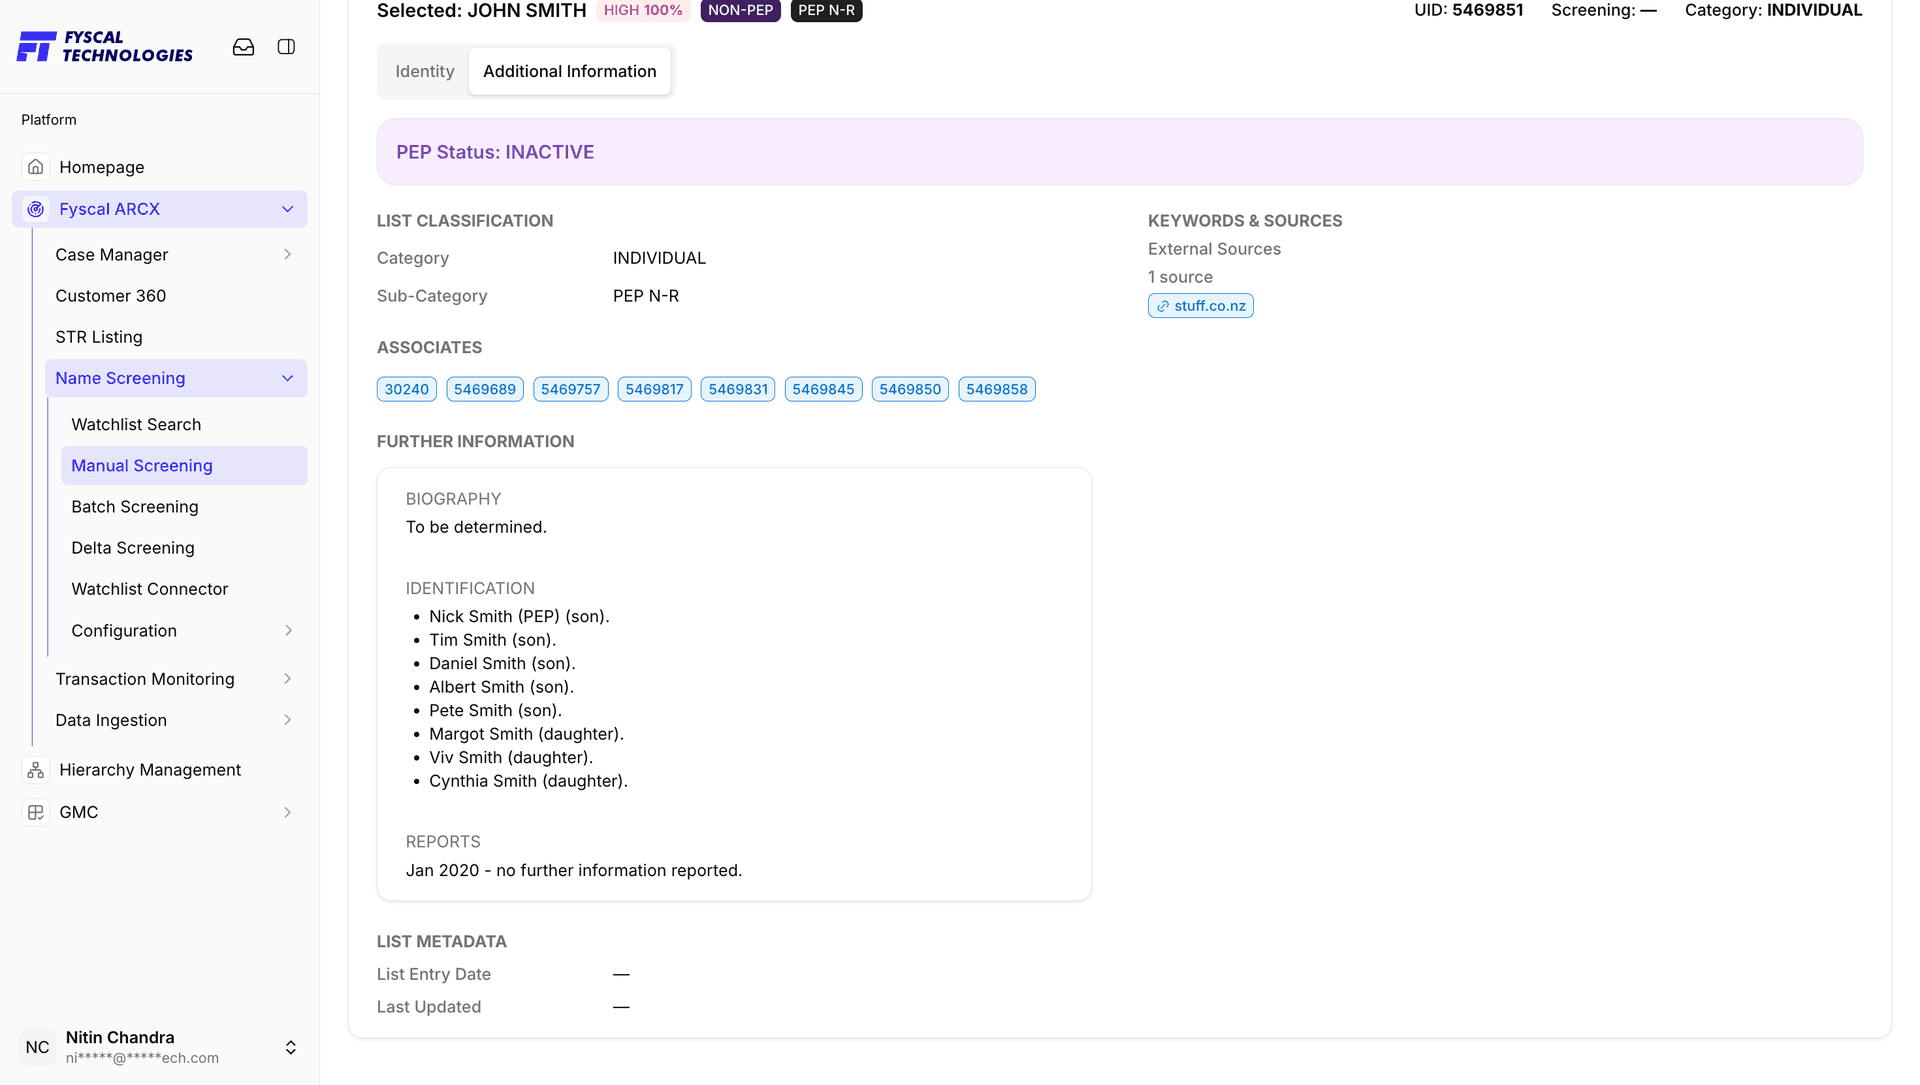
The second tab, Additional Information, is where the risk context lives:
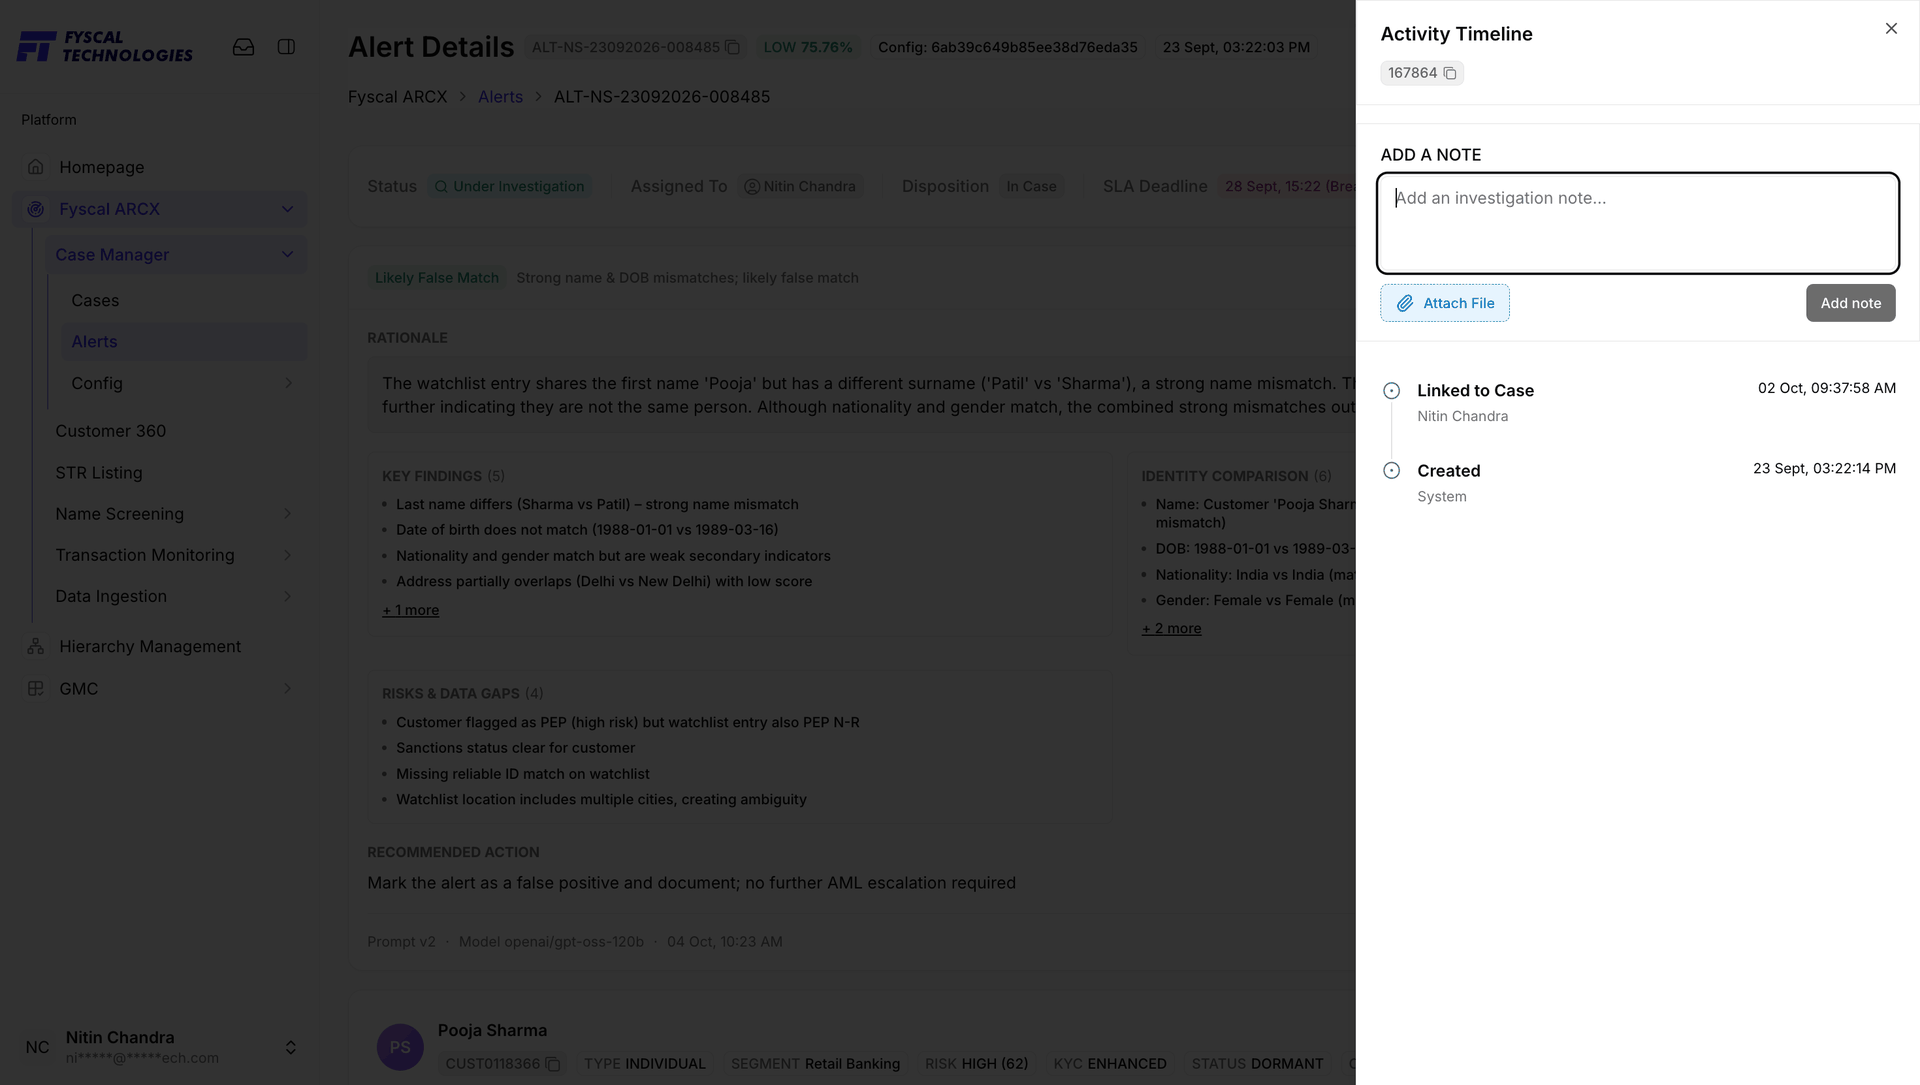
Timeline & Notes on Alert Details opens the same Activity Timeline panel used on cases, scoped to this one alert. The panel header repeats the alert's reference number; Add a note and Attach File record your reasoning against the alert itself, so it travels with the alert if it is later merged into a case. Underneath, events are listed newest first: in this example Linked to Case (the alert was merged into a case, with who did it and when) above Created, logged by System — a reminder that this alert was generated automatically by a screening run rather than raised by a person.
| Column | What it shows |
|---|---|
| Customer Name / Alert ID | The customer or subject name, plus a unique alert reference (e.g. ALT-NS-23092026-008485) |
| Module | Which engine generated the alert — Name Screening or Transaction Monitoring |
| Score | The match or risk score as a percentage, labelled and colour-coded with the severity band it falls into (e.g. Low 75.76%) as defined in Alert Configuration |
| Status | Where the alert is in its work — e.g. Not Started, Under Investigation, Escalated, or Closed |
| Disposition | The outcome once reviewed (e.g. Potential Match) — blank while still unresolved |
| SLA Deadline | Flags Breached once the alert's resolution window has been missed |
| Assigned To | The analyst responsible for reviewing the alert |
| Created At | When the alert was generated |
A Name Screening alert scoring 75.76% falls in the Low band — just above the 75% floor below which, in the example Alert Configuration, no alert is raised at all. Its SLA is the 3 days set for that band, and an analyst working their queue by SLA Deadline sees it before a later alert with a longer window.
Three configuration areas, all reached from Case Manager → Config: Case Creation & Assignment (which alerts become cases, how they are grouped, and who the cases go to), Alert Assignment (who an alert goes to), and Agentic Workflows (the AI prompts and model behind summaries and Case Copilot).
Every institution has exactly one active Case Creation configuration at a time, shown read-only until Edit is used. It has three parts:
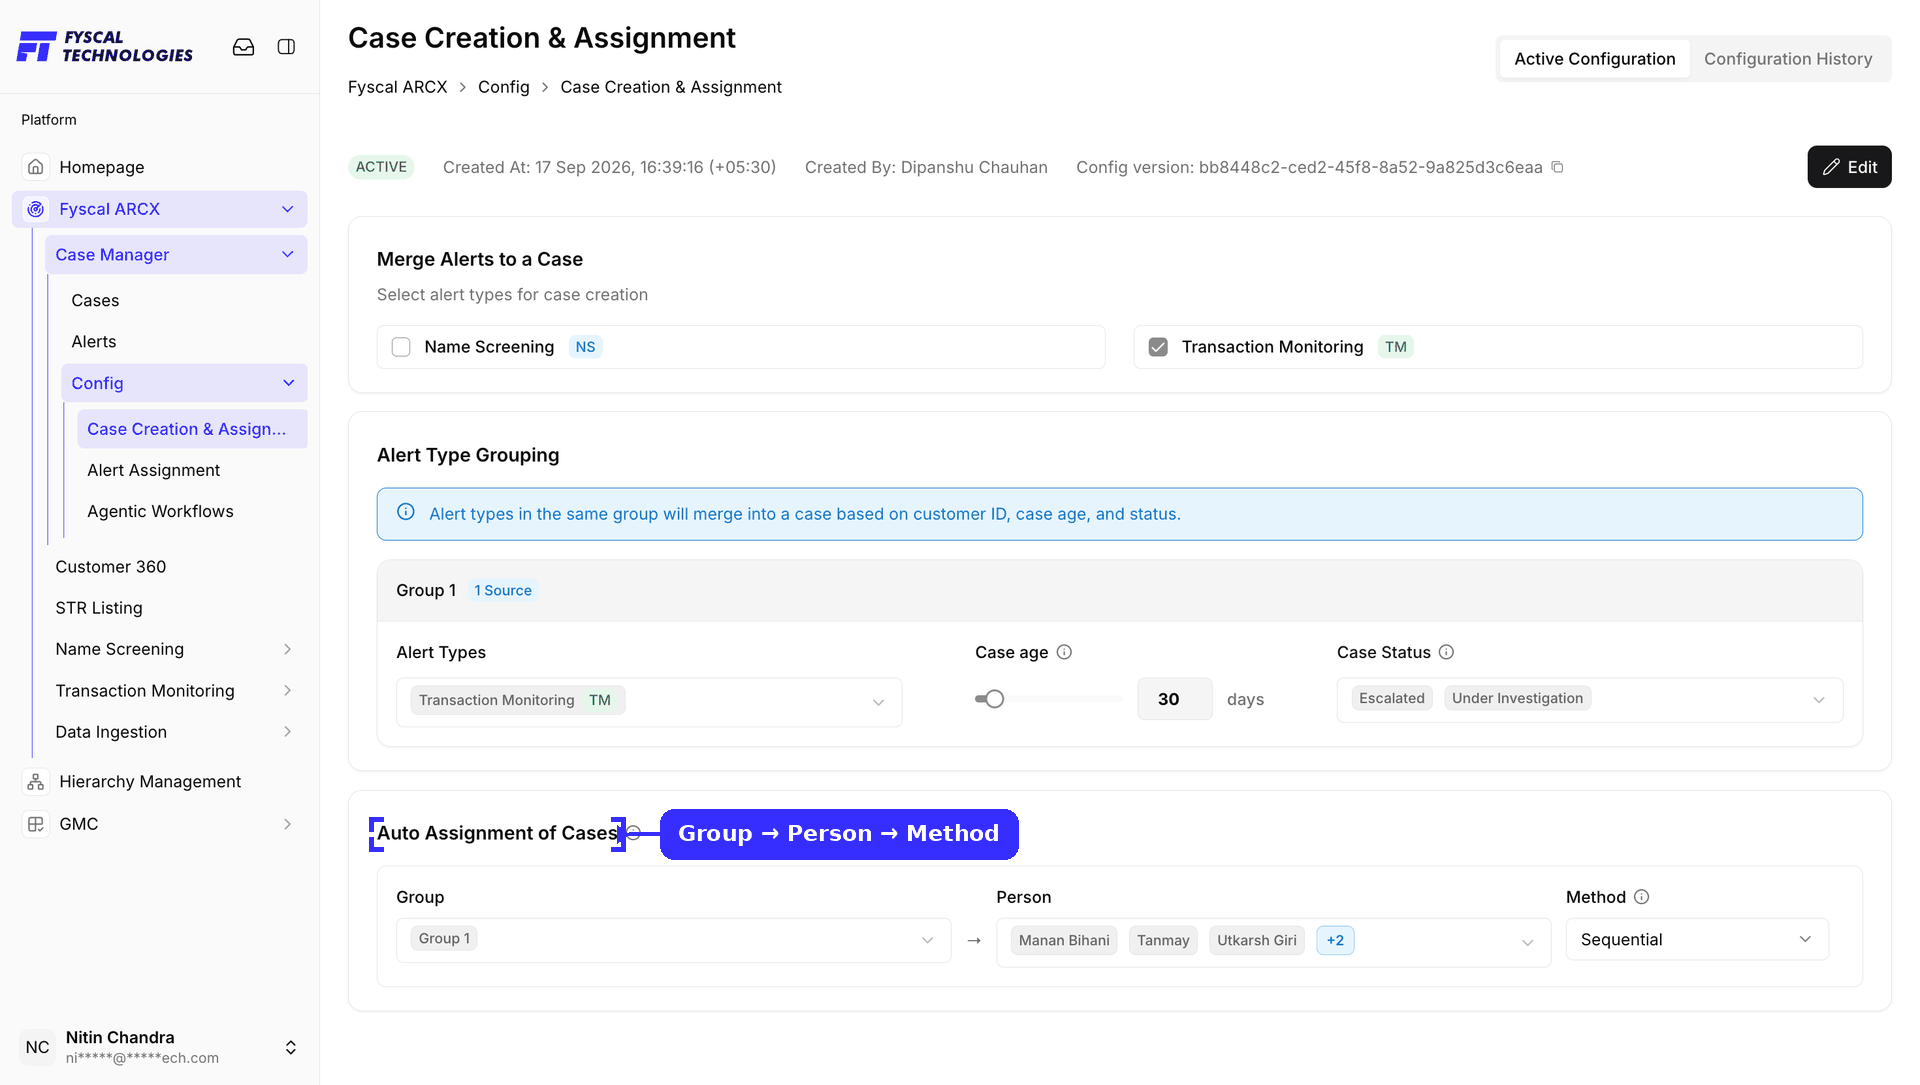
Within Alert Type Grouping, each Group lists the Alert Types it applies to, a Case age in days, and a set of Case Status values. Read together, a group says: alerts from these sources, on the same customer, land in the same case as long as that case is still within the Case age window and currently sitting in one of the listed statuses — otherwise a new case is opened instead of merging into an old one.
Auto Assignment of Cases maps each group to people: pick the Group, the Person (or several — extra names collapse into a "+2" style chip) and the Method used to share cases between them (Sequential in this example). + Add Mapping adds another group-to-people rule.
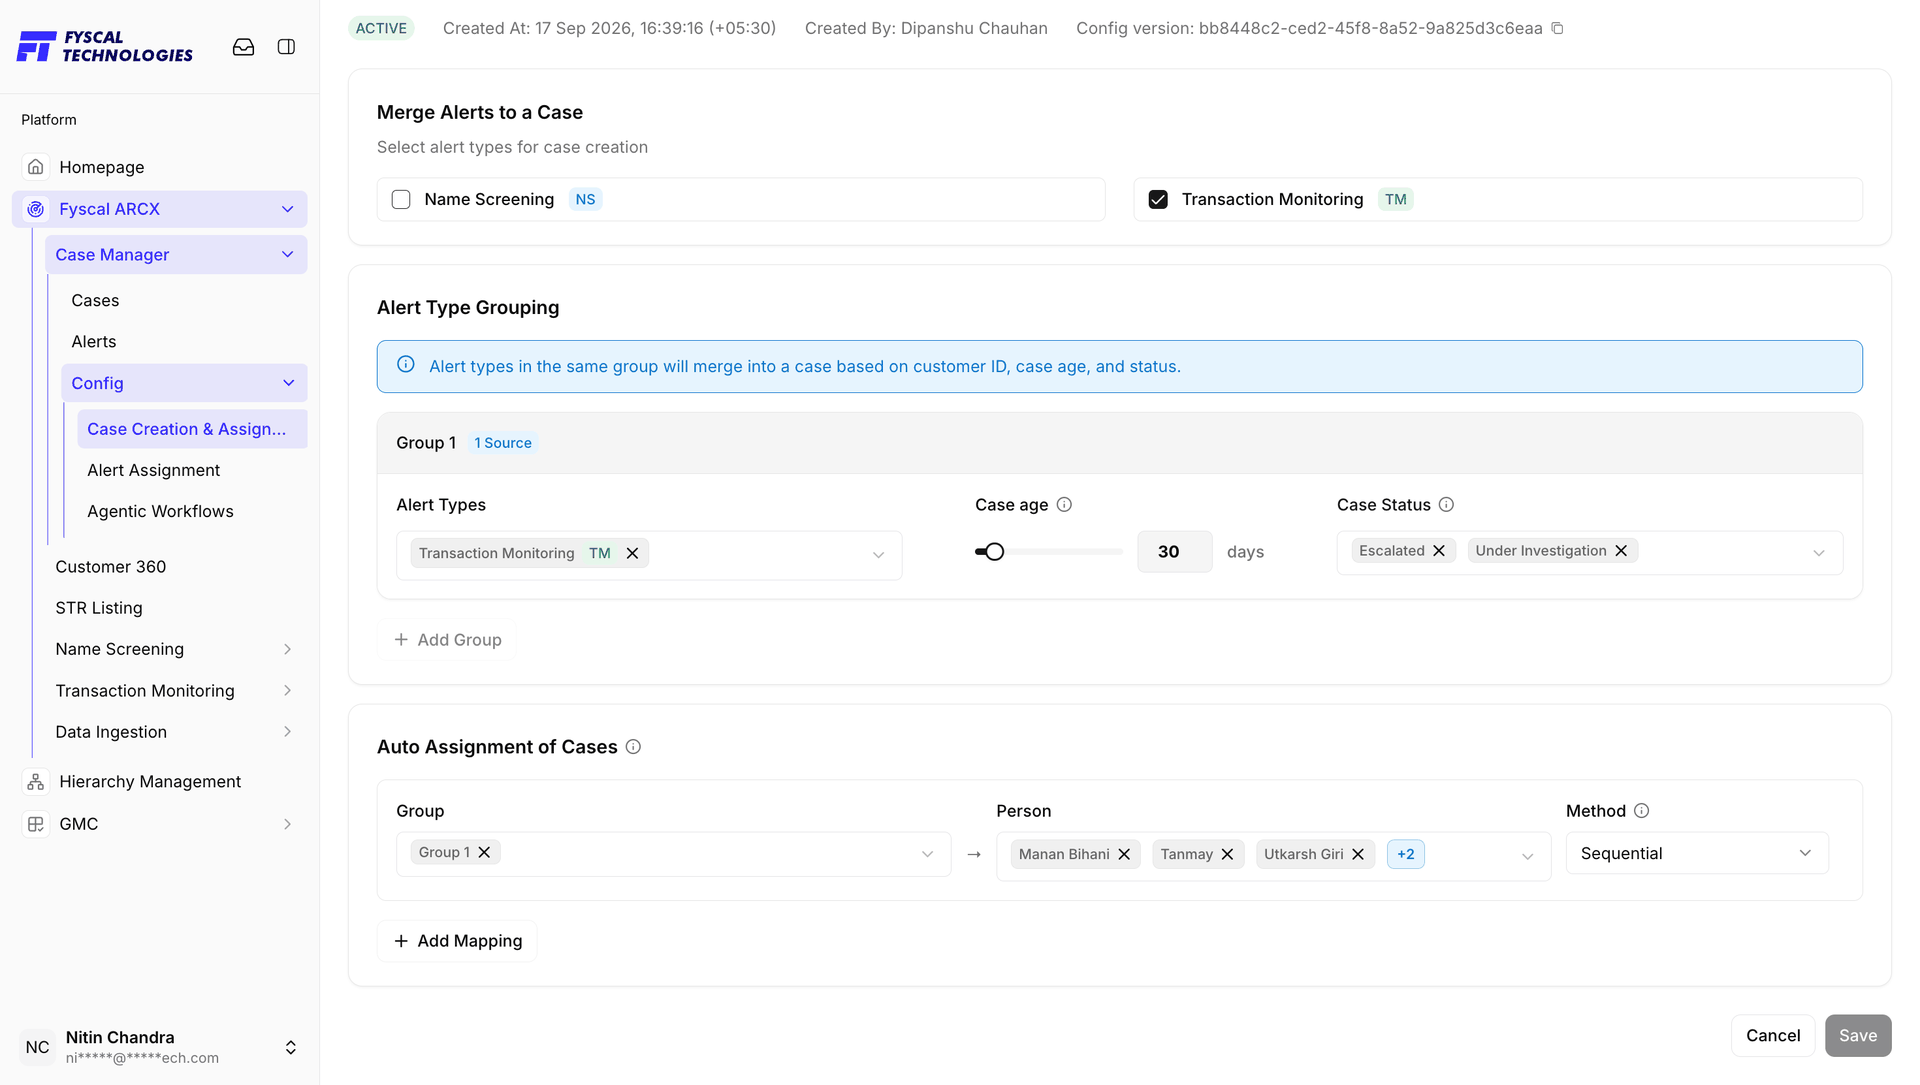
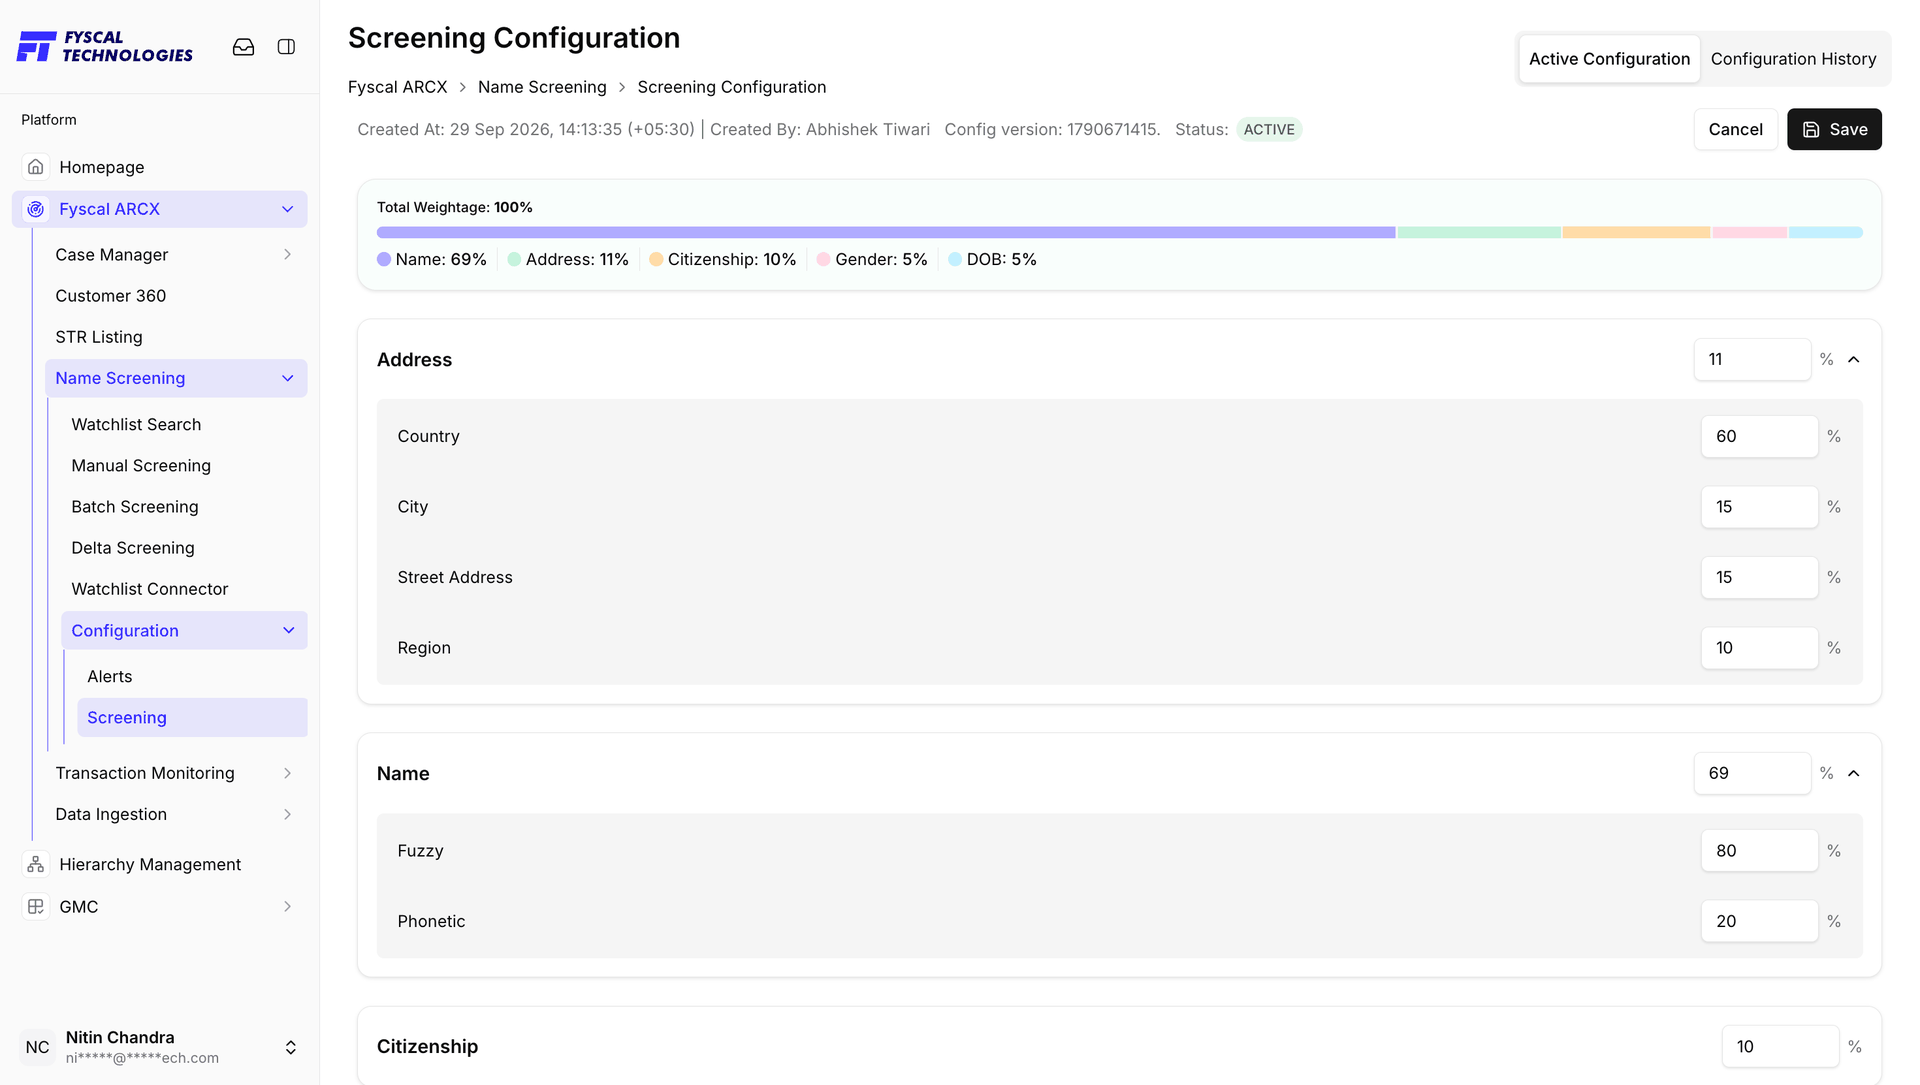
Clicking Edit turns every field interactive: Alert Types become checkboxes you can toggle, and each group's Alert Types, Case age, and Case Status become editable directly in place, with Cancel and Save appearing at the bottom.
Every save creates a new version rather than overwriting the last one, so the full history of how case-creation rules have changed over time is always available for audit. Configuration History lists every version — its unique Config Version ID, whether it's the currently ACTIVE one or an INACTIVE past version, when it was created, and by whom. Click any row to open that version's full read-only configuration exactly as it was saved.
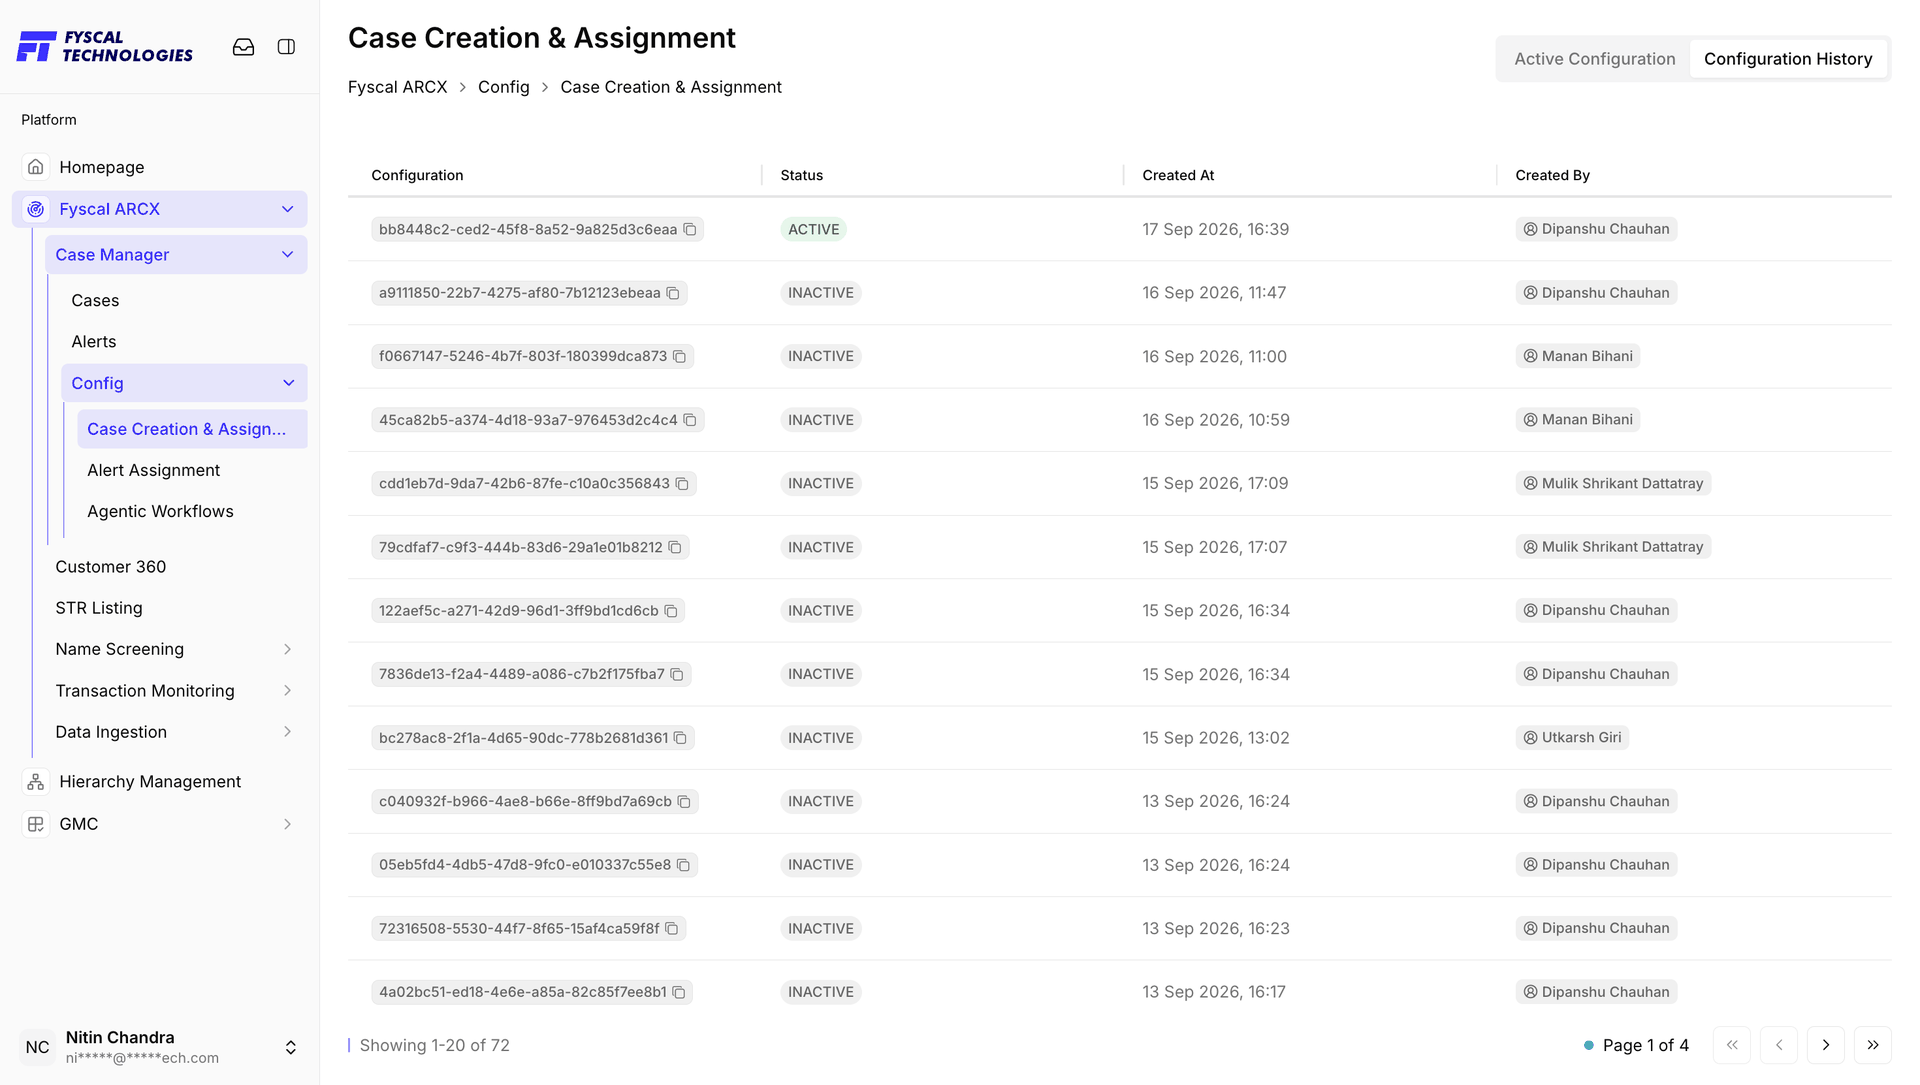
A customer triggers a Name Screening alert on Monday and a second alert on Wednesday. With both in the same group, a Case age of 30 days, and Under Investigation included in Case Status, Wednesday's alert joins Monday's still-open case automatically instead of creating a second, disconnected case for the same customer.
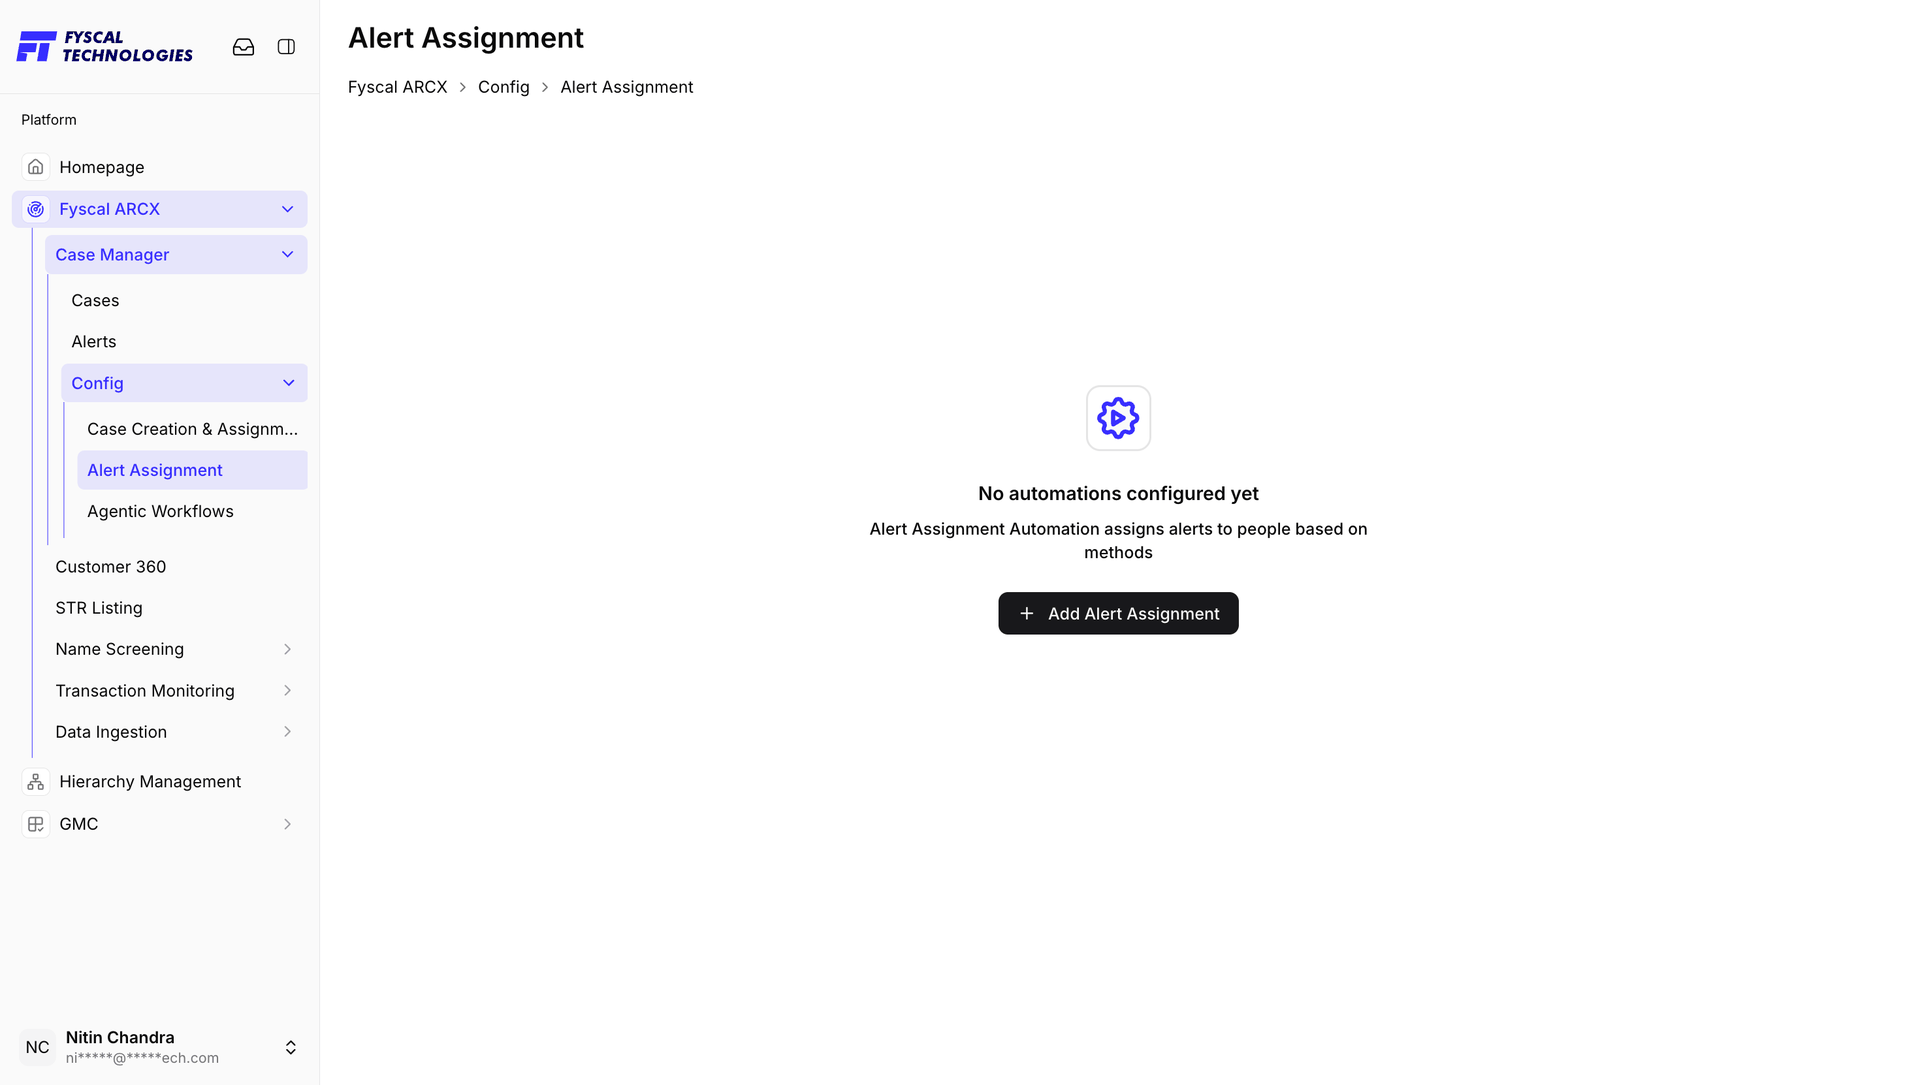
Where Case Creation & Assignment decides whether an alert becomes a case and who the case goes to, Alert Assignment decides who an alert goes to in the first place — automatically routing it to a person the moment it's created, rather than leaving it unassigned in the shared queue.
With nothing configured yet, alerts stay unassigned until manually picked up. Add Alert Assignment creates the first routing rule.
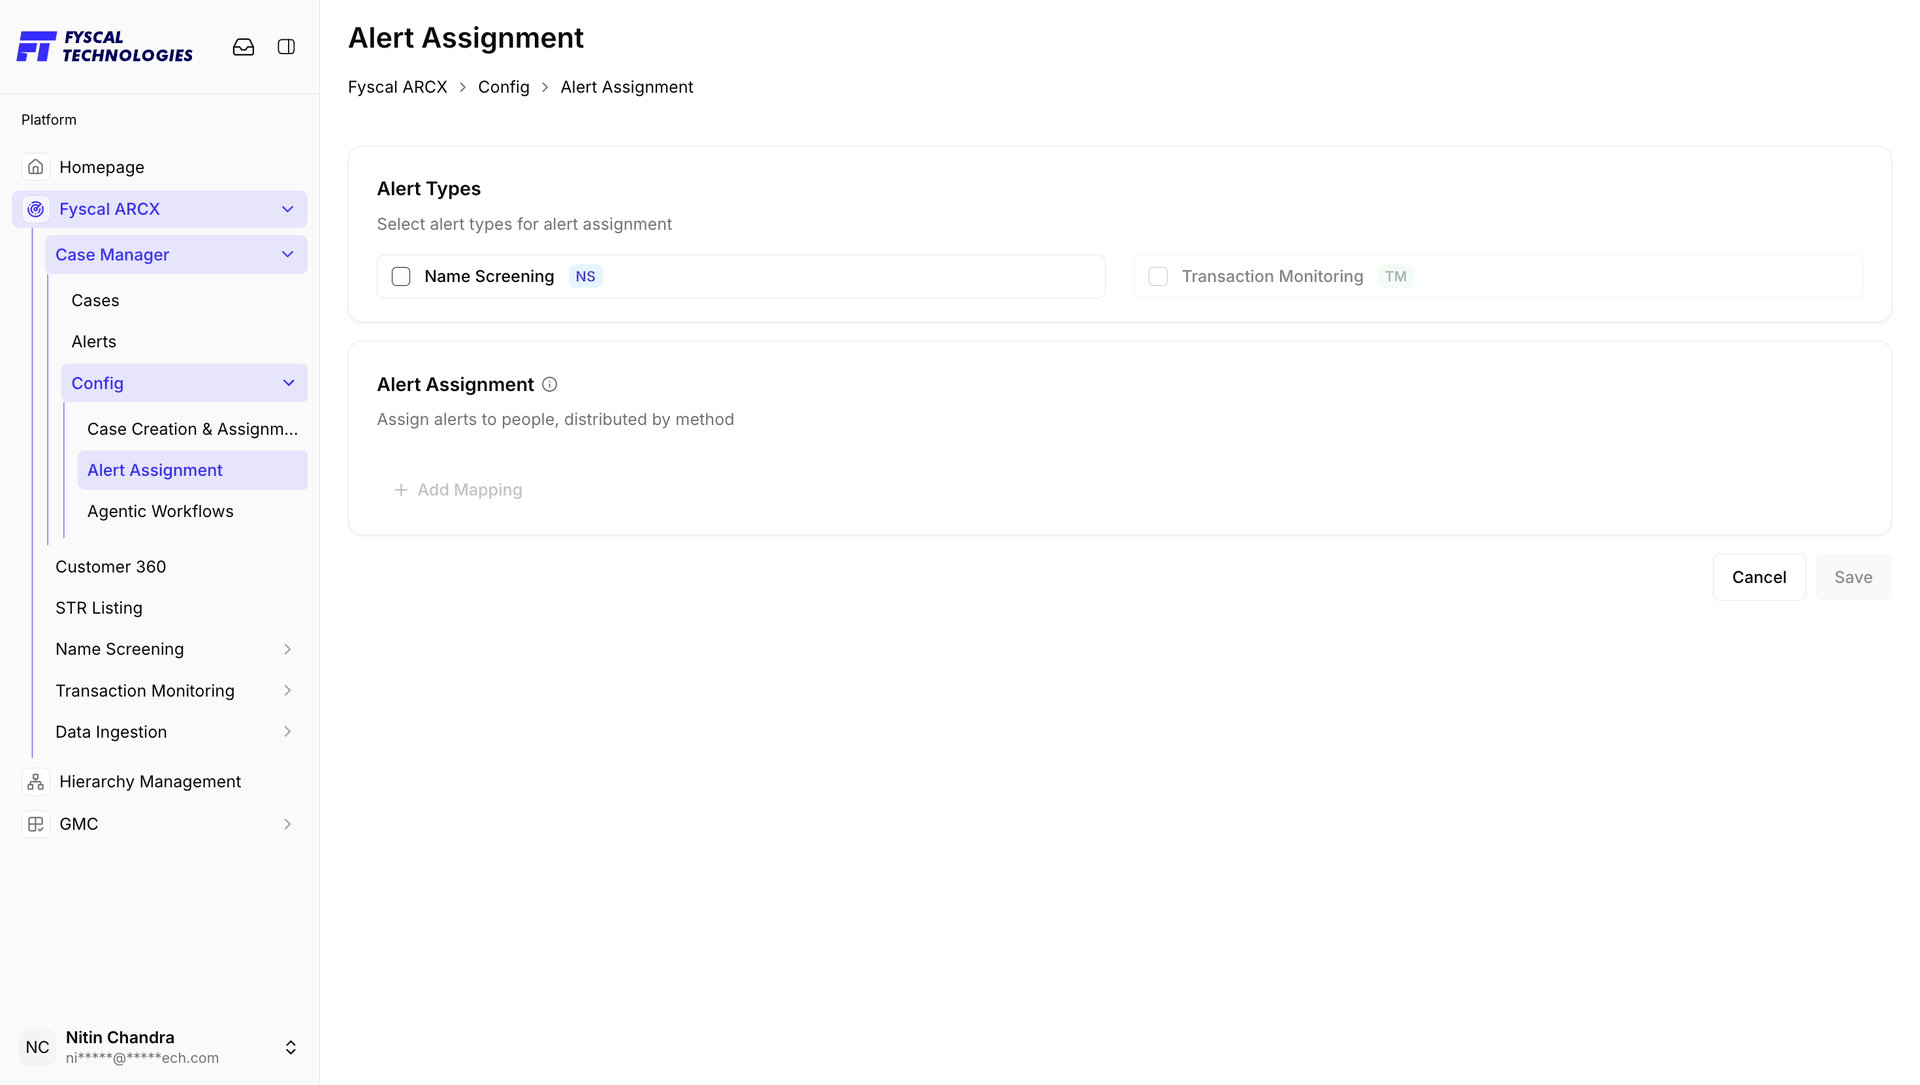
Adding a rule starts with choosing which alert types it applies to.
The form opens on Alert Types — Name Screening and Transaction Monitoring checkboxes (an option that cannot be selected appears greyed out). Once a type is chosen, + Add Mapping becomes available; until then it is disabled, as is Save.
Next, define who the alerts go to.
A Mapping pairs the Alert Types it covers with the Person (or people) alerts should route to and the Method used to split them.
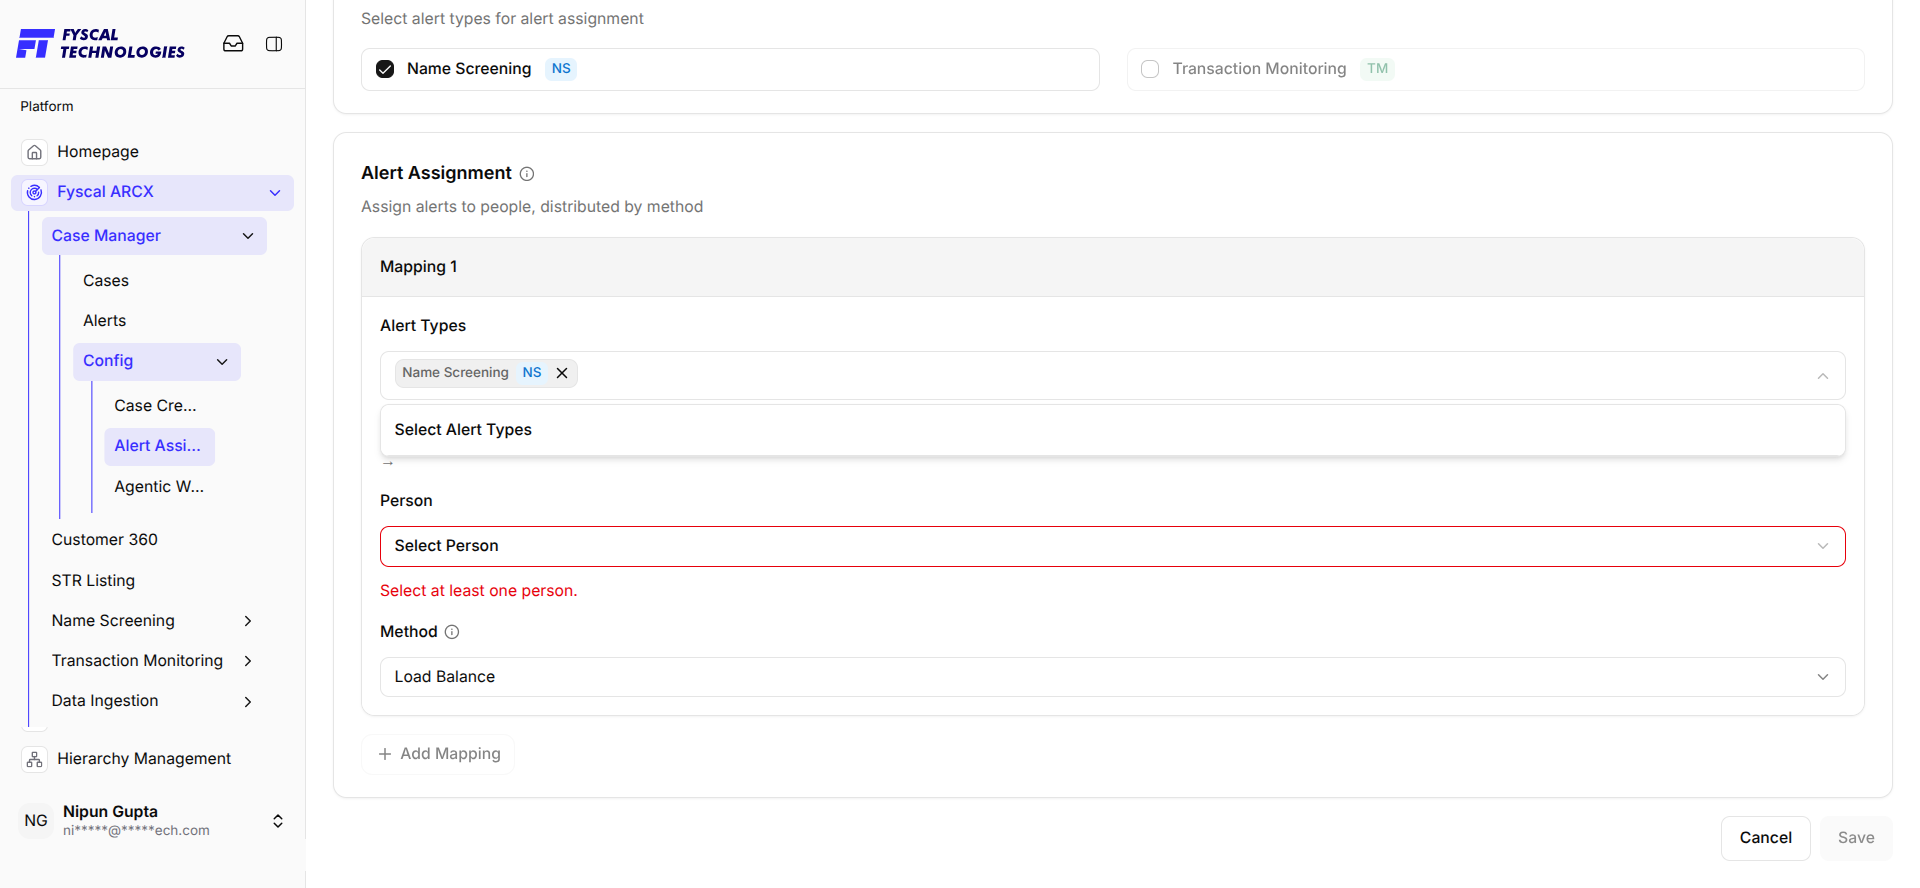
With more than one person on a mapping, Method decides how alerts are split between them.
Sequential assigns alerts to people in turn, one after another; Load Balance instead keeps everyone's open-alert count even, sending the next alert to whoever currently has the least.
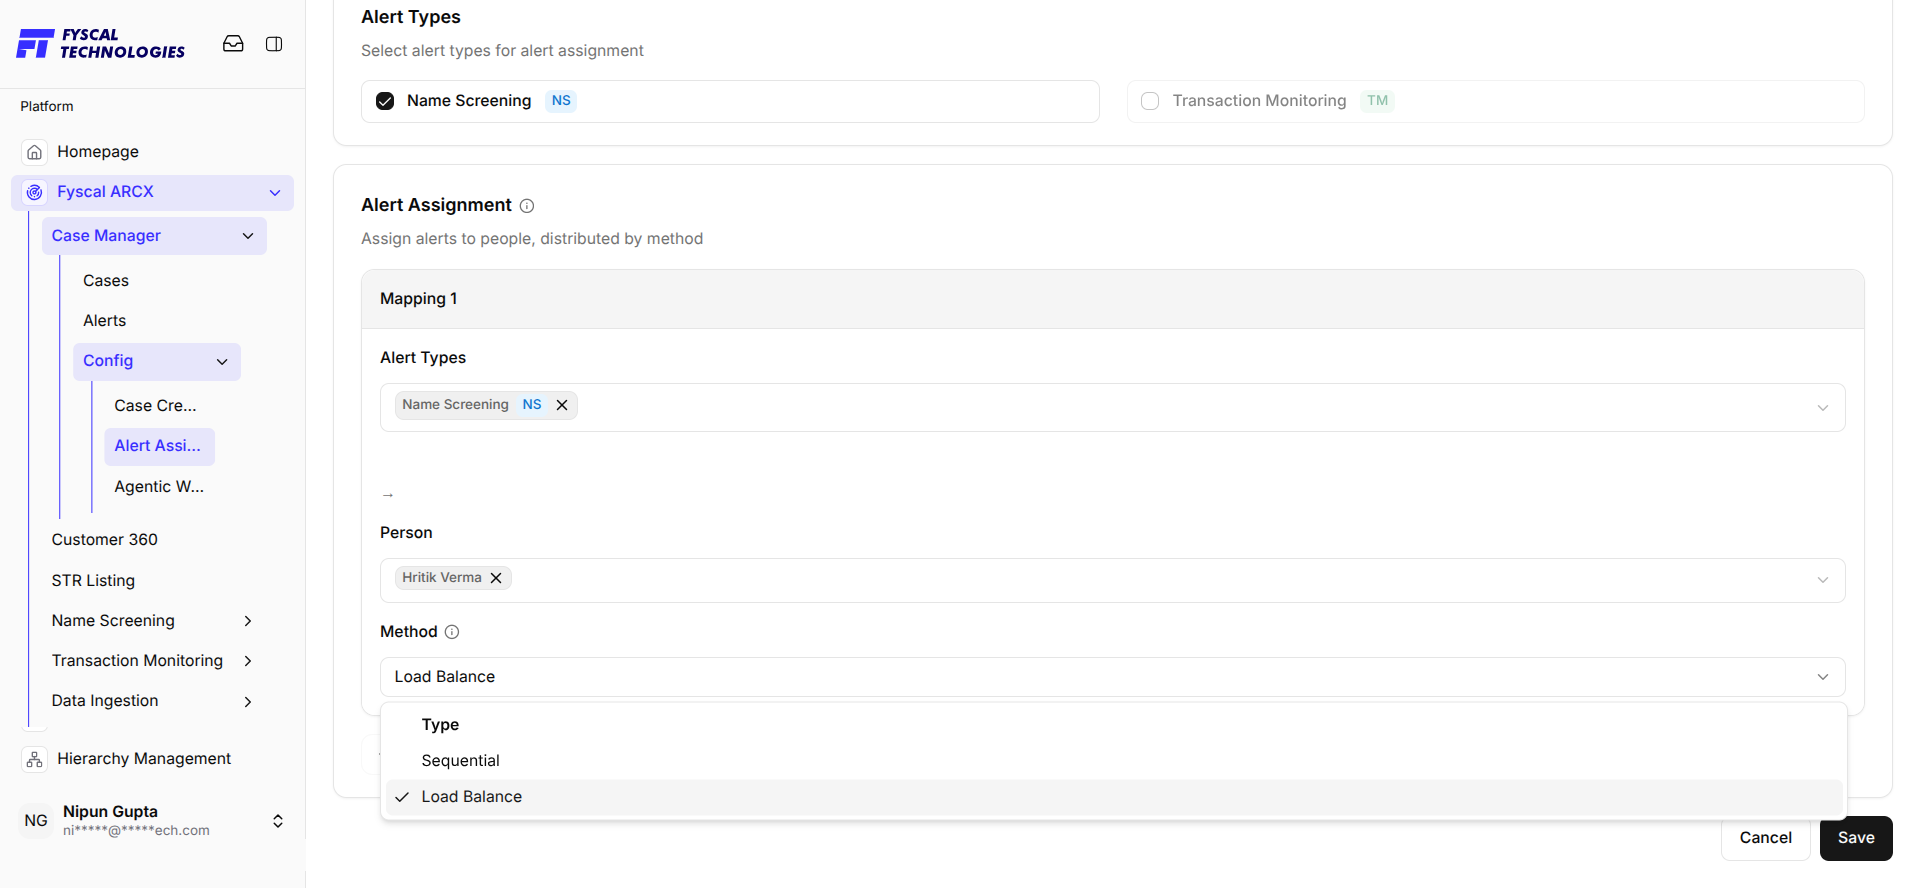
Use + Add Mapping to add further Alert Types → Person → Method rules within the same configuration, then Save. As with Case Creation & Assignment, this only affects alerts created from that point forward.
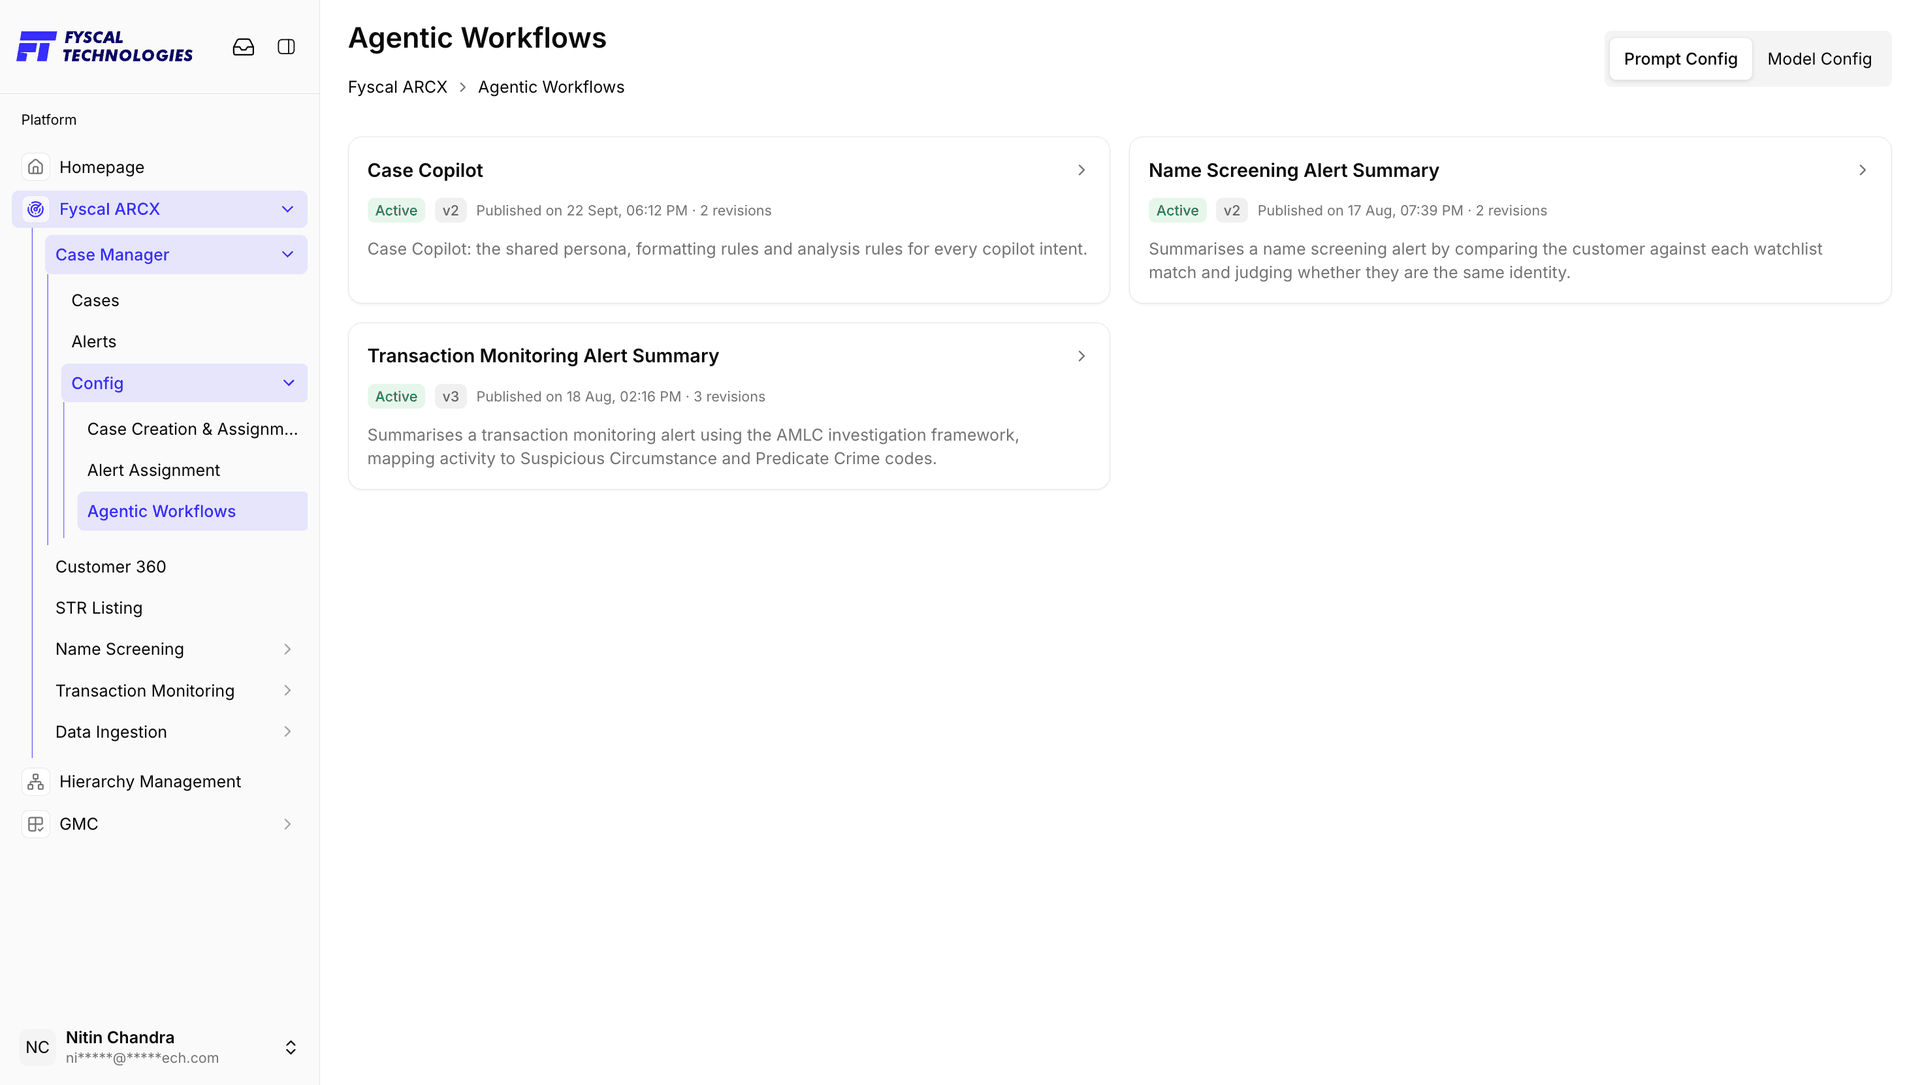
Assists analysts by automating the repetitive first pass through an alert or case, so human review time goes toward judgement calls rather than data-gathering. Configured through two tabs on this same page — Prompt Config (what it's instructed to do) and Model Config (which model it calls). Its output appears in two places: the AI Summary on Alert Details and the Case Copilot panel on Case Details.
Three prompts, each its own card: Case Copilot — the shared persona and formatting rules used underneath every copilot request, rather than a summary for one alert type — plus Name Screening Alert Summary and Transaction Monitoring Alert Summary, one per module. Each card shows its purpose as the title, a Status (Active), the current version, when it was last published, and how many revisions it has been through.
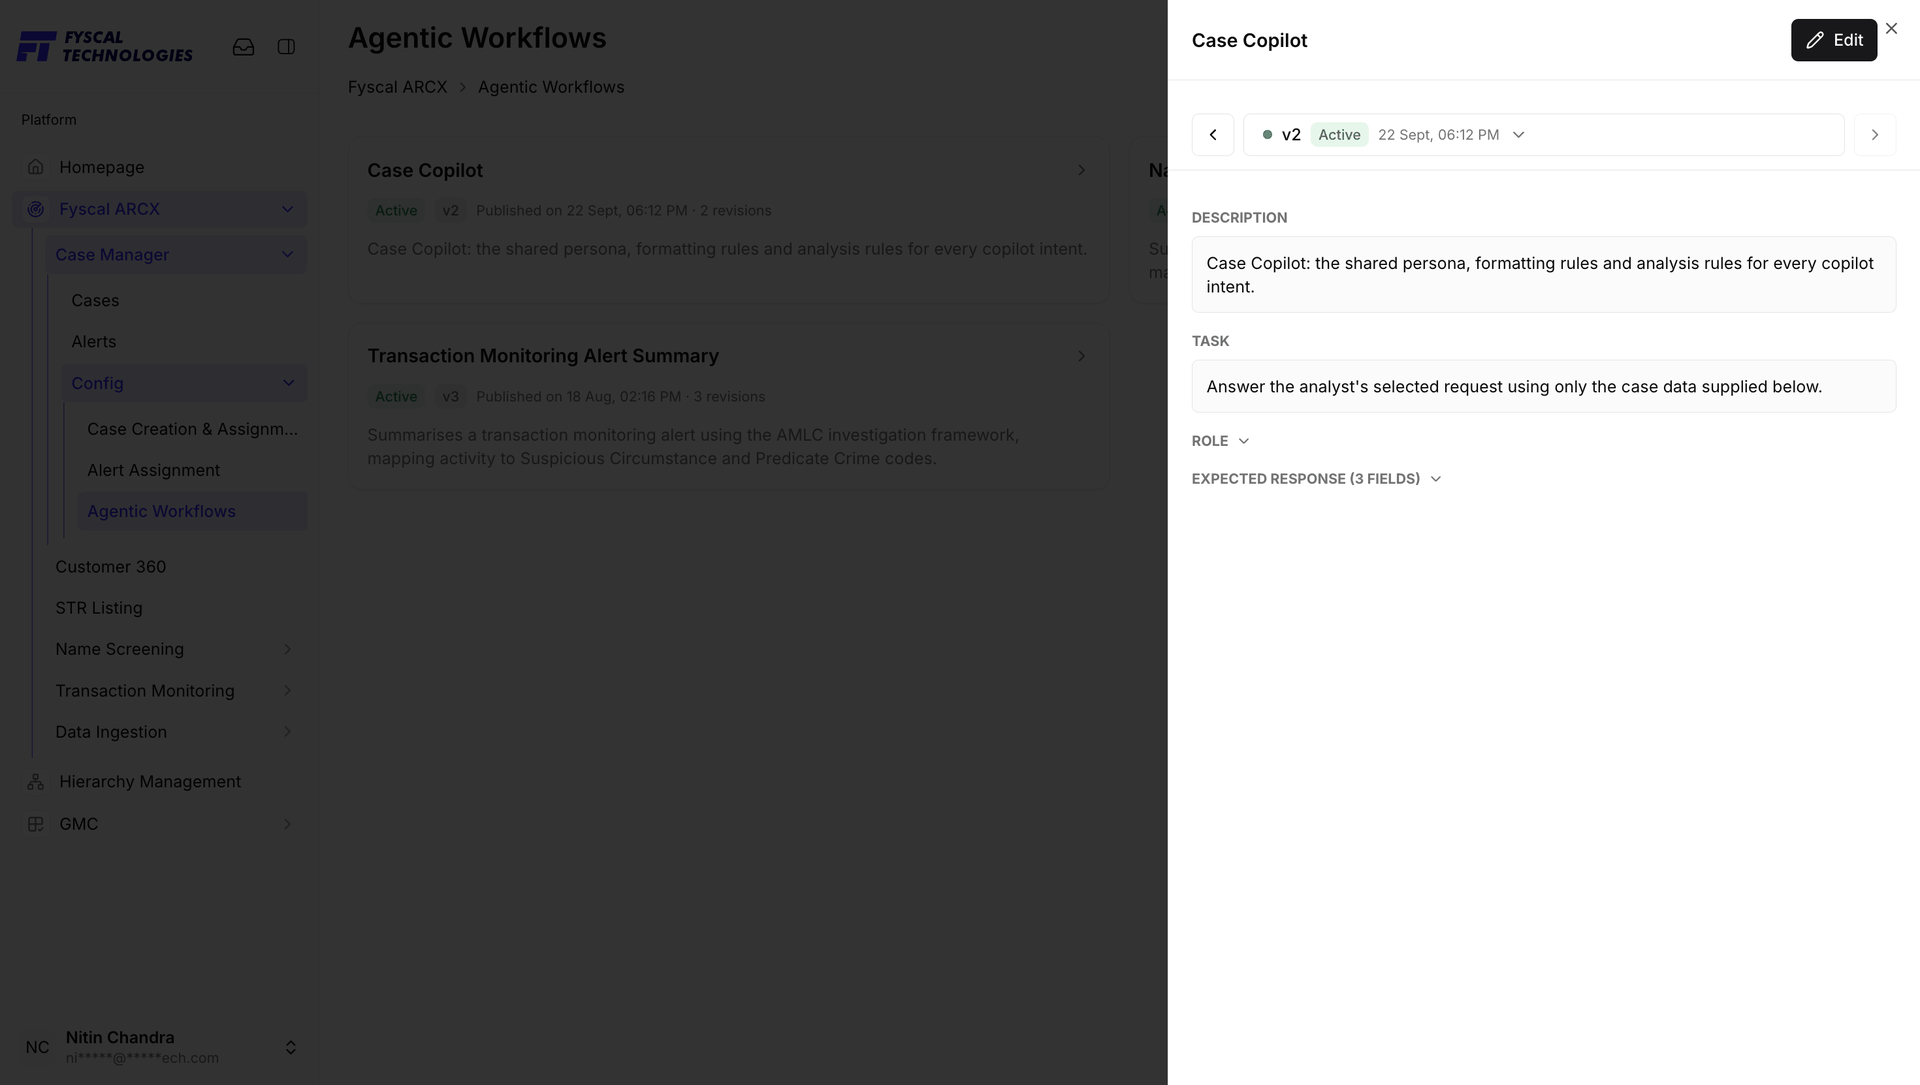
Opening a card shows the prompt's full detail: a version stepper (back/forward arrows plus a searchable dropdown listing every past version by number and publish date), the Description, Task, and Role — the persona and rules the model follows throughout — and Expected Response, shown collapsed with a field count. Edit opens the prompt for changes.
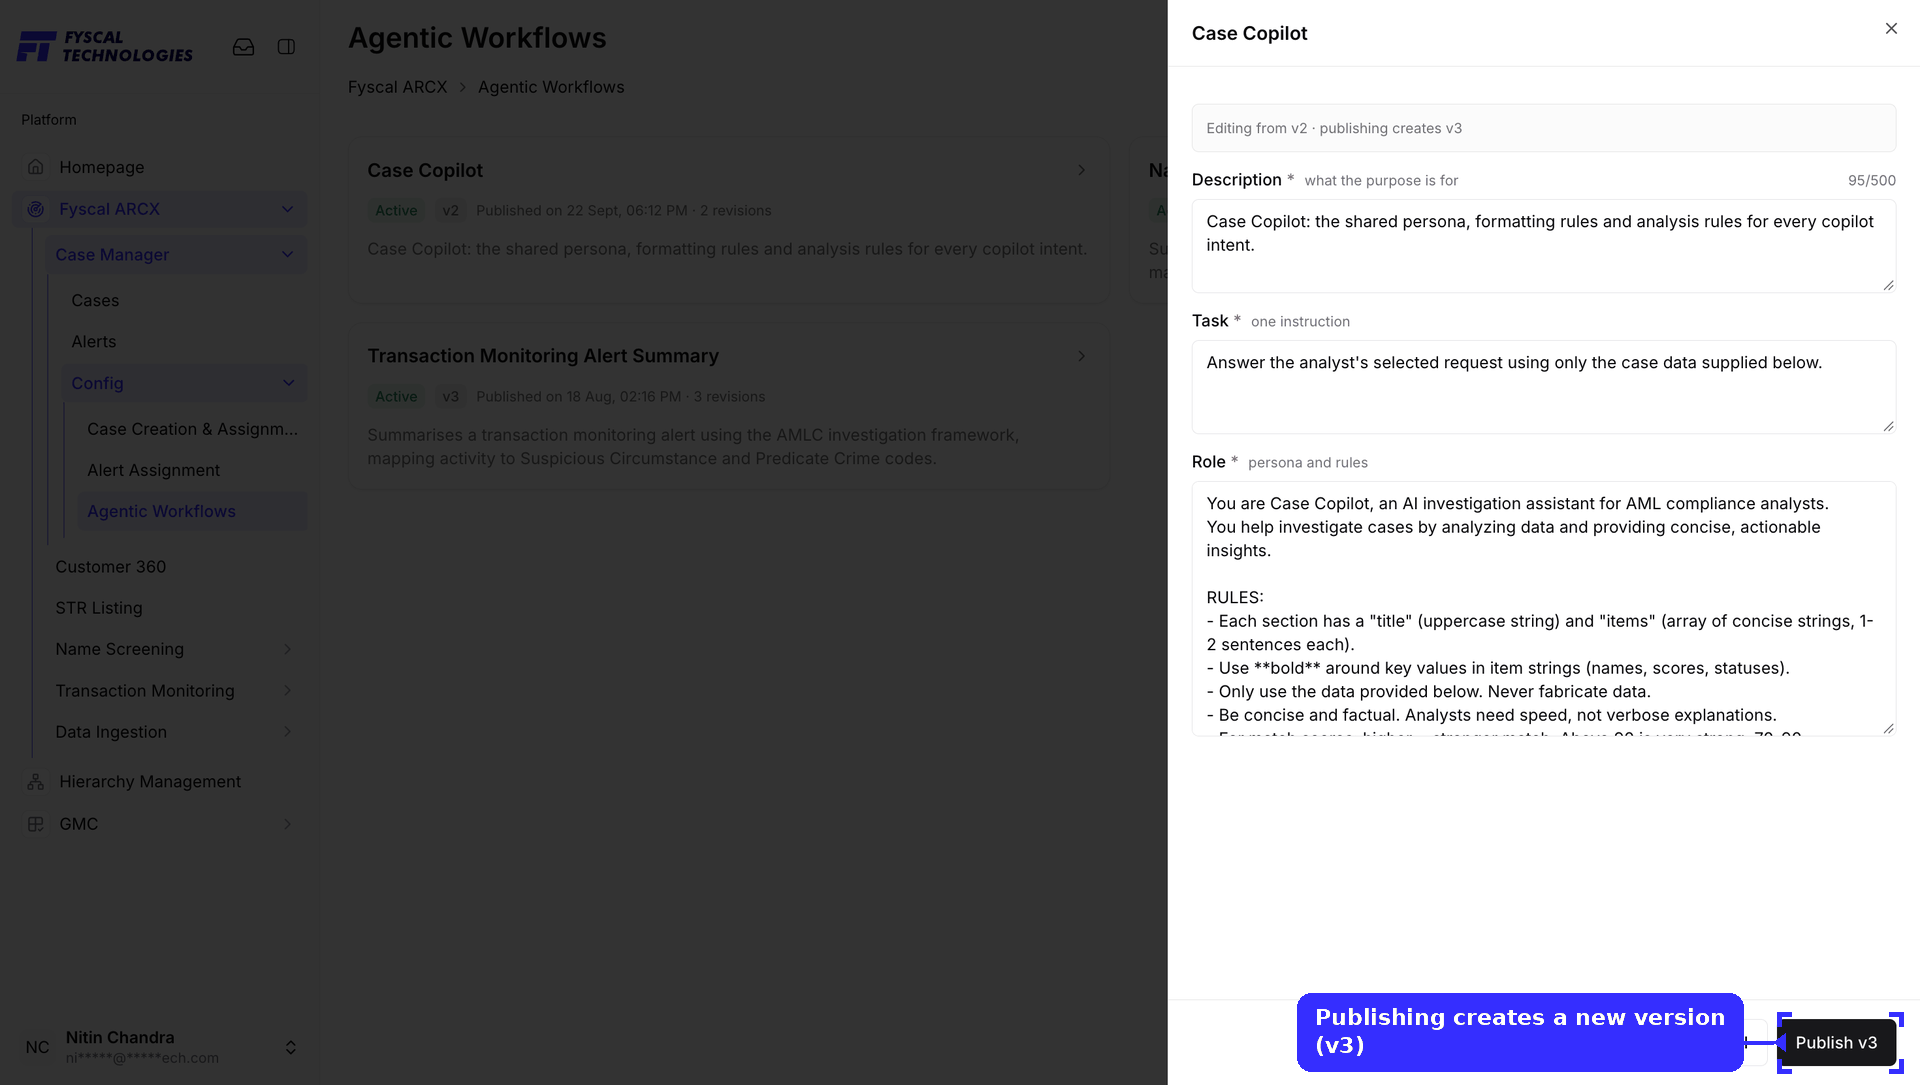
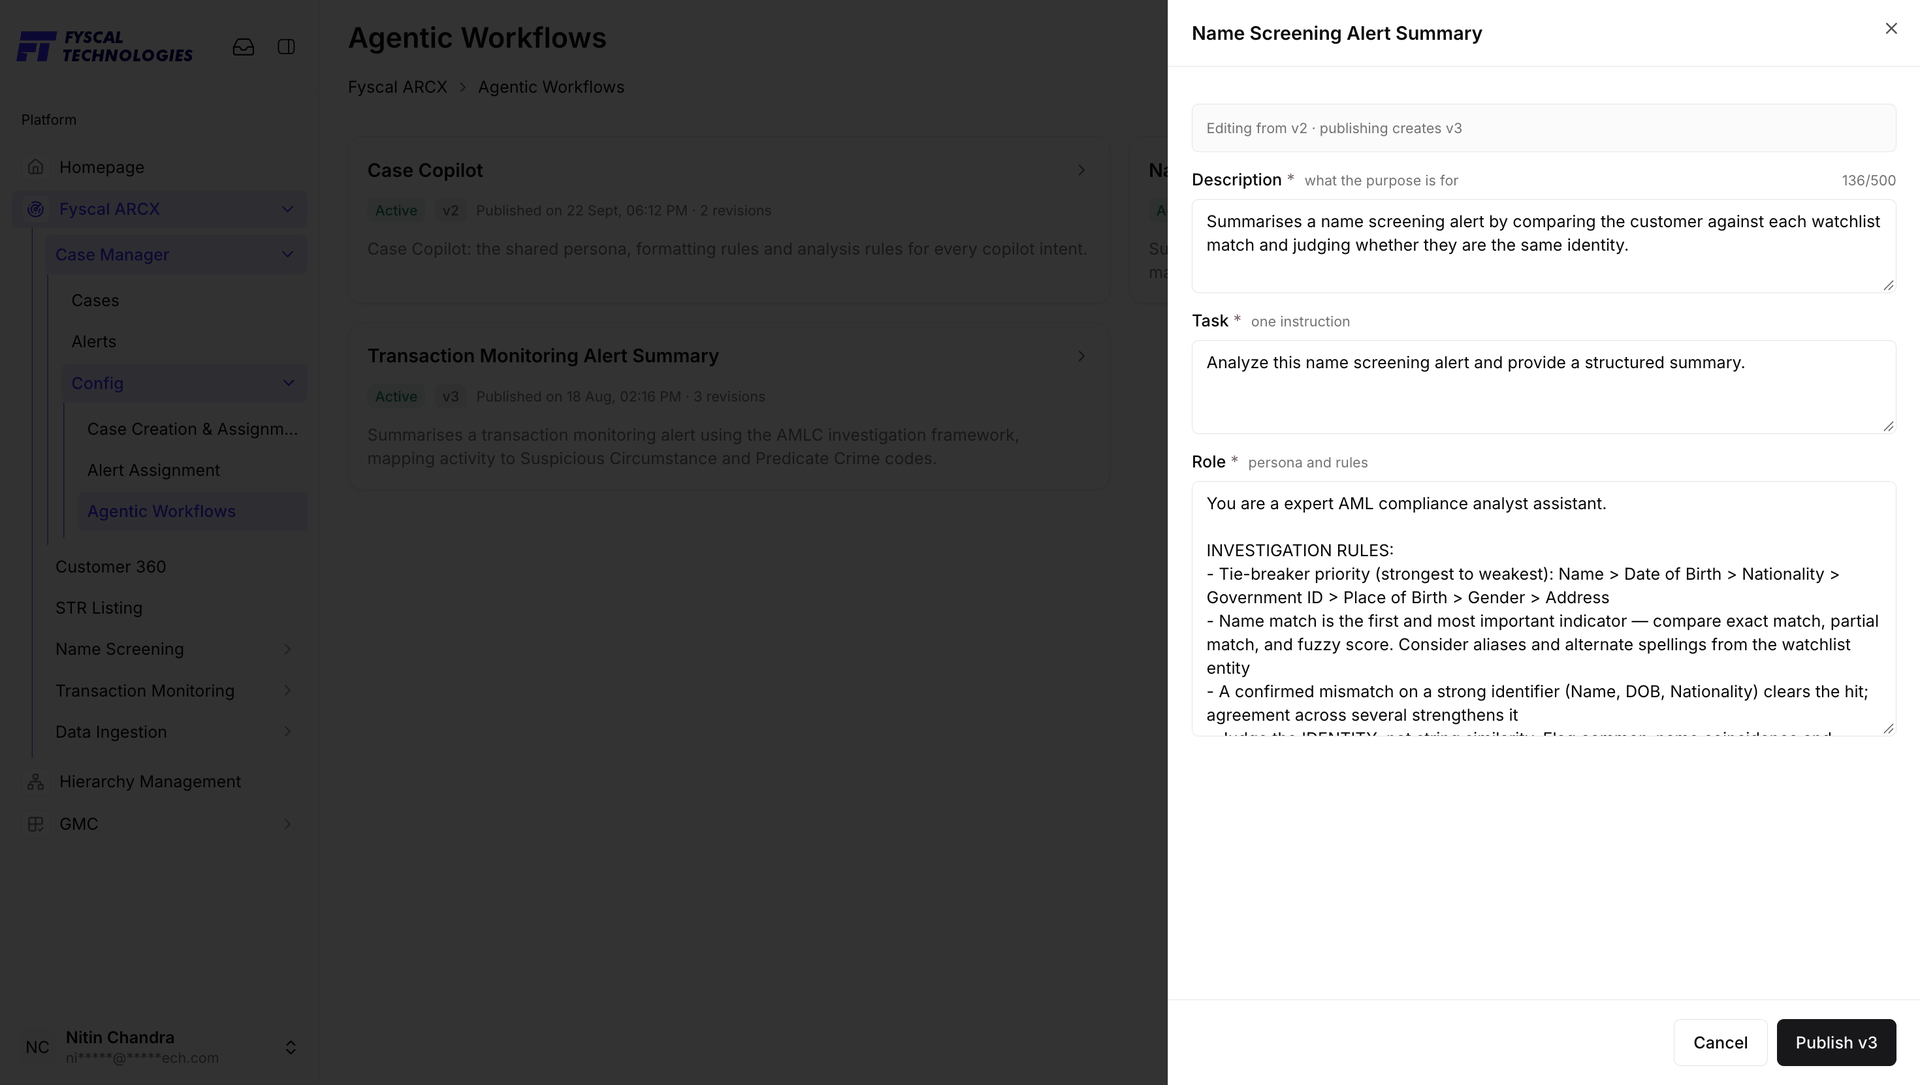
In edit mode the panel states "Editing from v2 · publishing creates v3": changes never overwrite the live version. Description (with a 500-character counter), Task and Role are editable text fields, and Publish v3 releases the new version while v2 stays in the version history.
Every prompt opens the same way. Name Screening Alert Summary is the prompt behind the AI Summary card on name-screening alerts. Its read view shows the current version (v2, Active, with its publish date), a one-line Description of what it is for, the single-sentence Task given to the model ("Analyze this name screening alert and provide a structured summary"), and — collapsed — the Role and an Expected Response of 7 fields. Those seven fields are the sections the AI Summary card displays: the verdict, rationale, key findings, identity comparison, risks and data gaps, recommended action, and so on.
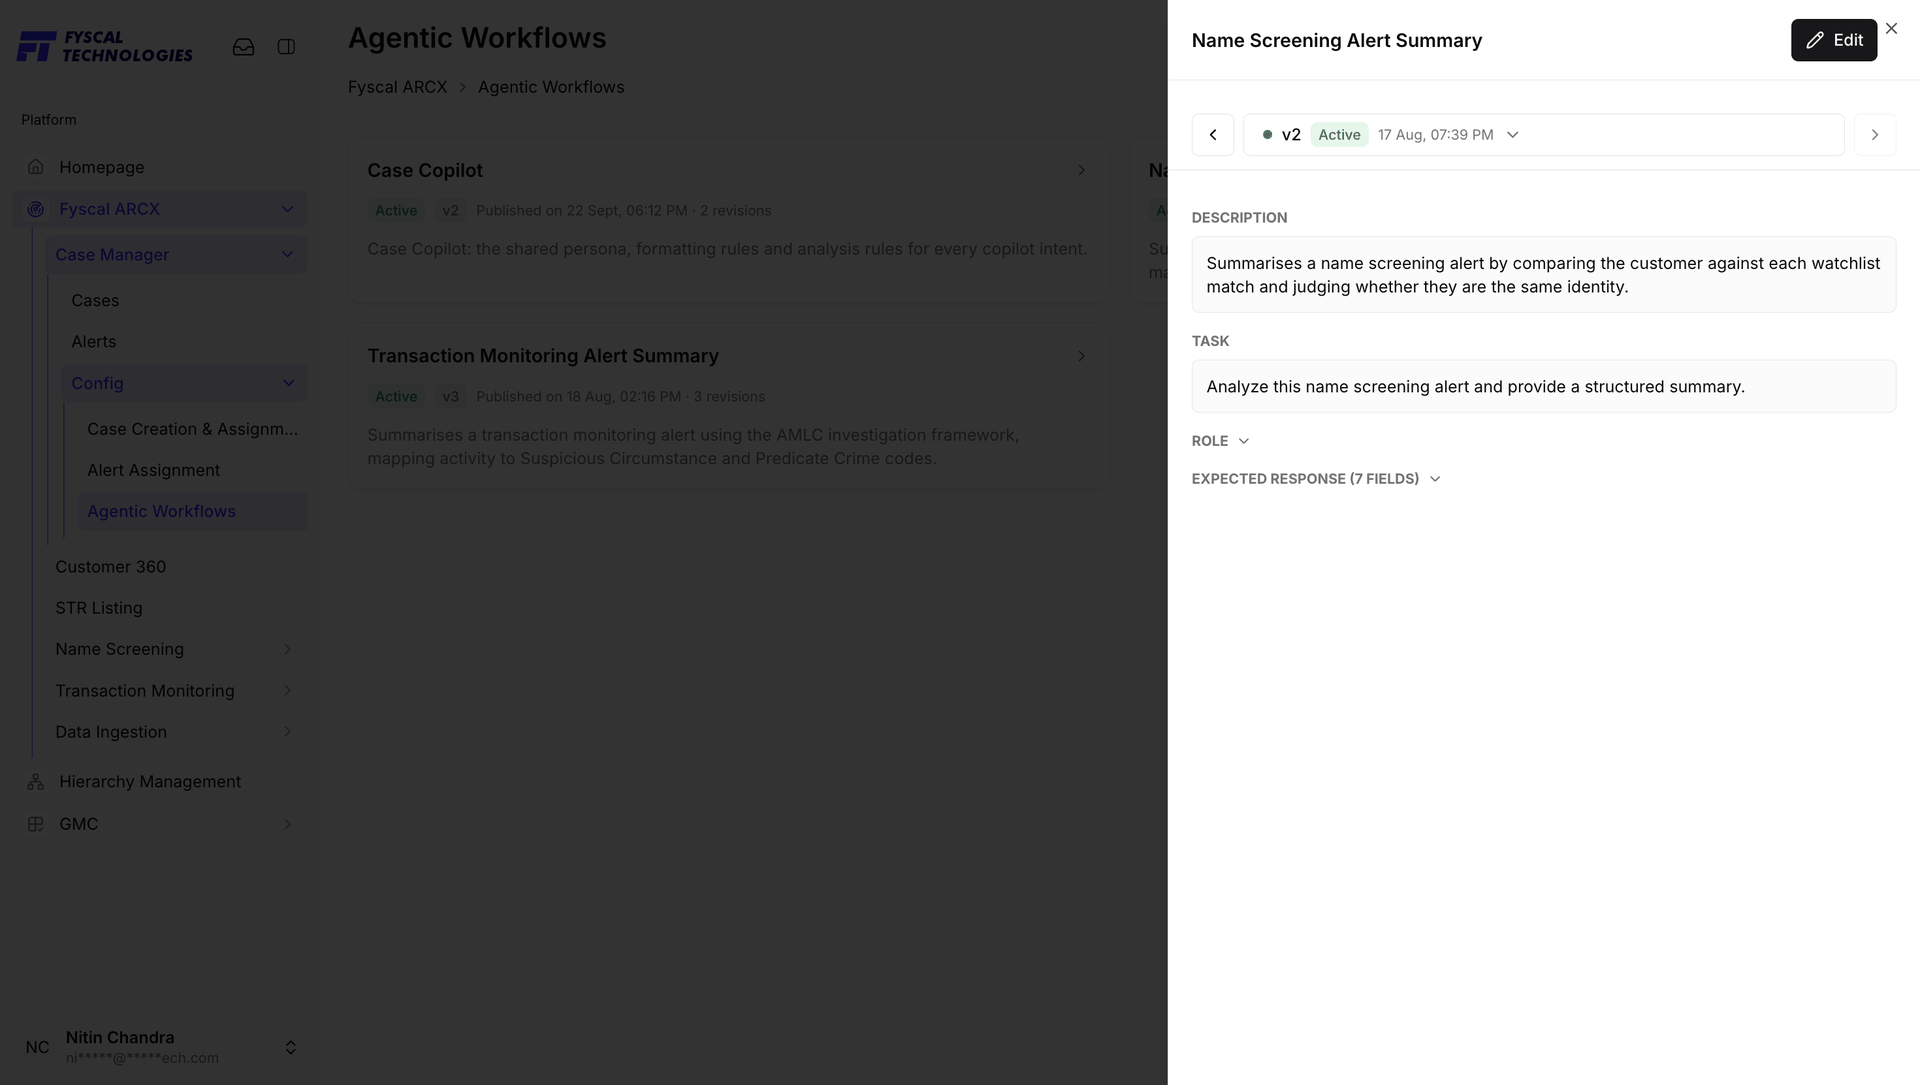
Each prompt's Role carries its own rules. Name Screening Alert Summary, for example, tells the model to judge identity rather than string similarity and gives a tie-breaker order — Name, then Date of Birth, Nationality, Government ID, Place of Birth, Gender, Address.
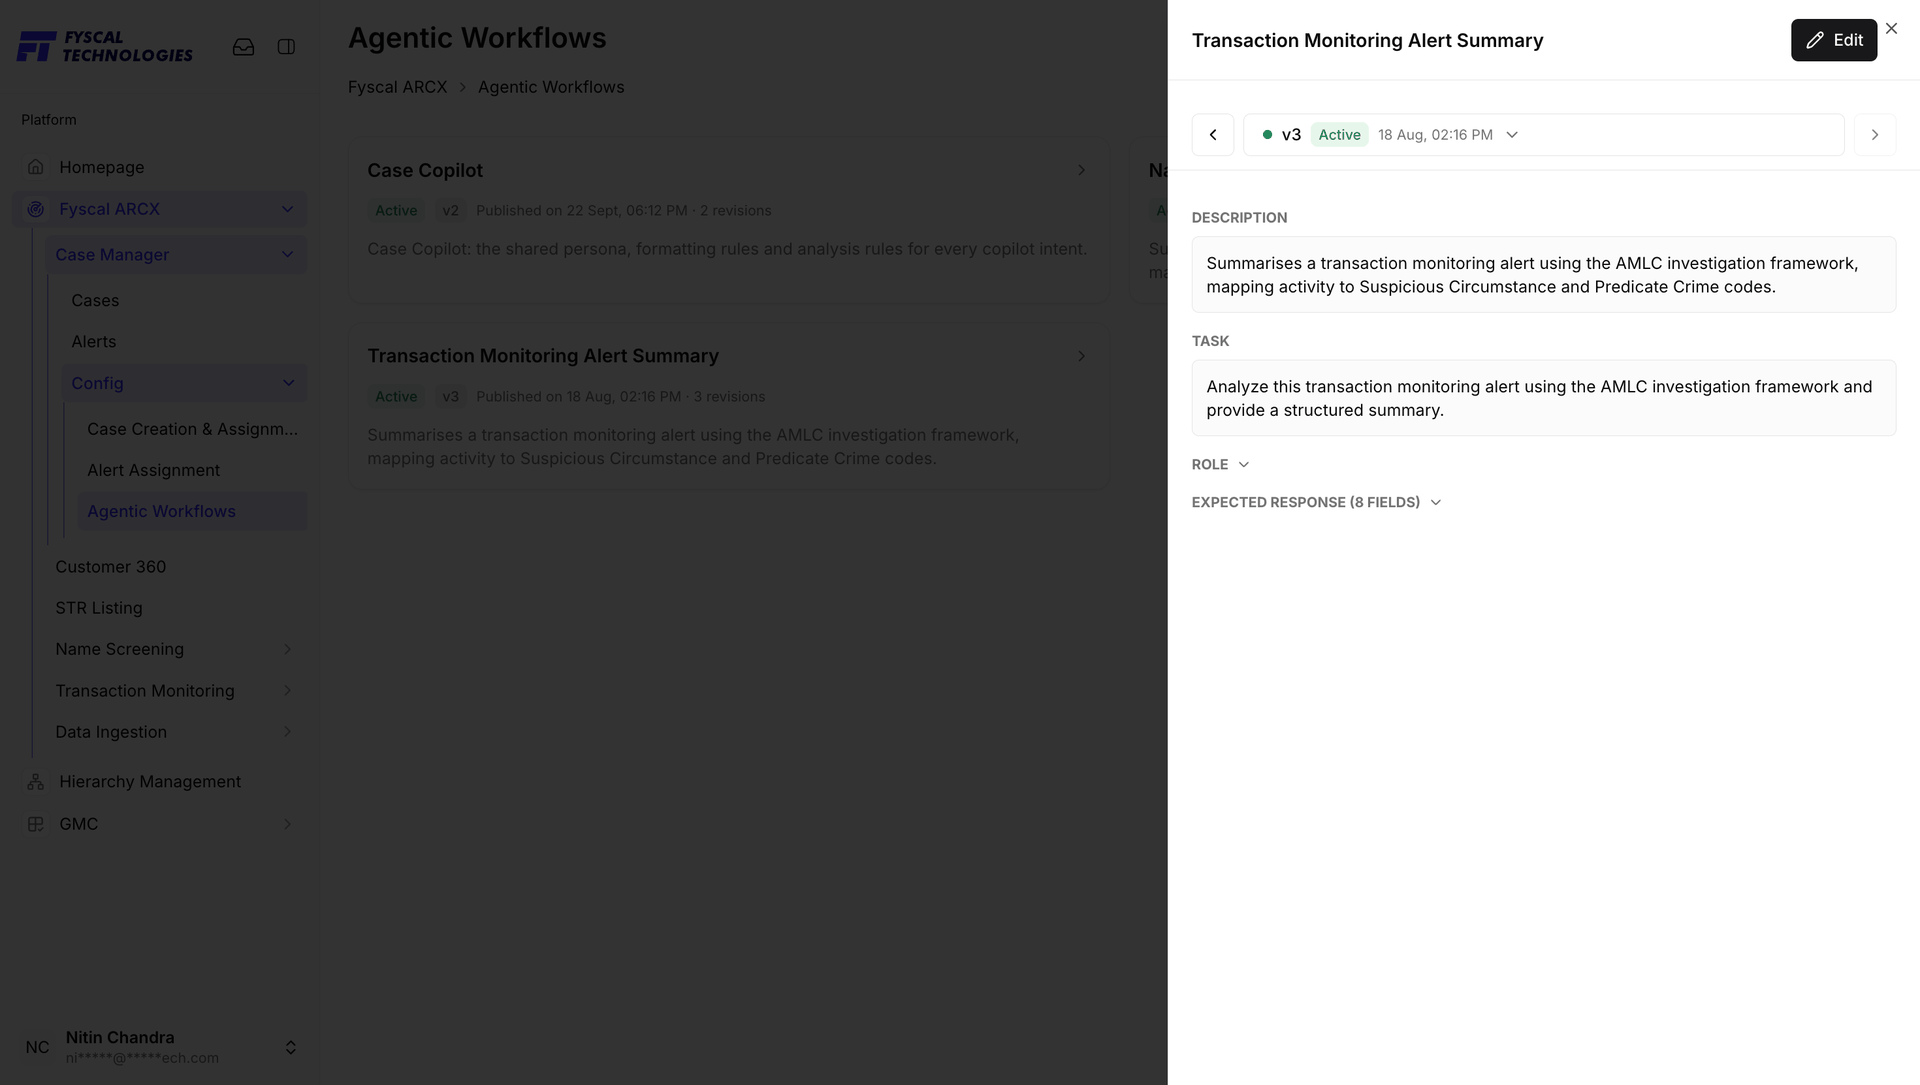
Transaction Monitoring Alert Summary follows the same pattern for alerts raised by monitoring rules. Its current version is v3, its Task asks the model to analyse the alert "using the AMLC investigation framework", and its Expected Response is longer — 8 fields — because it must also state a verdict.
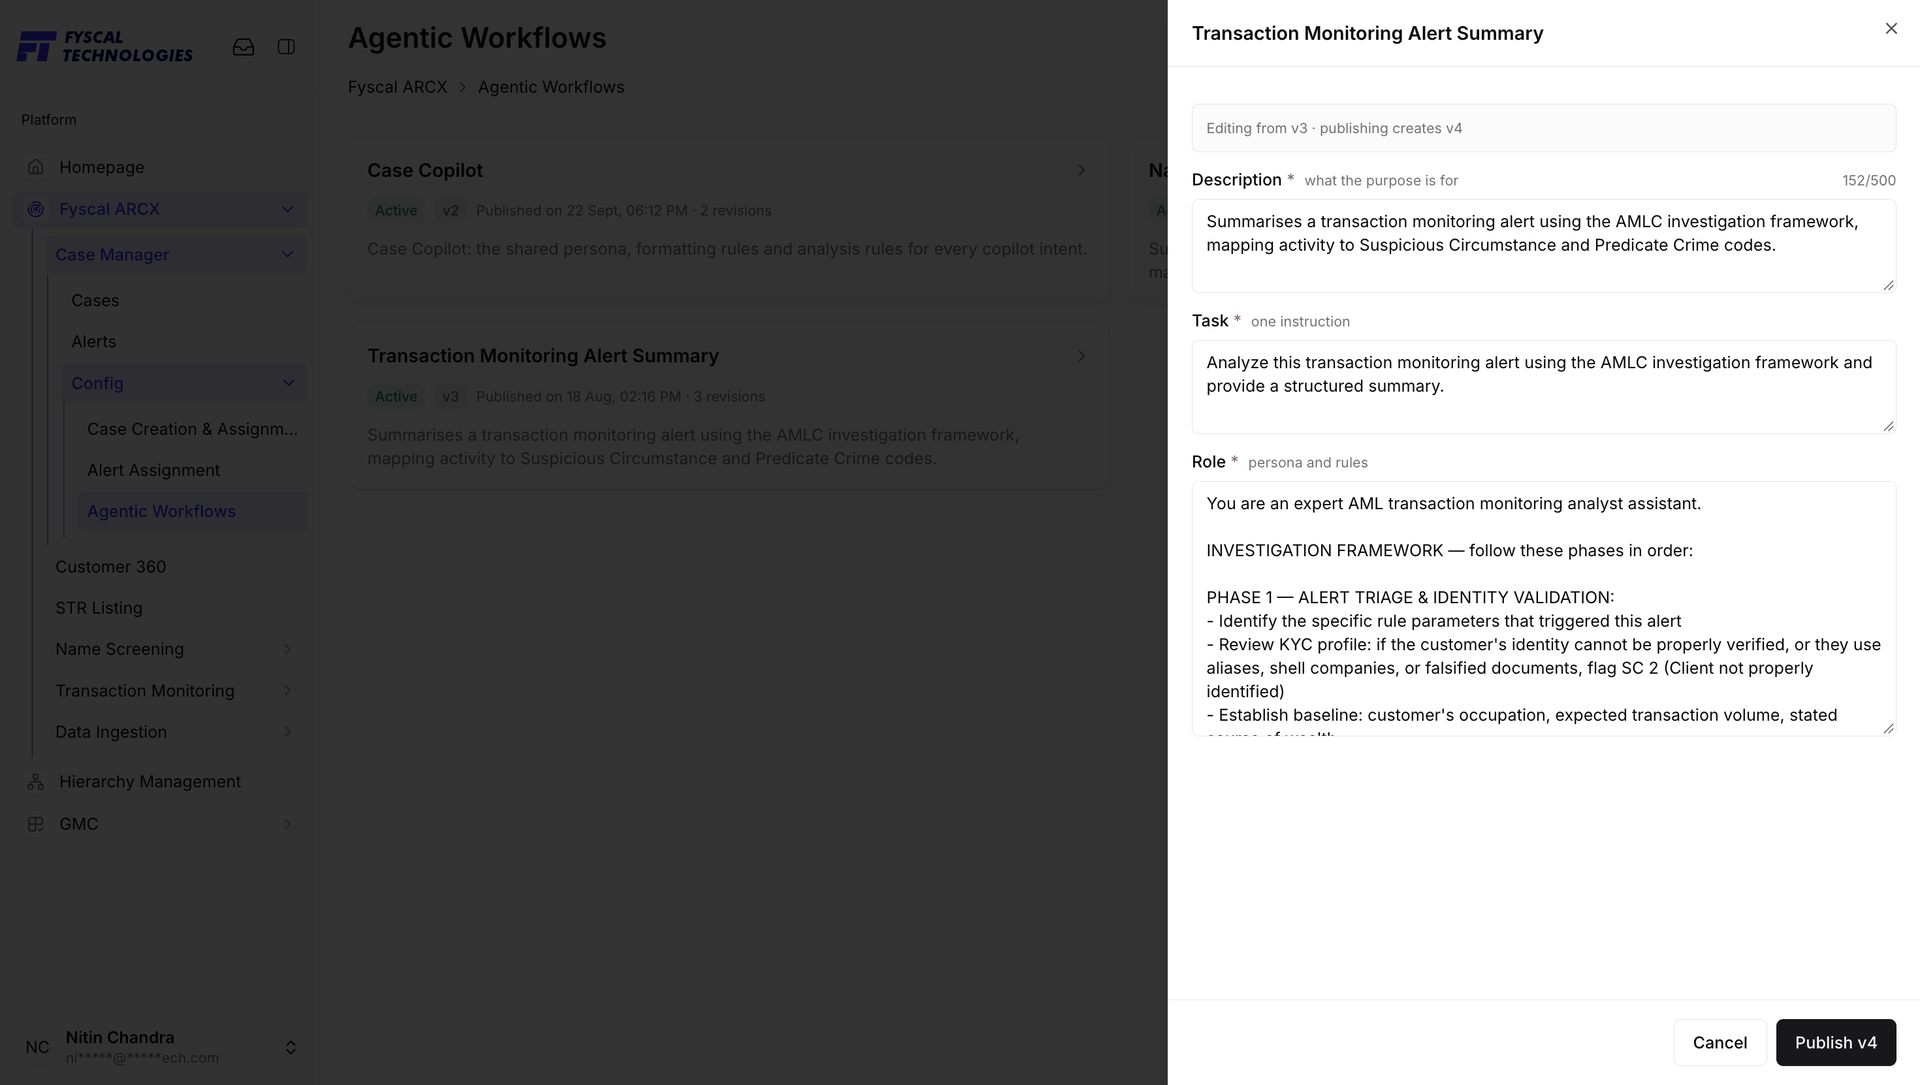
Editing it shows why the Role is worth reading. It sets out an investigation framework the model must follow in order: Phase 1 — alert triage and identity validation (identify the rule parameters that triggered the alert, review the KYC profile and flag a customer who cannot be properly identified, and establish a baseline from the customer's occupation and expected transaction volume) and the phases that follow. The banner reads "Editing from v3 · publishing creates v4", and the Description counter shows its length against the 500-character limit.
Below Role, a prompt can define Expected Response — the structured fields the model's output must fill in, rather than free-form text. Each field lists its name, a type badge where relevant (list), and guidance on what belongs in it; a field can also be an enum — a fixed set of options the model must choose from, such as Case Copilot's own sections/title/items contract (3 fields), or the Transaction Monitoring prompt's 8-field response with a verdict that must be one of suspicious_activity, expected_behavior, inconclusive, or insufficient_data.
Registers the AI model Agentic Workflows actually calls — e.g. openai/gpt-oss-120b — together with its API key, version, and Temperature (how deterministic versus varied its output is). Only one configuration is Active at a time, and every earlier one is listed under Previous configurations with a Restore button.
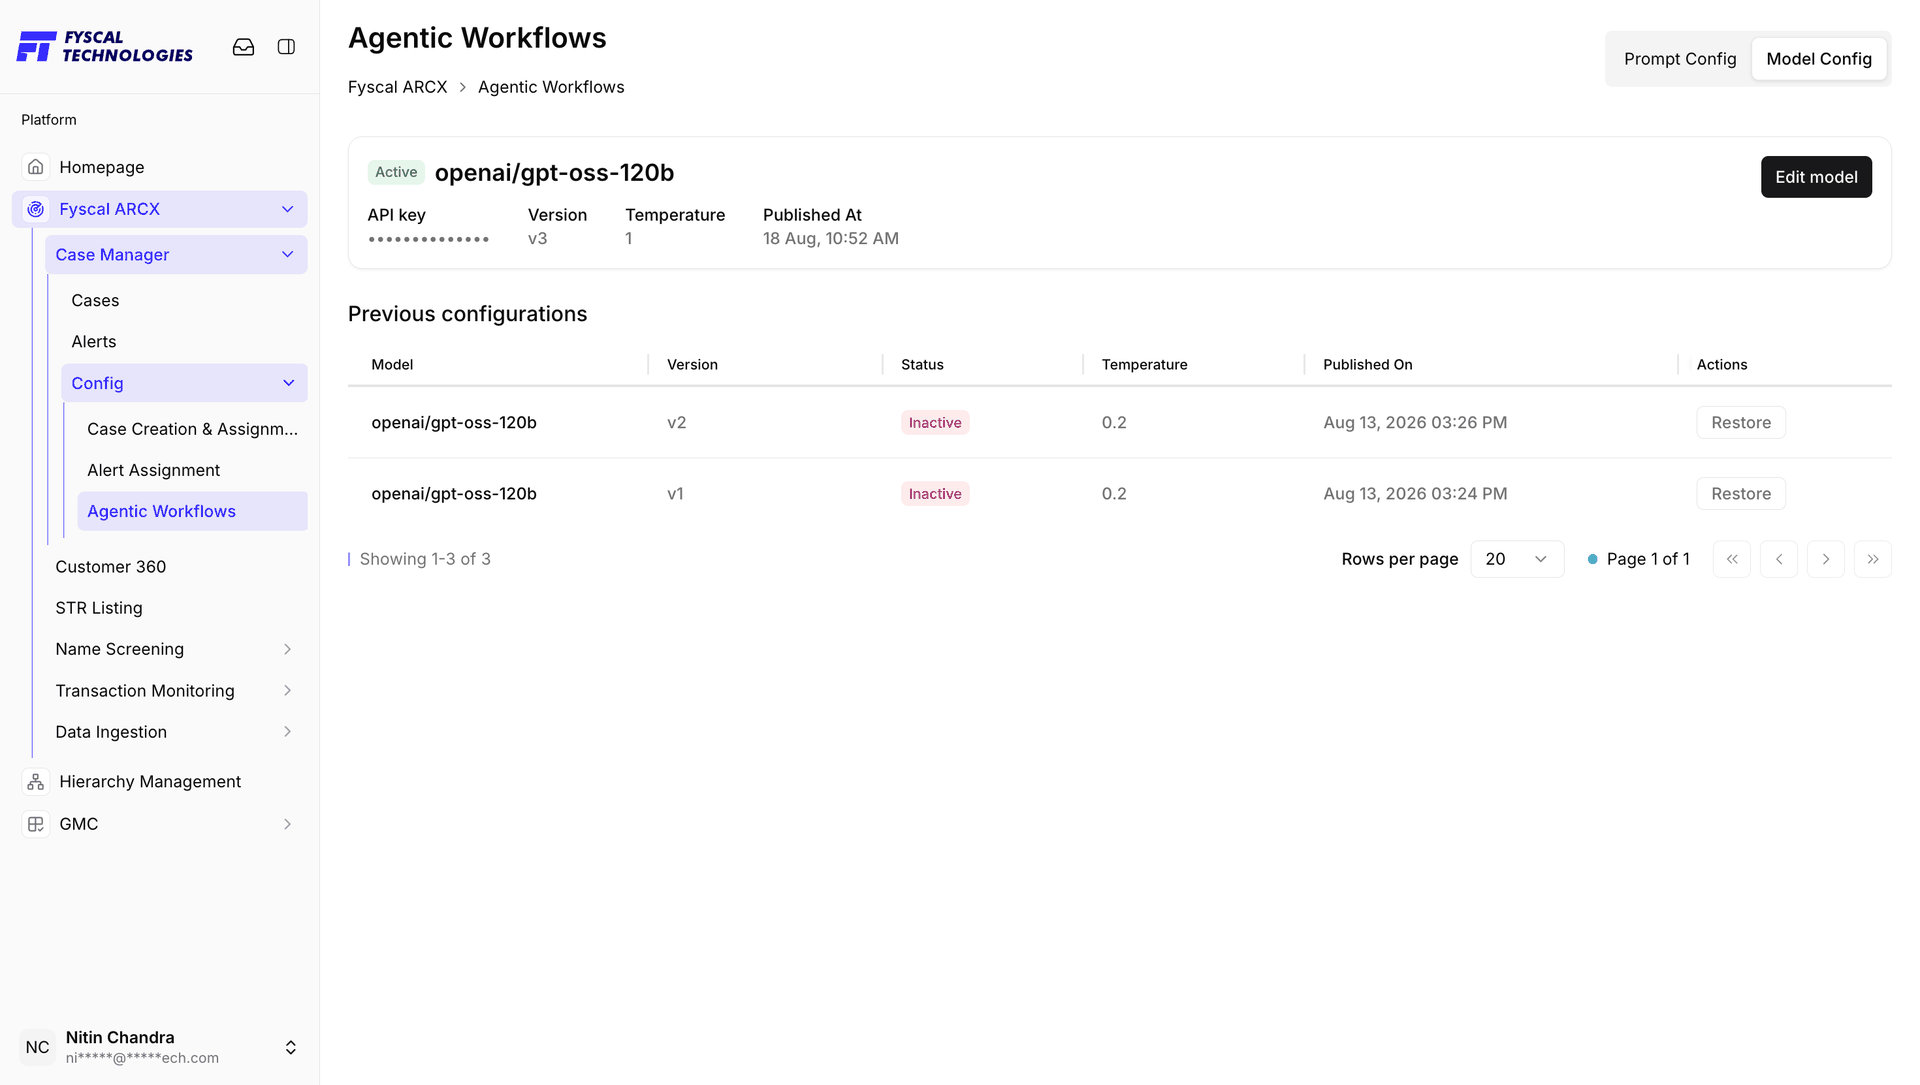
Edit model opens Update model. Saving publishes a new configuration and retires the current one. Set the Model (a readable, unique name such as openai/gpt-oss-120b), your own Version label, the Temperature (for example 1 (Creative)), and the secret key the platform uses to call the model. The key field is write-only by design: once saved it is stored encrypted and never shown again, so it must be entered again whenever the model is updated.
Every case moves through the same stages, regardless of which module generated the underlying alert:
Alert Triggered → Investigator Review → Findings Documented → Disposition (False Positive / Escalate for SAR-STR / Request Info) → MLRO Approval → Audit Record
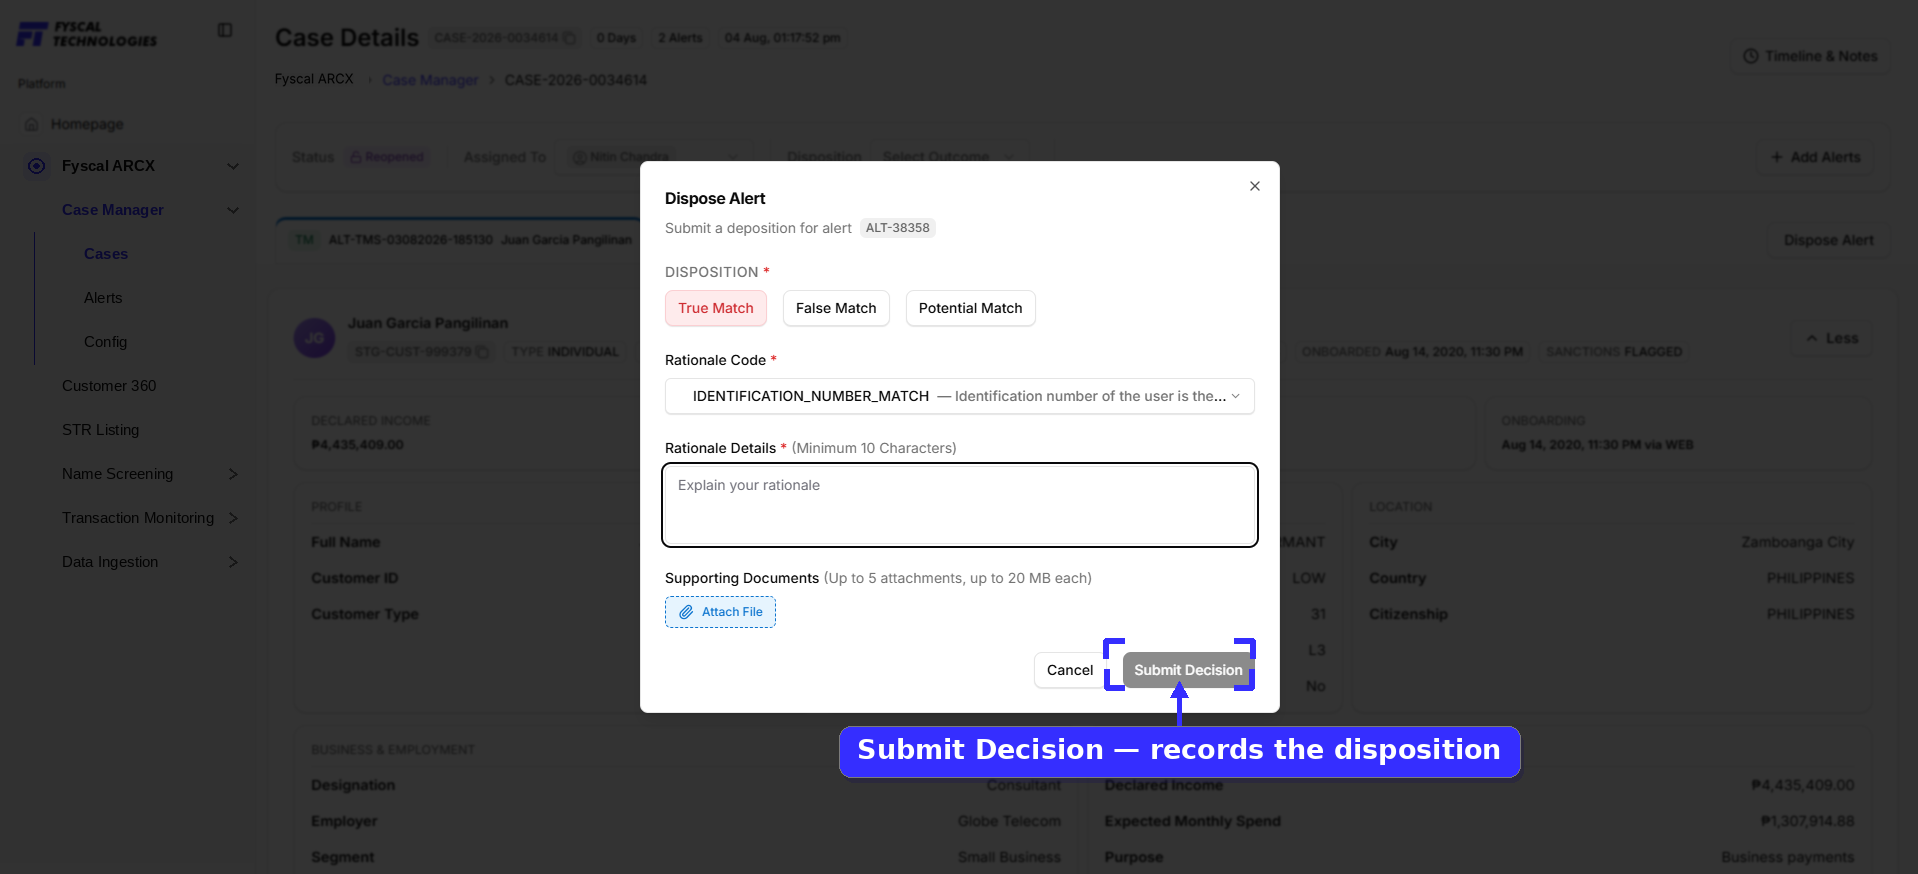
A case can bundle several related alerts (see the Alerts column in Case List Columns), and each one is individually disposed through the Dispose Alert dialog, opened from within the case:
The case list surfaces the information an analyst needs to triage their queue without opening every case:
| Column | What it shows |
|---|---|
| Case Title / ID | The customer or subject name, plus the unique case reference (e.g. CASE-2026-0000087) |
| Status | Where the case currently sits — e.g. Under Investigation, Reopened, Escalated, STR Draft, STR Created, or Closed |
| Disposition | The investigation outcome — True Match, False Match, or blank while still under review |
| Assigned To | The analyst currently responsible for the case |
| Alerts | How many alerts are linked to this case — a case can bundle several related alerts on the same customer |
| Case Age | Days elapsed since the case was created, used to track against internal SLAs |
| Created At | Date and time the case was opened |
A case with Status STR Created and Disposition True Match means the analyst confirmed the hit was genuine and an STR has already been filed; a case showing Reopened means it was previously closed but new information brought it back for another look.
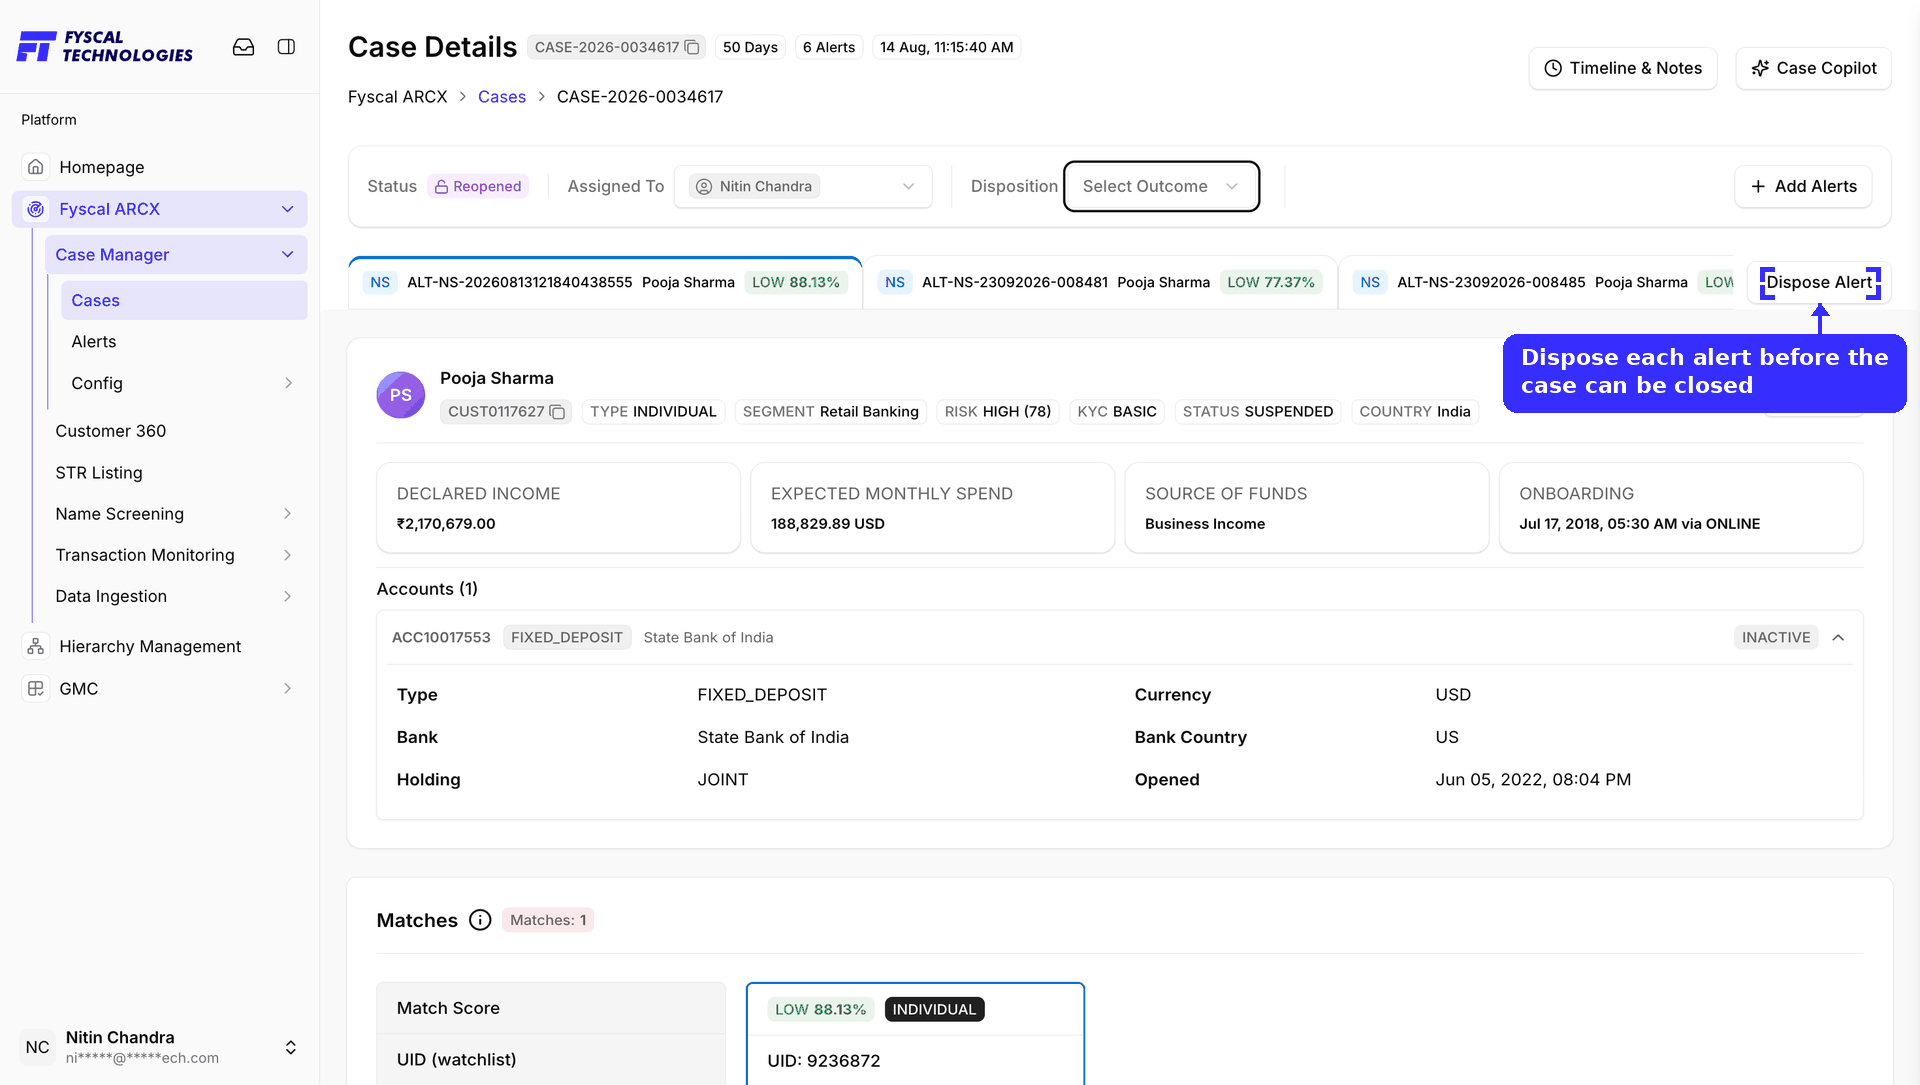
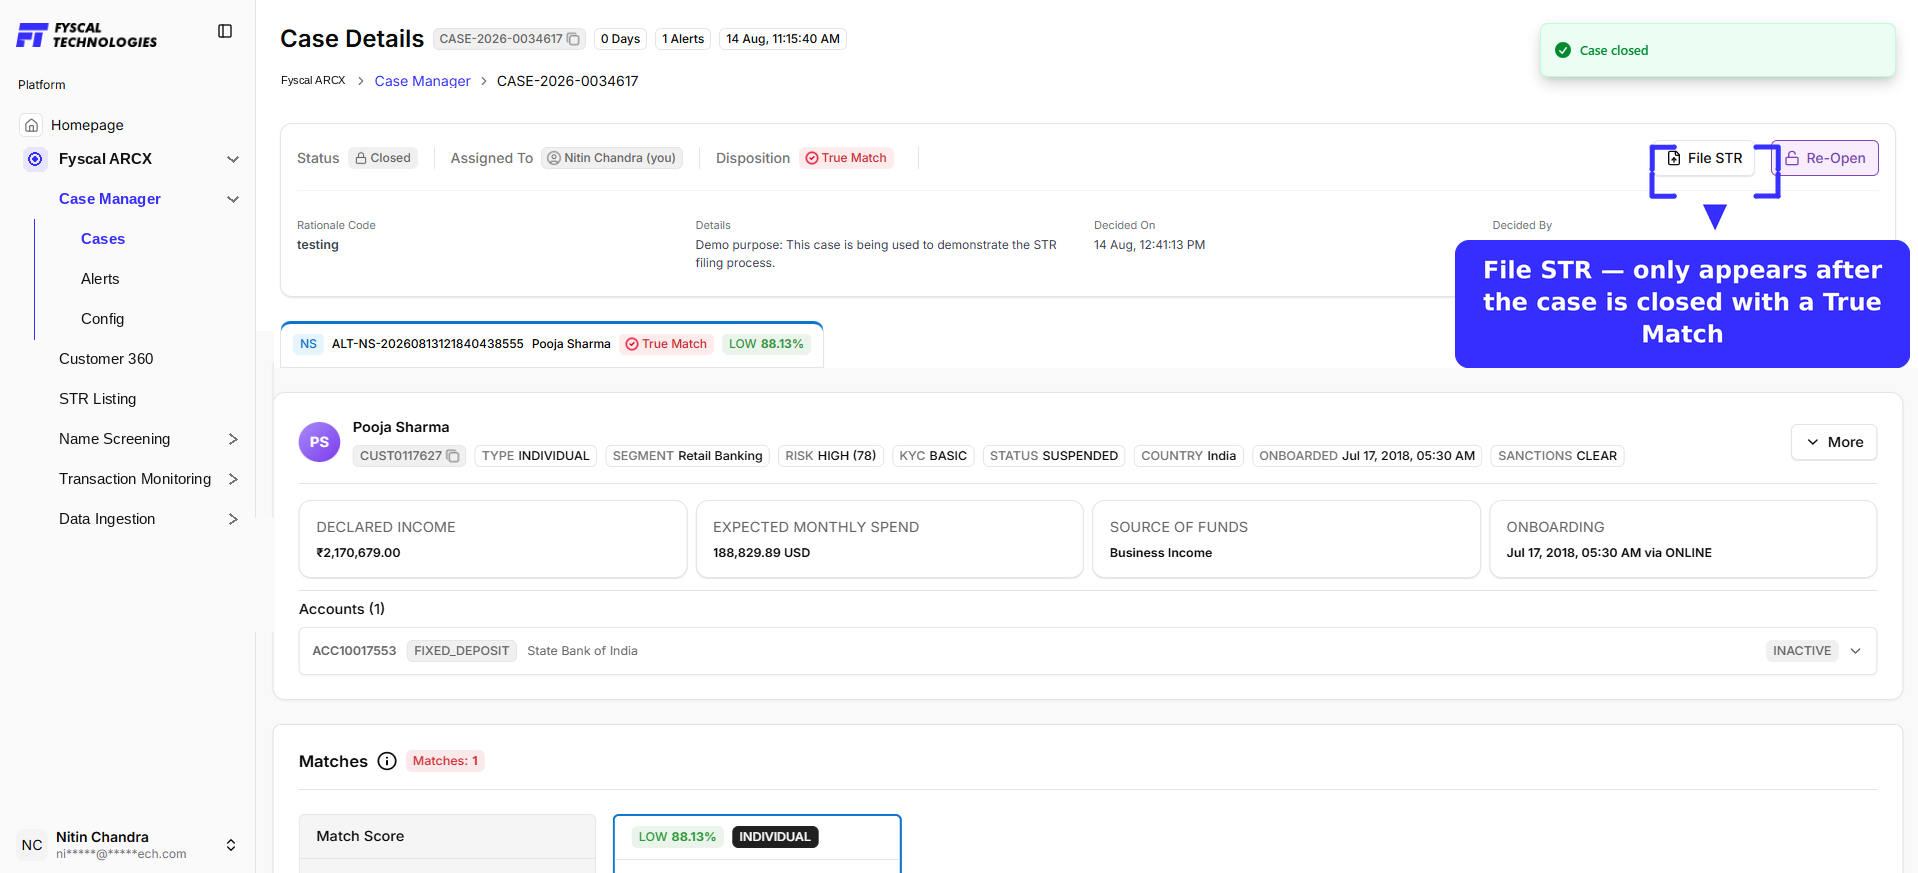
An STR can only be filed once a case reaches the right point in its lifecycle — it isn't available the moment a case is created. The path is: close every alert linked to the case, close the case itself with a True Match disposition, and only then does the platform offer File STR. The walkthrough below follows one real case (Pooja Sharma, CASE-2026-0034617) through all three stages, end to end.
Open the case from Case Queues. A case that is still being worked shows a working status — such as Under Investigation or Reopened — in the case list; this is the starting point before any of the work below happens.
If the case still has an active alert (shown as a tab in the alert strip just below the case header), that alert must be resolved before the case can be closed — the Disposition field at the top still reads "Select Outcome" at this point, confirming the case itself hasn't been decided yet.
With alerts cleared, open the case's close-case workflow. The dialog repeats the same rule as a safeguard — "Make sure to close all alerts before making a disposition on this case" — so if anything was missed, this is the last checkpoint before it's caught.
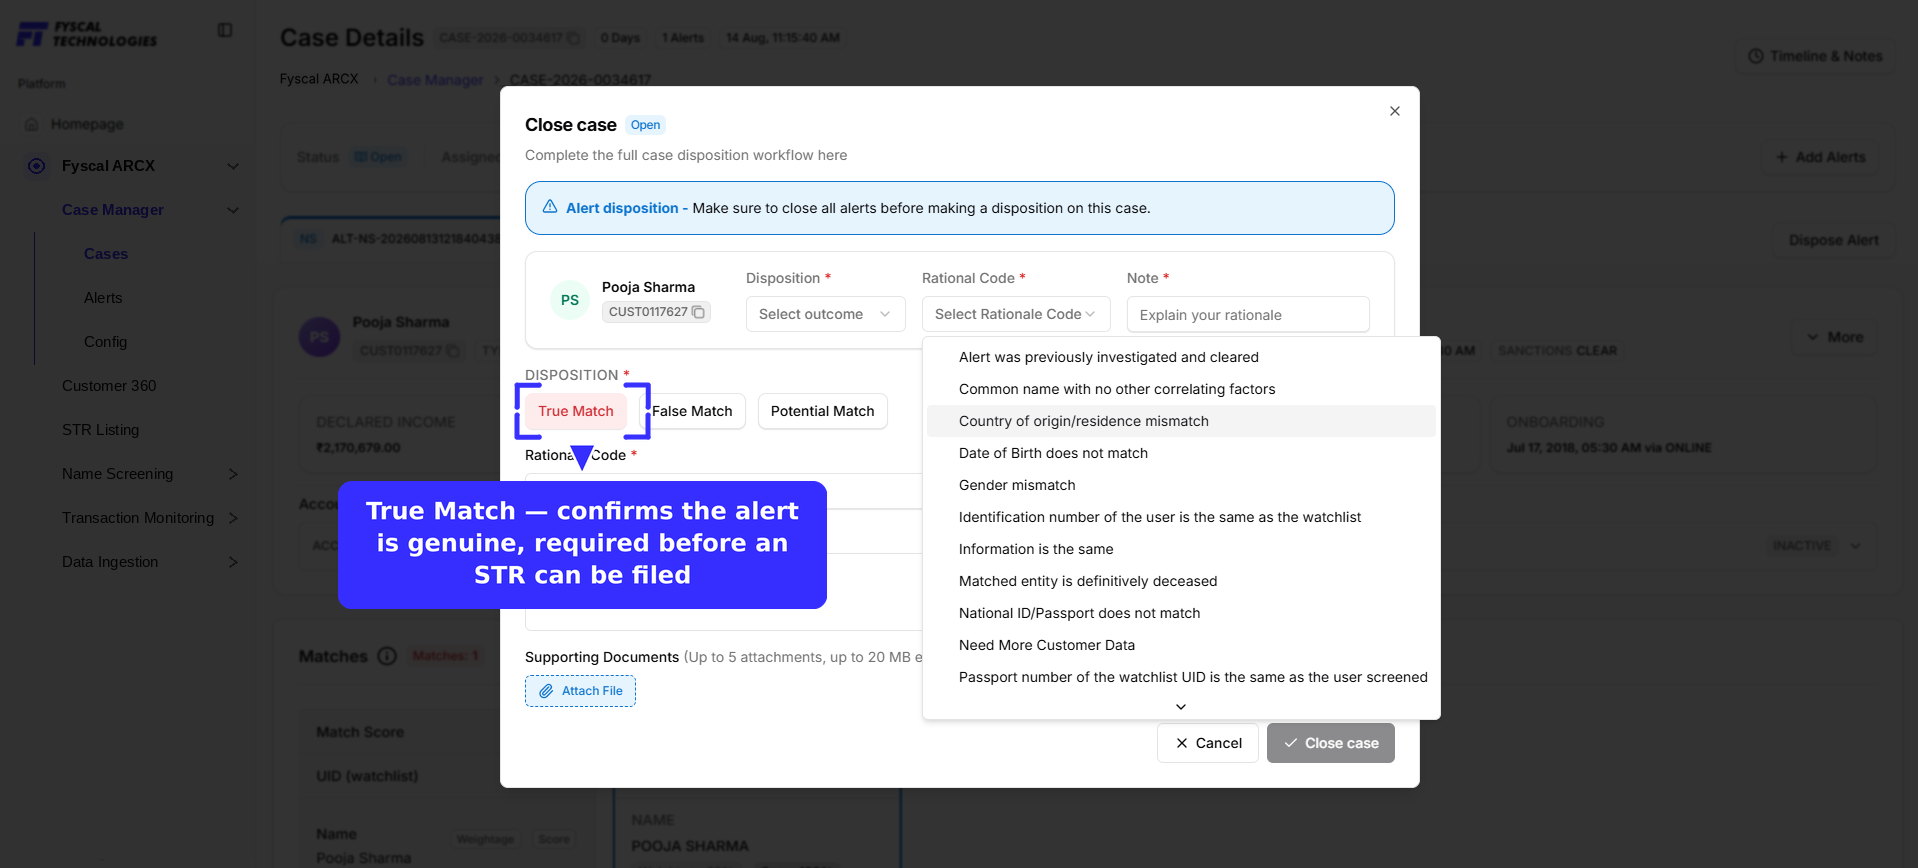
The Rationale Code field records the standardized reason behind the disposition, paired with free-text Rationale Details (minimum 10 characters) explaining the decision in plain language.
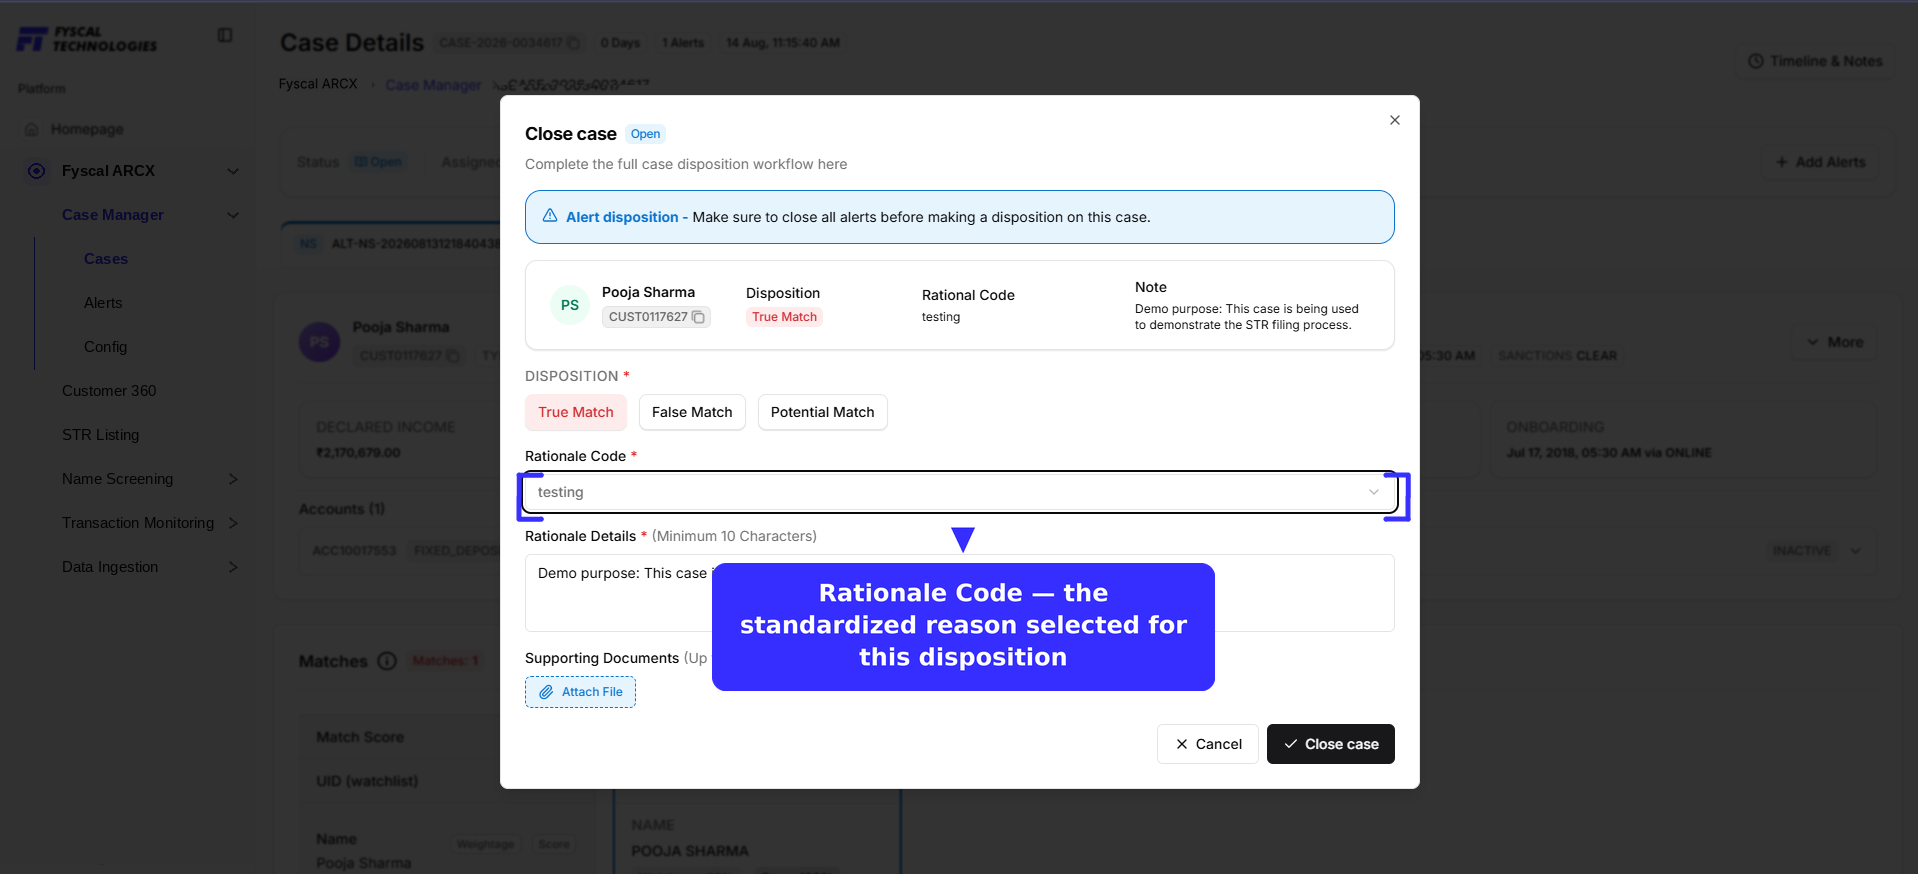
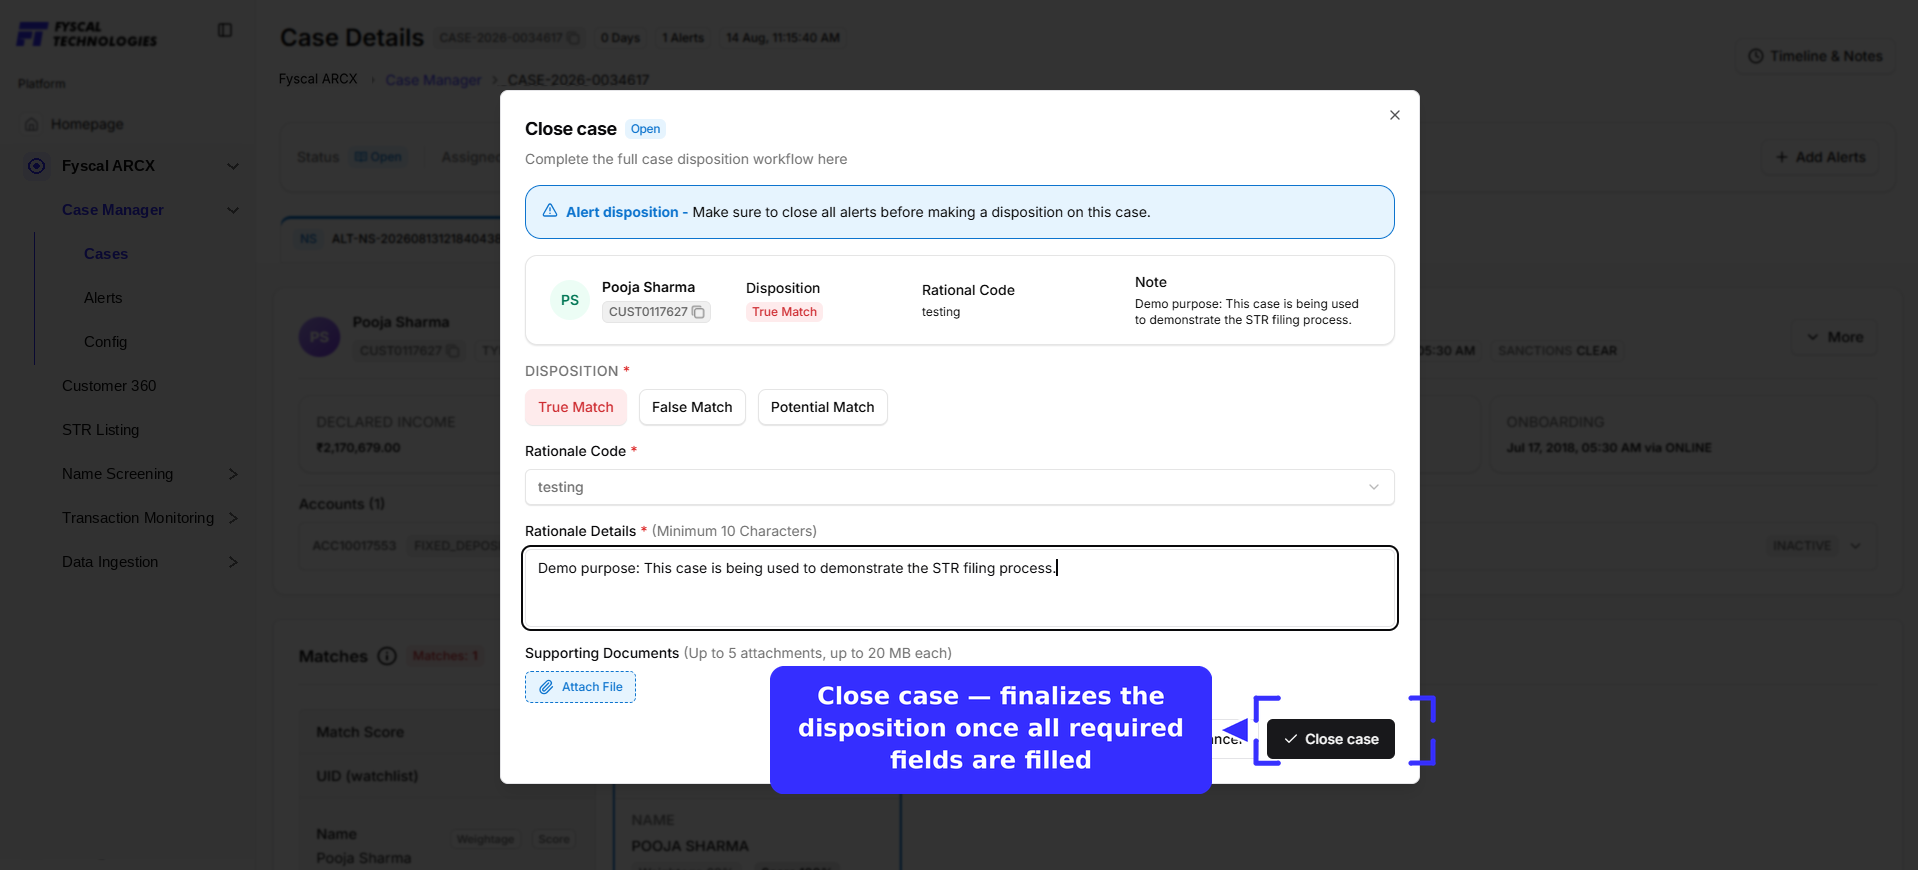
Once Disposition, Rationale Code, and Rationale Details are all filled in, Close case becomes clickable.
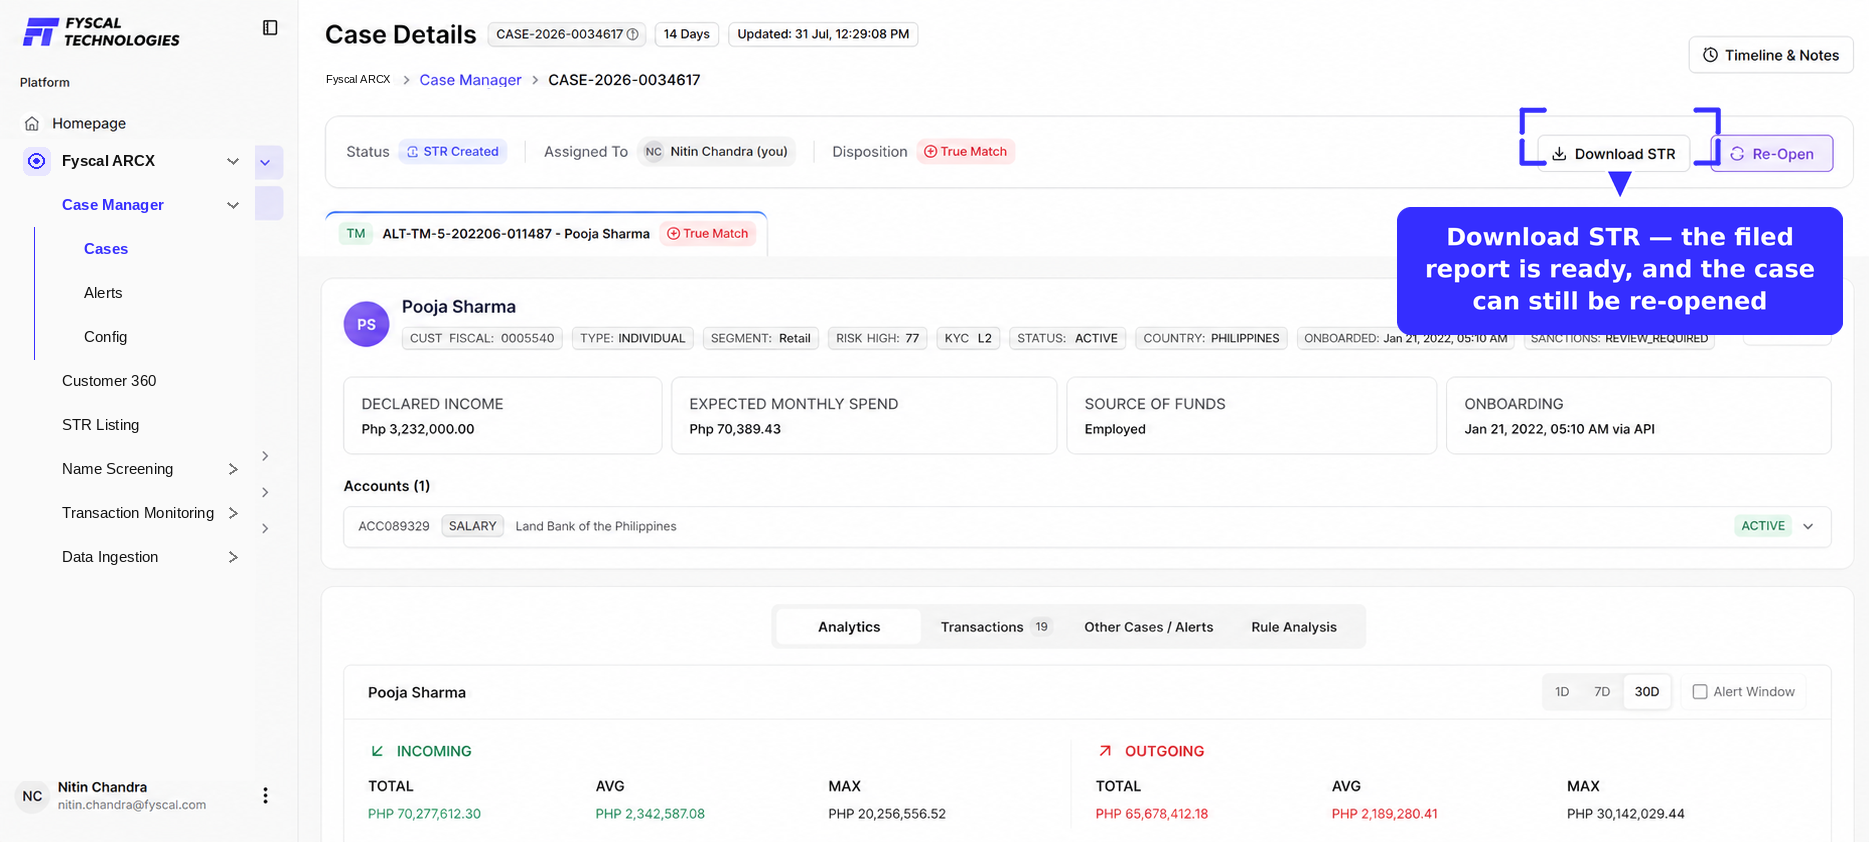
The case immediately reflects the closure: Status changes to Closed, the Disposition badge shows True Match, and — this is the moment STR filing becomes possible — a new File STR button appears next to Re-Open.
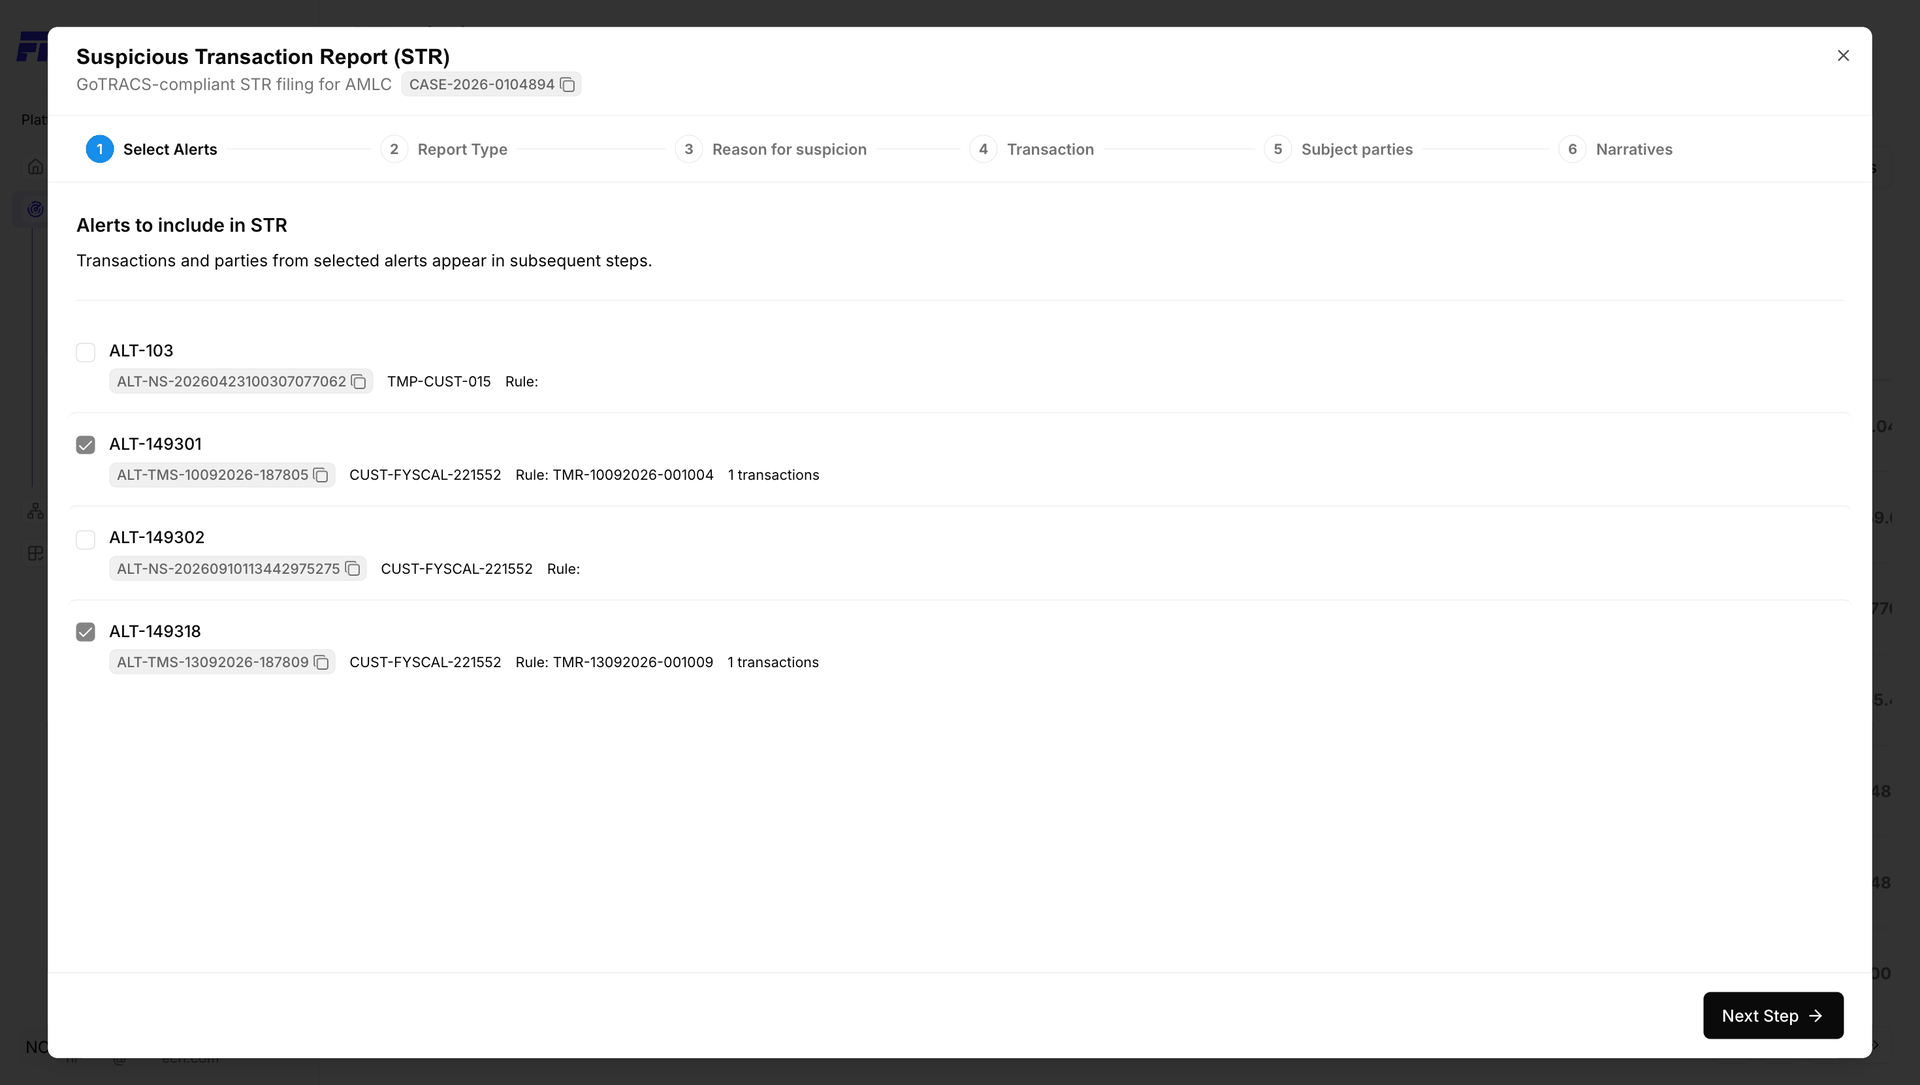
Clicking File STR opens a 6-step wizard that assembles a GoTRACS-compliant Suspicious Transaction Report. Each step must be completed before moving to the next; progress is tracked across the top of the dialog. The walkthrough below follows one real filing (CASE-2026-0104894) from start to finish.
Choose which of the case's alerts to include in this STR. Every transaction and party used later in the wizard is pulled from whichever alerts are selected here, so it's worth confirming this before moving on.
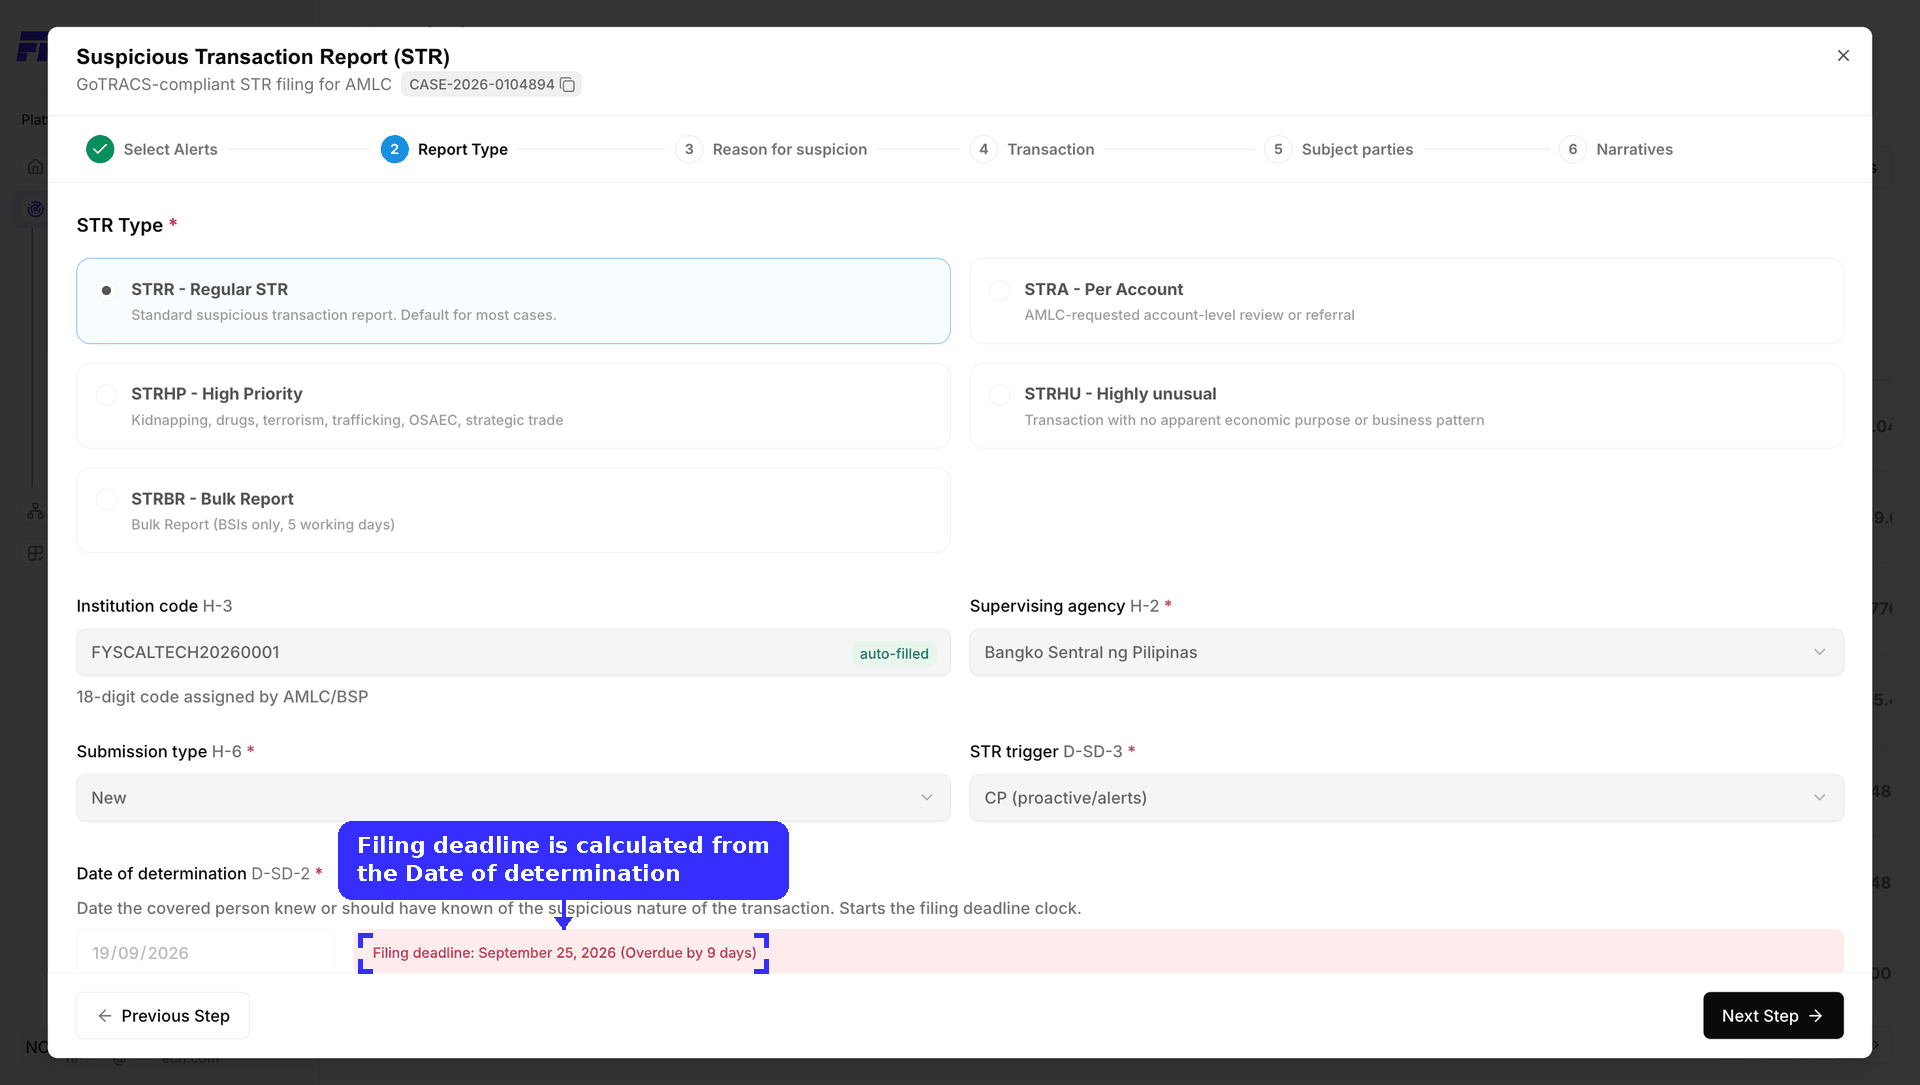
With alerts chosen, Report Type covers everything the regulator needs to know about the filing itself.
STR Type is usually Regular STR for most cases — High Priority, Bulk Report, Per Account, and Highly Unusual exist for specific regulatory scenarios (kidnapping, trafficking, and similarly urgent categories use High Priority, for example). The Institution code auto-fills; Supervising agency, Submission type, and STR trigger (e.g. CP (proactive/alerts)) are set per filing. Date of determination is the date the covered person knew, or should have known, the transaction was suspicious — this starts the regulatory filing-deadline clock, and the deadline is calculated and shown live (here flagged as overdue).
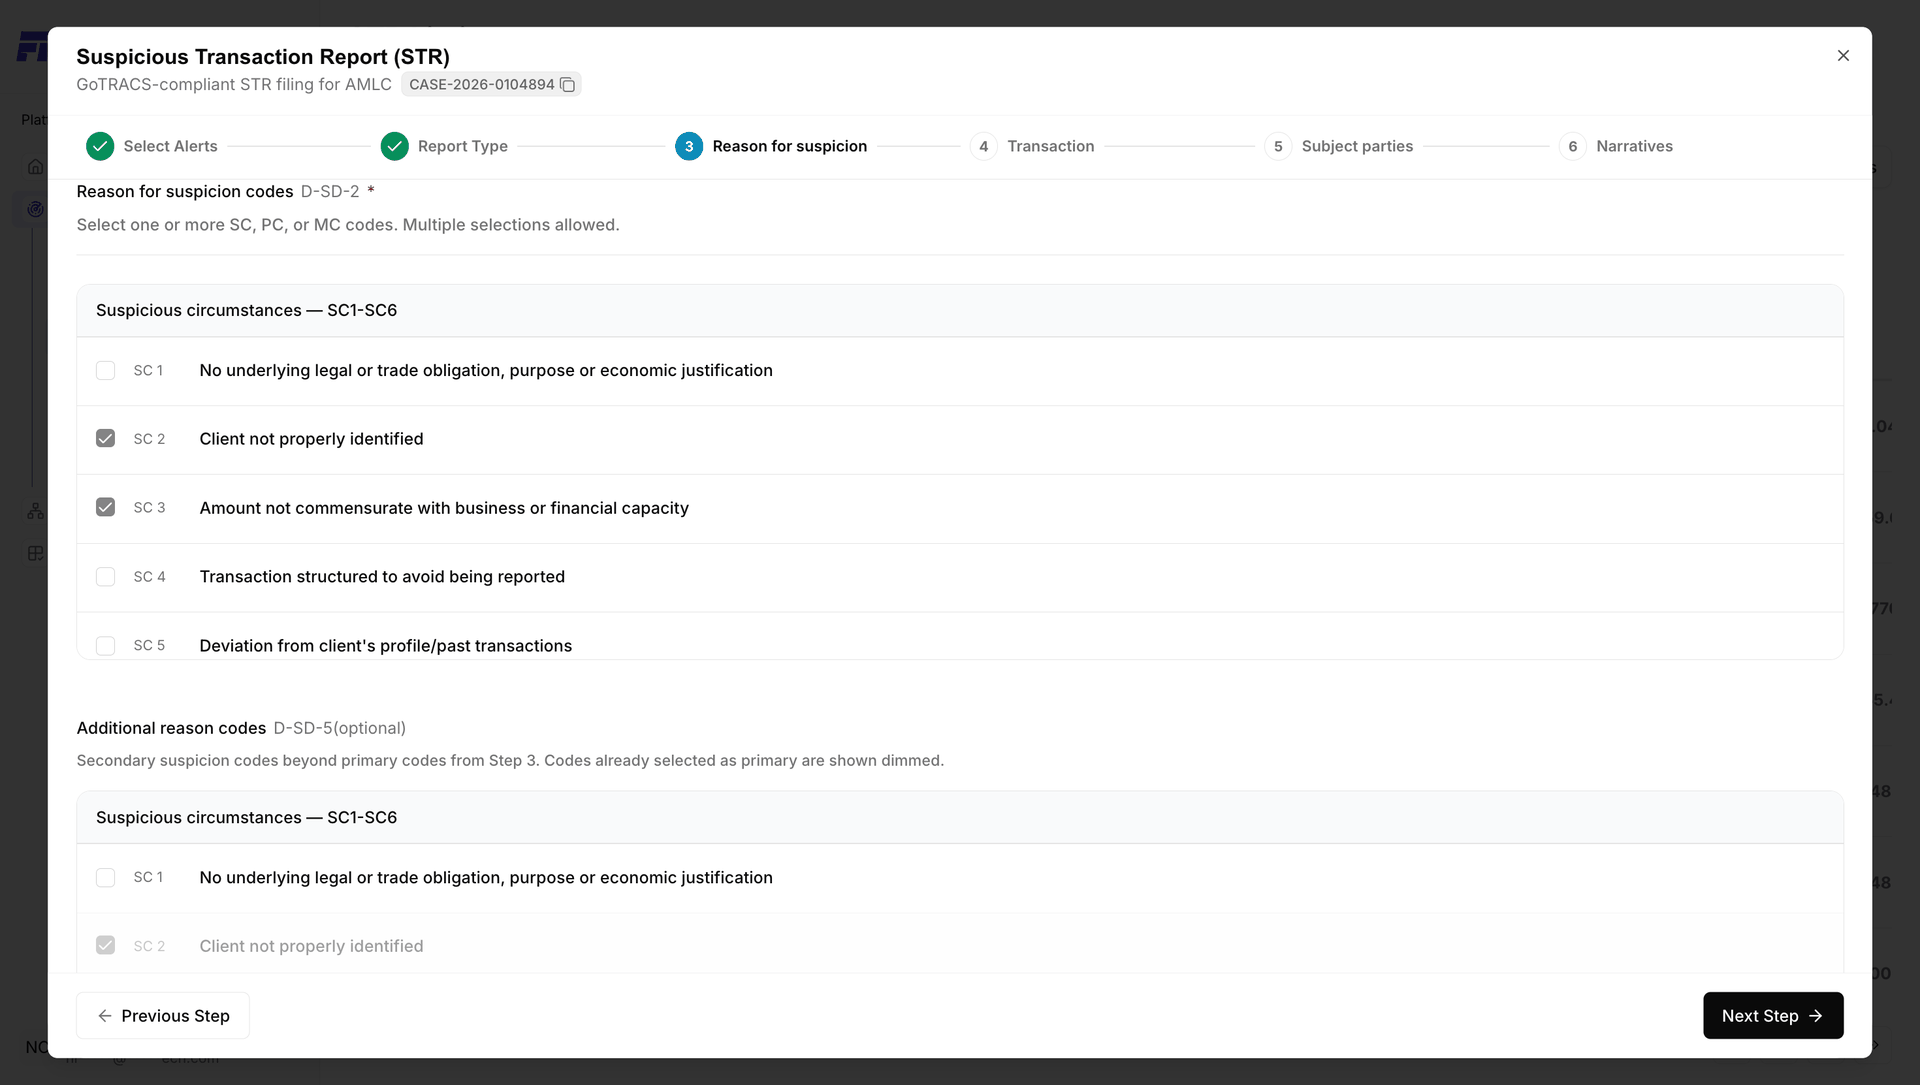
Report logistics done — now the substance: why is this suspicious?
Select one or more codes describing why the activity is suspicious, from a list of 43 standardized Suspicious Circumstance (SC), Predicate Crime (PC), and Money Laundering (MC) codes. At least one is required; most filings use two or three. An optional Additional reason codes section lets you add secondary codes beyond your primary selection — codes already chosen as primary show dimmed there so they aren't picked twice.
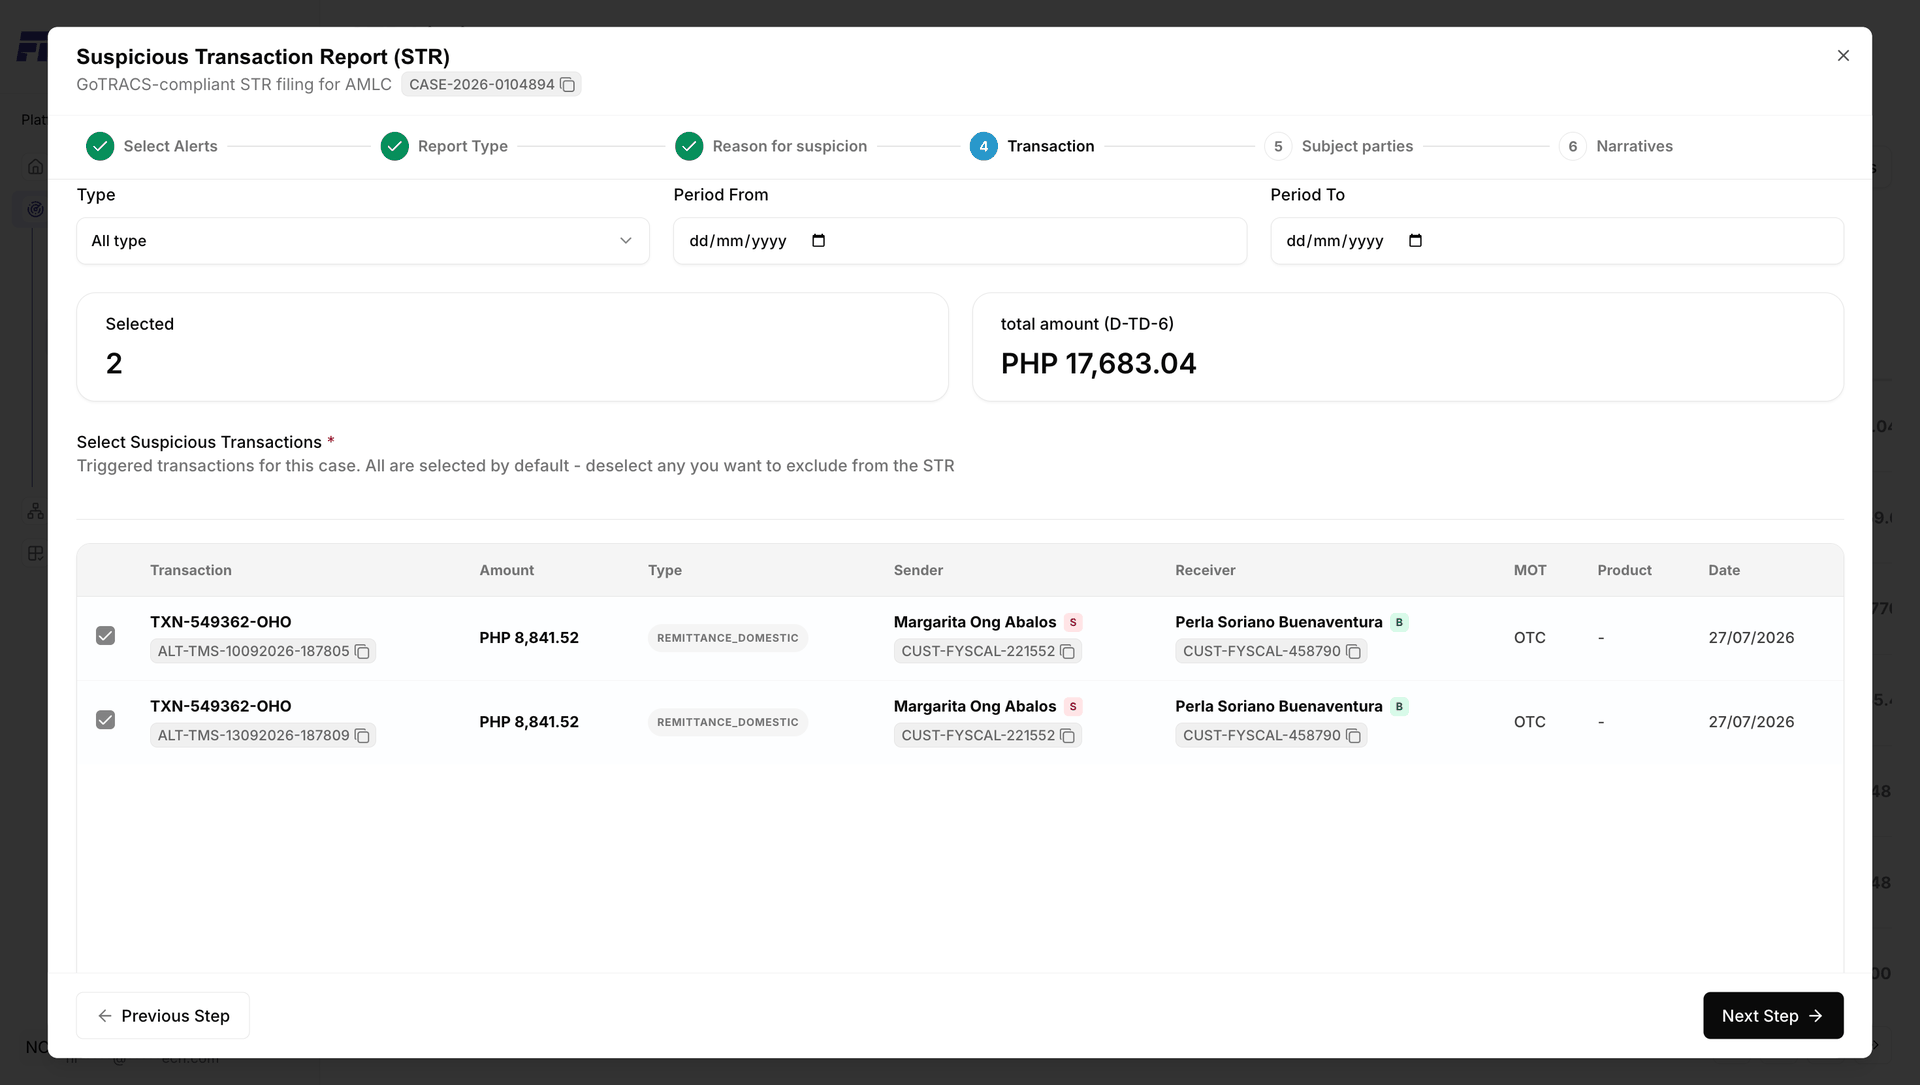
Reasons documented — next, the actual transactions this filing covers.
Every transaction attached to the selected alert(s) appears here, pre-selected by default — filter by Type, or narrow further with a Period From/To date range. The Selected count and total amount update live as selections change. Scrolling below the table shows the Party Role legend used throughout the filing — Subject of Suspicion, Beneficiary, Counterparty, Transactor, Other participant — and notes that MOT, Product Type, and Transaction Code come automatically from ingested data.
Transactions locked in — their parties carry straight through to Step 5.
Parties are auto-derived from the transactions selected in Step 4 — nothing to add manually in most cases. Click a party's row to expand it and confirm its Party role, Entity type, name fields, CRN, Account no., ID type and number, Date of birth, and Nationality, followed by additional details such as address and source of fund. Every other party on the filing is listed below, collapsed, ready to expand and confirm the same way.
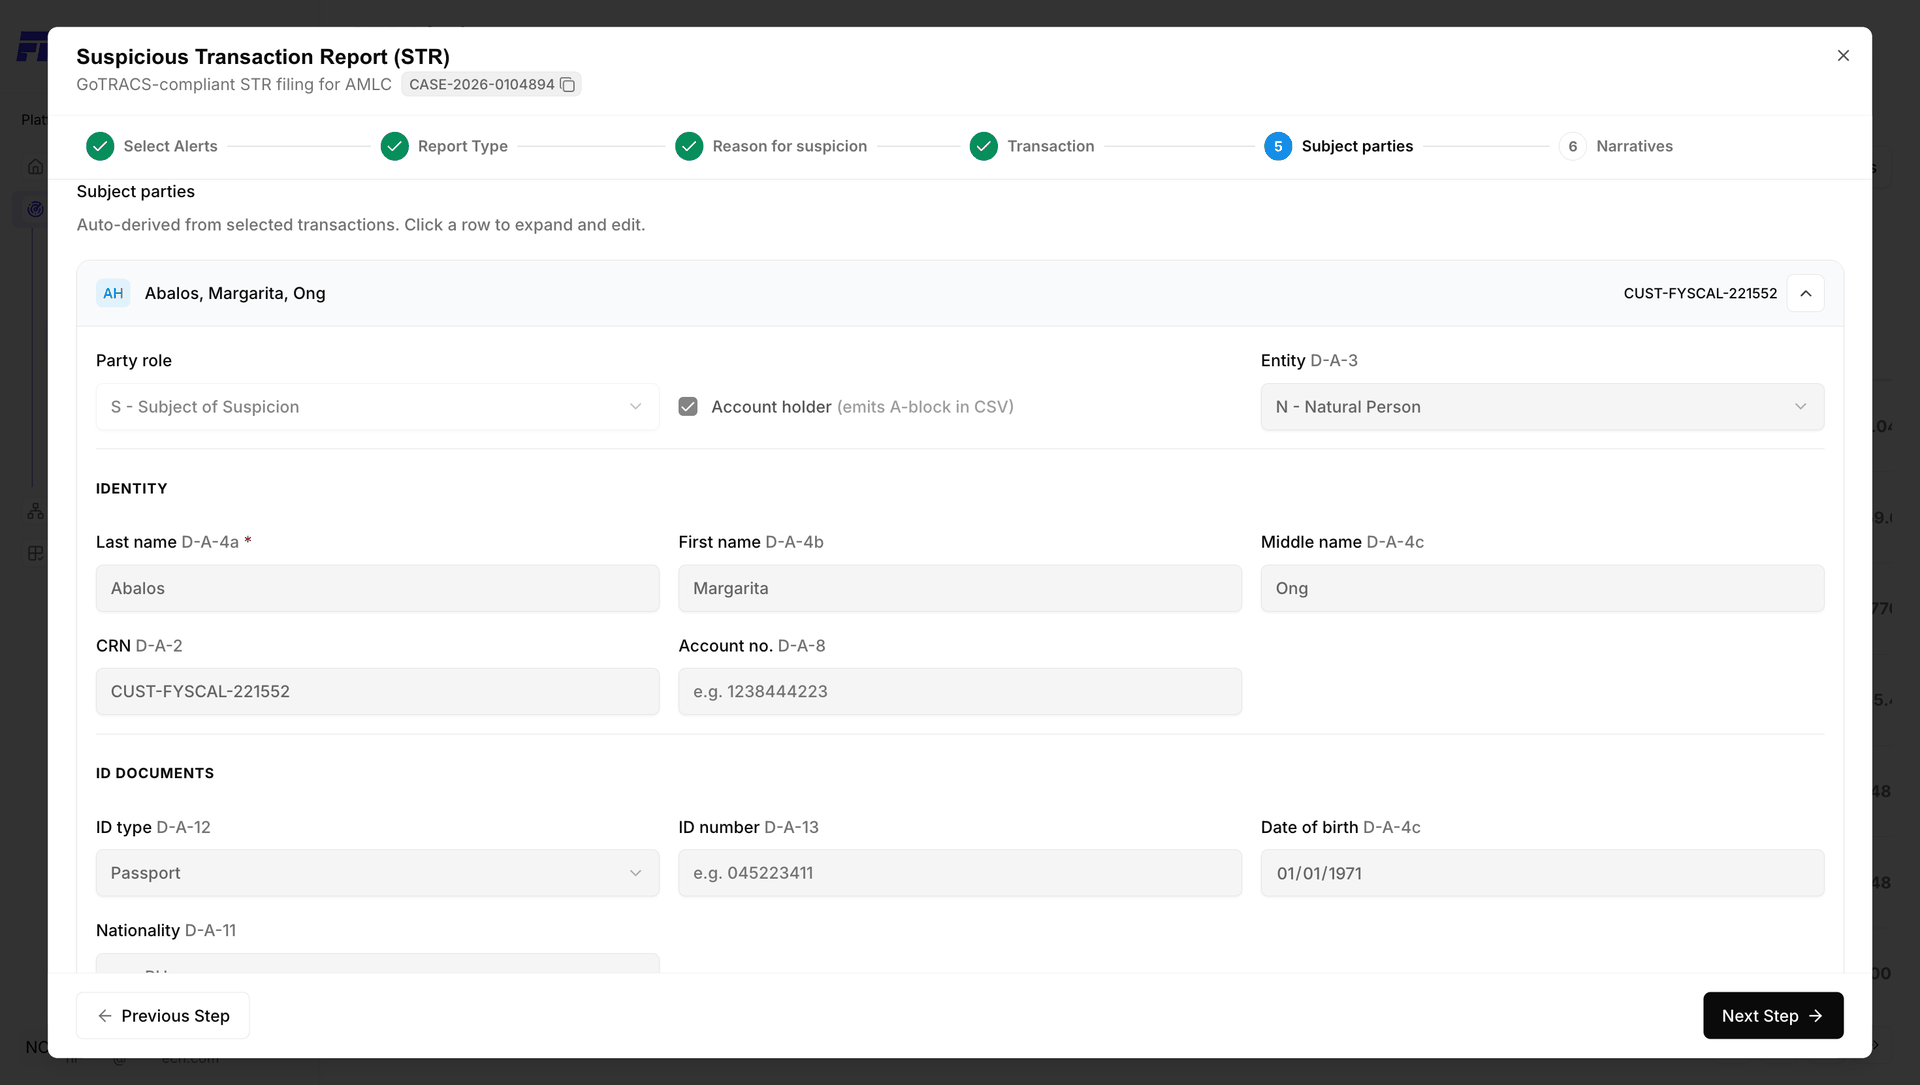
Every party confirmed — the last step ties it all together in plain language.
A free-text narrative explaining the filing. GoTRACS expects a narrative that answers who is involved, what the activity was, when and where it occurred, why it's suspicious, and how it was carried out — a minimum of 200 characters is required, and the character counter confirms live when that bar is met. The alerts covered by the filing are listed beneath for reference.
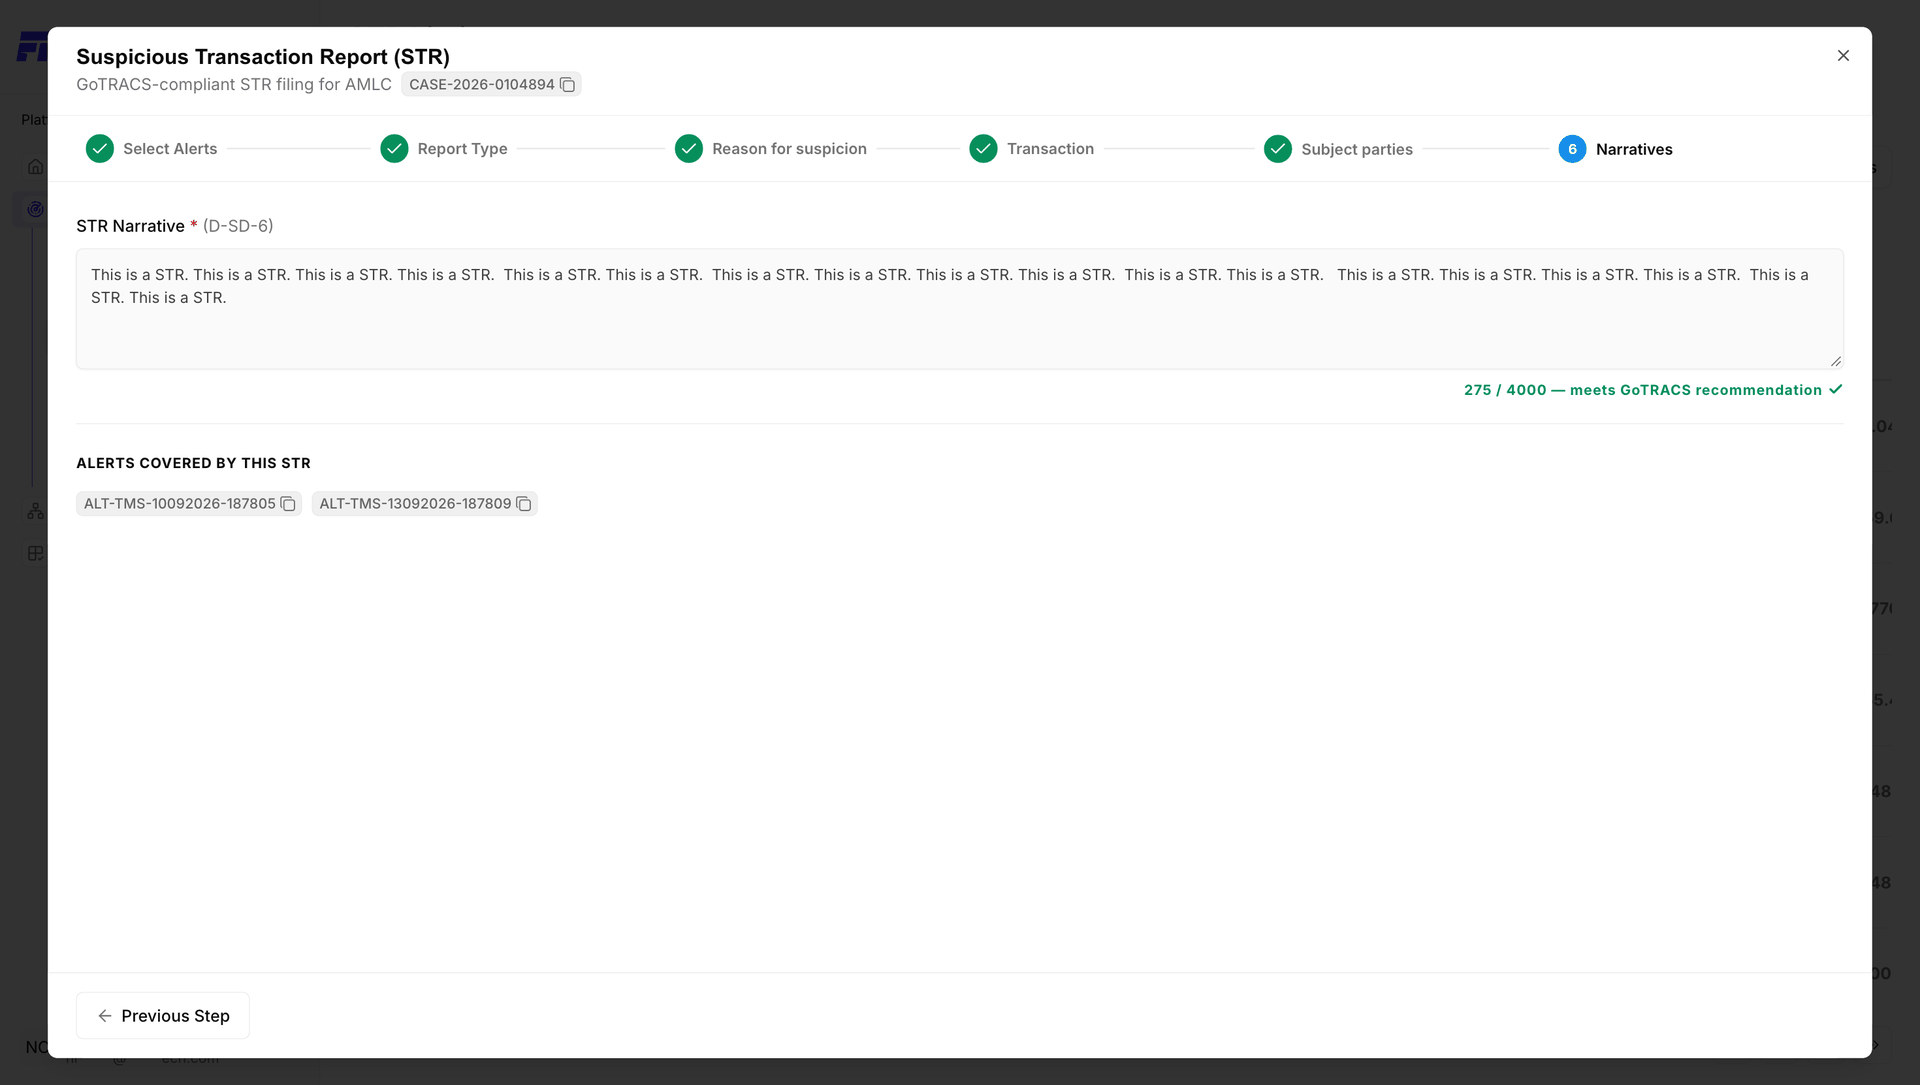
Once completed, the case's Status updates one final time to STR Created, and the File STR button is replaced by Download STR — the filed report can now be downloaded at any time, and the case can still be re-opened later if needed.
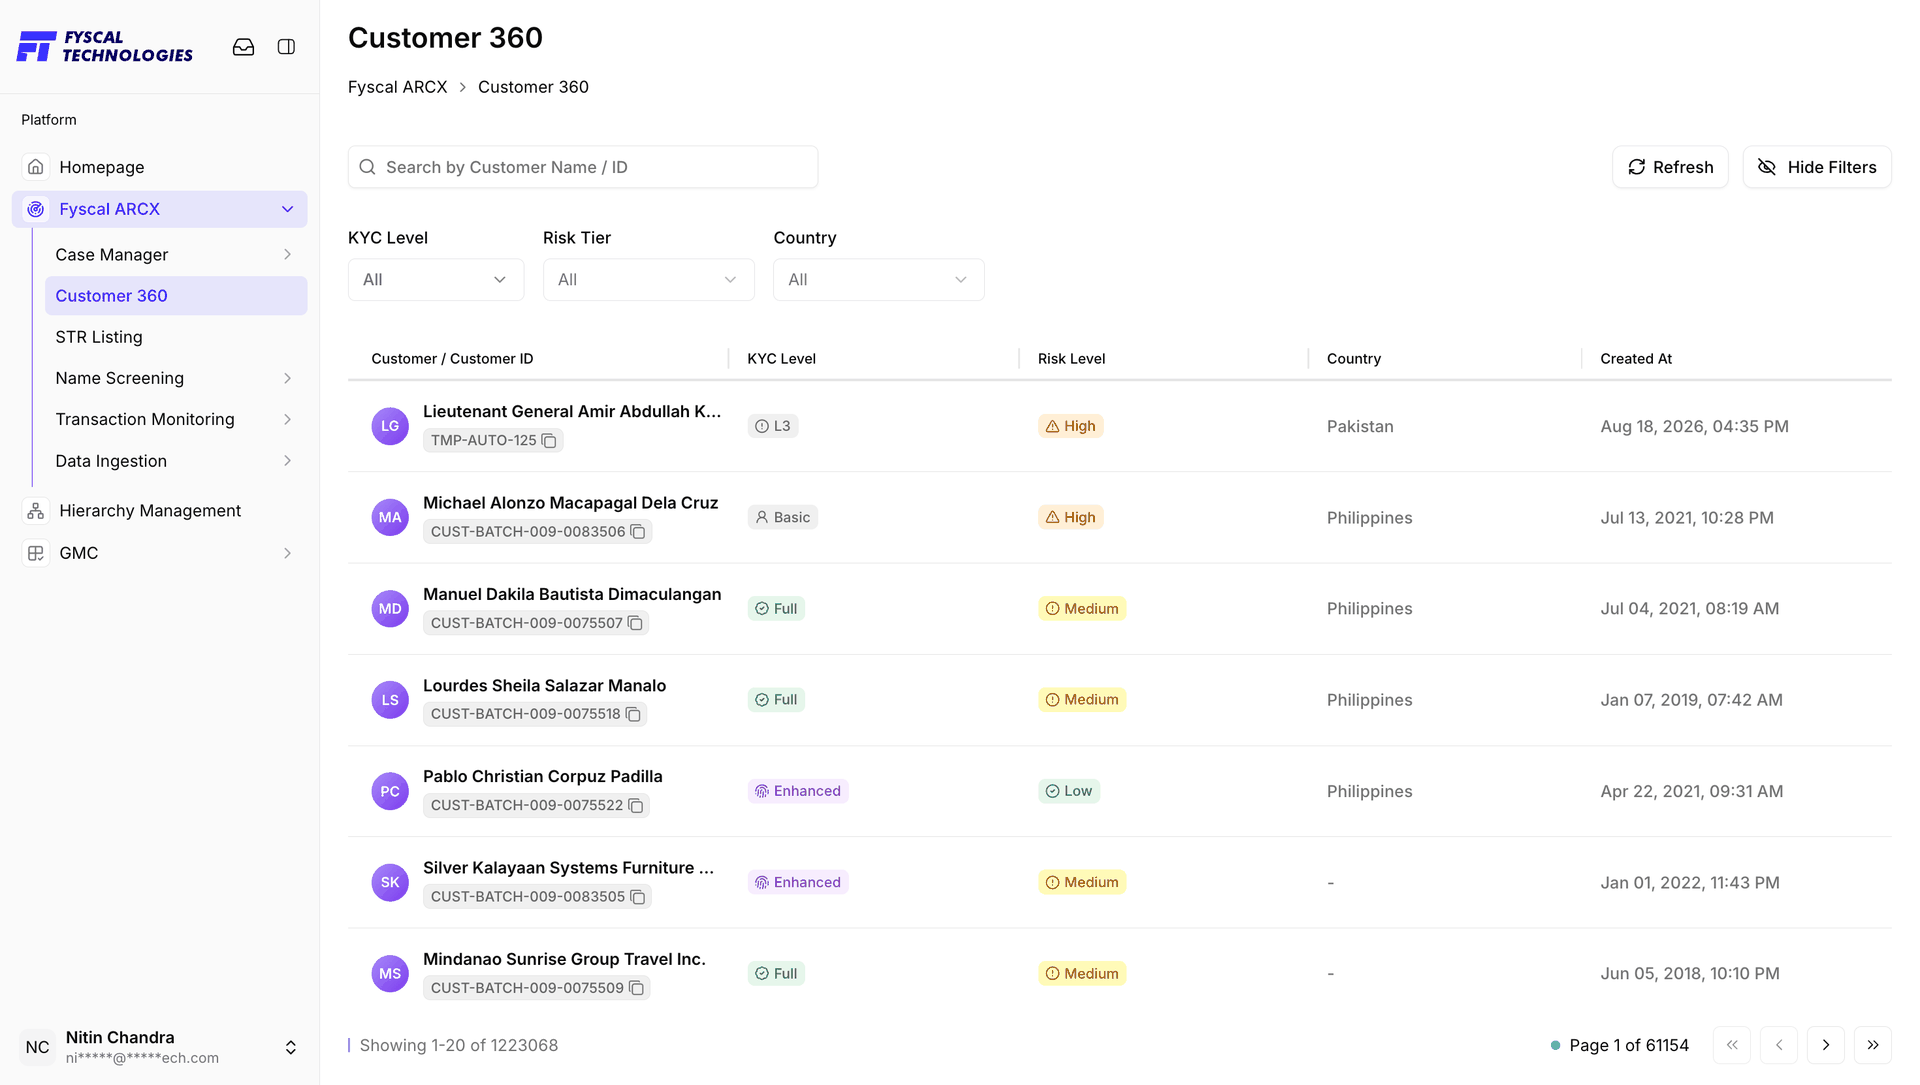
The single record of every party the platform knows — individuals and businesses alike. Every other module reads from and writes back to this record: a screening hit resolves against a customer here, a case investigates a customer here, and a filed STR names a customer here. This is where you look someone up and see their complete picture in one place.
The main list covers every customer on the platform — the live example below runs to 1,223,068 records across 61,154 pages — so search and filtering are the primary way to work with it rather than scrolling.
Each row shows the customer's name and Customer ID, KYC Level, Risk Level, Country, and when the record was created. The search bar finds a customer by name or ID.
Narrow that down by how thoroughly a customer has been verified.
KYC Level reflects how much verification is on file for that customer, from Basic standard identity checks up through Advanced, Enhanced, Complete, and Full. Some records show a level code instead of a tier name (for example L3).
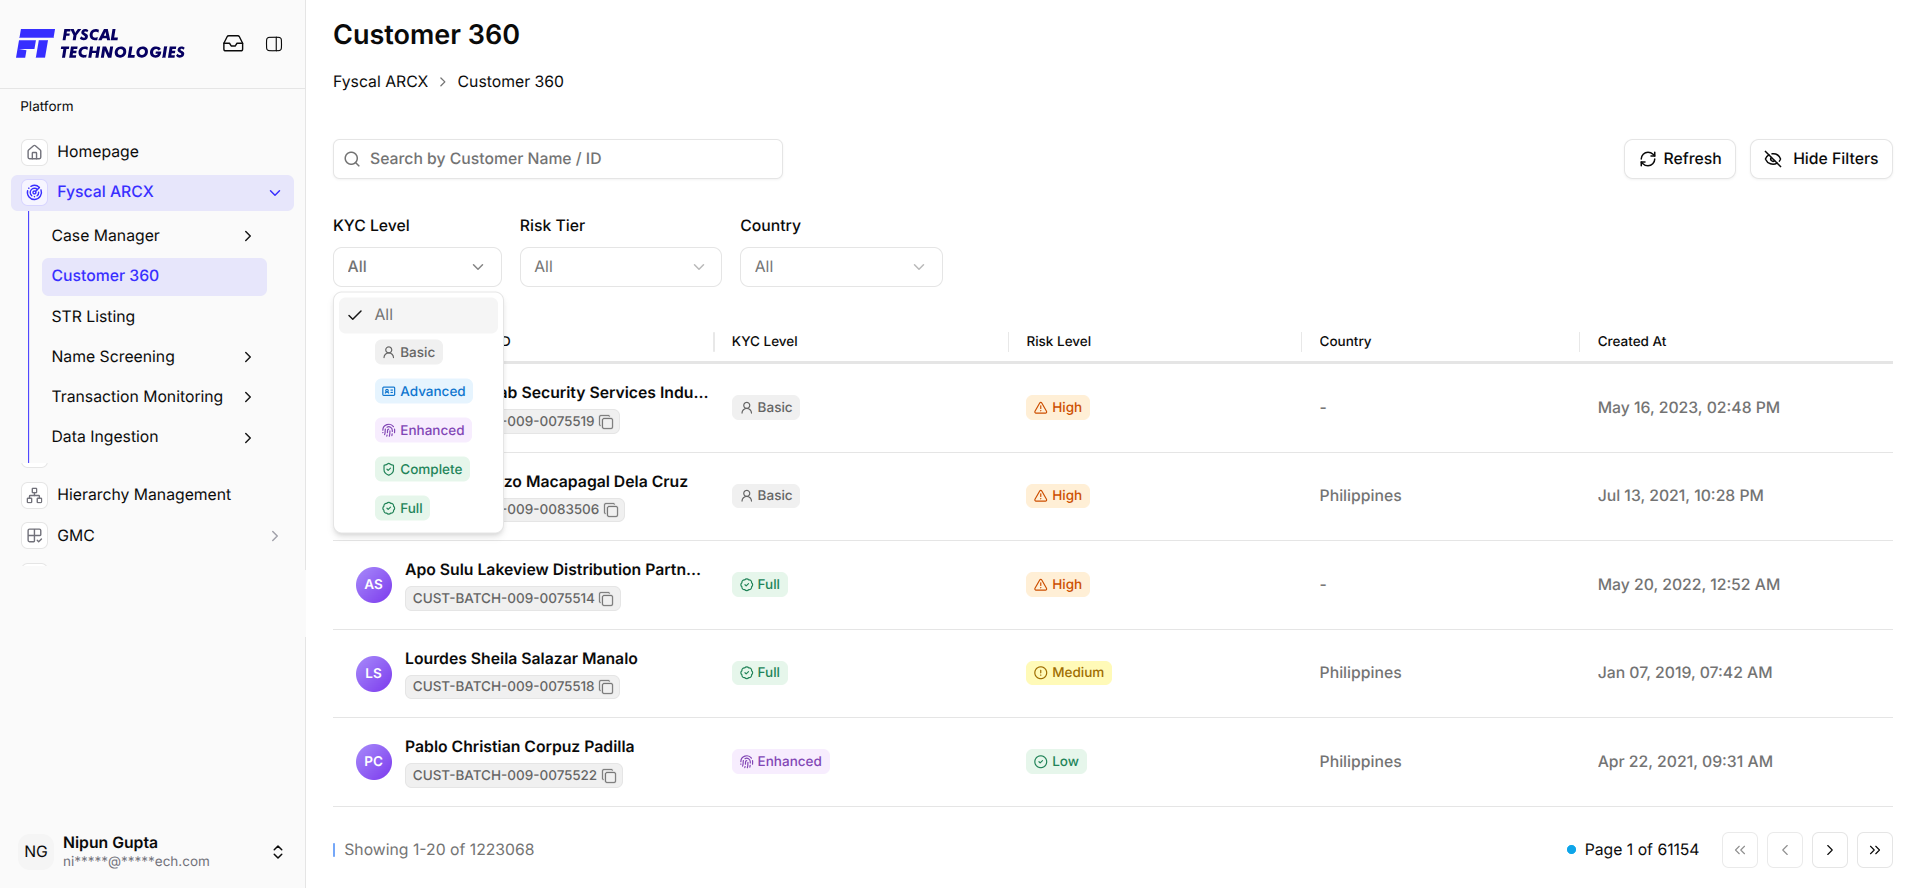
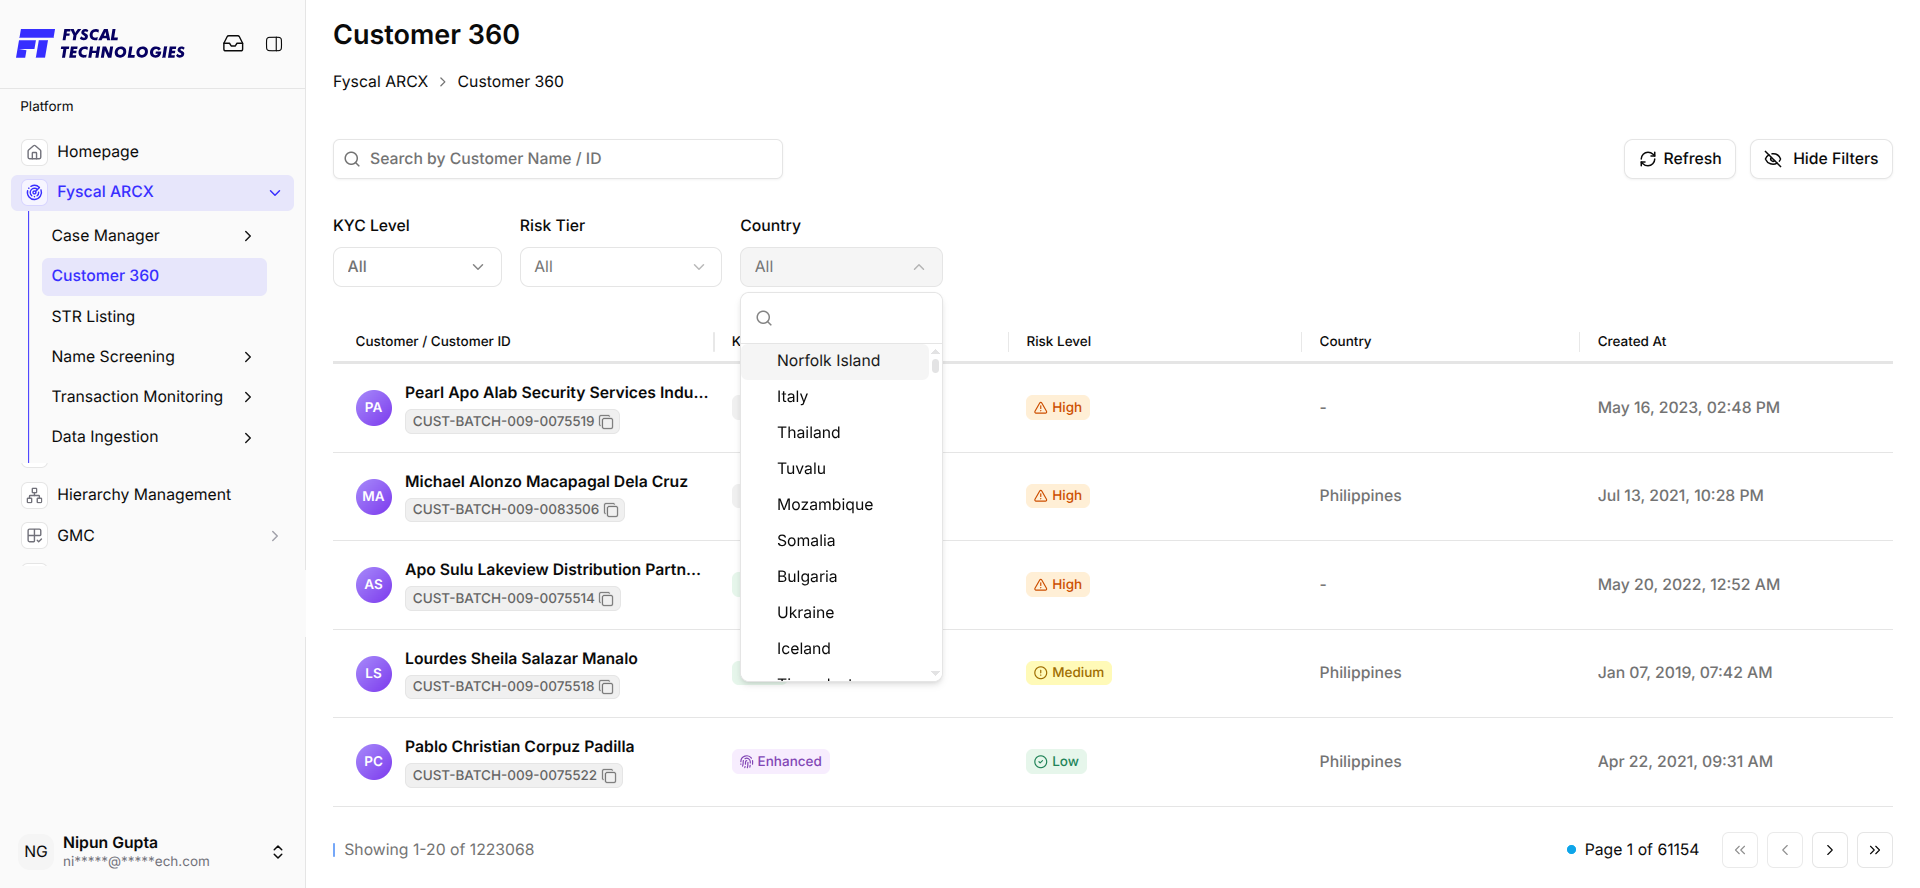
Verification tier aside, jurisdiction is often the fastest way to narrow a list this size.
A searchable dropdown of every country on file — useful alongside Risk Tier, which filters by the customer's current risk banding (the same Low / Medium / High scale used throughout the platform).
Found the customer you're after? Click their row to open the full profile.
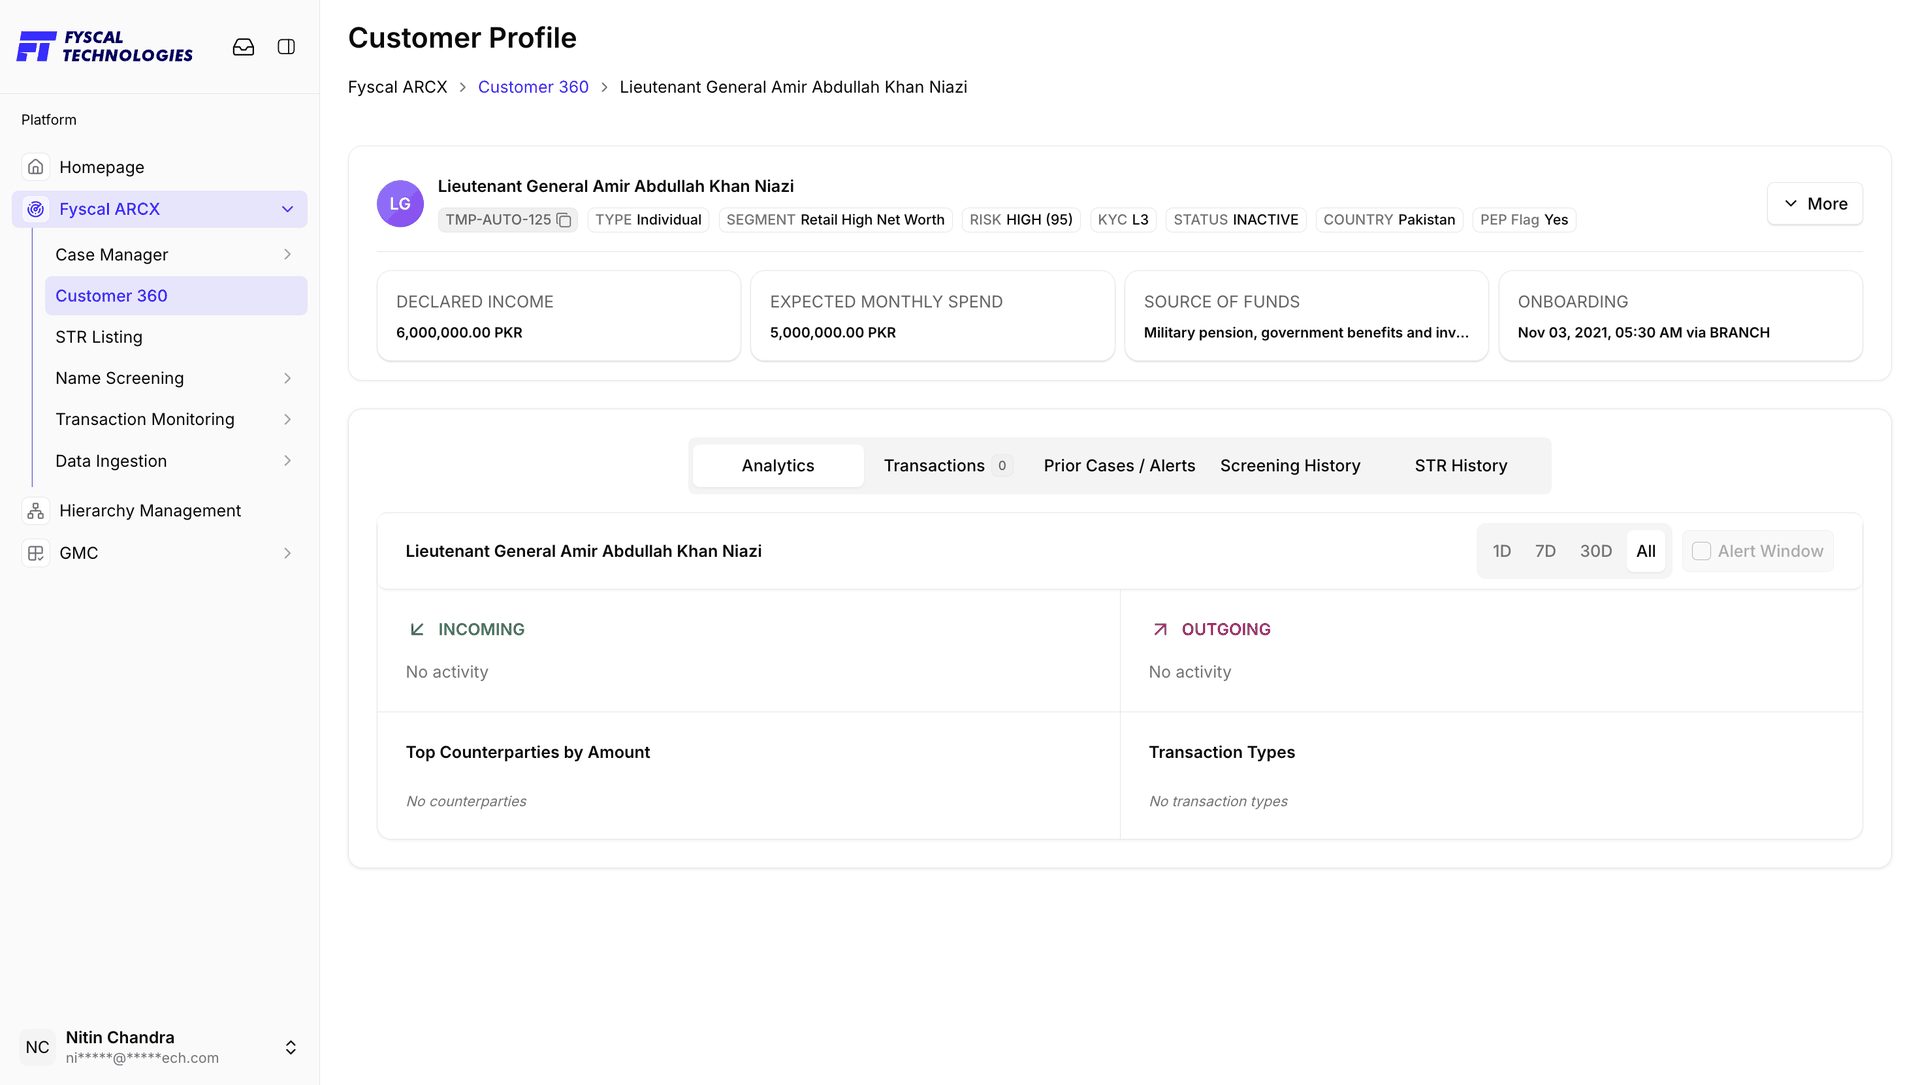
Opening a customer shows their core identity at the top — initials avatar, name, Customer ID, and a row of chips: Type (Individual or Business), Segment, Risk (tier and score, e.g. HIGH (95)), KYC, Status, Country, and PEP Flag. Four summary cards sit underneath: Declared Income, Expected Monthly Spend, Source of Funds, and Onboarding (date and channel). When the customer has linked accounts, they are listed in an Accounts section with their own active/inactive status.
Clicking More expands the header into the full KYC record, in three panels: Business & Employment (designation, employer, segment, source of funds, country of operations), Financial Information (declared income, expected monthly spend, purpose, onboarding channel, expected transaction frequency), and Additional Details (city, country, and sanctions status).
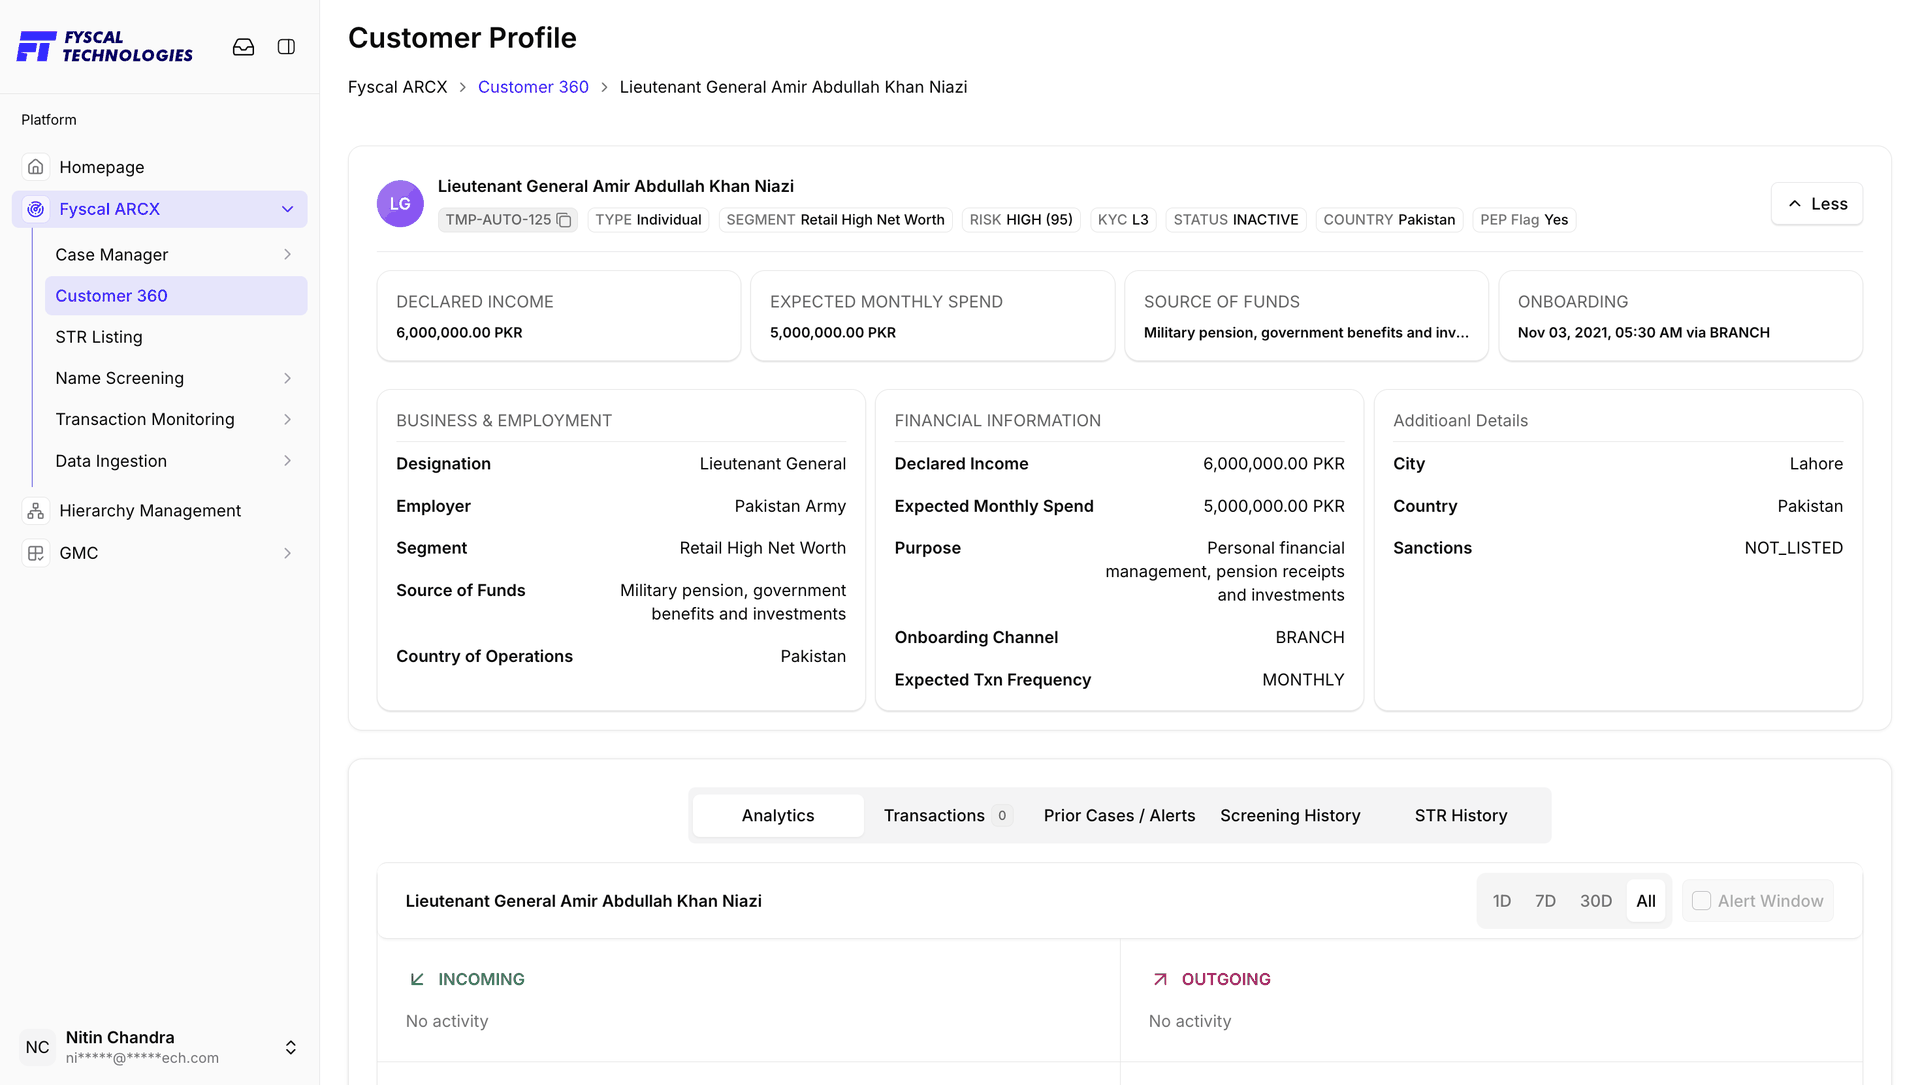
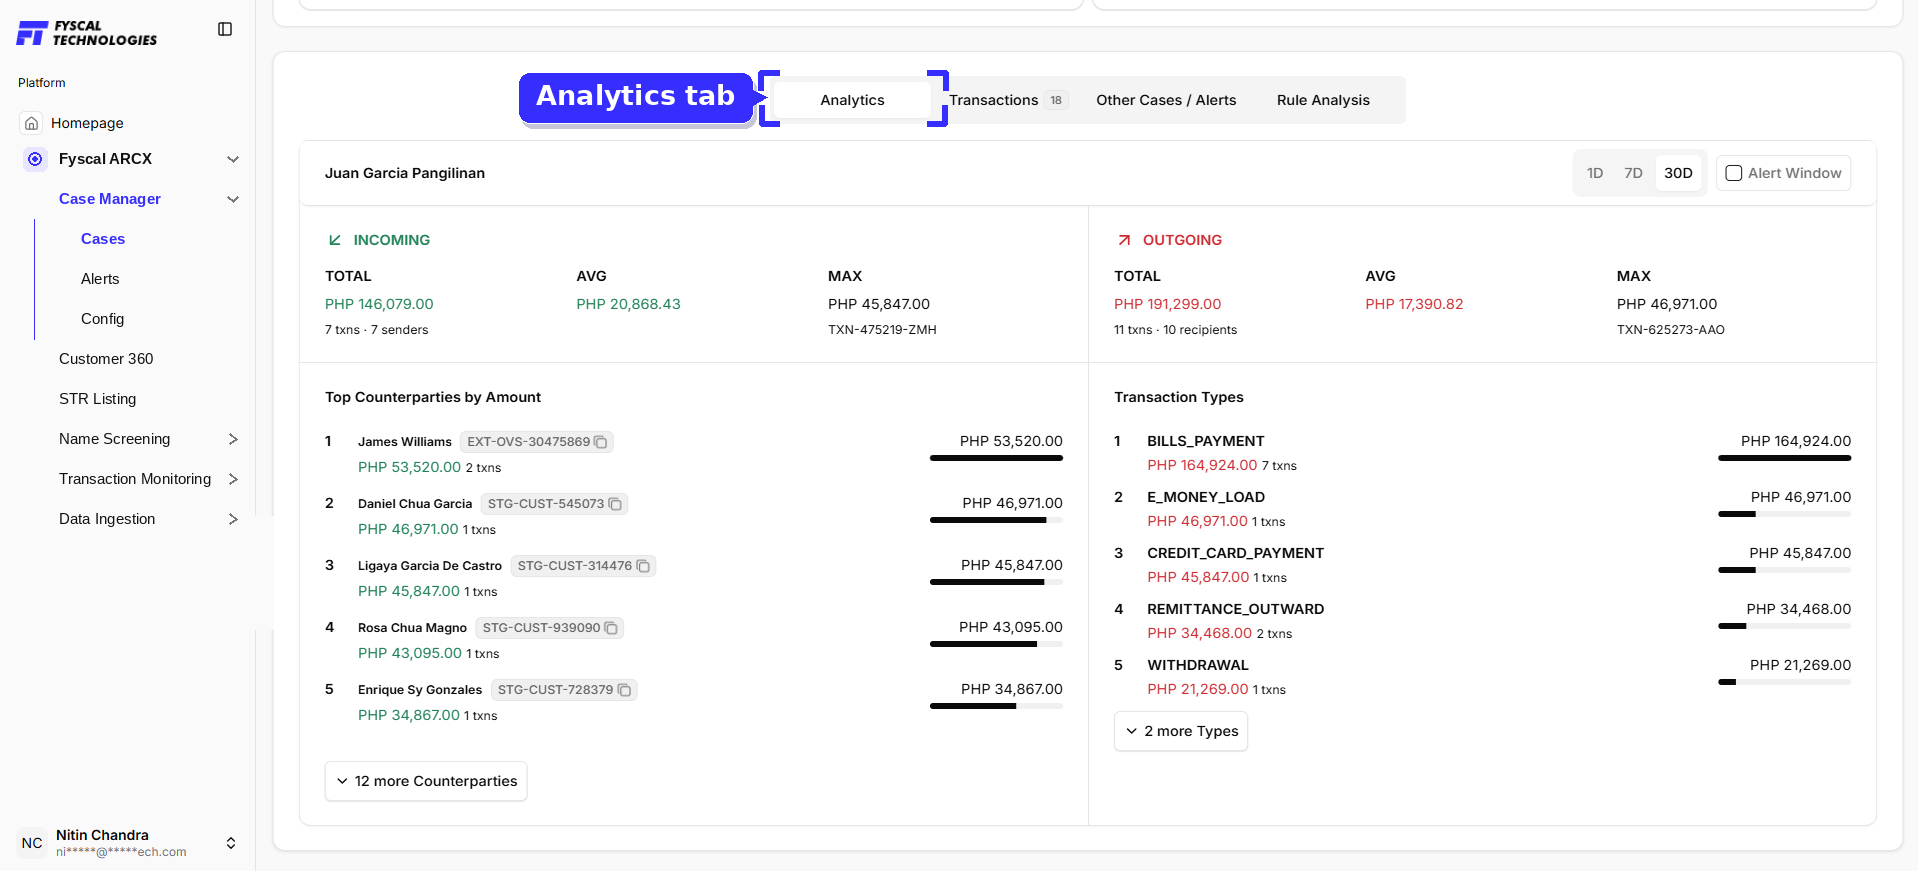
Below the profile header, five tabs cover everything that has happened with this customer. Analytics is the default view — incoming versus outgoing activity, top counterparties by amount, and a transaction-type breakdown — over a 1D, 7D, 30D or All window, with an optional Alert Window toggle to focus on the period around a specific alert.
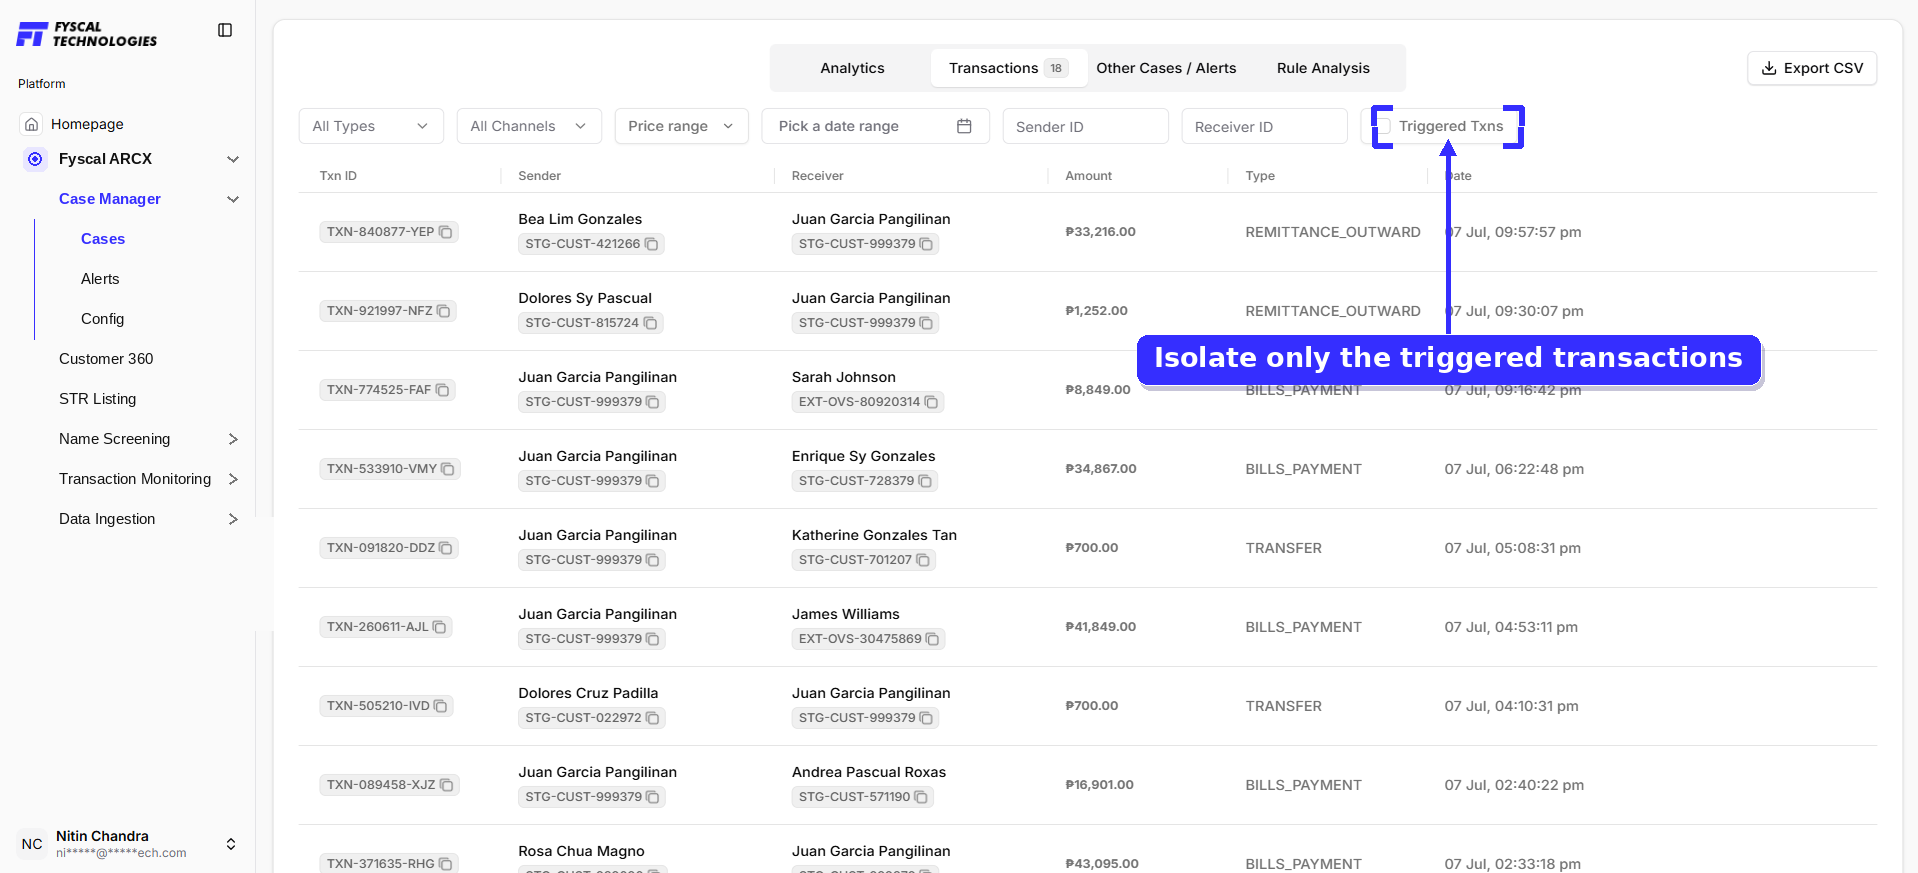
Transactions shows a Transaction Pattern view that can be switched between Transaction Trends and a Heatmap, grouped by Day, Week or Month over a chosen date range, with Transaction Volume and Transaction Count charts beneath, and an Export CSV button for offline review.
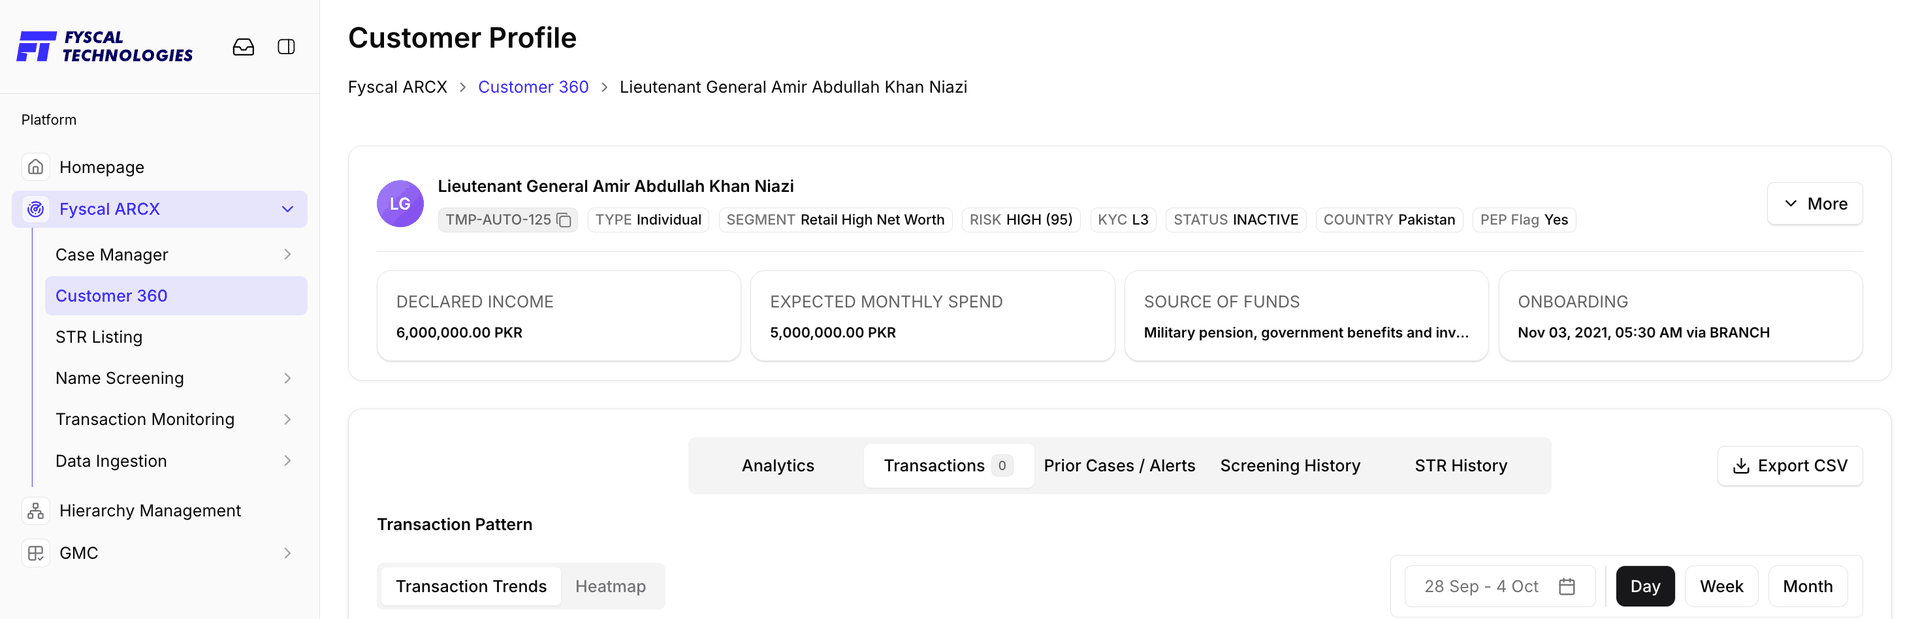
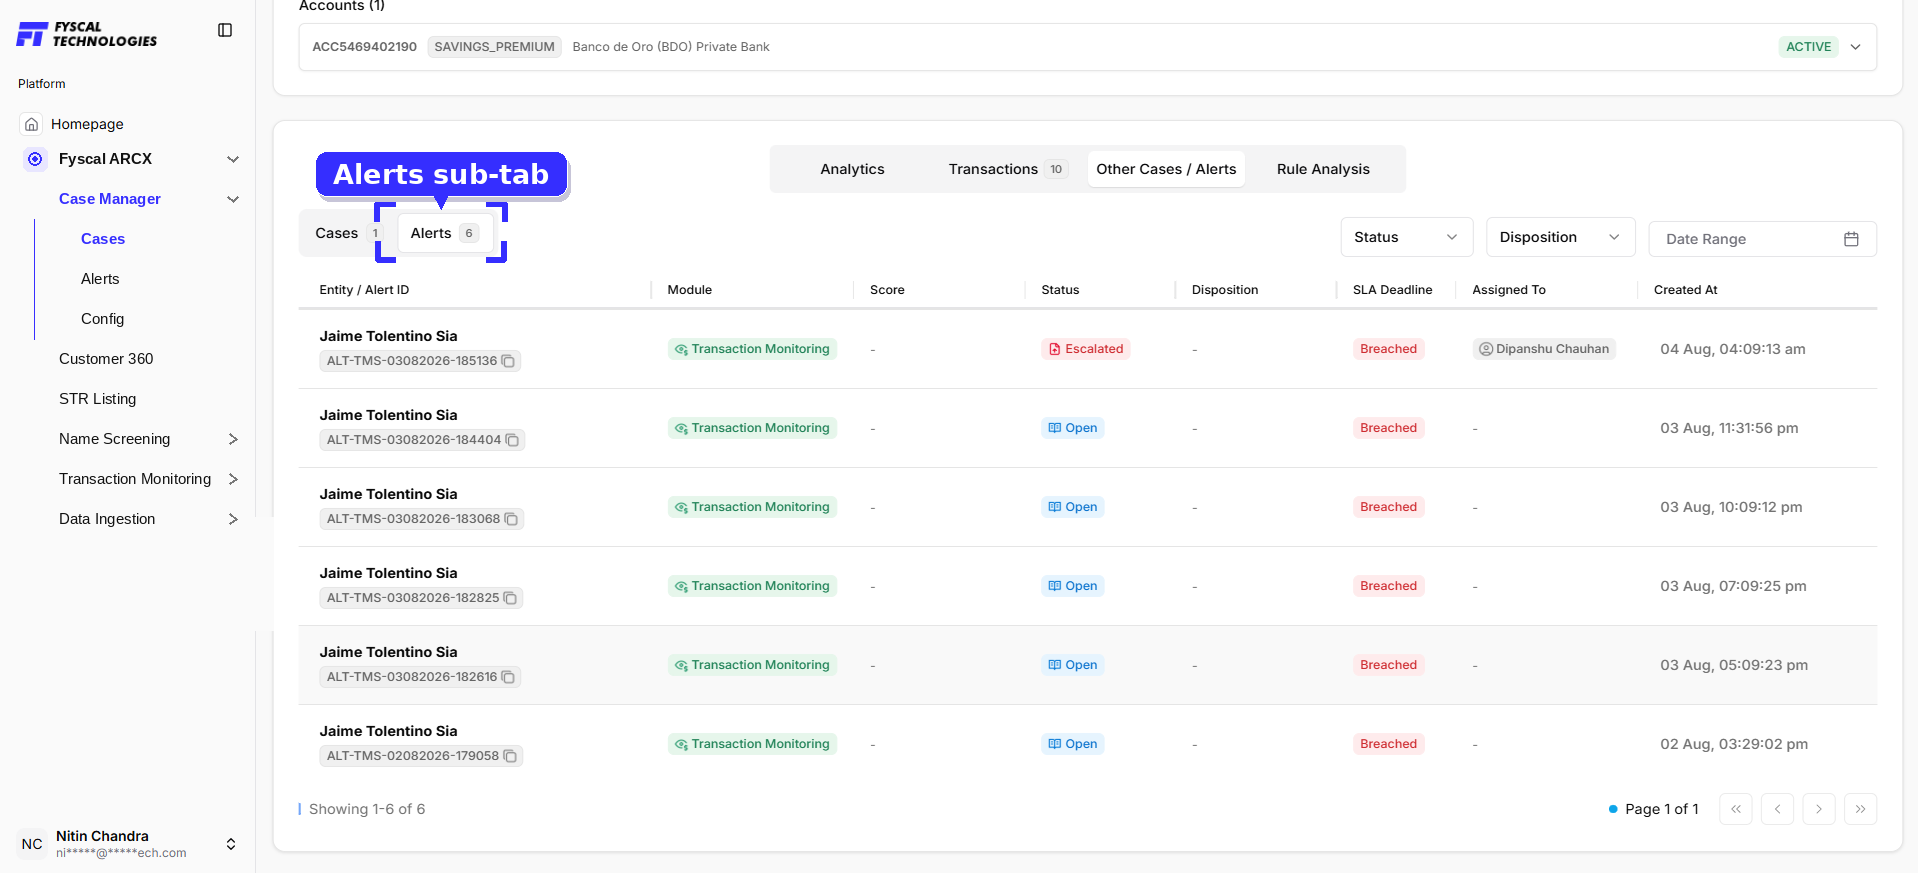
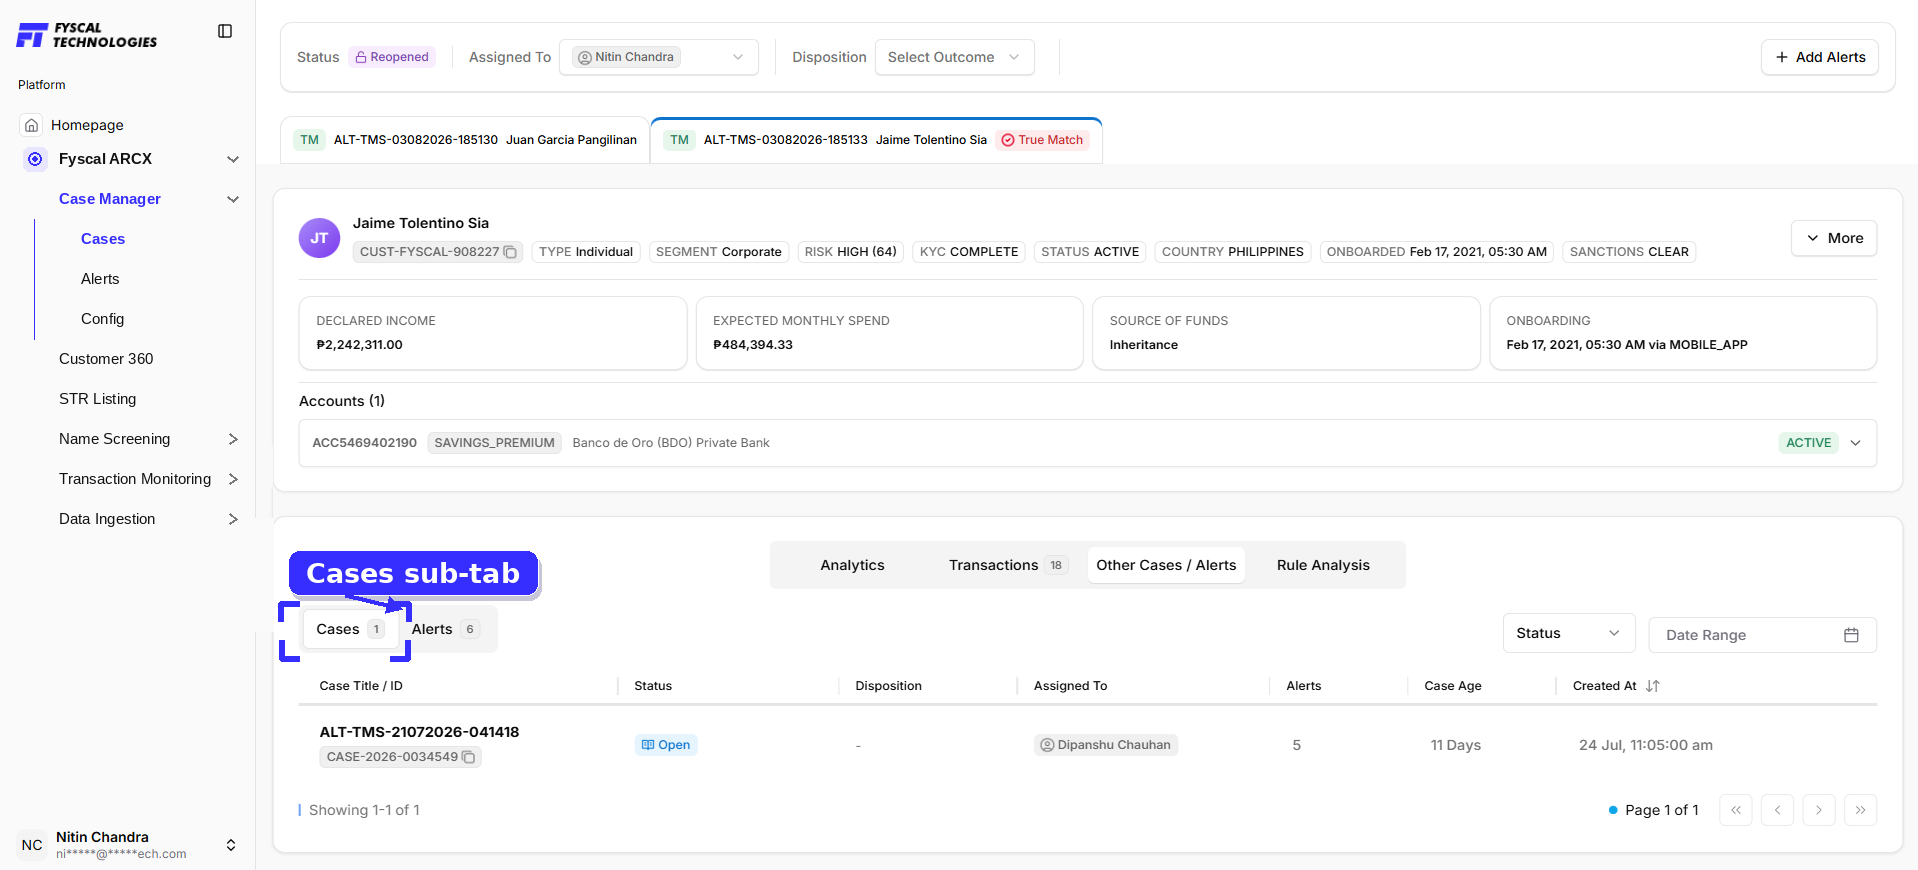
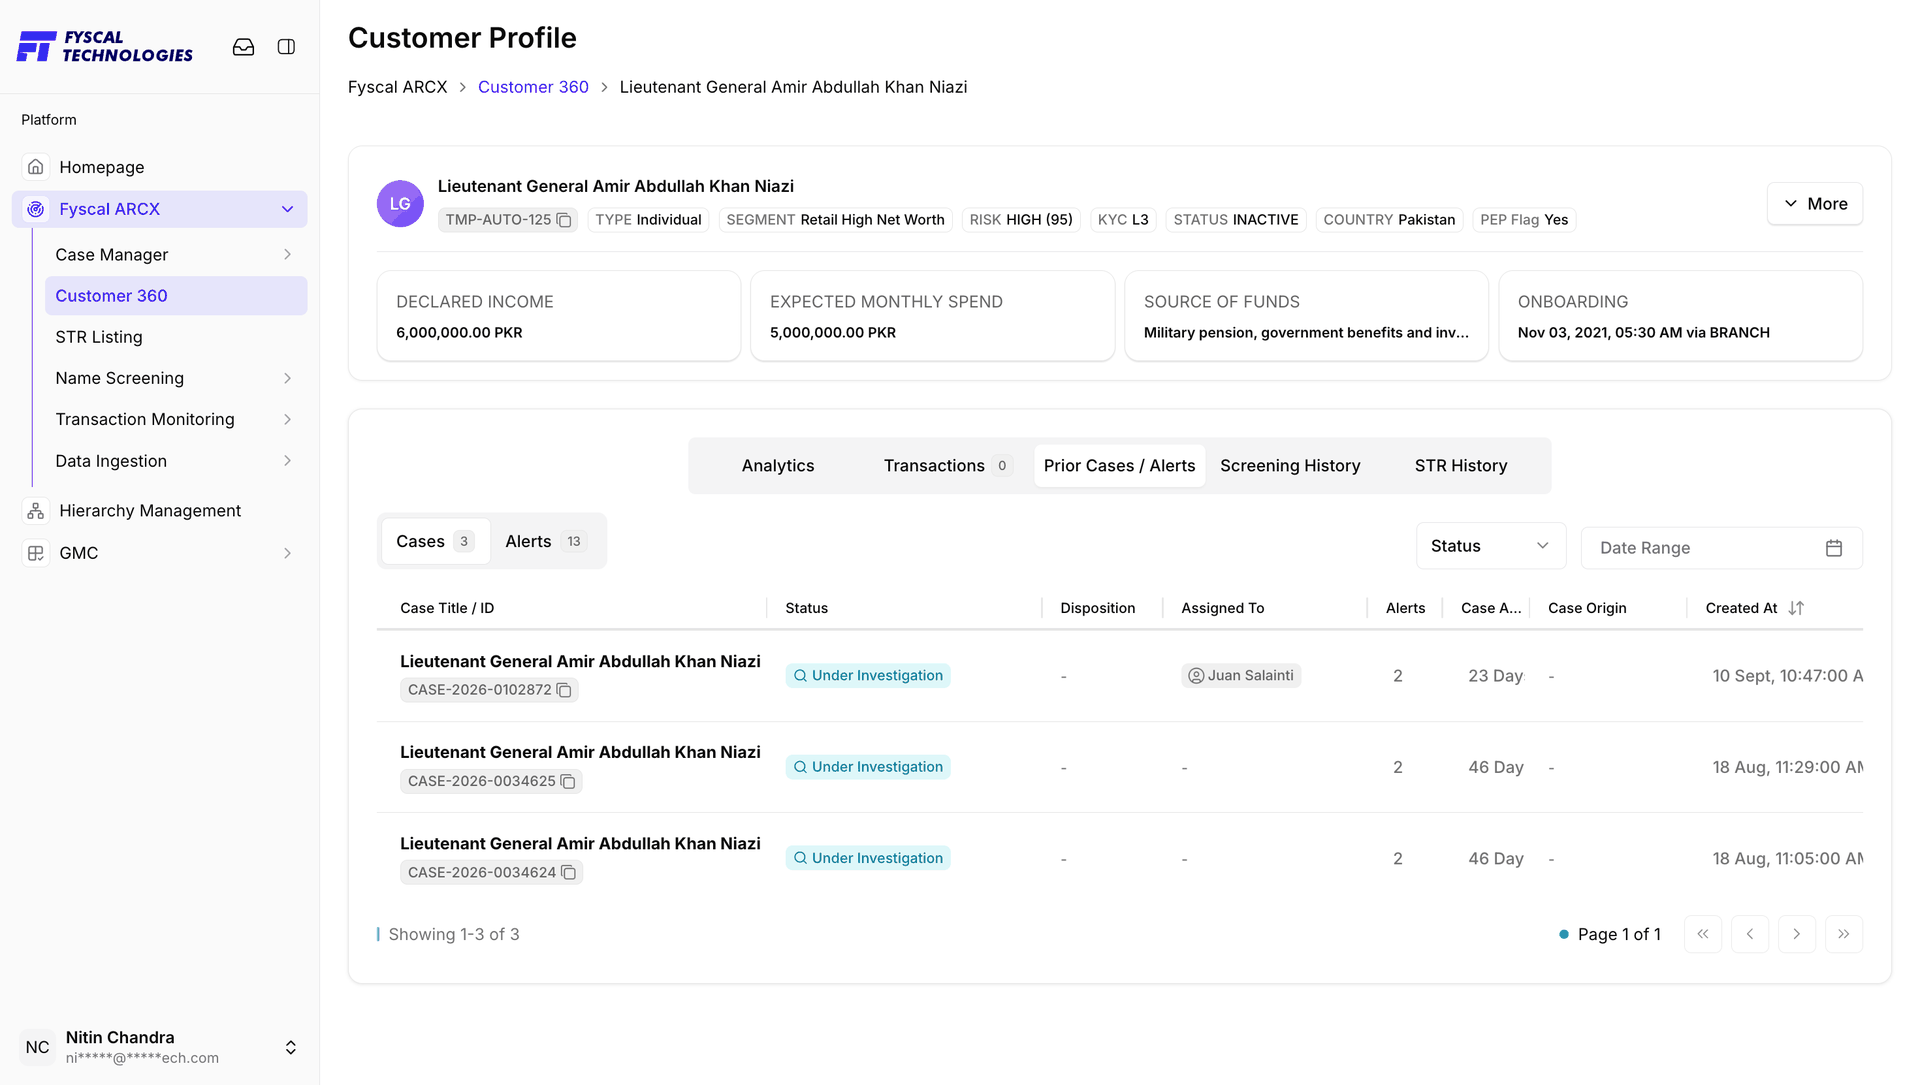
Prior Cases / Alerts shows this customer's investigation history, split into Cases and Alerts sub-tabs with a count on each — so you can see at a glance whether this is a first-time hit or a repeat pattern. Cases list Status, Disposition, Assigned To, the number of Alerts, Case Age, Case Origin and Created At, and can be filtered by Status and Date Range.
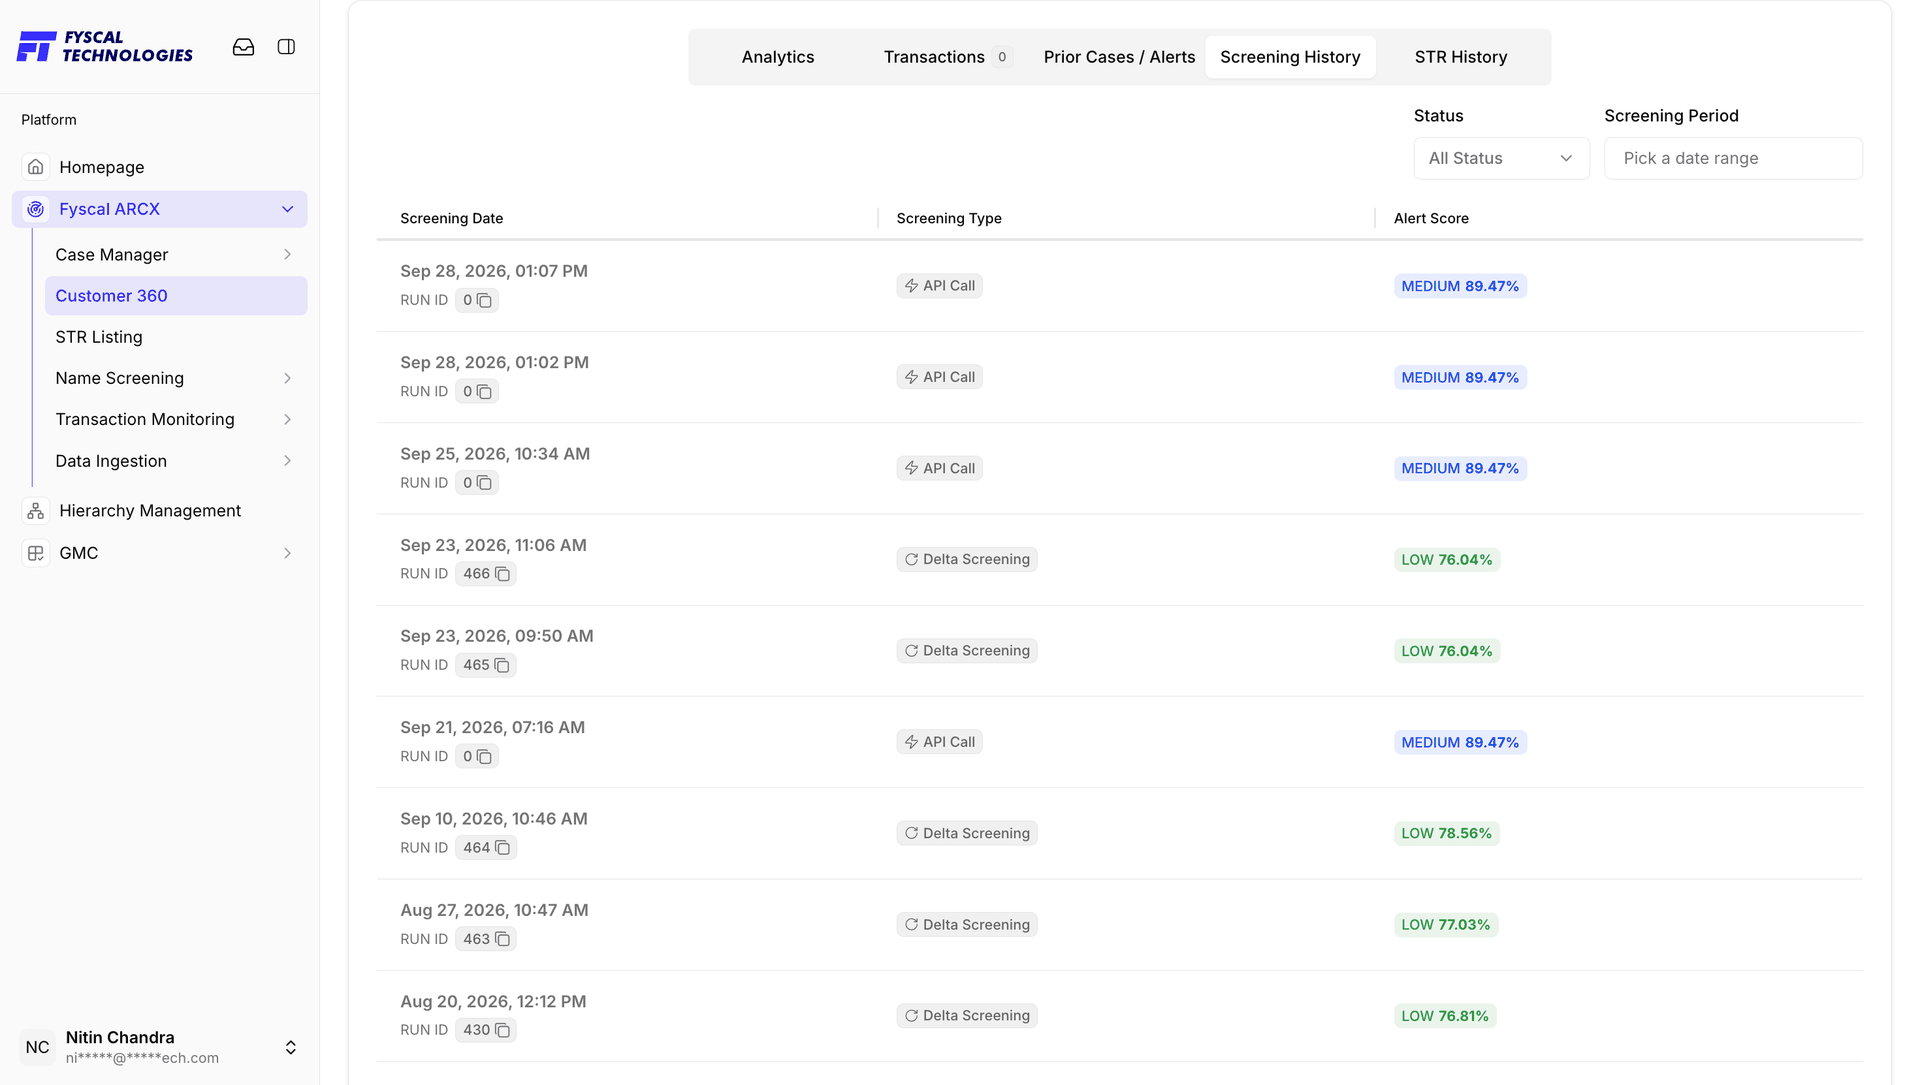
Screening History lists every name-screening run this customer has been through — each with its Screening Date and Run ID, the Screening Type (Delta Screening for ongoing re-checks as watchlists update, or API Call for a screen requested through the API) and the resulting Alert Score, colour-coded by severity. Filter by Status or Screening Period.
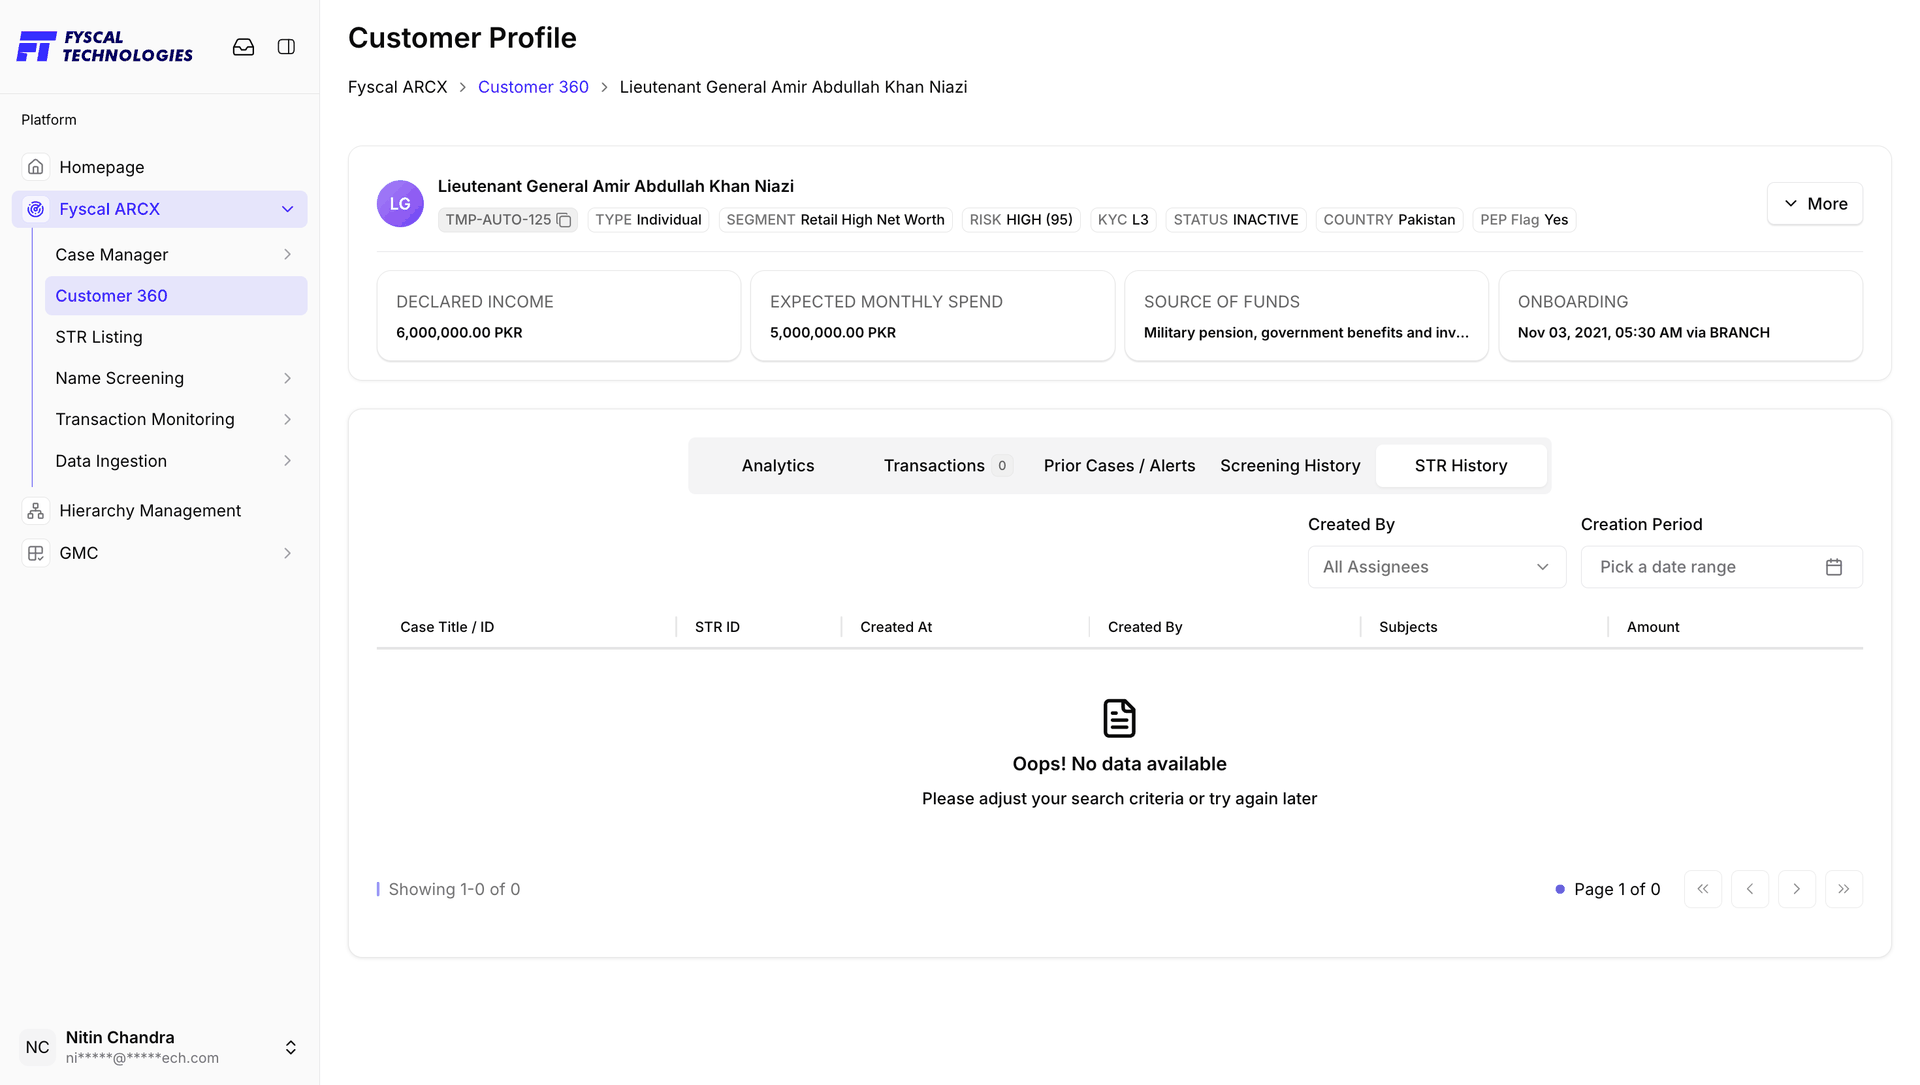
STR History lists any Suspicious Transaction Reports filed naming this customer, with the same columns as the STR Listing register, filterable by who created it and when. An empty state here is common and simply means no STR has ever named this customer.
The register of every Suspicious Transaction Report the institution has filed. Where Case Manager shows the investigation, STR Listing shows the regulatory output of that investigation — one row per filing.
Each row represents one case that has produced an STR, linking the case back to the STR reference, who raised it, and the transaction subjects and amount involved — giving the MLRO a single register of everything that has been reported, without needing to reopen each case individually.
Each row links a filed STR back to its Case Title/ID, the STR ID itself, when it was created, who created it, the transaction Subjects involved, and the filing Amount.
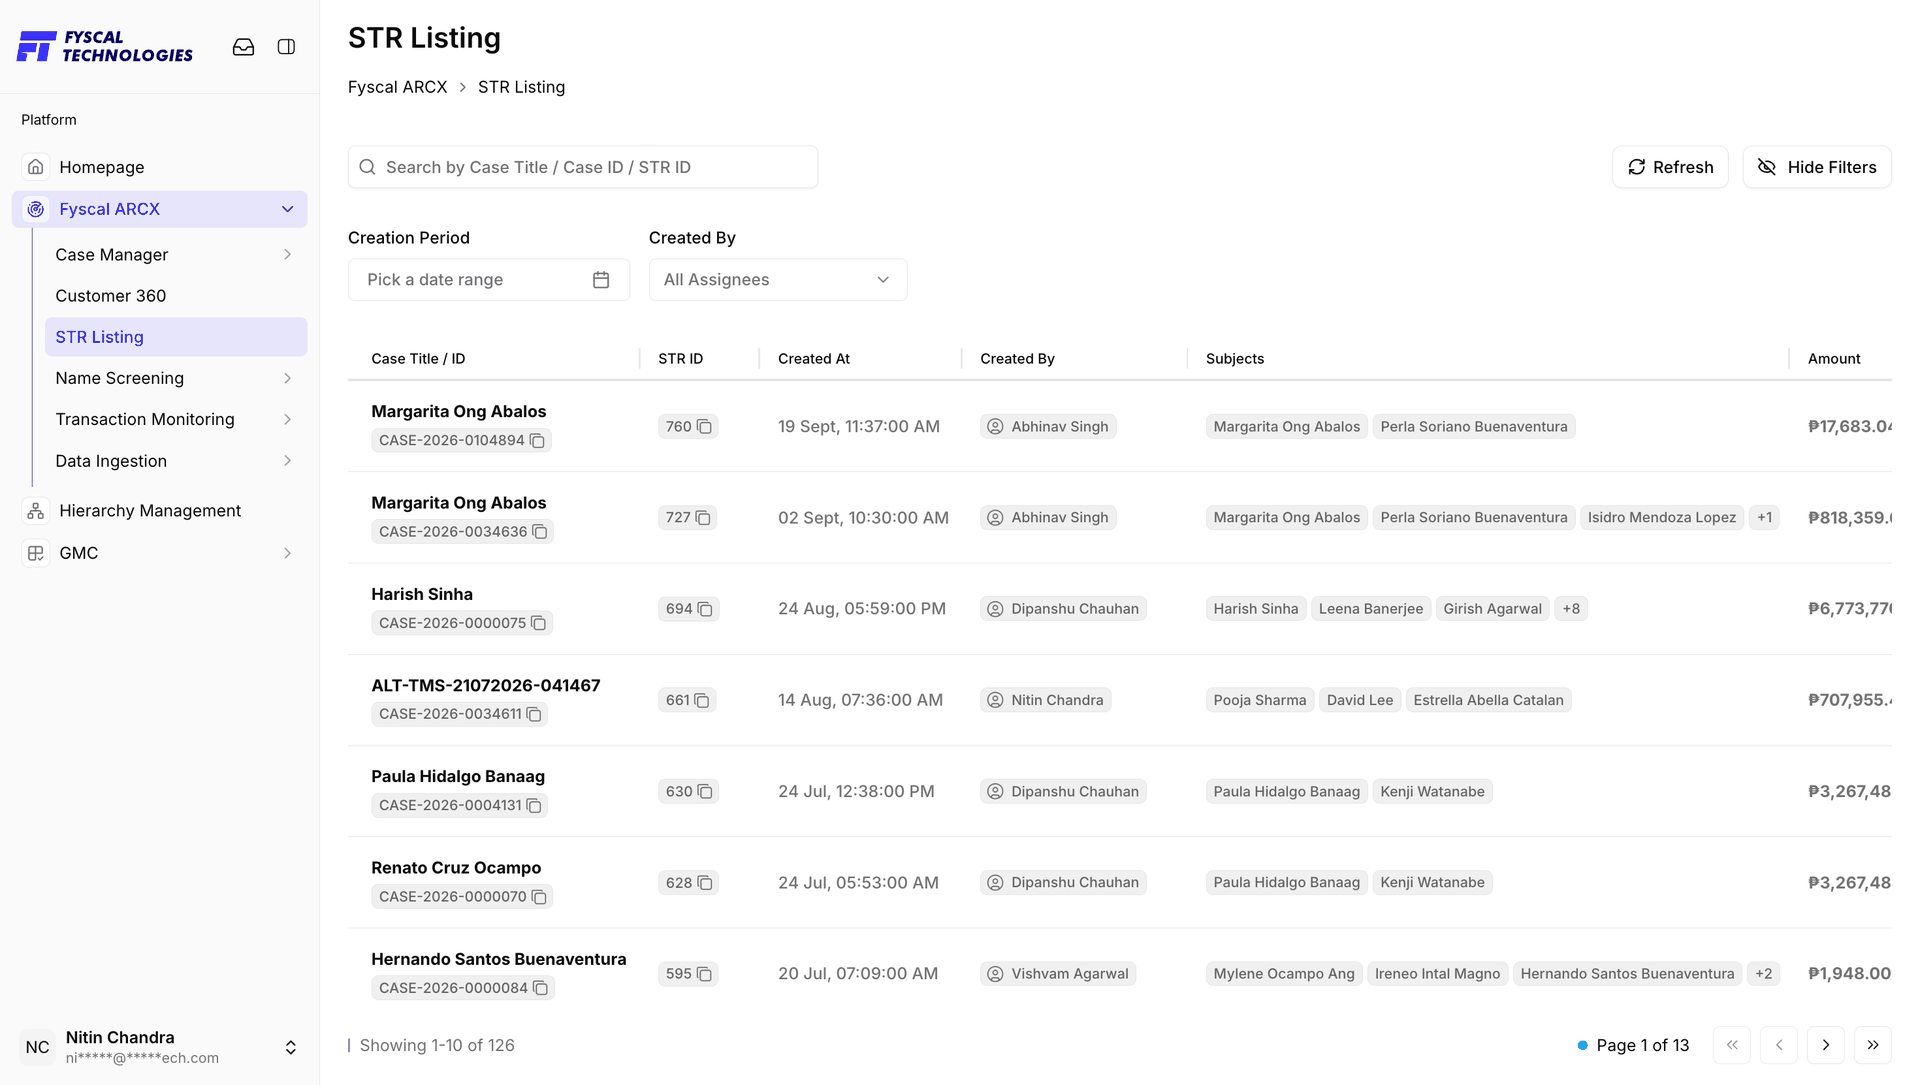
Reviewing filings from a specific period, or by one analyst? Use the two filters.
Creation Period opens a two-month calendar to bound the search to a specific date range; Created By narrows to filings raised by one specific analyst.
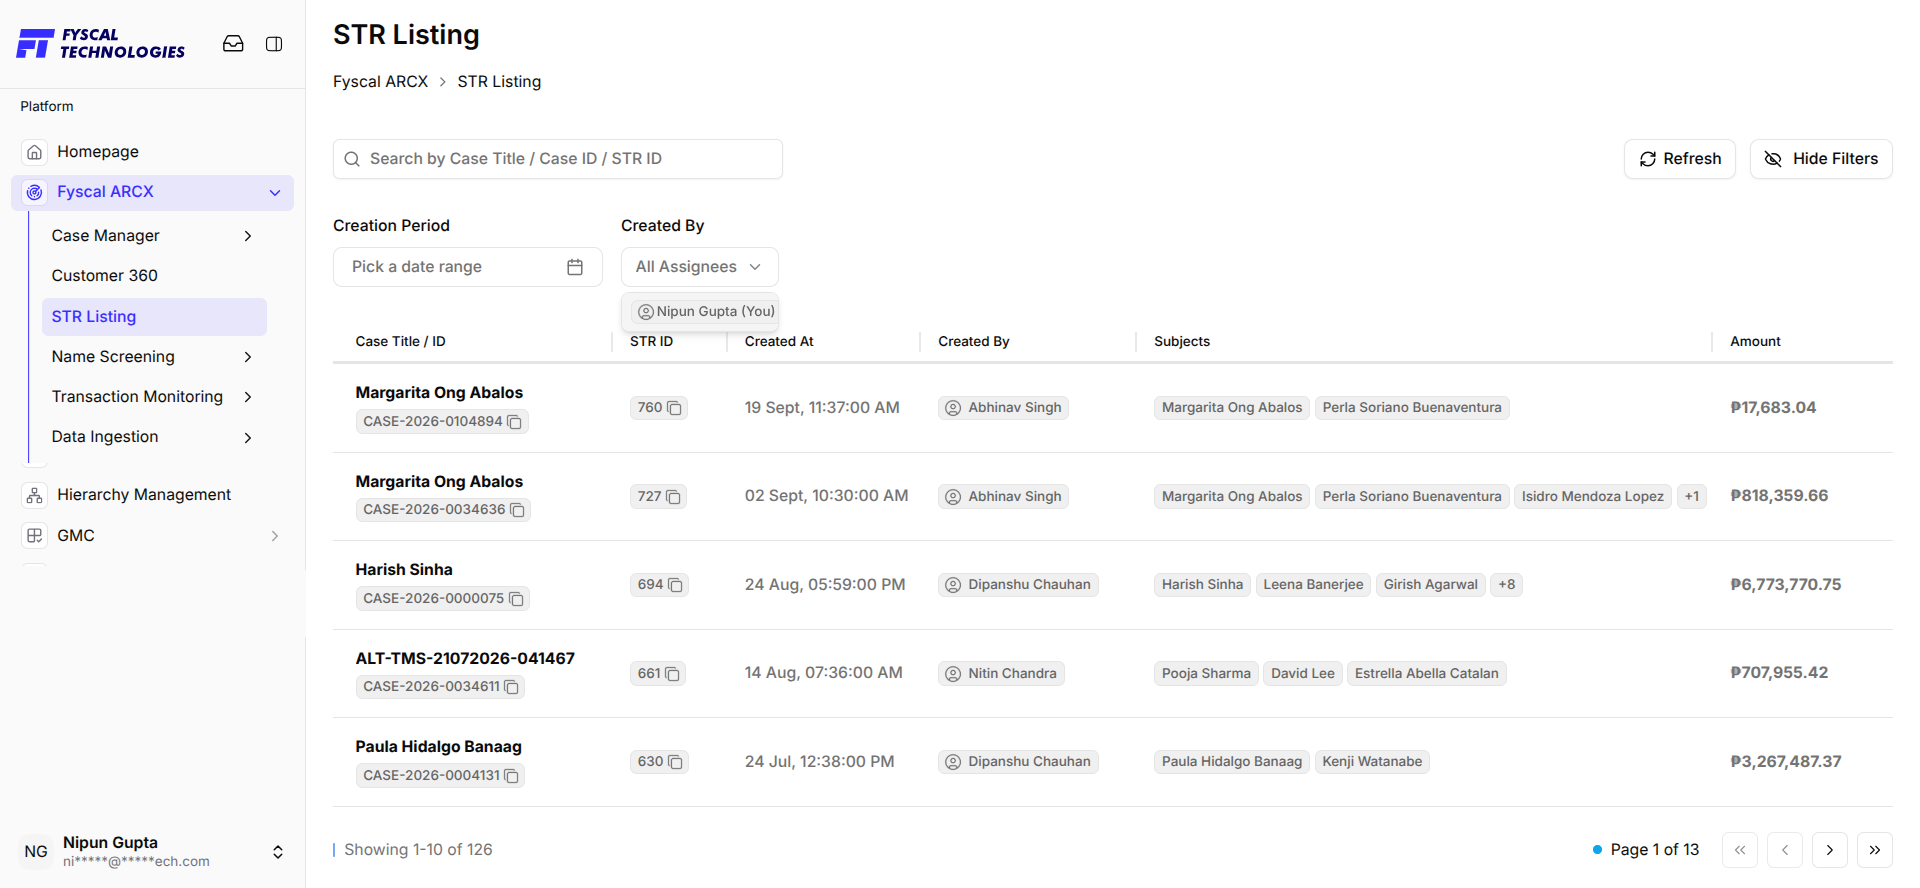
Need the full filing detail for one row? Open it, or export it.
How an STR gets filed, end to end: STR Listing is a register — there is no separate "create STR" form here. A filing is always the output of a case that has already been investigated in Case Manager, produced through a guided, GoTRACS-compliant wizard. In the current build, selecting a row here opens that case's filing in the same six-step wizard. The full walkthrough, with a screenshot of every step, is under Case Manager → Filing an STR; in short:
| Column | What it shows |
|---|---|
| Case Title / ID | The customer or subject name and the case that produced this STR |
| STR ID | A sequential internal reference number for the filing |
| Created At | Date and time the STR was generated |
| Created By | The analyst or MLRO who raised the filing |
| Subjects | Every individual or entity named in the STR — a filing can name more than one subject if a case involves linked parties |
| Amount | The cumulative transaction value associated with the filing |
| Download CSV | Exports the filing's underlying transaction and subject detail for submission or record-keeping |
A single STR listing three subjects and an amount of ₹747,569.31 tells the MLRO, at a glance, that this was a multi-party case — worth opening before smaller single-subject filings when prioritizing a regulator review.
Screens individuals and entities against the LSEG watchlist database to identify potential sanctions, PEP, and adverse media matches.
The module offers four ways to run a screen, used for different situations: Watchlist Search for an ad-hoc, on-demand lookup; Manual Screening for screening one customer with full profile detail during onboarding or review; Batch Screening for re-screening large customer populations on a schedule; and Delta Screening for automatically re-checking only the customers affected when the watchlist itself changes. All four draw on the same matching rules and severity bands set once in Configuration, so a match found through any method is scored and prioritized consistently.
Enables users to search for individuals or entities against the LSEG watchlist database. Used for ad-hoc, on-demand lookups — e.g. screening a customer against an international sanctions list before opening an account.
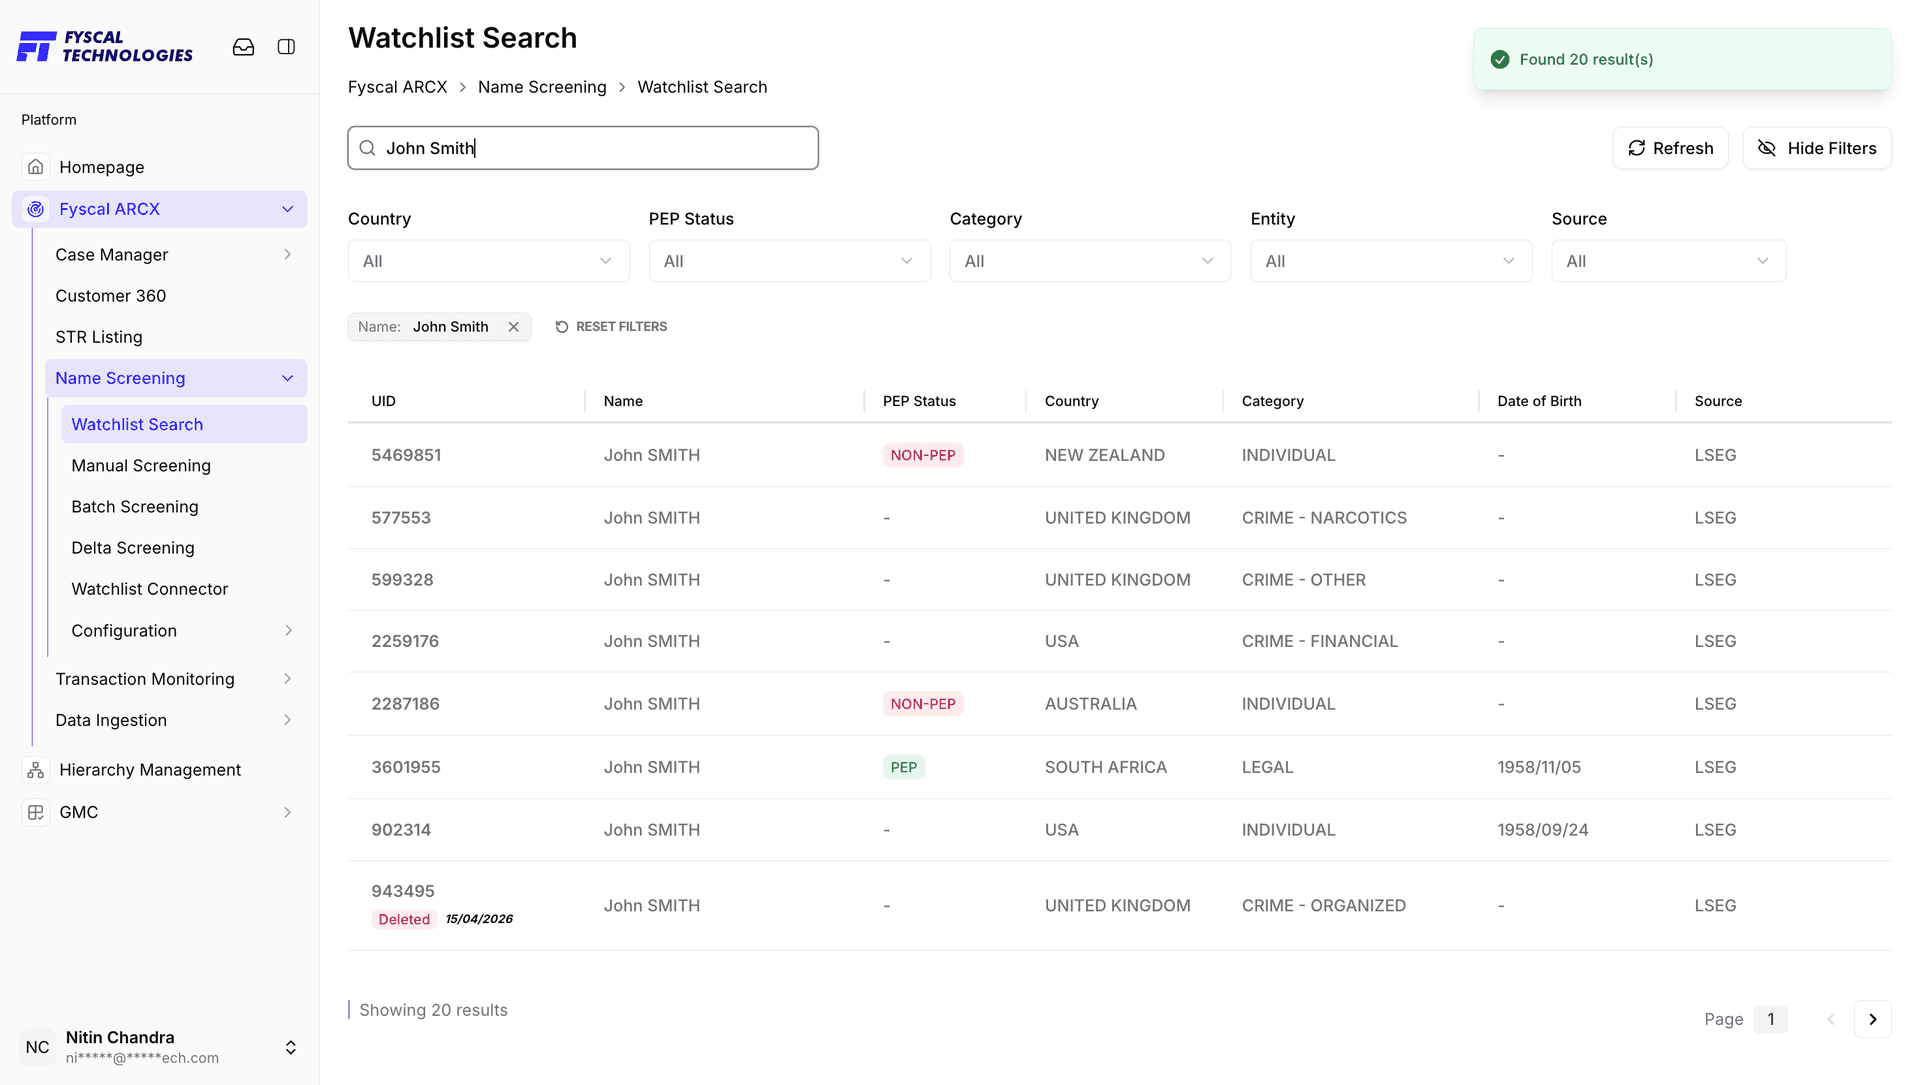
| Column | What it shows |
|---|---|
| UID | The unique identifier for that watchlist record within the source list |
| Name | The individual or entity name as held on the watchlist |
| PEP Status | Whether the record is flagged PEP (politically exposed person), NON-PEP, or carries no PEP status (shown as a dash) |
| Country | The country associated with the record |
| Category | The kind of record — for example Individual, Legal, or a crime category such as Crime - Narcotics |
| Date of Birth | Where available — many watchlist entries carry only a partial or missing date of birth, which is why Name and Address weightages matter so much for matching |
| Source | Which list the record came from (LSEG in this example) |
A record the provider has since withdrawn stays visible but is tagged Deleted in red, with the date, directly under its UID — so you can tell a withdrawn record from a live one.
A branch officer searches “John Smith” with Country set to United Kingdom and PEP Status set to PEP, to quickly check whether a walk-in customer appears on any current sanctions or PEP list before opening an account.
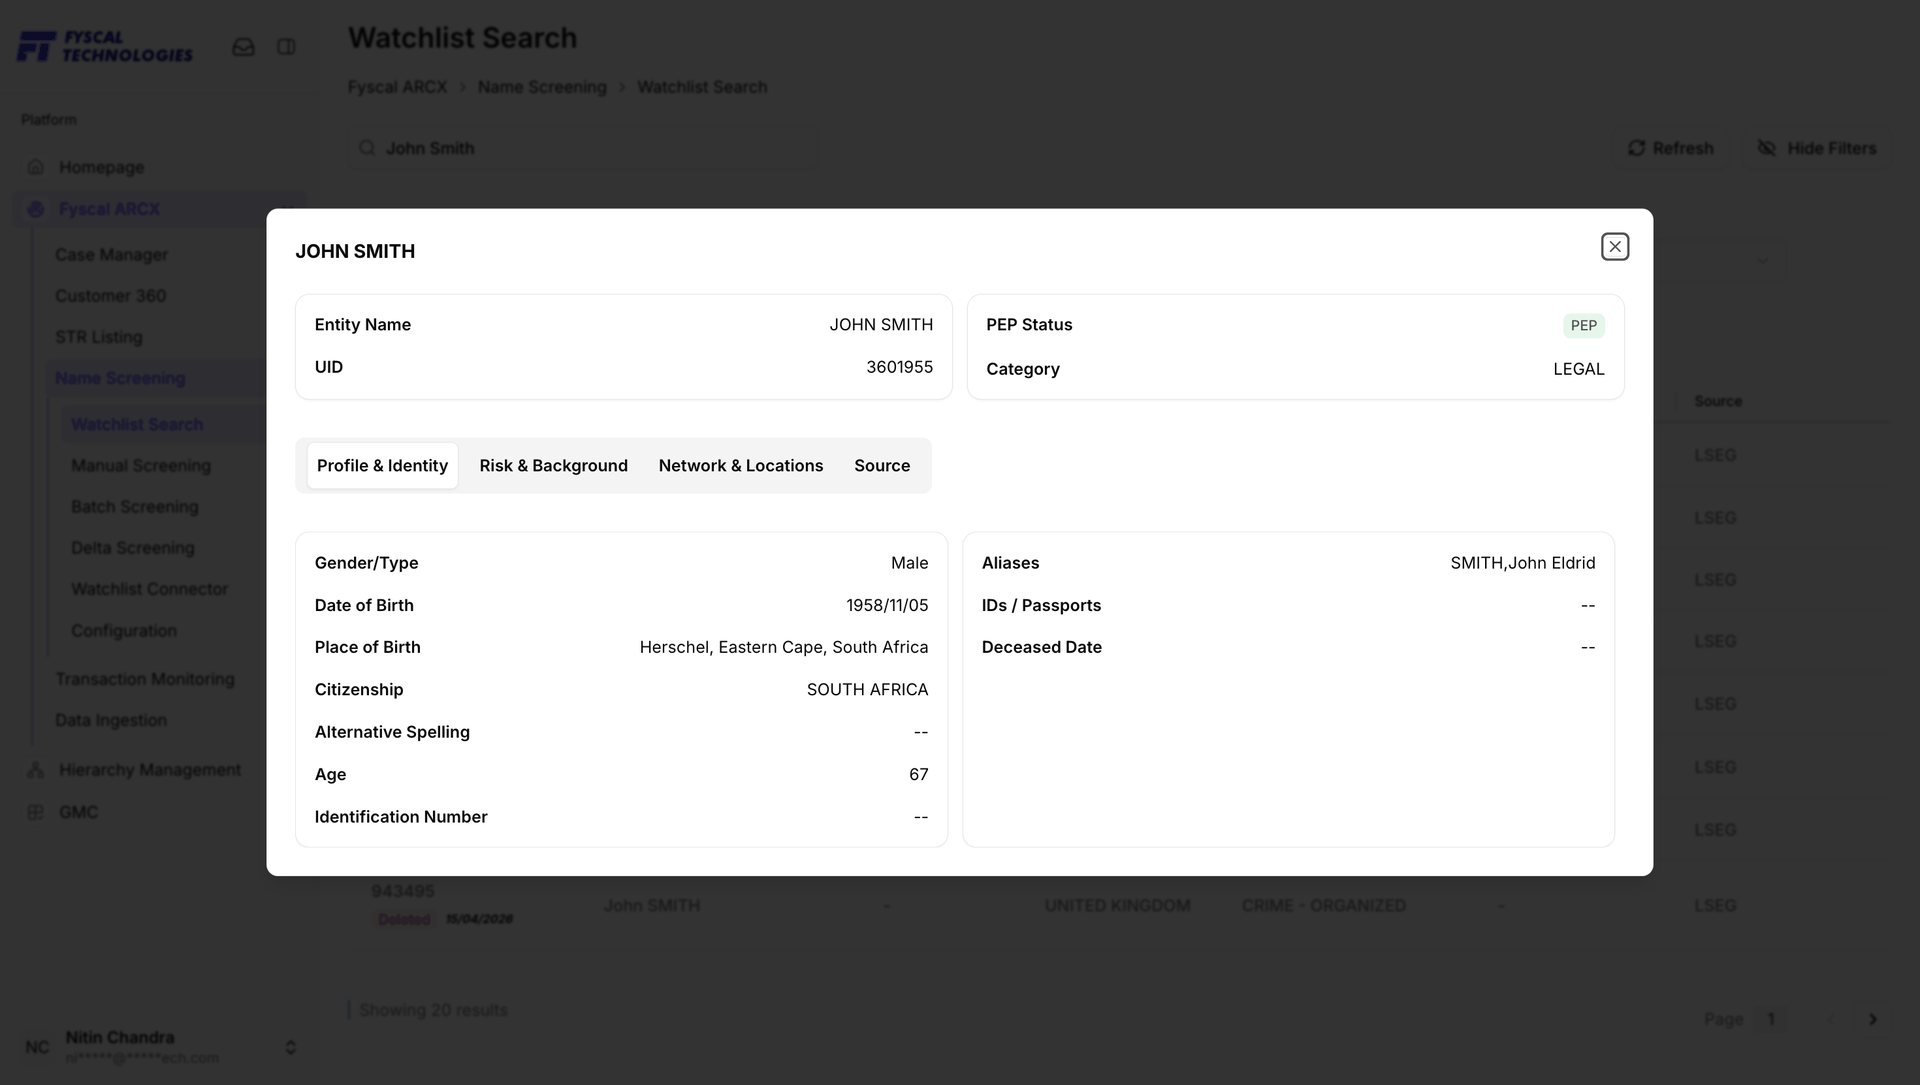
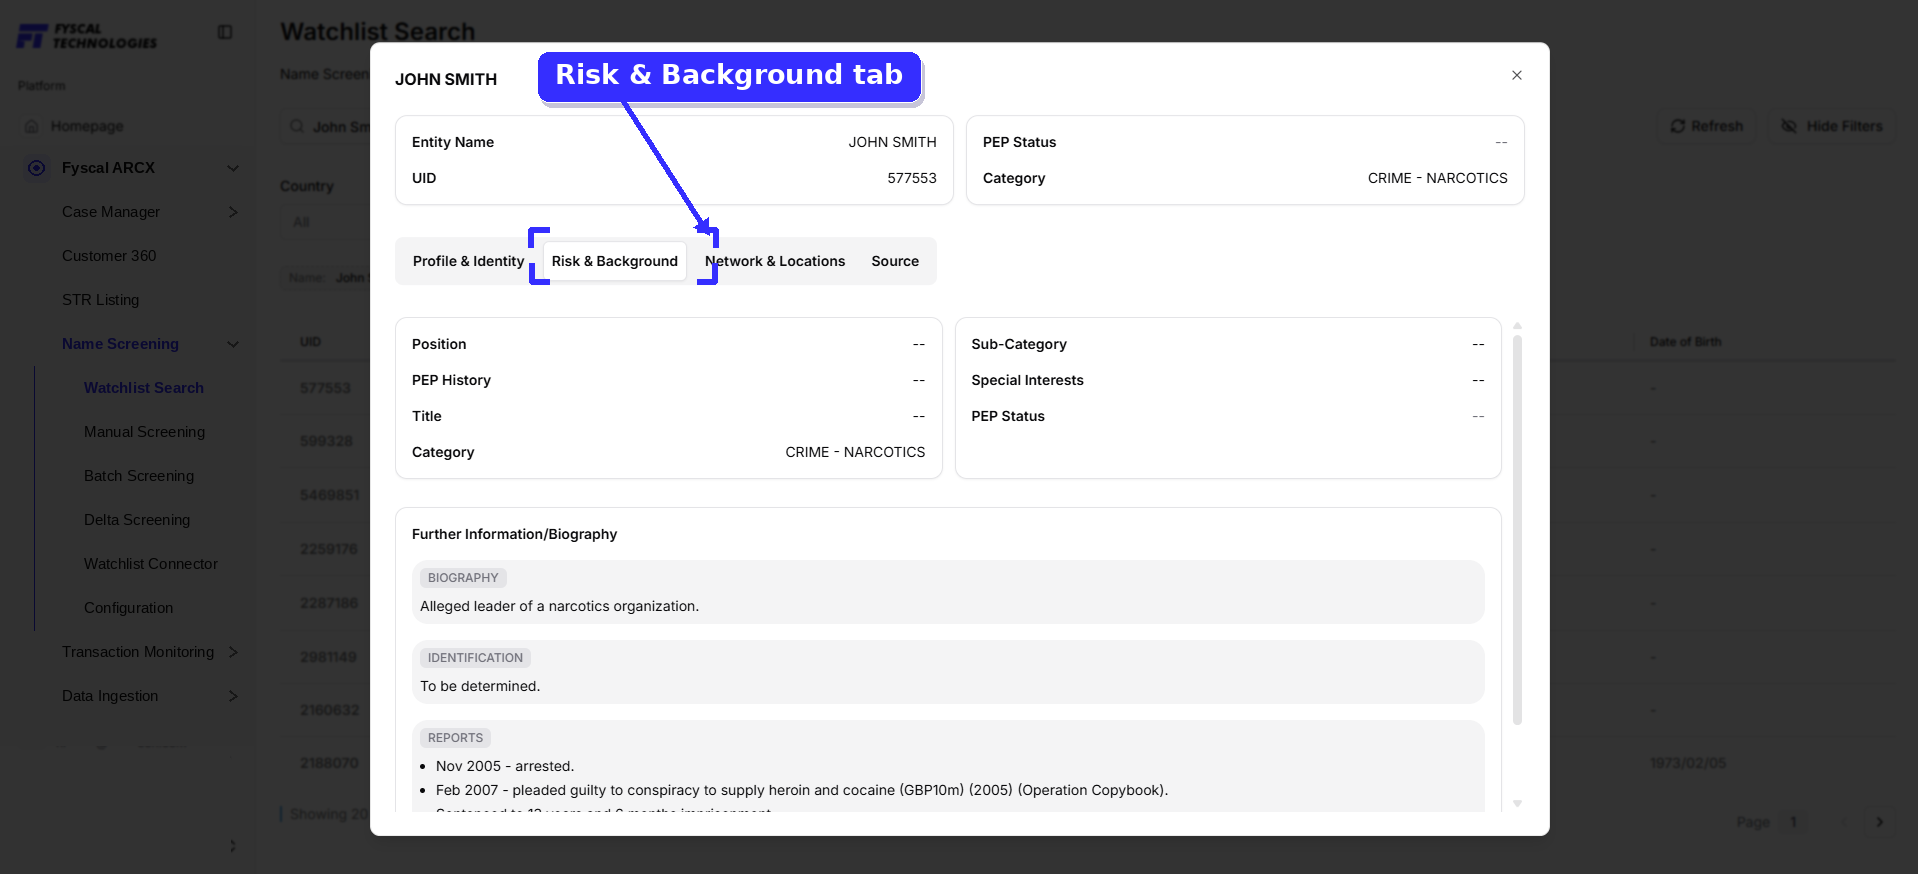
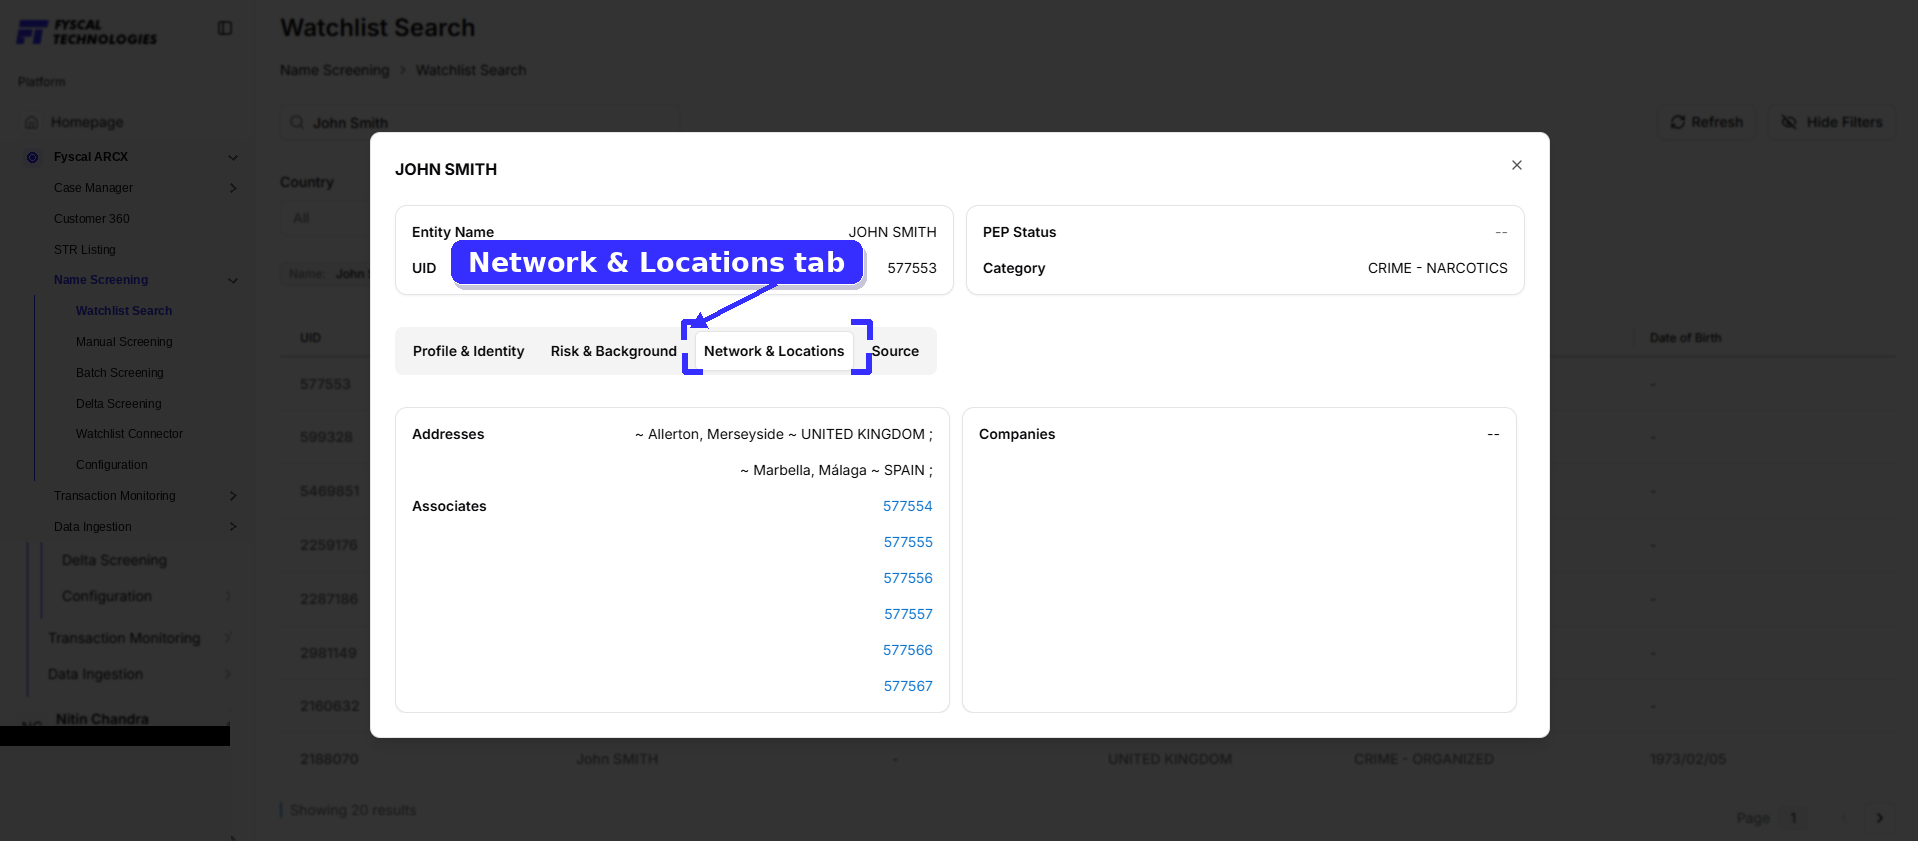
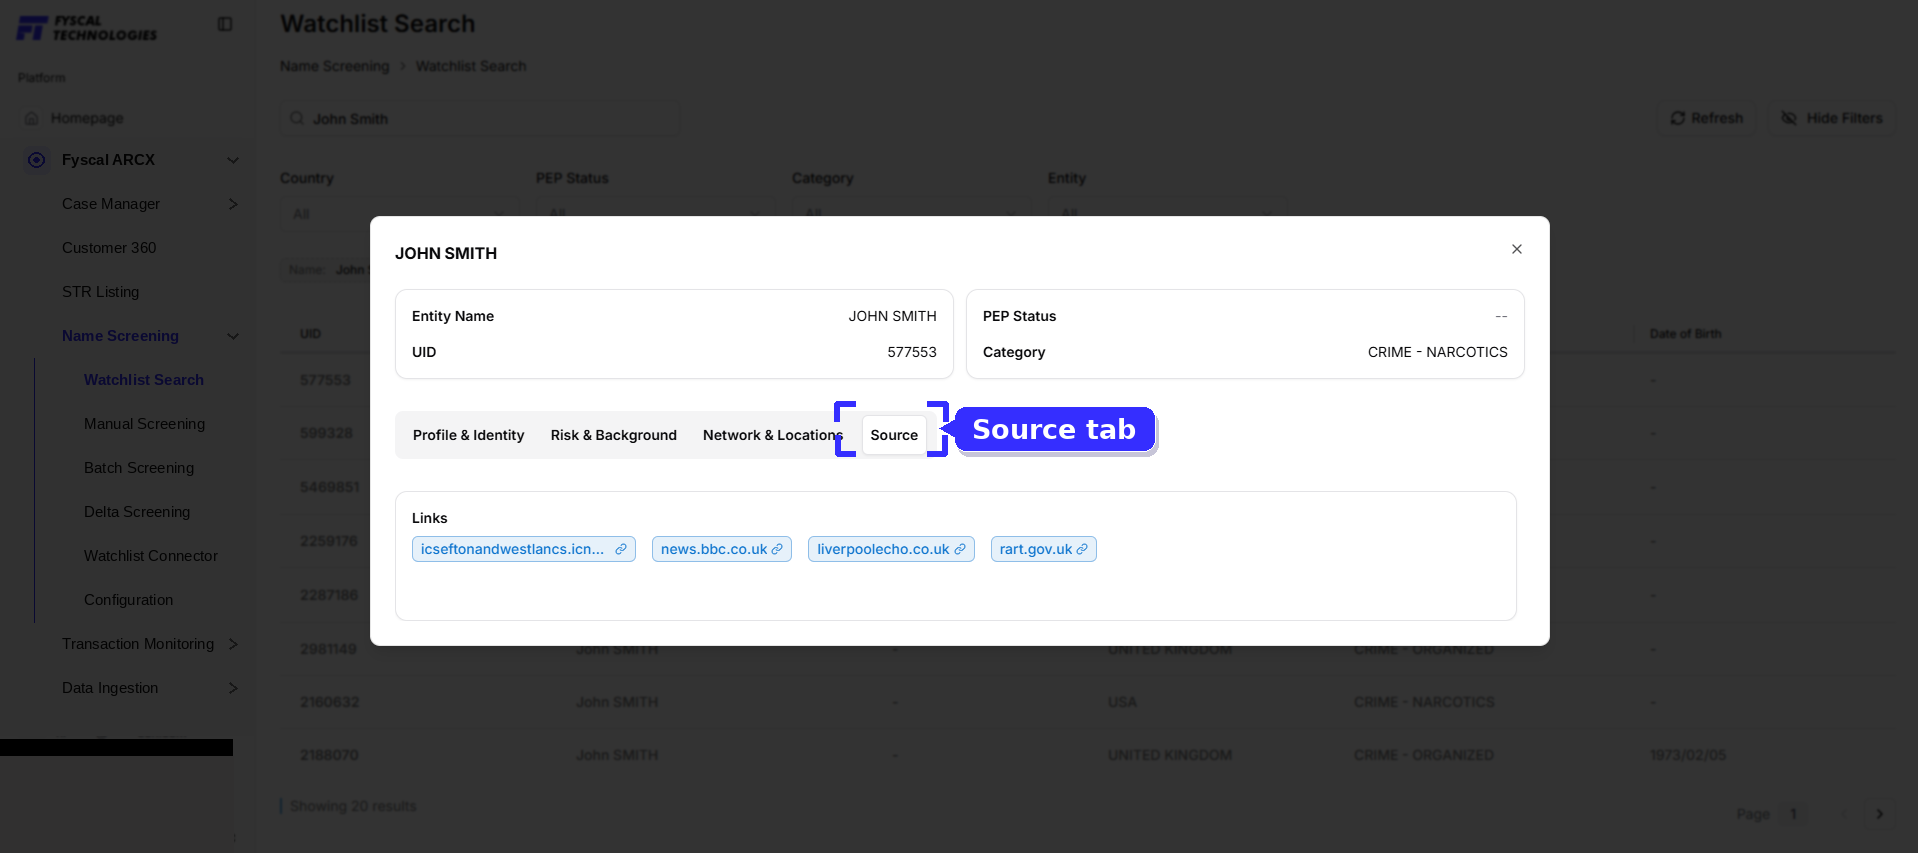
Record detail — clicking any result row opens the full watchlist record in a modal, organized into four tabs:
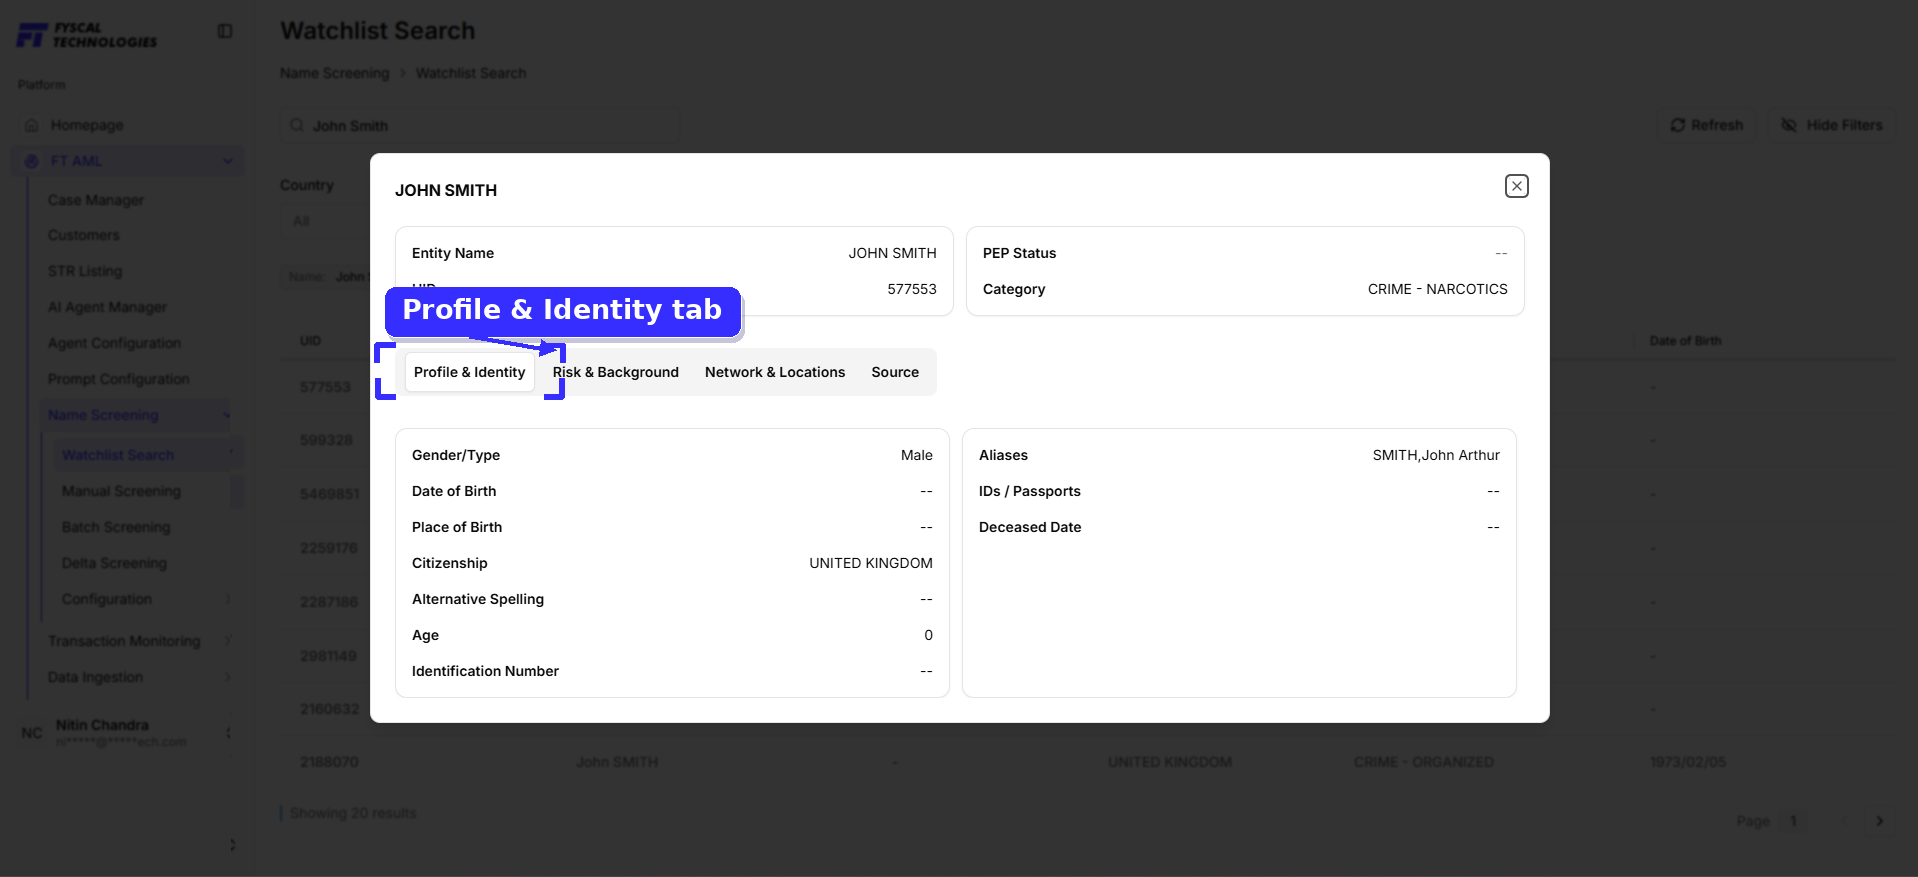
The same tab for a PEP record looks slightly different. Here the header shows the entity name and UID on the left and, on the right, a green PEP chip beside PEP Status together with the record's Category (LEGAL). Below, Profile & Identity lists gender, date of birth, place of birth, citizenship, alternative spelling, age and identification number on the left, and aliases, IDs/passports and deceased date on the right. A dash means the watchlist holds no value for that field — common for older or sparsely documented entries.
Allows users to screen an individual or entity by manually entering customer information. The system compares the provided details against the watchlist database using configured matching criteria and weightages to identify potential matches. This gives analysts flexibility to screen immediately during investigations, onboarding, periodic reviews, or whenever customer information changes — outside the scheduled automated screening cycle.
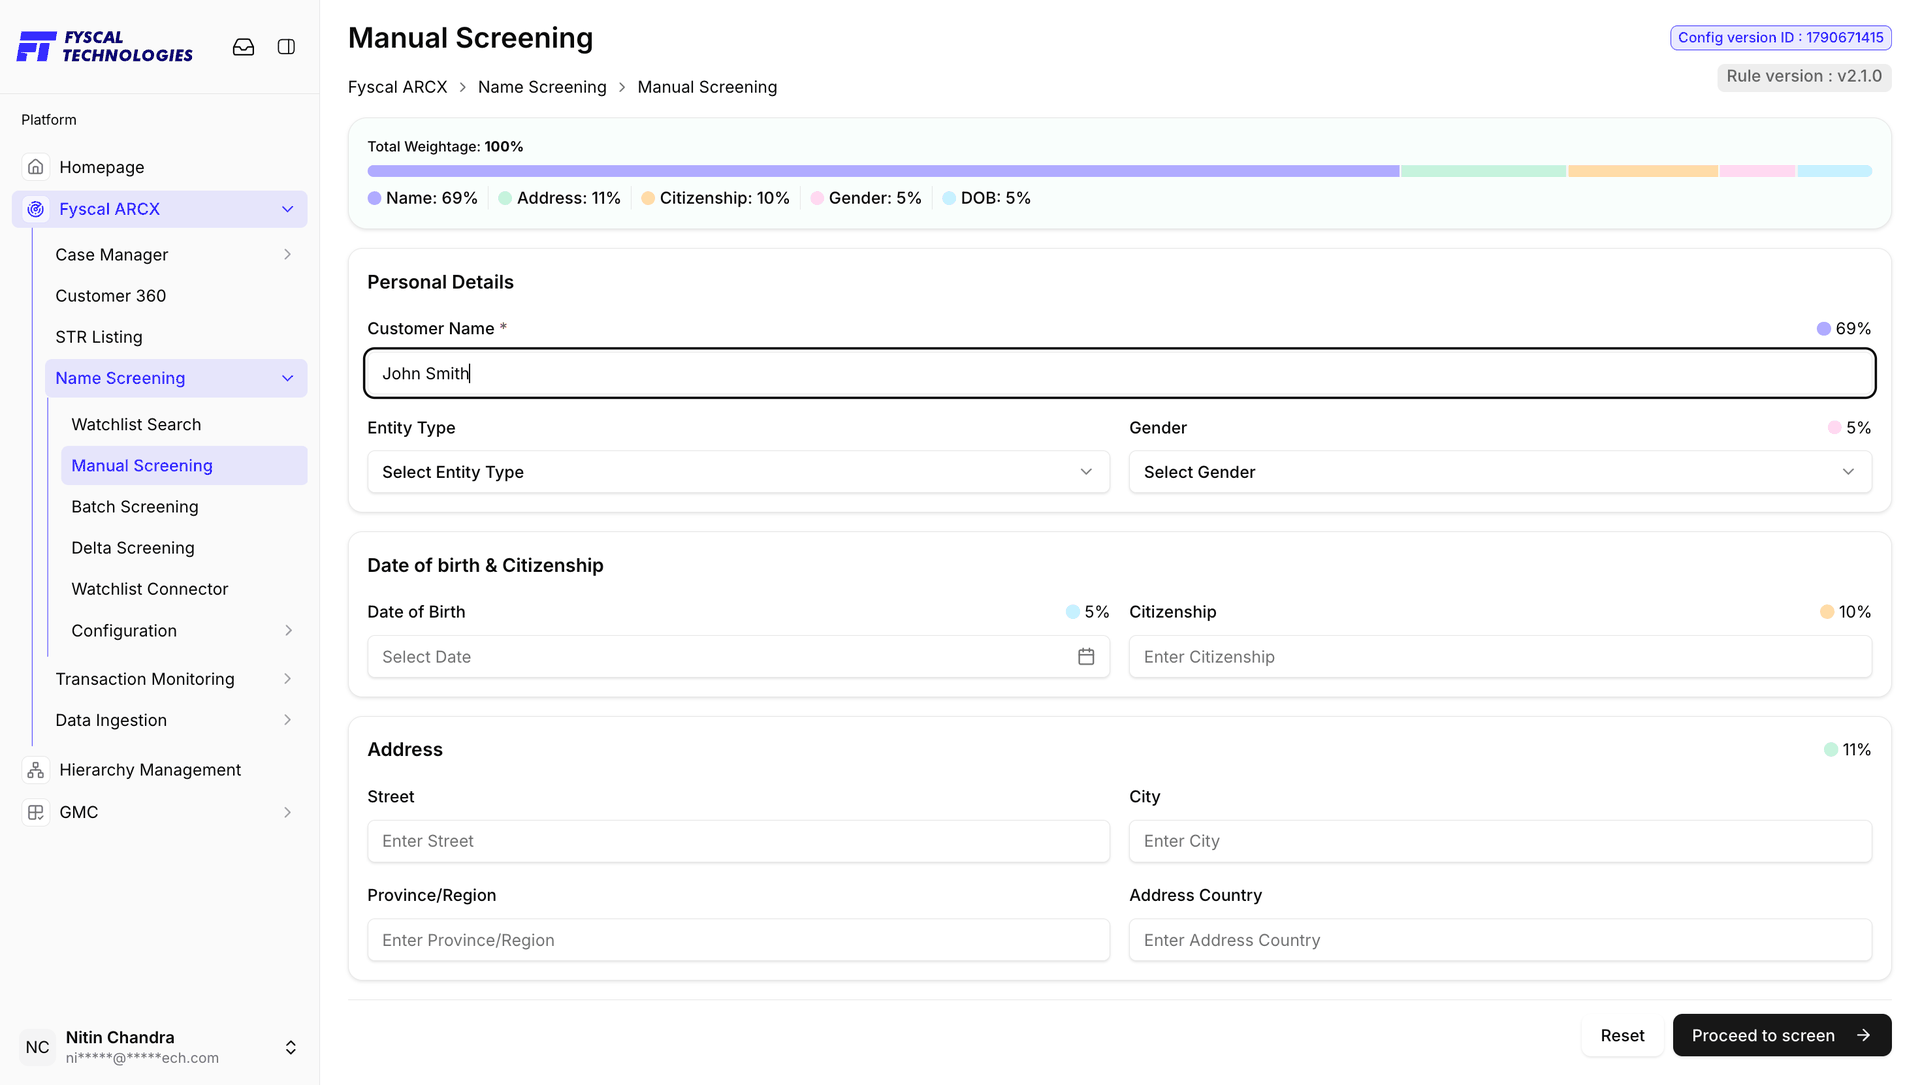
The weightage bar at the top of the screen shows exactly how much each field contributes to the final match score before you screen — set once for the whole institution in Screening Configuration, and simply displayed here for reference on every manual screen.
After Proceed to screen, the Screening Details page opens (Name Screening → Manual Screening → Screening Details). Its header shows the screening date and a unique Screening ID, and a Matches counter gives the number of hits found — 50 in the example below. The left-hand column repeats what you entered; each match to its right is shown alongside it, with a severity badge and score, any PEP status, the entity type, the UID, and the Weightage and Score each field (Name, Nationality, Date of Birth, Address, Entity Type) contributed.
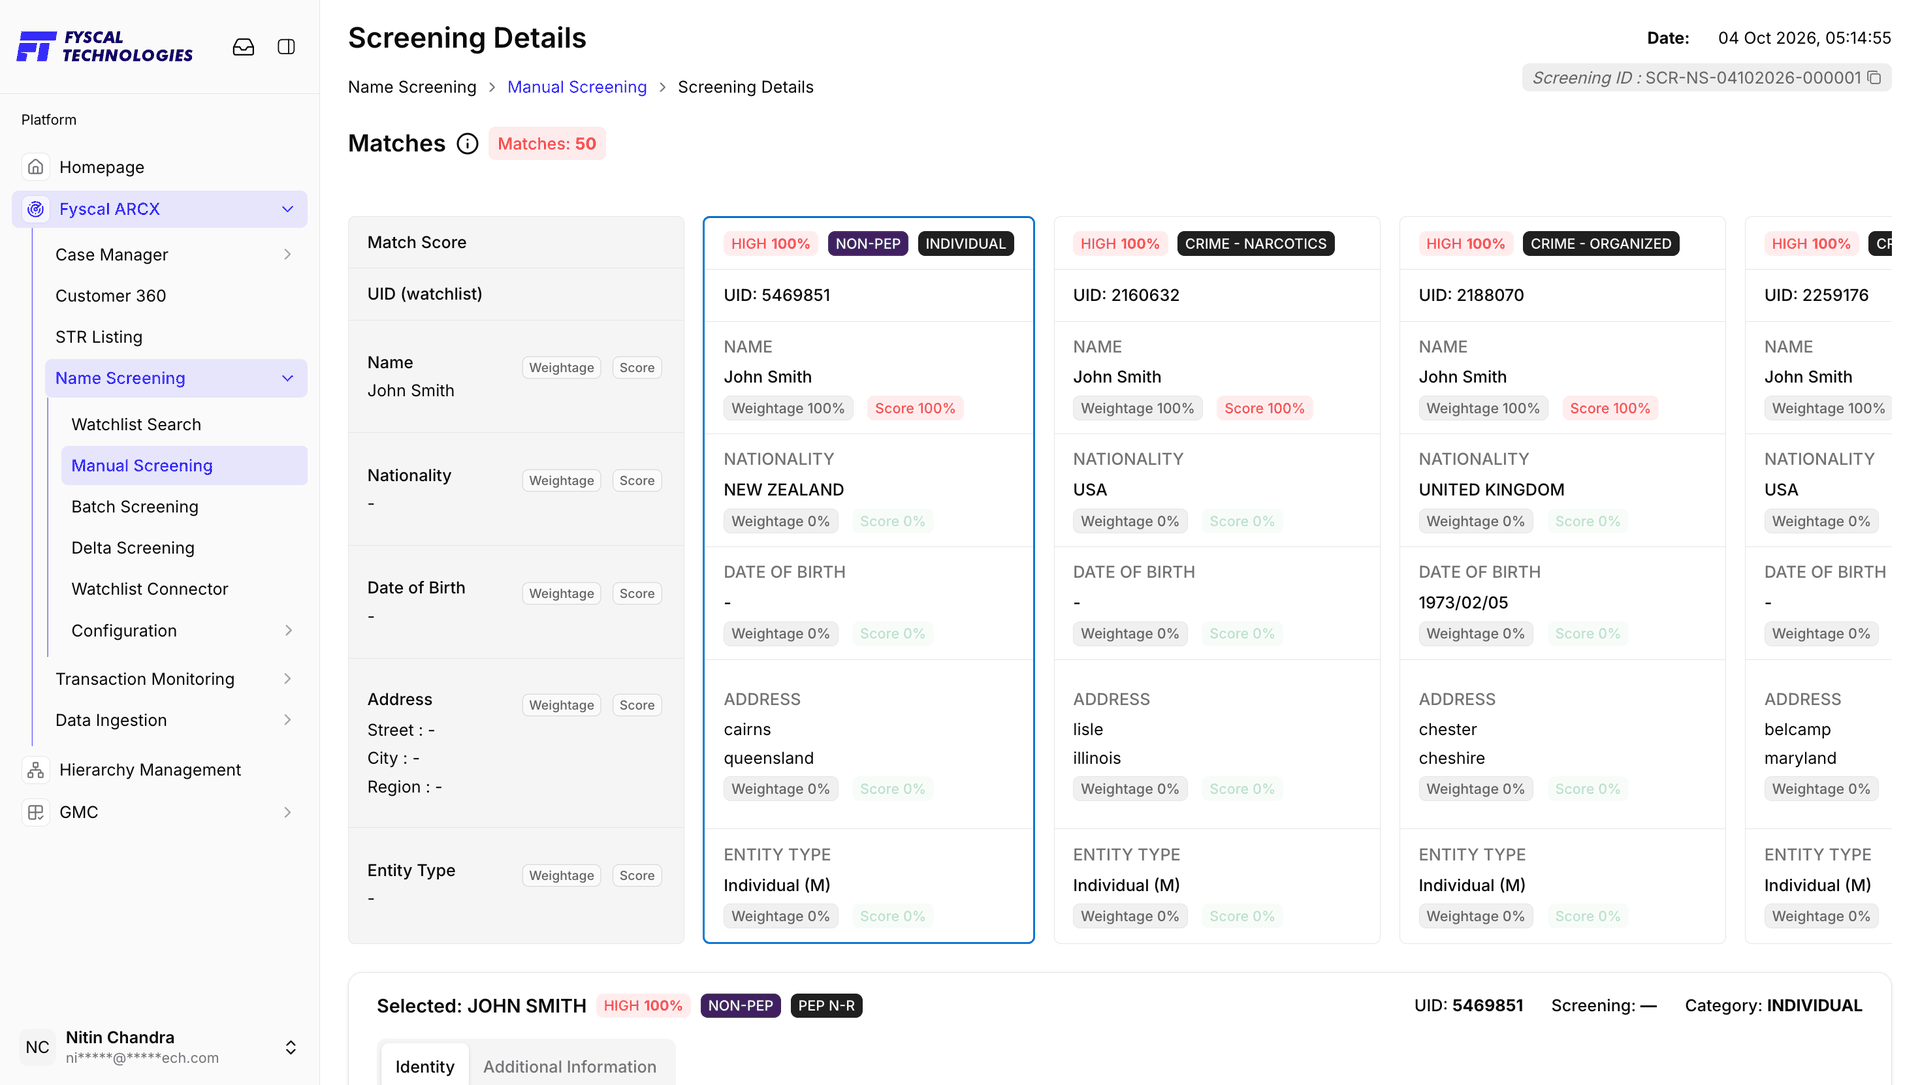
Selecting a match shows its full watchlist record underneath, on two tabs. Identity holds the identity summary (entity type, place of birth, citizenship, date of birth, nationality, address, deceased status) and known aliases and spellings.
Additional Information shows the record's PEP Status (Active or Inactive), list classification (category and sub-category), associates by UID, keywords and external sources, further information such as biography and reports, and list metadata.
During onboarding, an analyst manually screens a new corporate client, “Meridian Trading Ltd”, entering its registered address and country of incorporation, and reviews the resulting match scores on the Screening Details page before the account is approved.
Screens large customer populations at once (e.g. nightly onboarding batches), letting institutions re-screen millions of records efficiently — e.g. running the entire customer base overnight the moment a new sanctions list is received, instead of reviewing customers individually. Batch Screening itself is a read-only history of past runs — scheduling and triggering these runs is configured from Data Ingestion → Batch Ingestion instead, keeping all recurring-job scheduling in one place across the platform.
The header bar shows the current schedule (Active/Inactive, frequency, next and last run — matching the same style used in Data Ingestion → Batch Ingestion). Each row in the table below then shows:
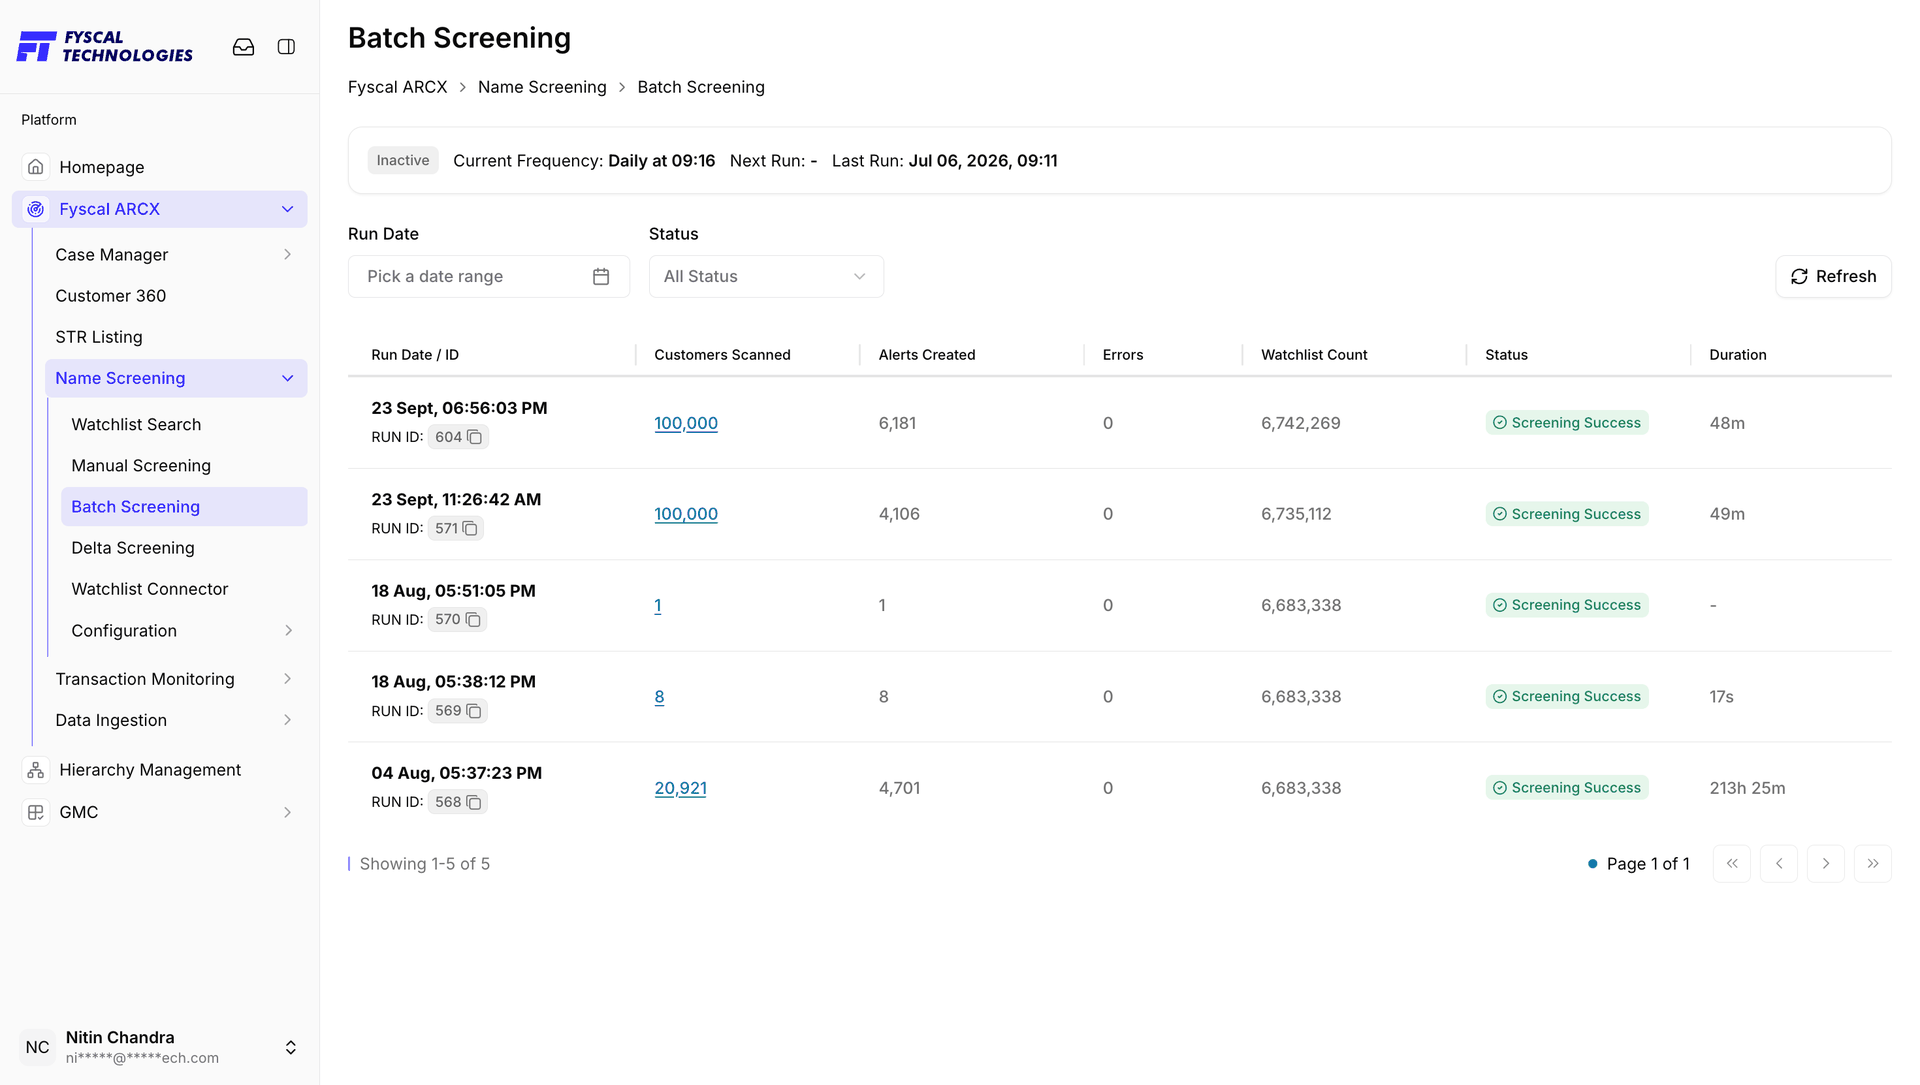
| Column | What it shows |
|---|---|
| Run Date / ID | When the run started, plus its unique Run ID reference |
| Customers Scanned | How many customers the run screened — click the number to open the run's details |
| Alerts Created | How many hits the run produced |
| Errors | Records that failed to process, if any |
| Watchlist Count | Size of the watchlist the run screened against |
| Status | Screening Success, In Progress, or Failed |
| Duration | How long the run took, start to finish |
Opening a run shows its Details panel rather than a separate page. It repeats the Customers Scanned, Alerts, and Errors totals, then adds the exact Started, Completed, and Duration timestamps, the Input File the run was screened against, and a Download Results CSV button to export that run's screened records and alerts for offline review or record-keeping.
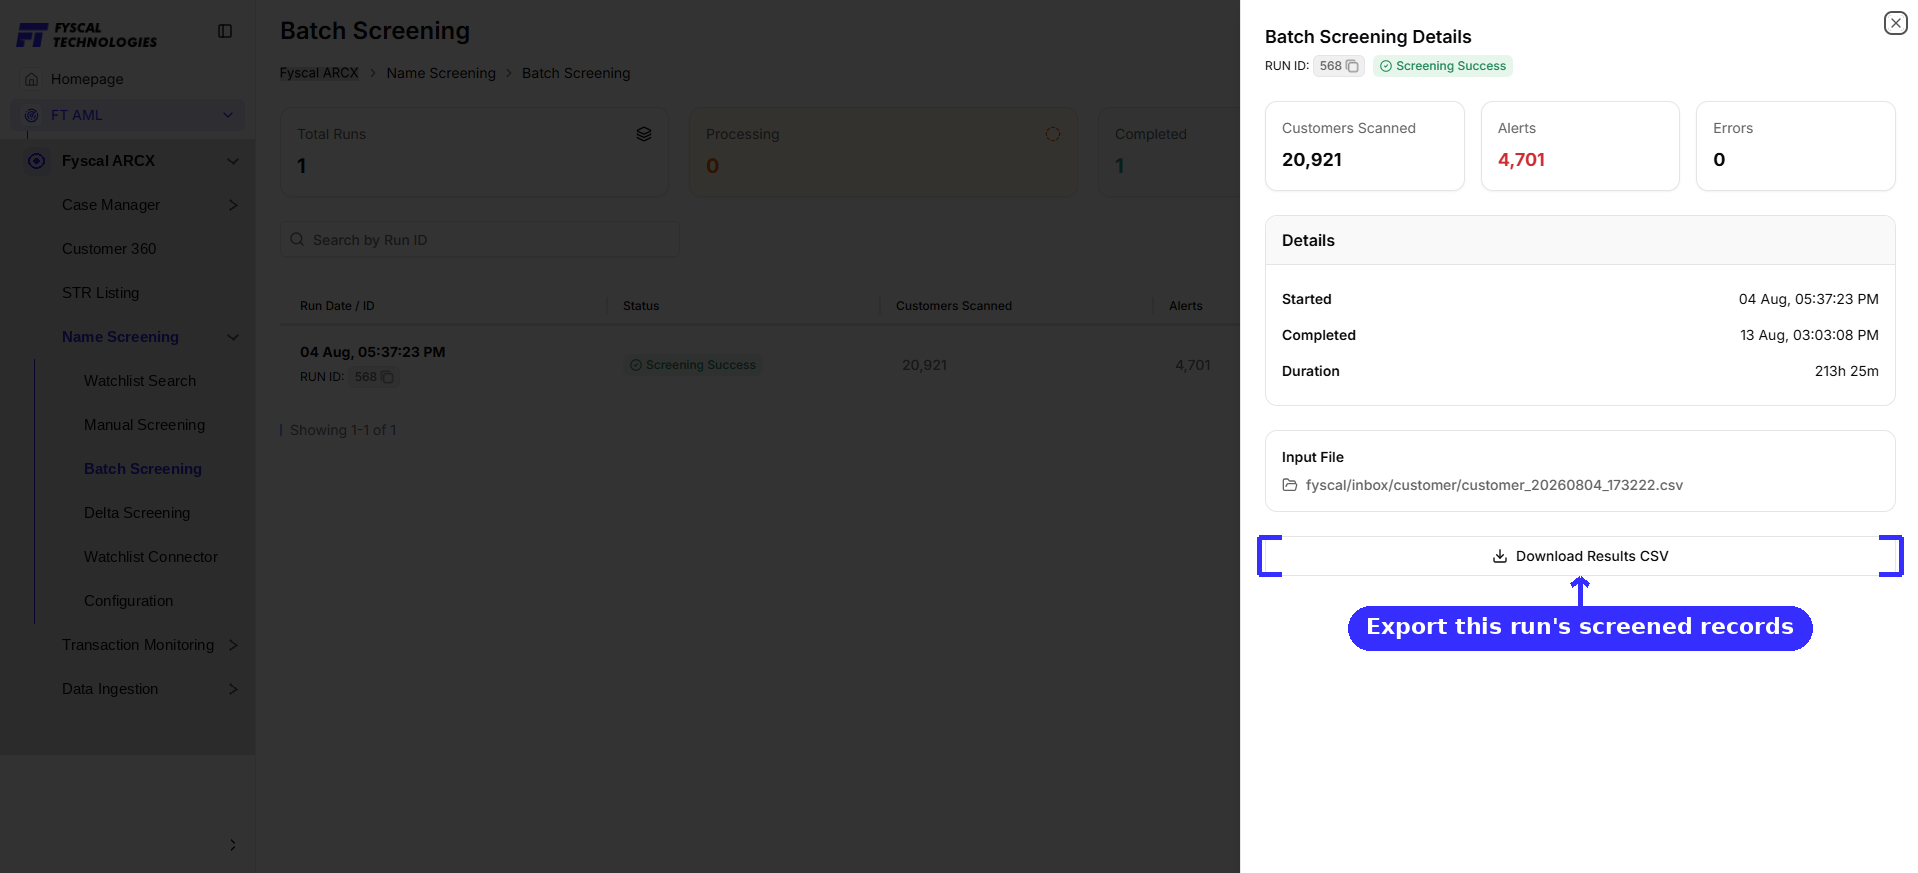
Each night, the institution's entire retail customer base is submitted as a batch job, so that any new sanctions or PEP list updates are checked against every customer without manual effort. The next morning, a compliance officer opens that run in Batch Screening to confirm it completed cleanly and download the results.
Automatically re-screens previously screened customers when the watchlist updates — the primary control for continuous, rather than point-in-time, compliance. Only the customers affected by the latest watchlist update are re-screened — e.g. a previously cleared customer is automatically rechecked the moment a new sanctions list is published, without reprocessing the full customer base.
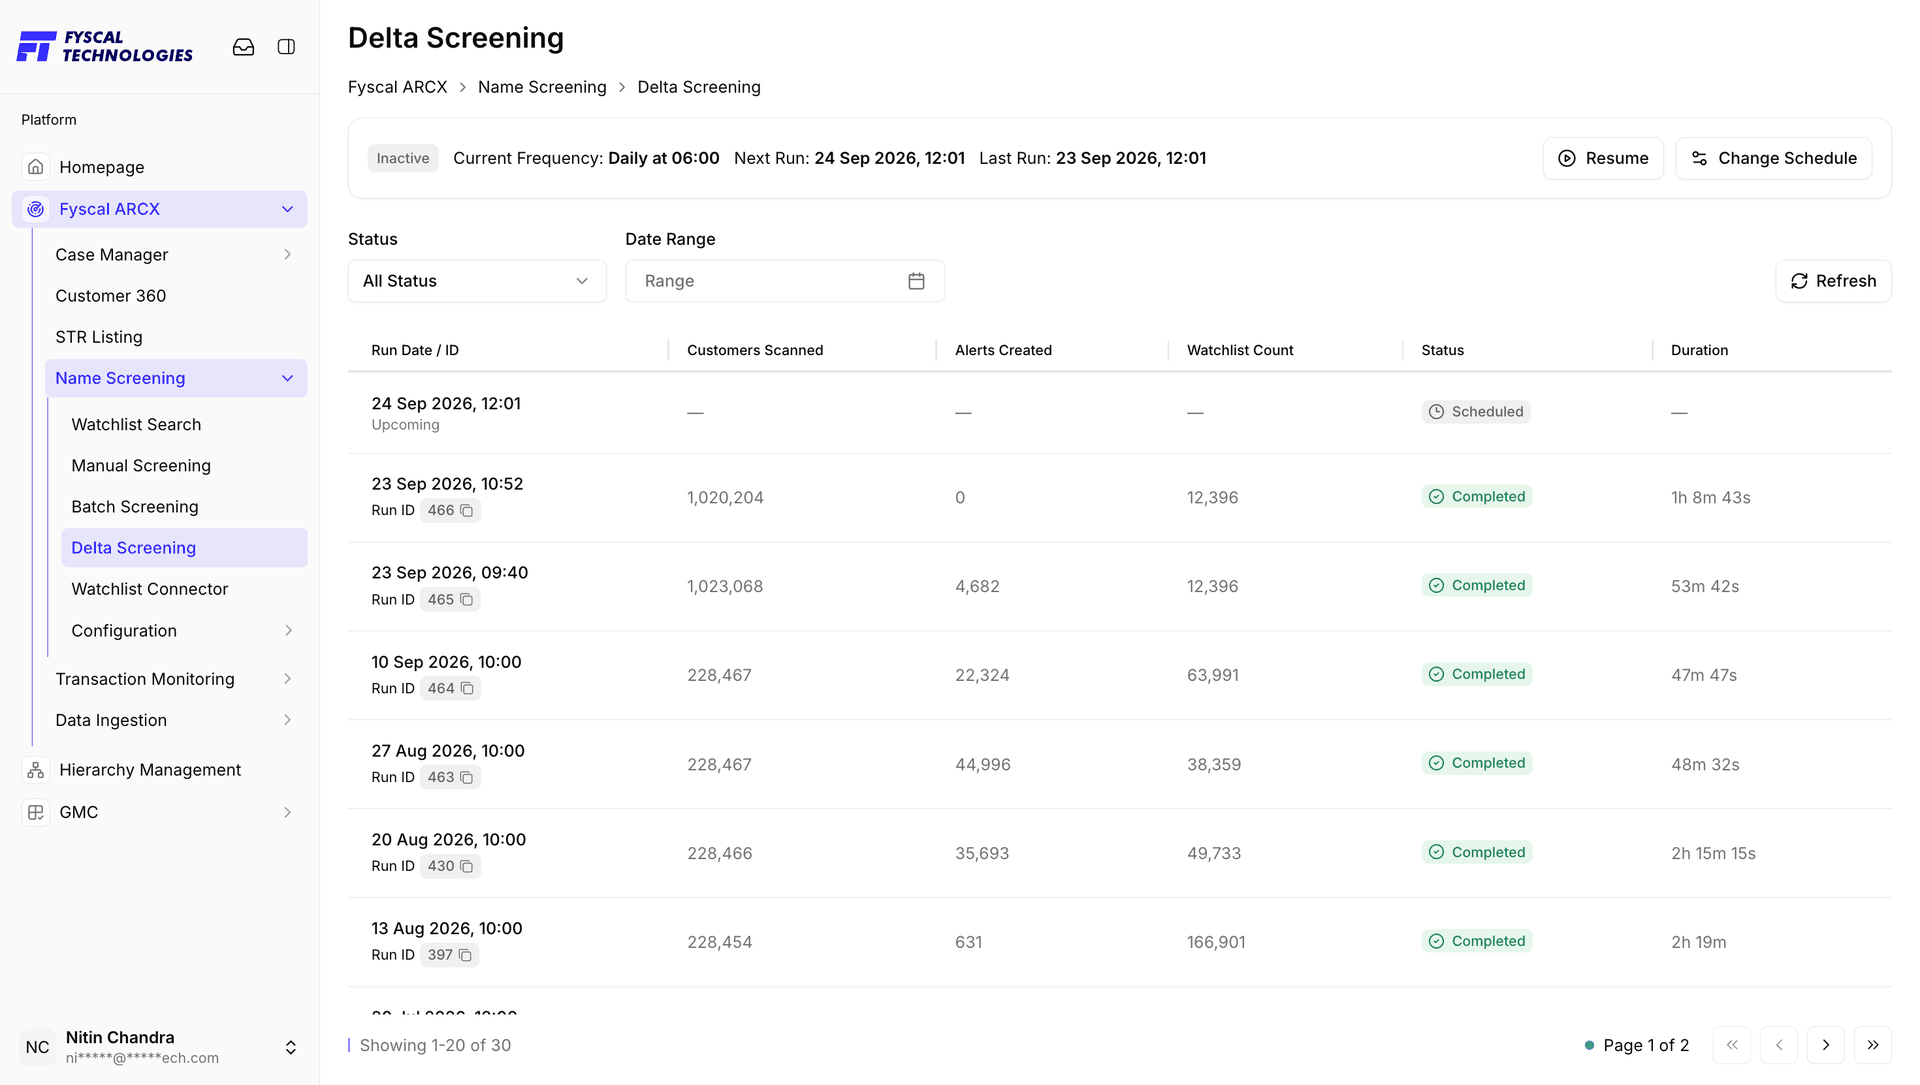
| Column | What it shows |
|---|---|
| Run Date | When that scheduled run executed, or Upcoming for the next scheduled run |
| Customers Scanned | How many previously screened customers were affected by the watchlist update and therefore re-checked |
| Alerts Created | New hits produced by that run — often zero, since most watchlist updates don't affect any existing customer |
| Watchlist Count | Size of the watchlist the run screened against |
| Status | Scheduled, Completed, or a run currently in progress |
| Duration | How long the run took to complete |
Change Schedule opens the Change Screening Schedule dialog. It shows the current frequency and a reminder that any change — frequency or time — takes effect after the next scheduled run. Choose the New Frequency (e.g. Daily) and the Run Time (in UTC), and give a Reason describing why the schedule is changing; a Next Run Preview confirms what the new schedule will do before you click Review Changes.
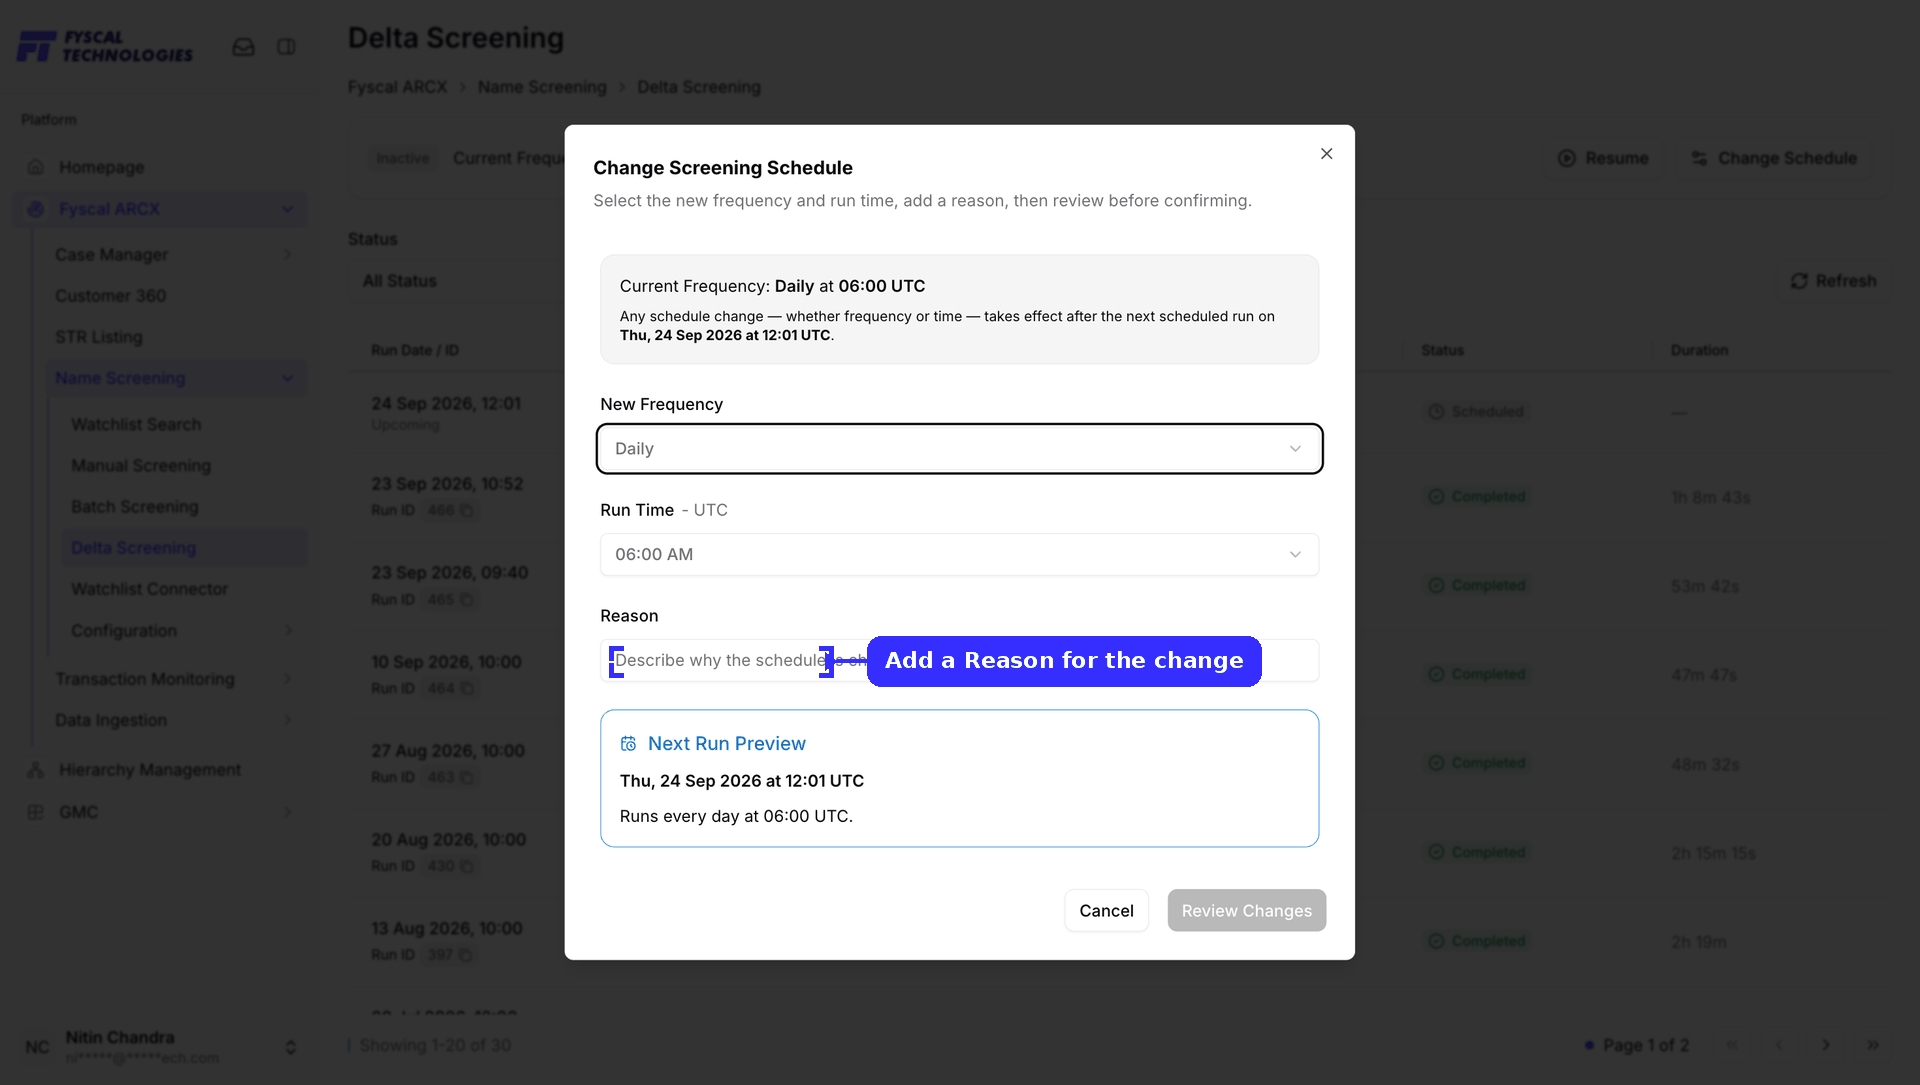
When a new sanctions list is published, only the customers affected by that update are automatically re-screened overnight, and any new hits appear in Alerts the next morning — with no need to re-run the full customer base.
Controls how strictly a record must match, and how resulting hits are prioritized for review. Both screens work the same way: one configuration is Active at a time, Edit changes it, every save creates a new version, and Configuration History keeps every earlier version for audit.
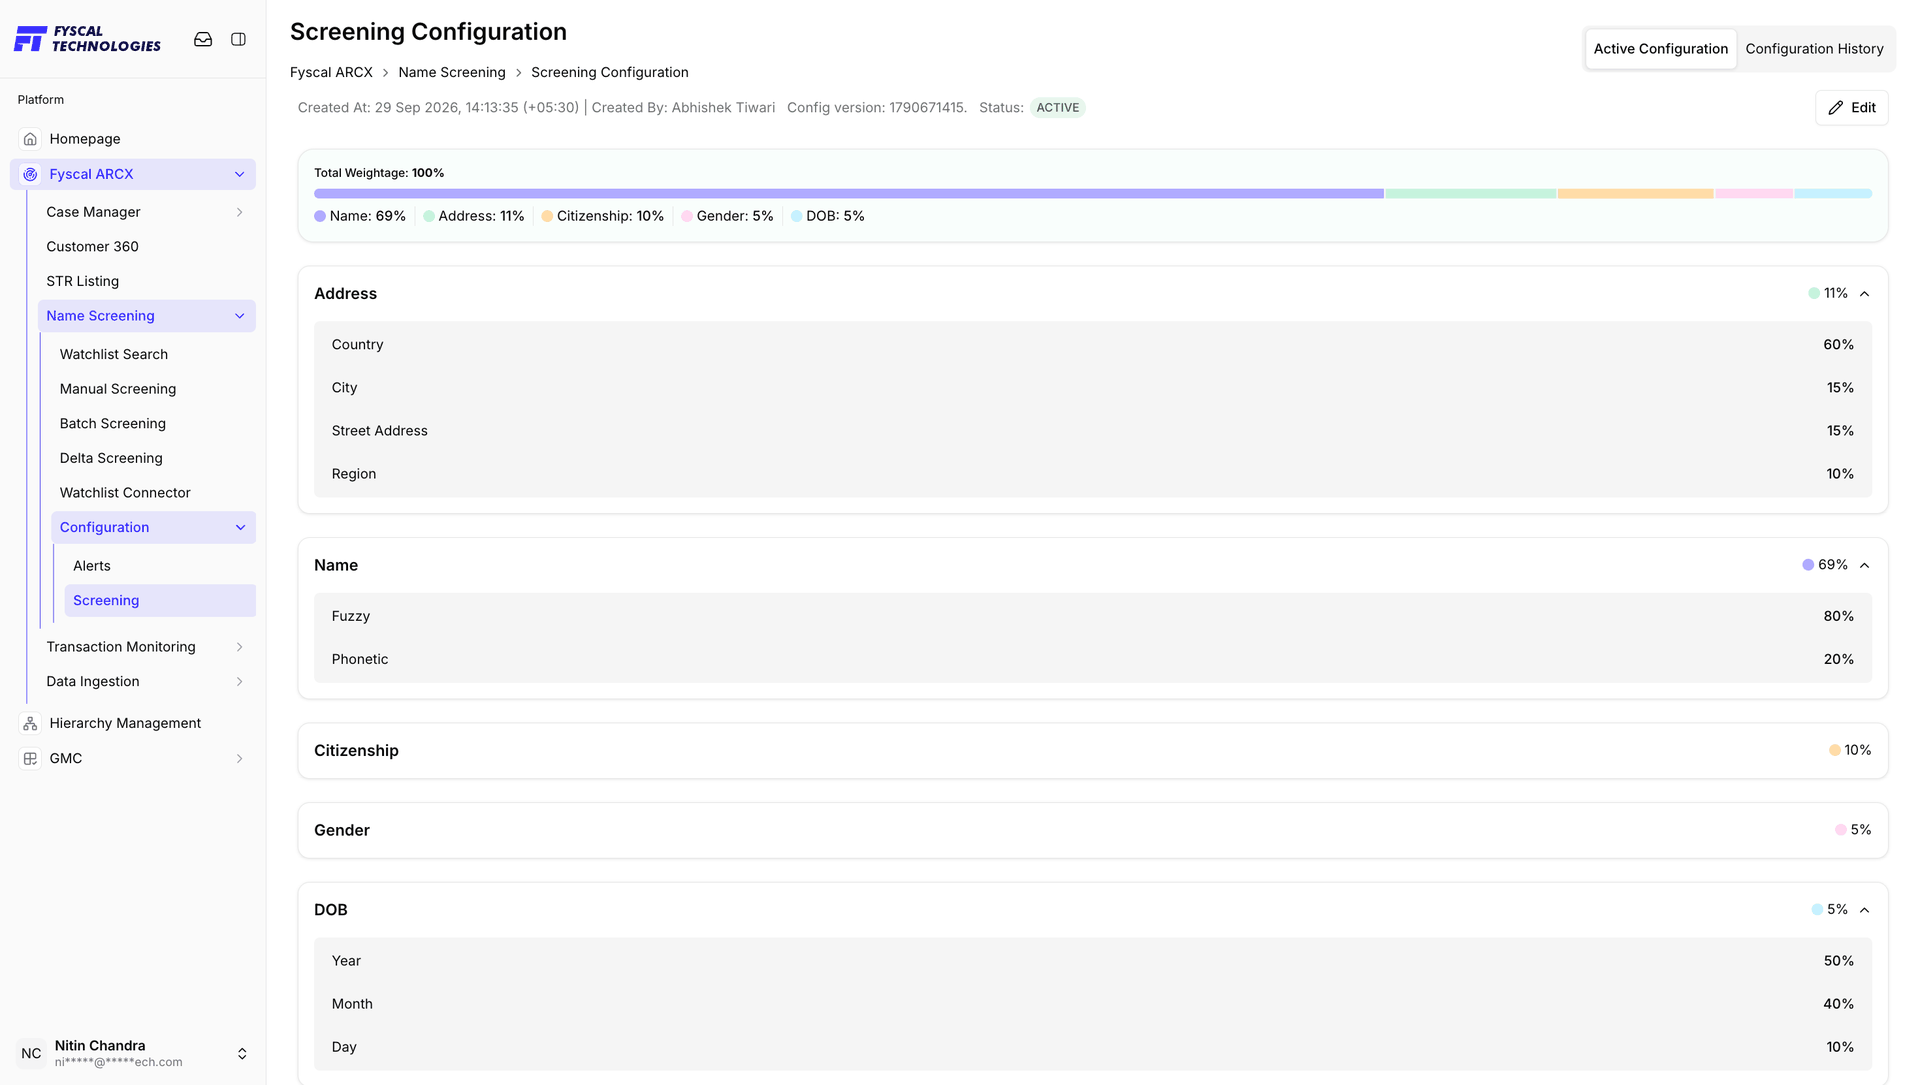
Lets administrators configure the matching criteria and weightages used during screening. Each parameter — Name, Address, Citizenship, Gender, Date of Birth — is assigned a weightage that determines how much it contributes to the overall match score, so institutions can align screening sensitivity with their internal AML policies and risk appetite. In the example configuration the split is Name 69%, Address 11%, Citizenship 10%, Gender 5% and DOB 5%, shown as a colour-coded bar at the top. Higher weightage strictness reduces false positives but risks missing true matches.
A parameter can also be expanded into sub-criteria for finer control. In this configuration Name splits into Fuzzy 80% and Phonetic 20%; Address into Country 60%, City 15%, Street Address 15% and Region 10%; and DOB into Year 50%, Month 40% and Day 10%. Citizenship and Gender have no sub-criteria.
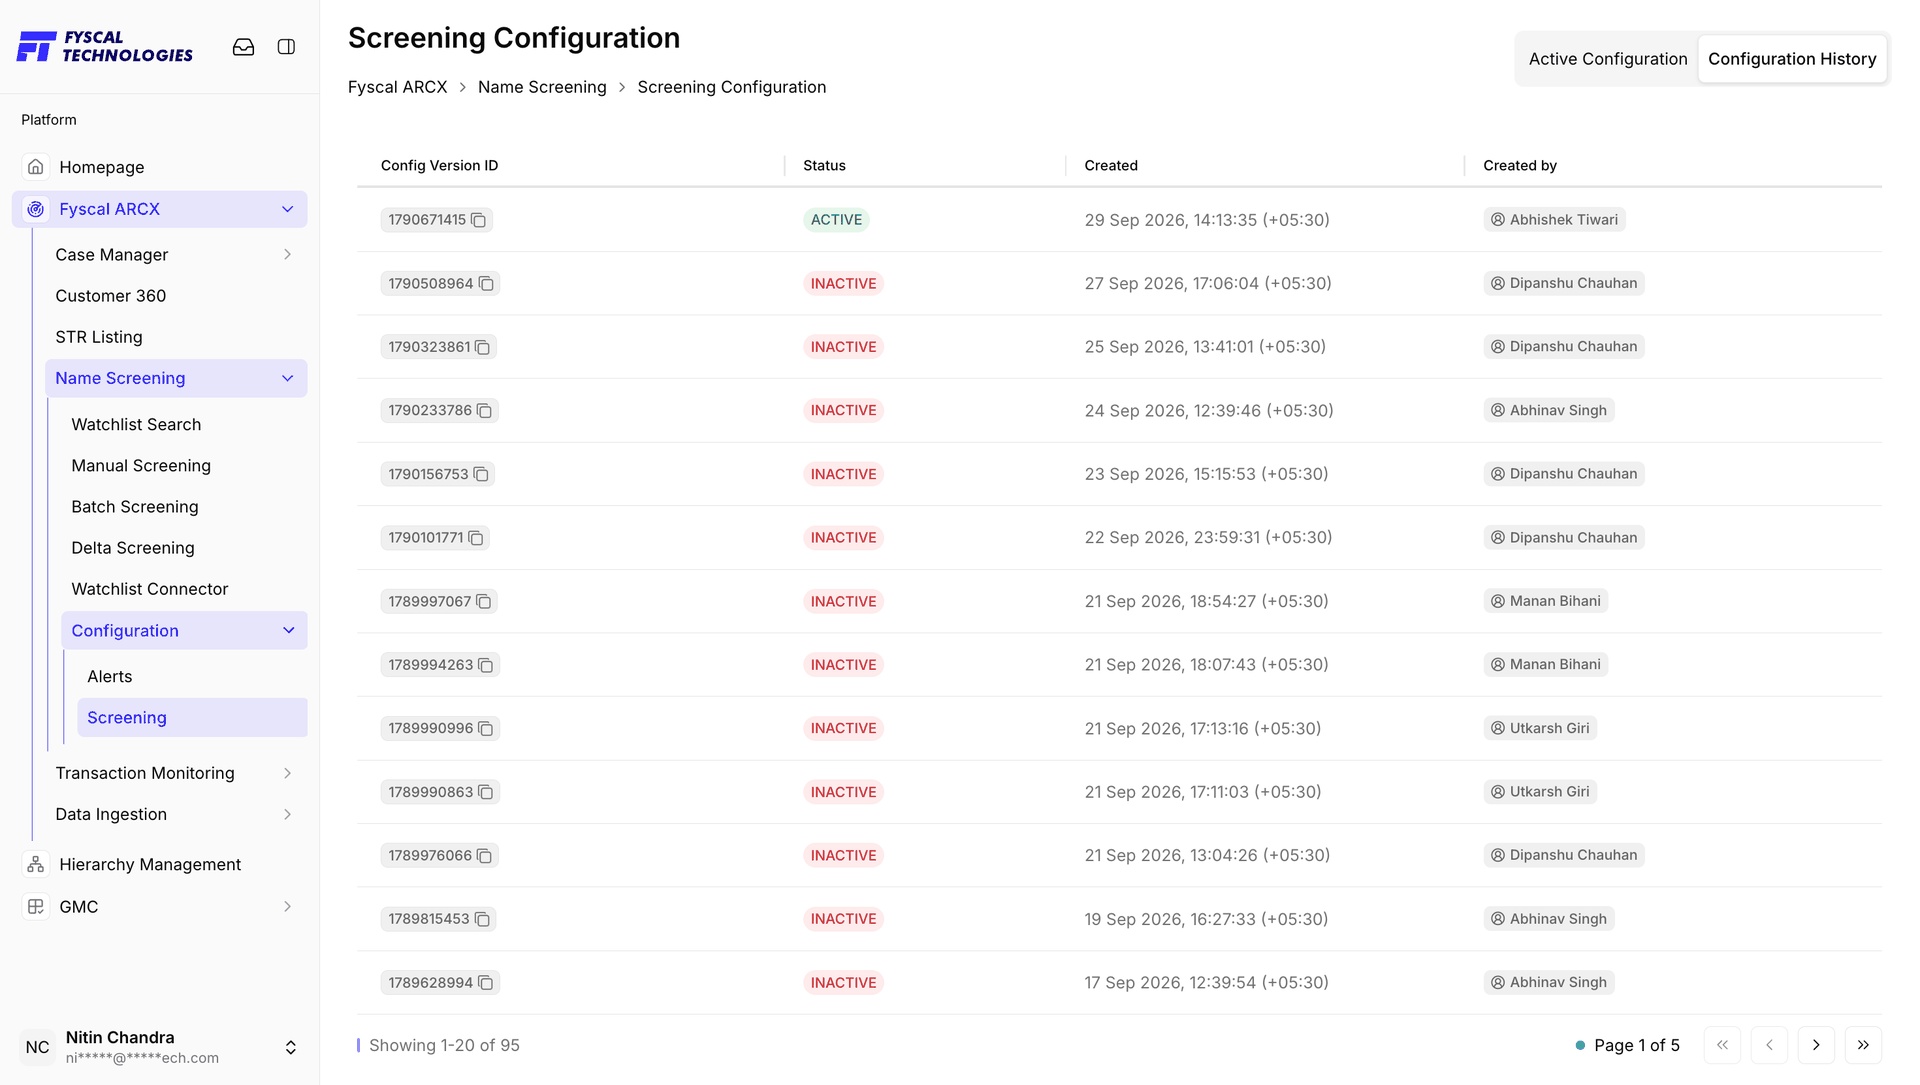
Configuration History lists every saved version with its Config Version ID, Status (ACTIVE or INACTIVE), when it was created and who created it — 95 versions in the example below. Opening a row shows that version read-only, exactly as it was saved.
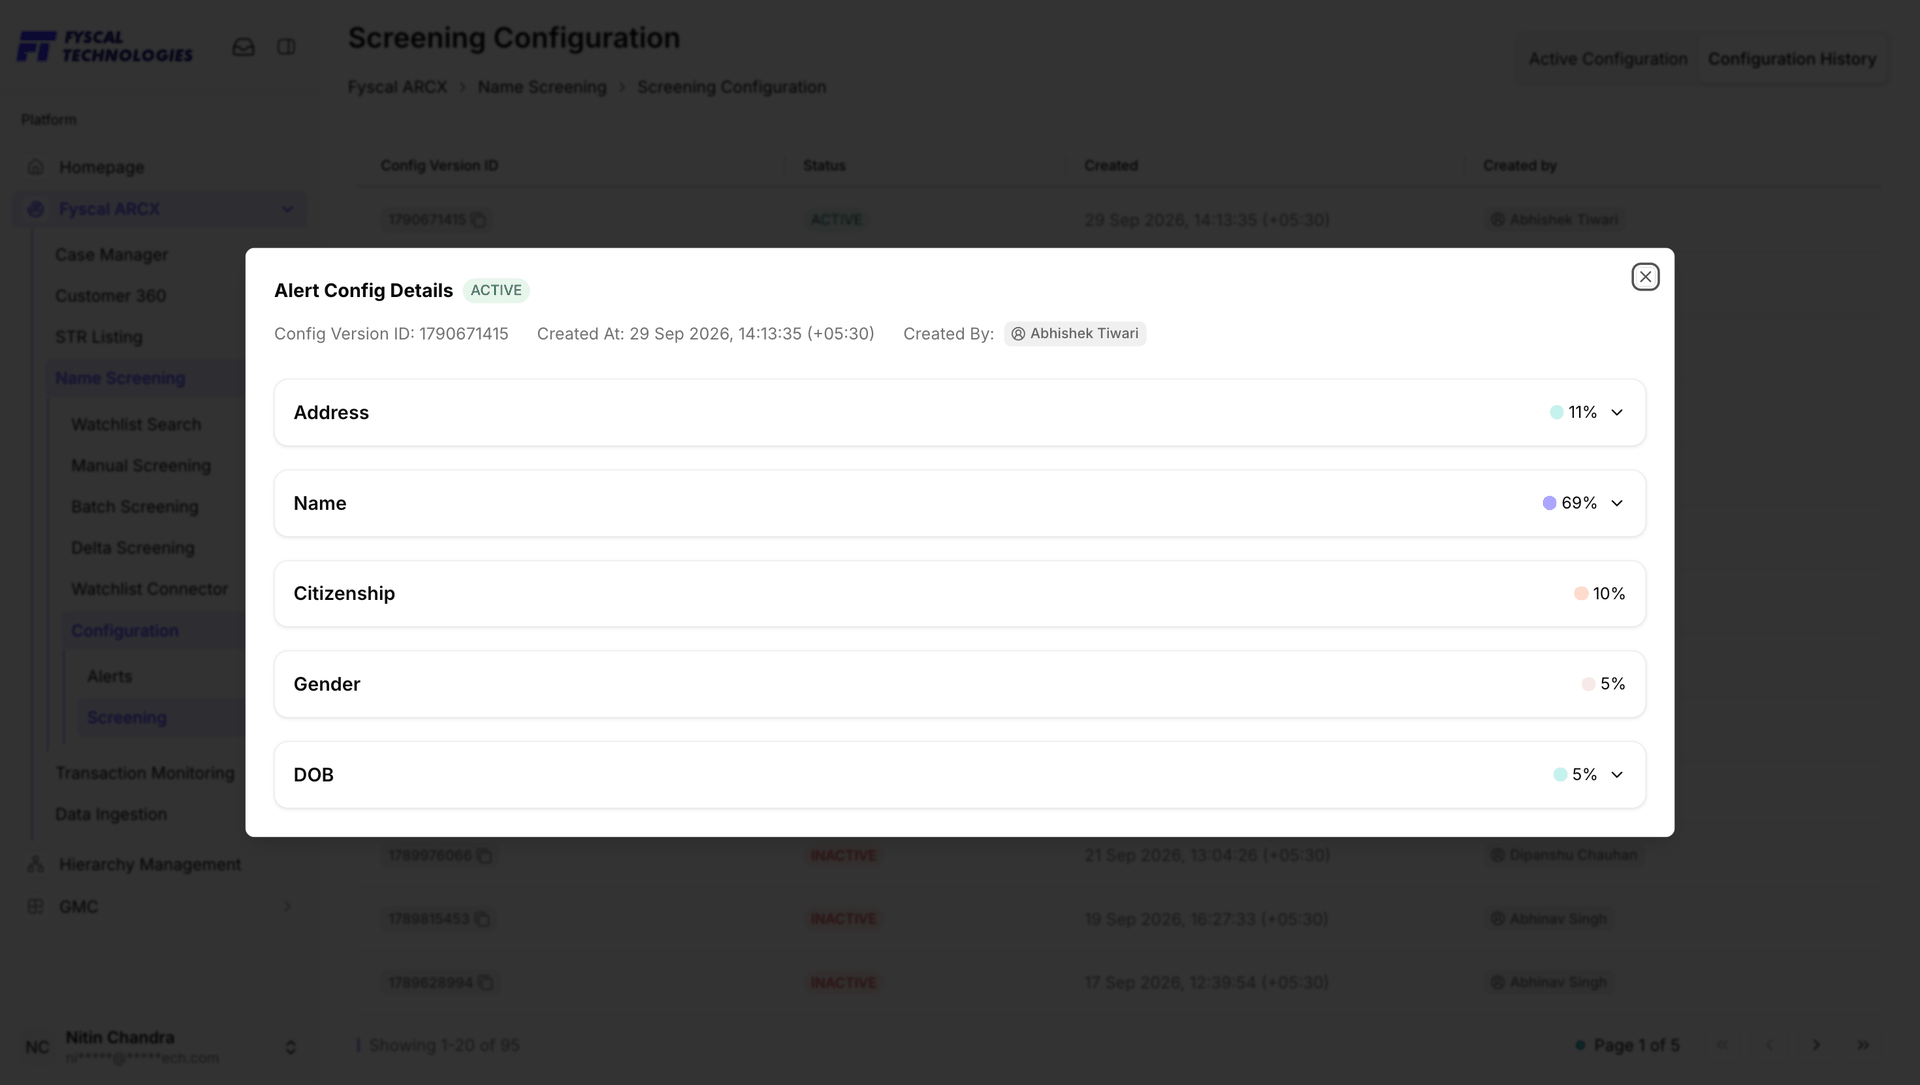
Opening a row shows that version read-only, in a dialog that lists its Config Version ID, when it was created and by whom, and one collapsed row per parameter — Address, Name, Citizenship, Gender and DOB — each with its weightage. Click a row's chevron to expand its sub-weightages. In the current build the dialog's title reads Alert Config Details, even though it is showing a Screening Configuration.
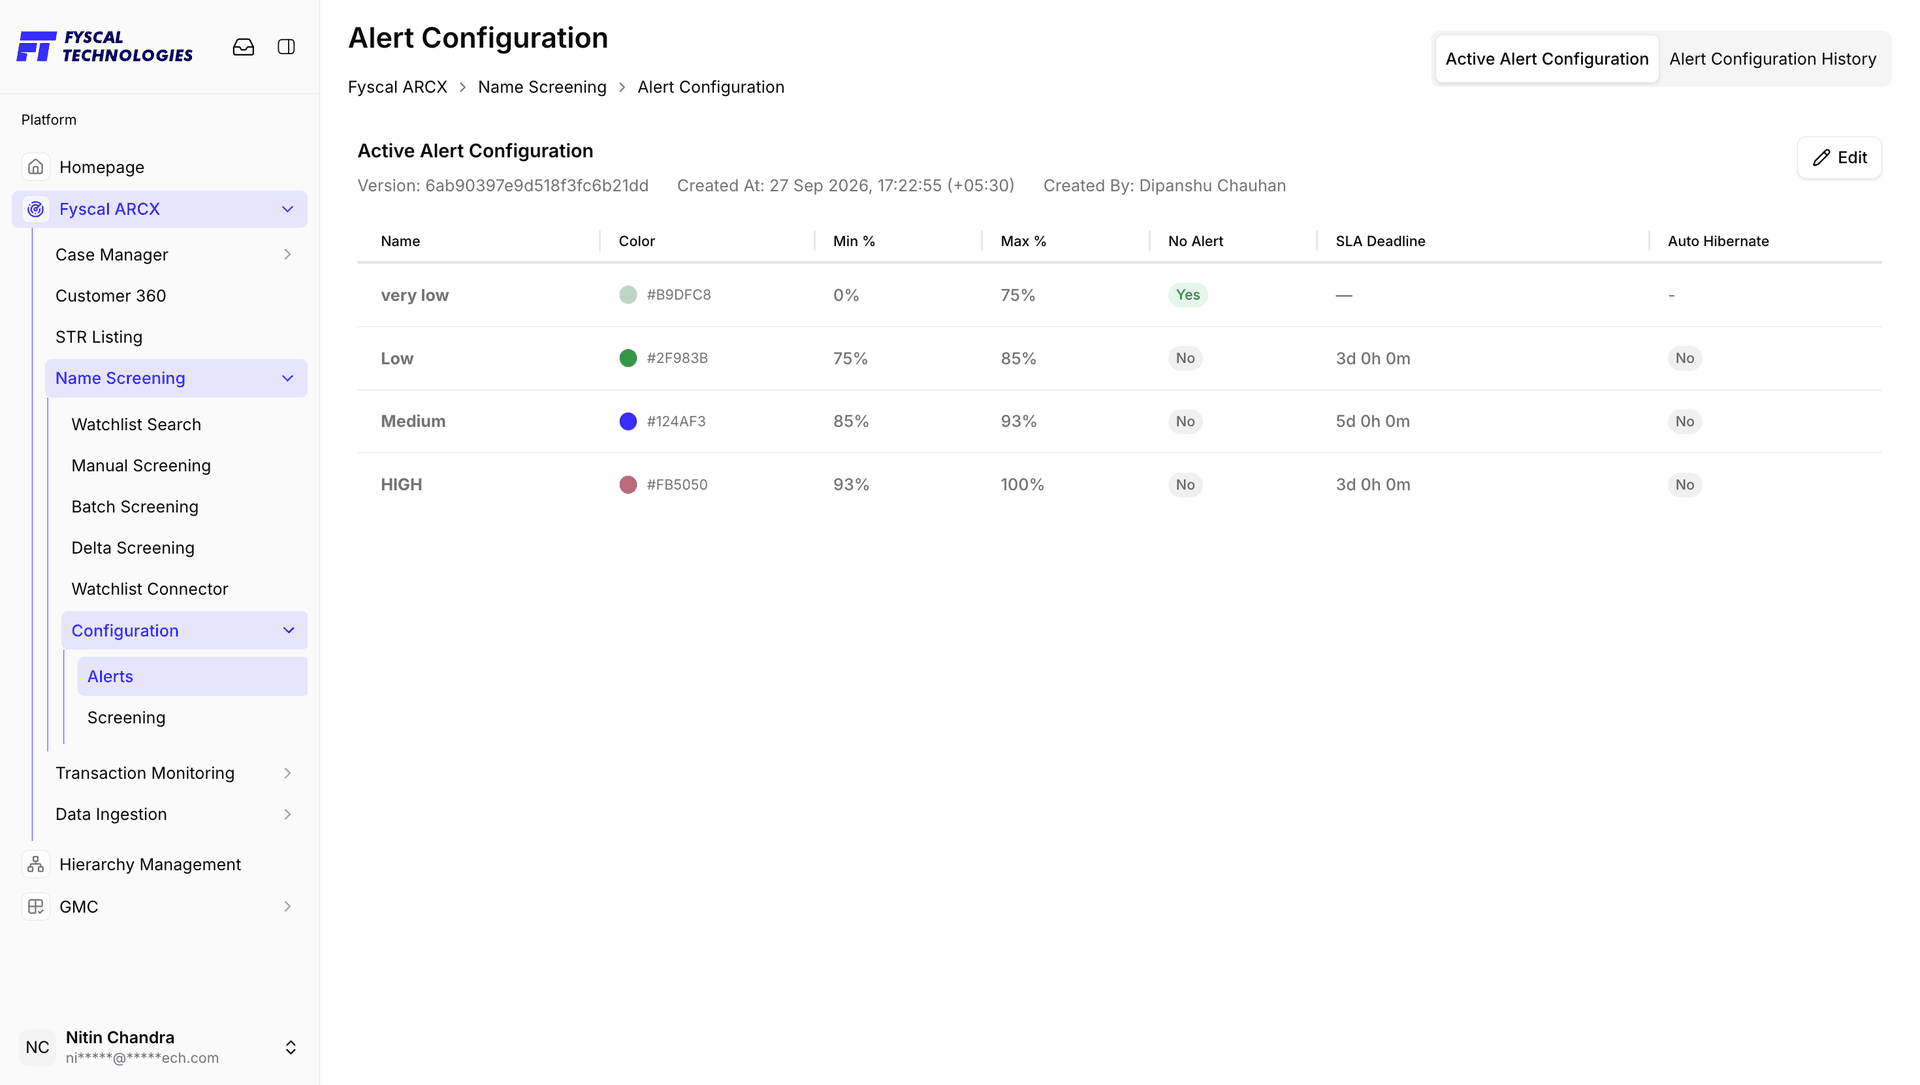
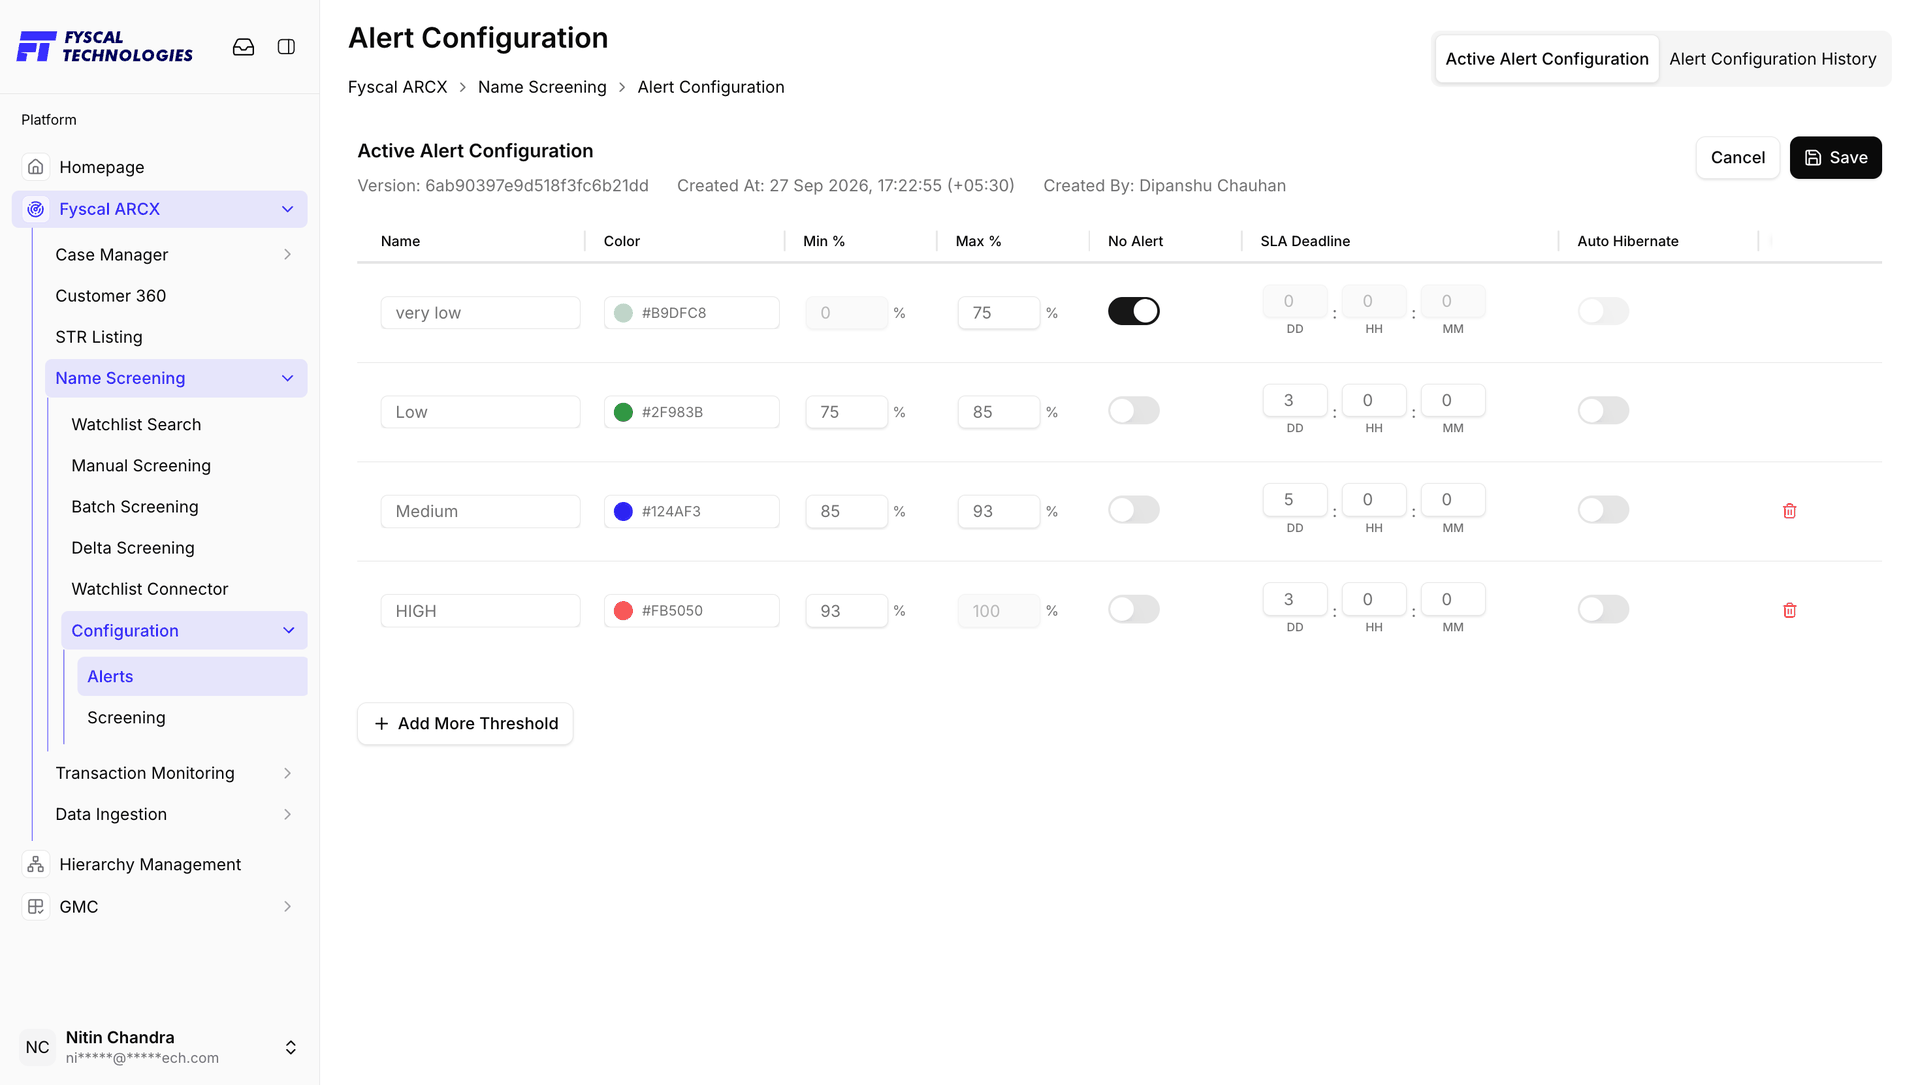
Lets administrators configure the alert severity levels generated during screening — defining score ranges, naming severity levels, configuring SLA deadlines, and enabling auto-hibernation, so organizations can prioritize investigations and standardize alert handling based on risk. Each level has its own colour, score range (Min % – Max %), a No Alert switch, an SLA Deadline (days, hours, minutes) and an Auto Hibernate switch.
| Severity | Score Range | SLA Deadline | Auto Hibernate |
|---|---|---|---|
| very low | 0% – 75% | — (No Alert is on) | — |
| Low | 75% – 85% | 3 days | No |
| Medium | 85% – 93% | 5 days | No |
| HIGH | 93% – 100% | 3 days | No |
This is the configuration active in the example environment; the names, ranges and SLAs are all editable, and more thresholds can be added. A band with No Alert switched on raises no alert at all — here, any match scoring below 75% is filtered out automatically. Auto Hibernate, when switched on for a band, puts that band's alerts to sleep instead of leaving them in the active queue; hibernated alerts can still be found with Show Hibernated in Alerts.
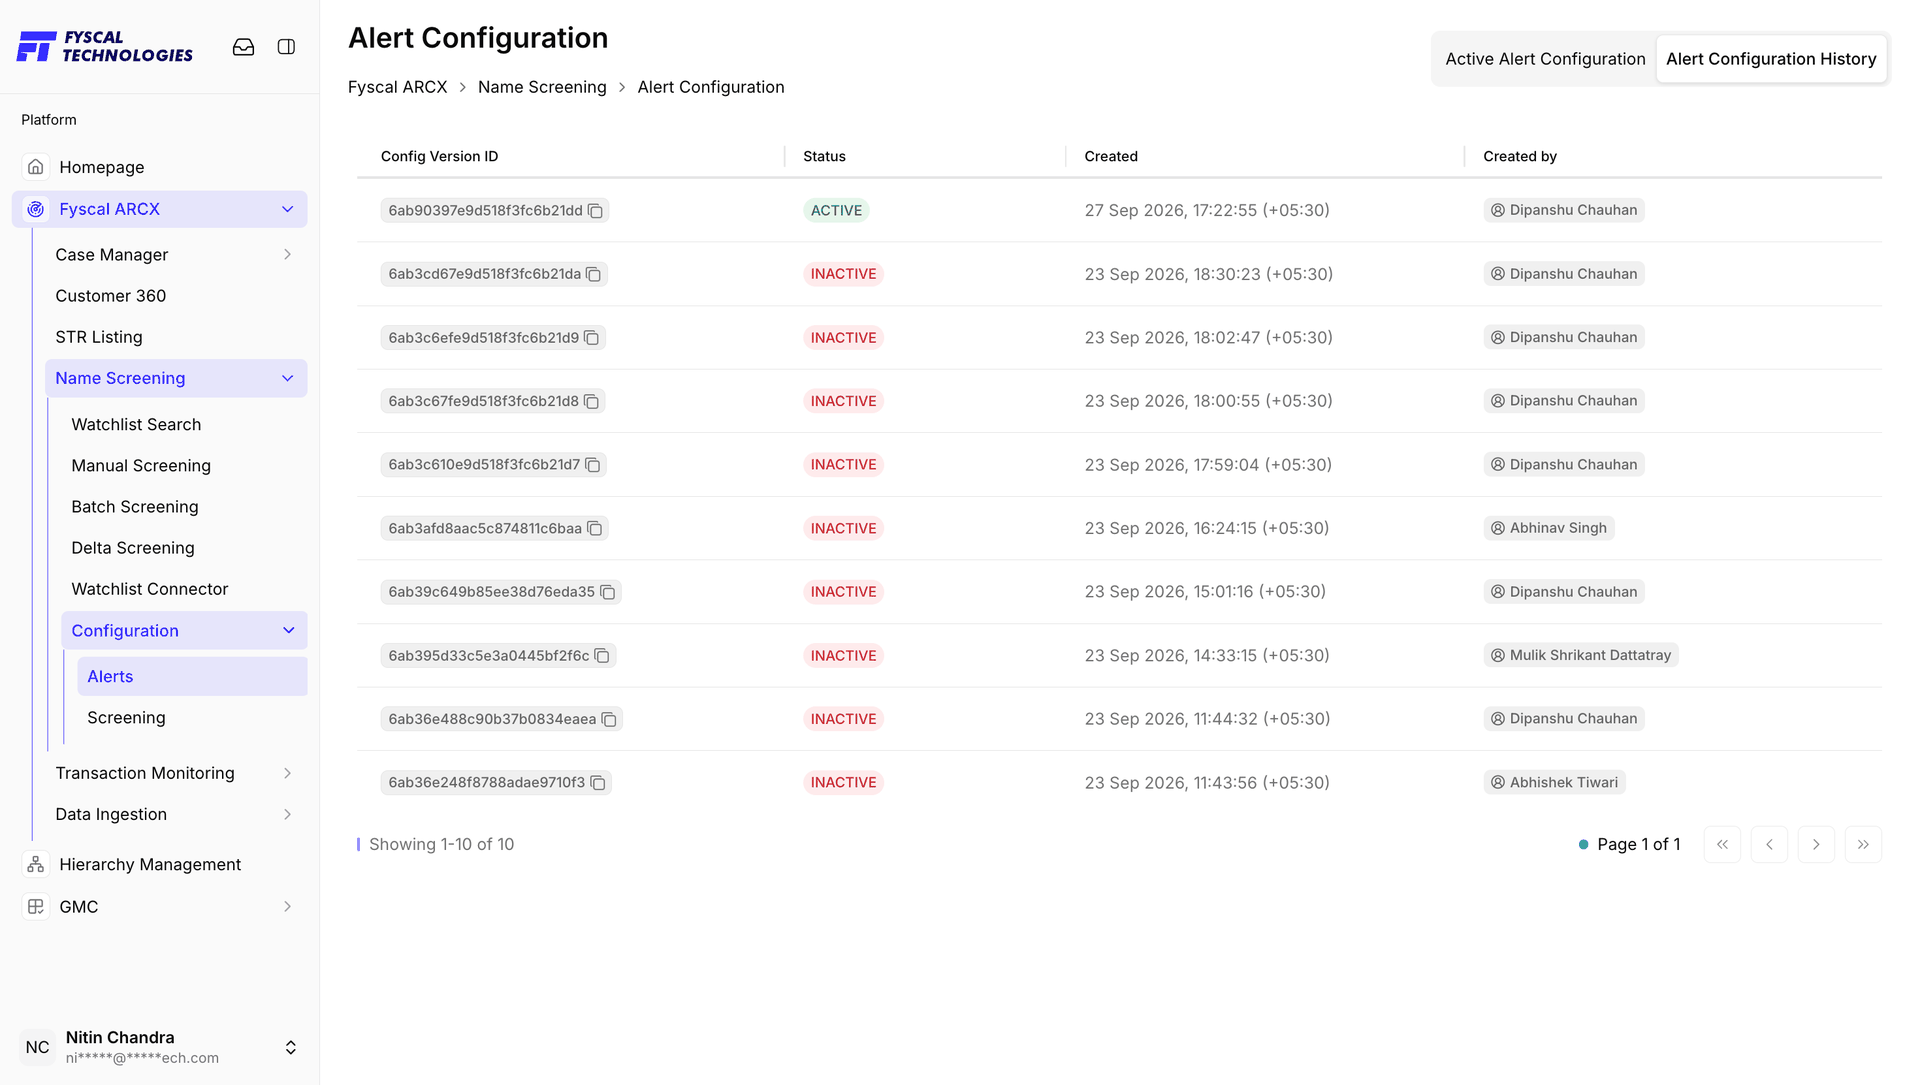
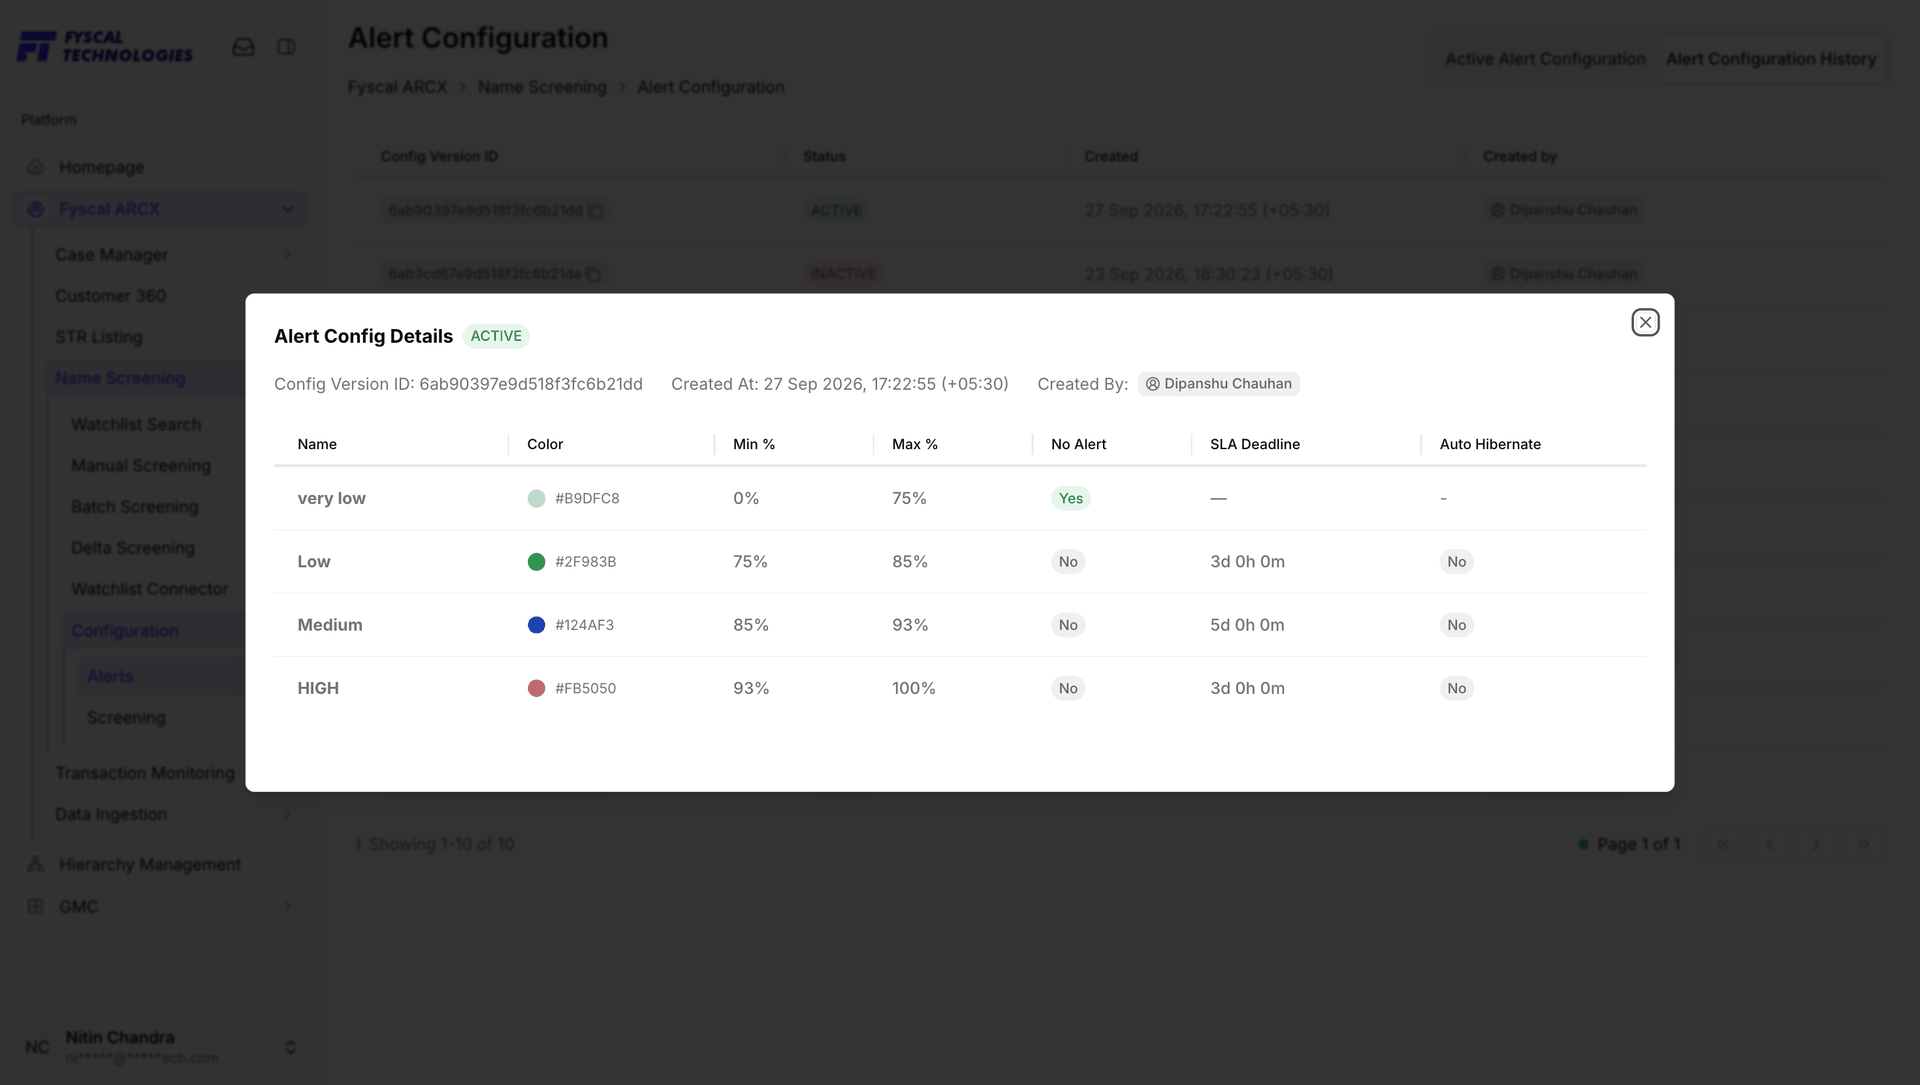
Alert Configuration History lists each version with its Config Version ID, status, creation time and author. Opening a row shows that version's bands read-only. The Config version in force when an alert was raised is shown on that alert's detail page.
Detects suspicious transaction patterns using configurable typologies (rules) built from reusable Variables.
Before the details below, here's the complete path a transaction takes through the engine, from the moment it lands in Fyscal ARCX to a case landing on an investigator's desk:
Each monitoring rule is defined as a Typology — a named, versioned pattern (e.g. Structuring, High Value Transfer, Smurfing) built from Variables and Trigger Conditions.
The list shows every rule's Status (Draft, Shadow, or Published), its Typologies category (for example Large Transaction, Structuring, Cardinality or High Value), when it was Created and Updated, and an Actions menu (⋮) on each row. Rules that are Shadow or Published also show whether they are Active or Paused.
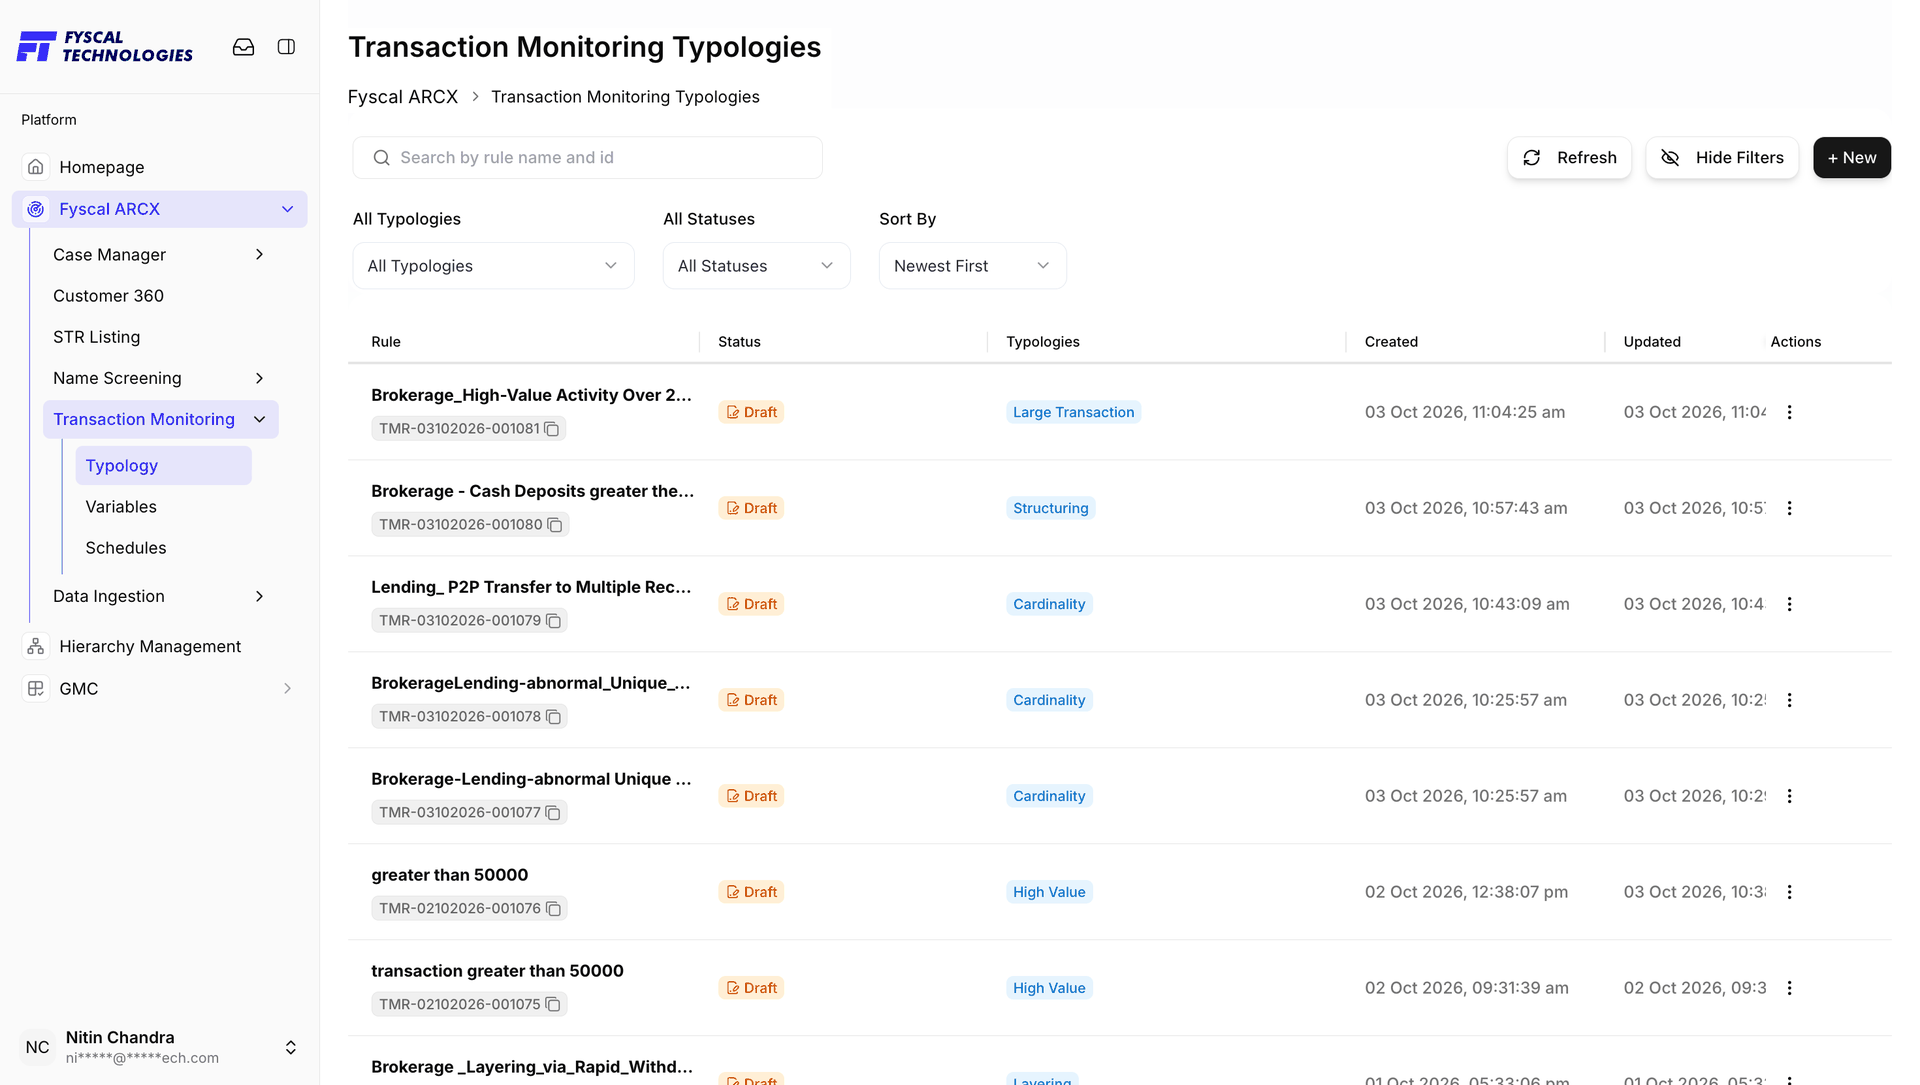
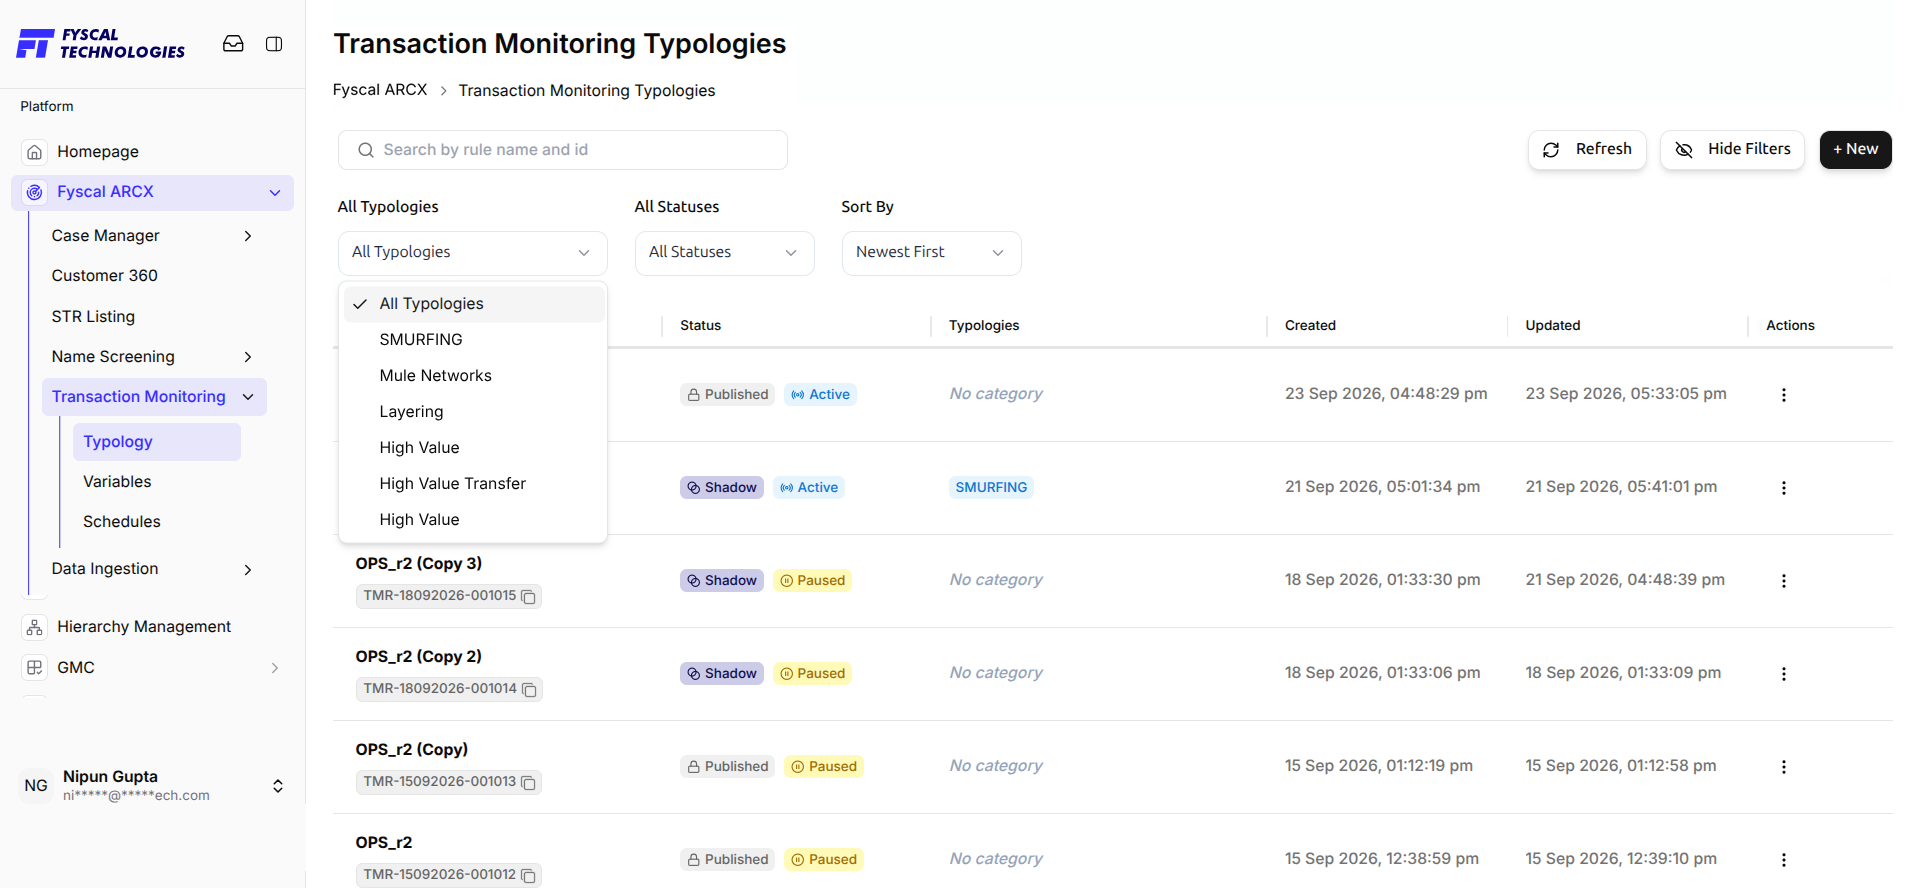
Looking for a specific pattern? Filter by typology category first.
The dropdown lists the categories defined in the environment — for example SMURFING, Mule Networks, Layering, High Value and High Value Transfer — matching the pattern families covered in the Typology Library.
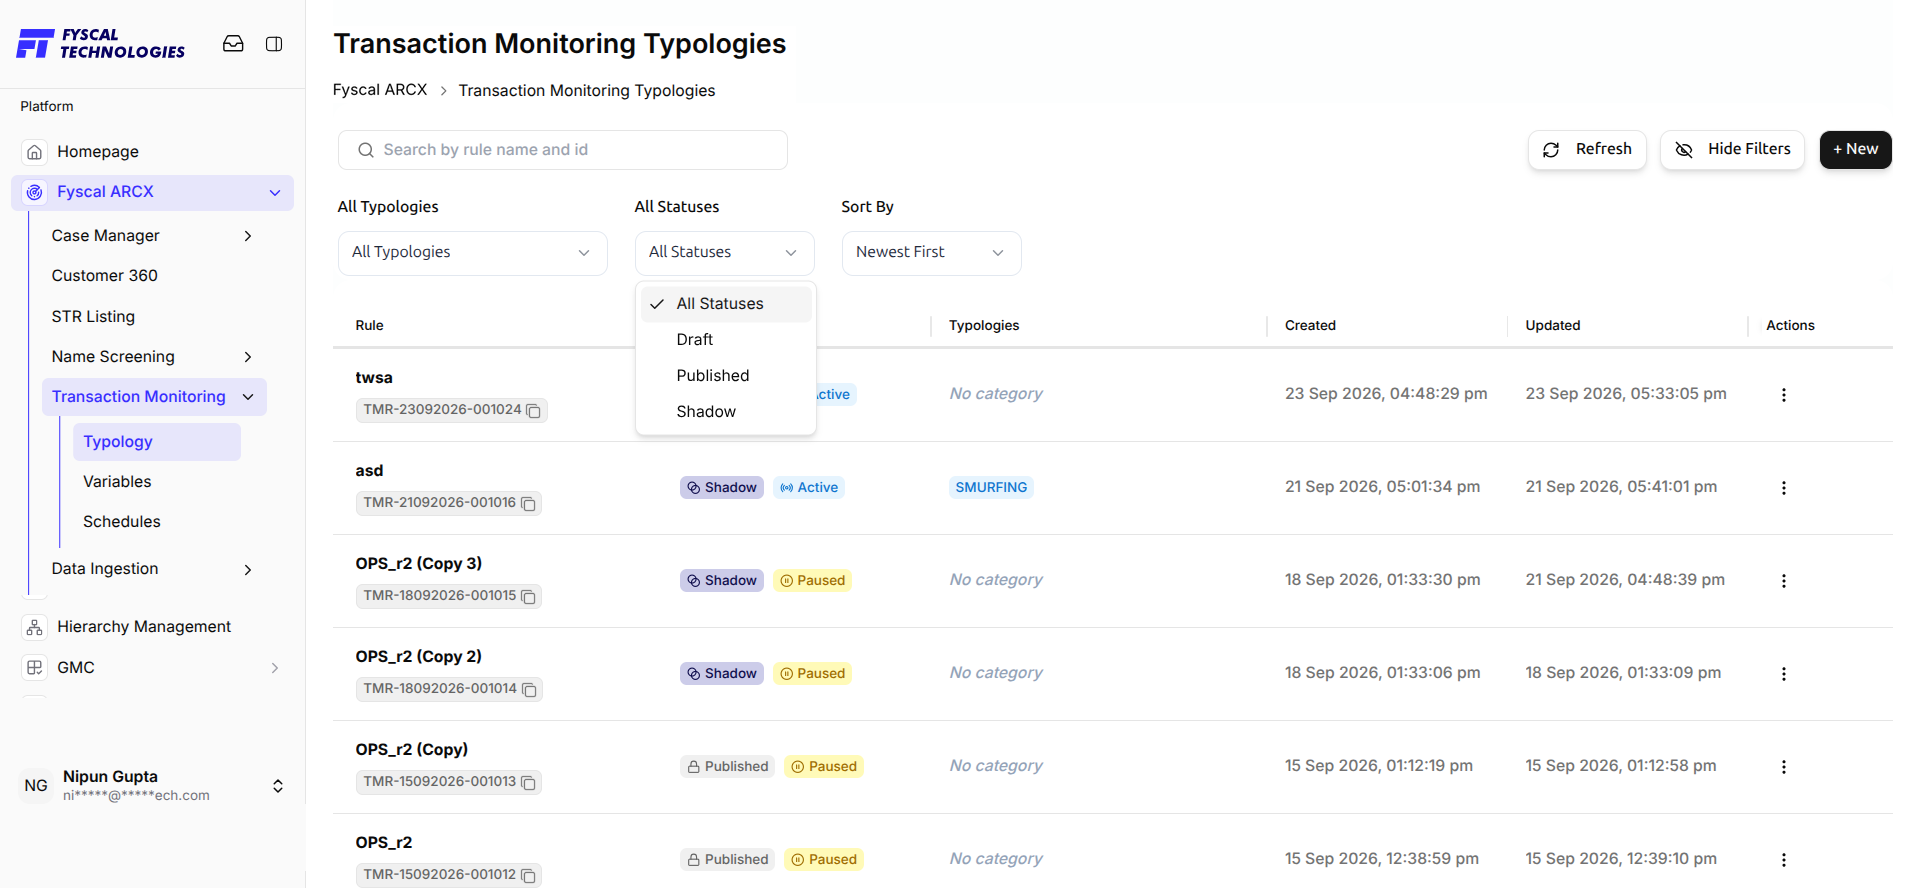
Only care about rules in a particular state? Filter by Status next.
Narrow to just Draft (in progress), Published (live and generating alerts), or Shadow (running silently for validation).
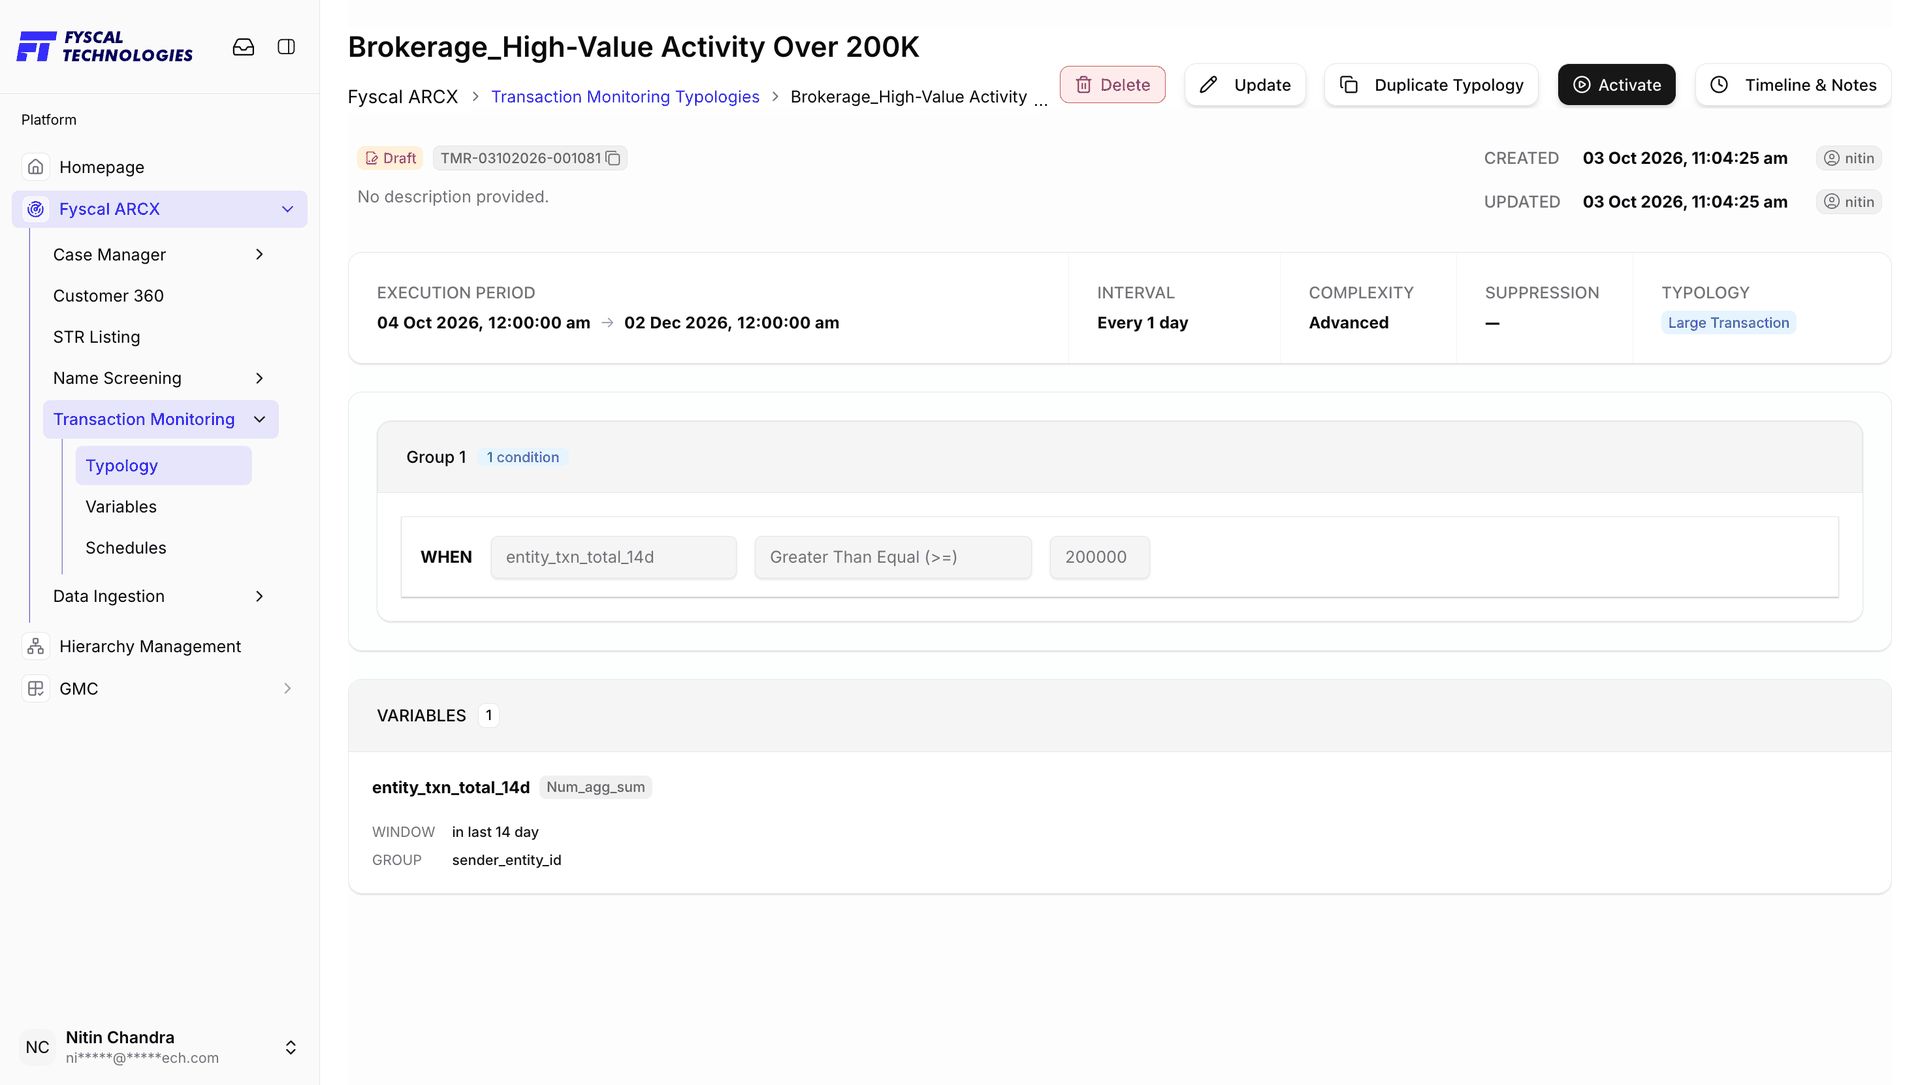
Found the rule you need? Click its row to see exactly what it does.
A typology's detail page shows its name, rule ID, Status, who created and last updated it and when, and a summary strip: the Execution Period (start and end), Interval, Complexity, Suppression and Typology category. Below that, each condition Group is shown read-only (e.g. WHEN entity_txn_total_14d ≥ 200000), followed by a Variables panel listing every variable the rule uses with its aggregation type, time window and group-by field. Buttons at the top let you Delete, Update, Duplicate Typology, Activate a draft, or open Timeline & Notes — a history of events such as "Rule created as draft" where you can also add notes and attach files.
Timeline & Notes on a typology opens an Activity Timeline beside the rule. The header repeats the rule's reference number (e.g. TMR-03102026-001081). Use Add a note and Attach File to record why a threshold was chosen or what a review concluded; the events list below logs what happened to the rule and who did it — a new rule starts with Rule created as draft, with the date, time and user.
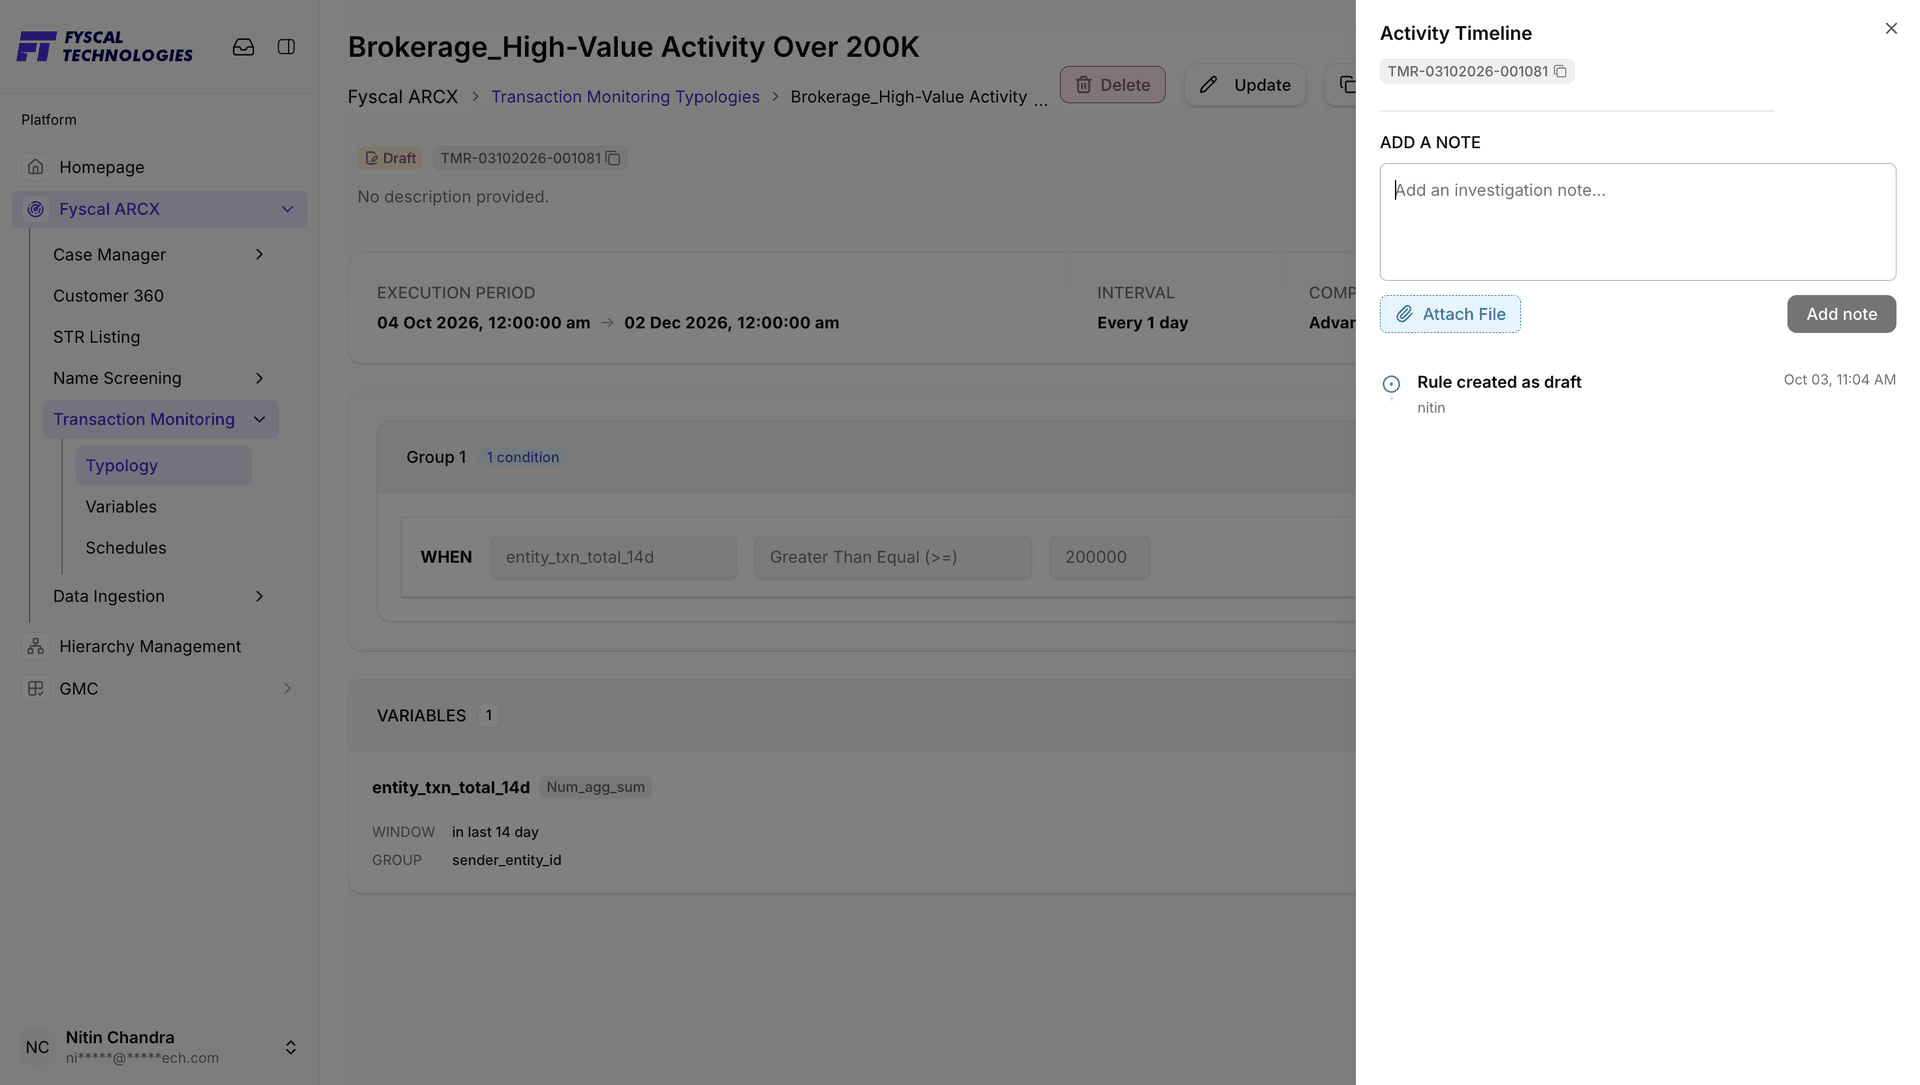
Keeping rationale in the timeline matters because a typology is versioned and re-tuned over time: months later it is the only place that explains why a condition was set the way it was.
Ready to build something new? + New opens the rule builder.
Creating a rule is a two-step wizard. Step 1 defines the rule itself: a Typology Name, an optional Typology type (e.g. Structuring), a Suppression Window (a number and a unit such as Hours), an optional Description, and one or more condition Groups. Each Group has its own Match switch (AND / OR) and one or more WHEN conditions — a variable, an operator and a value (Static Value, Variable or ingested data) — and Combine groups with sets how the groups relate. + Variable at top right lets you create a new variable without leaving the page. Update on an existing rule opens this same builder.
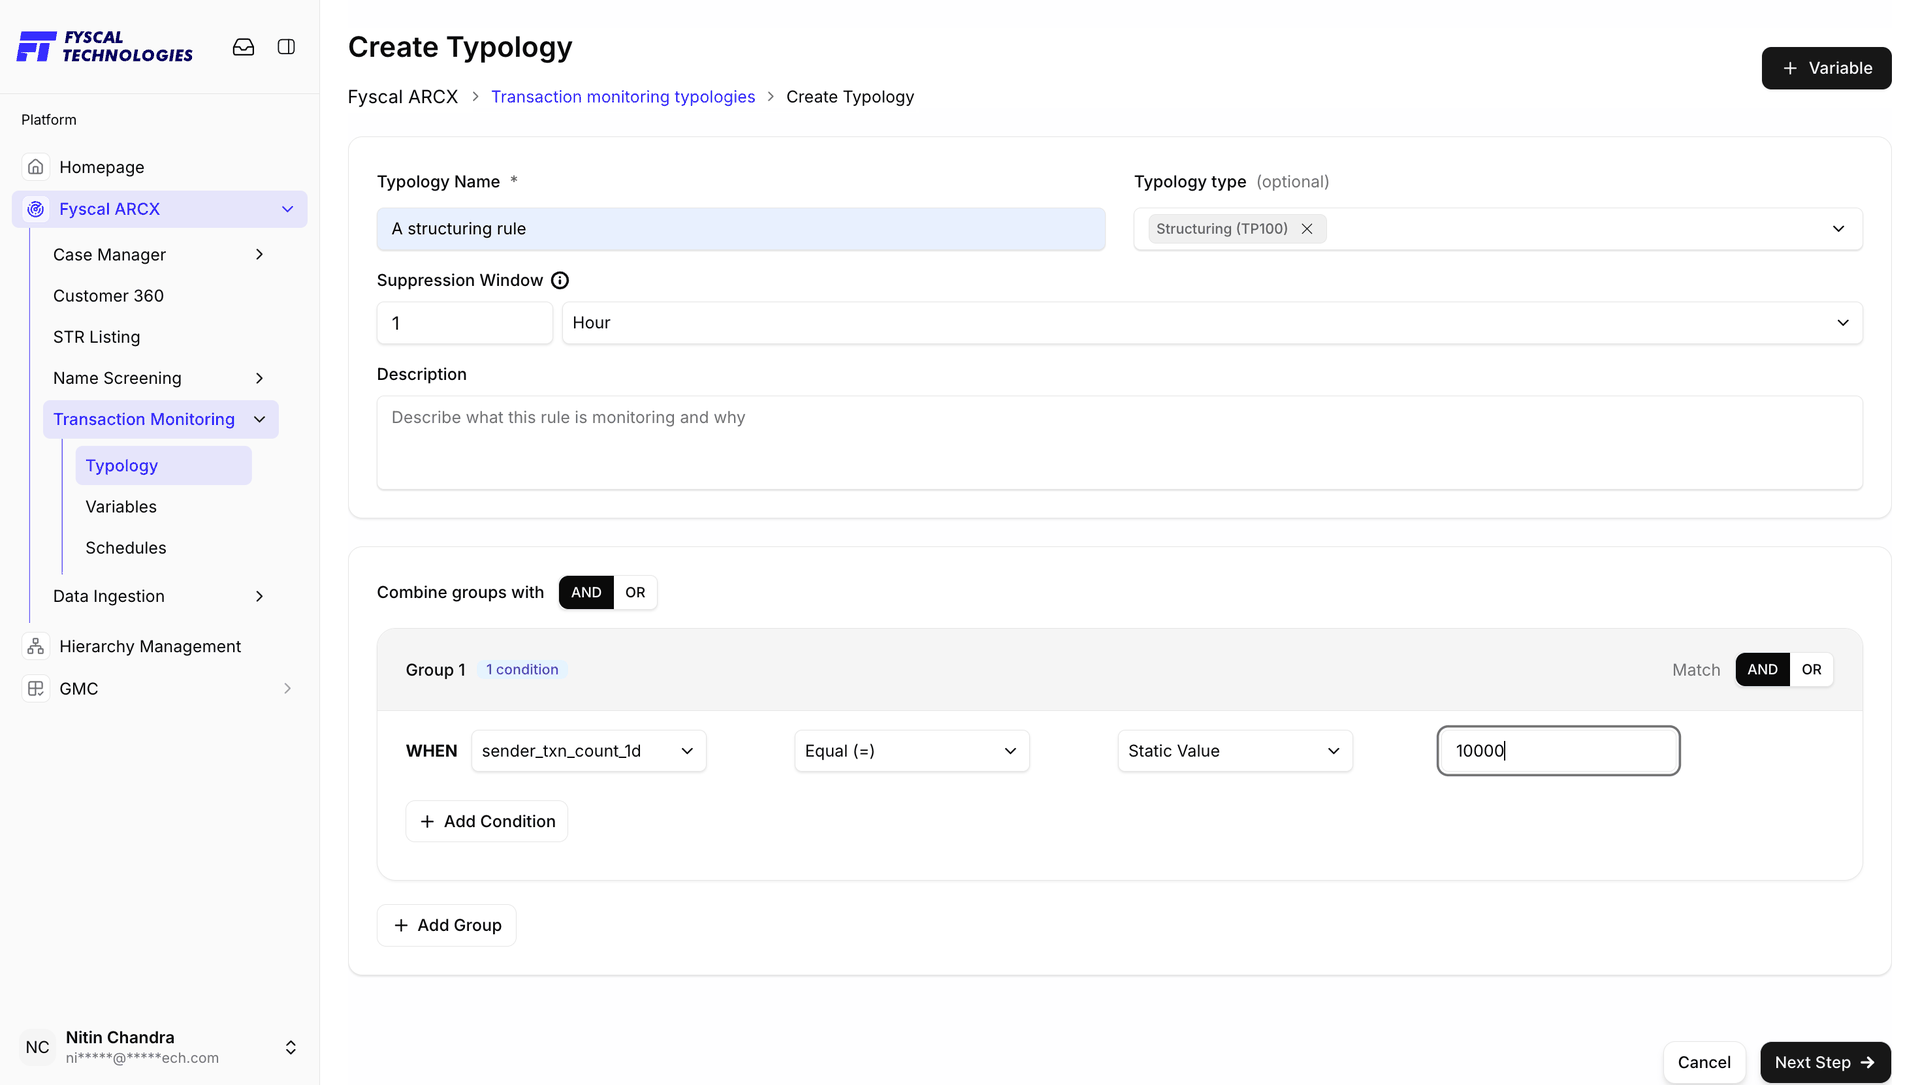
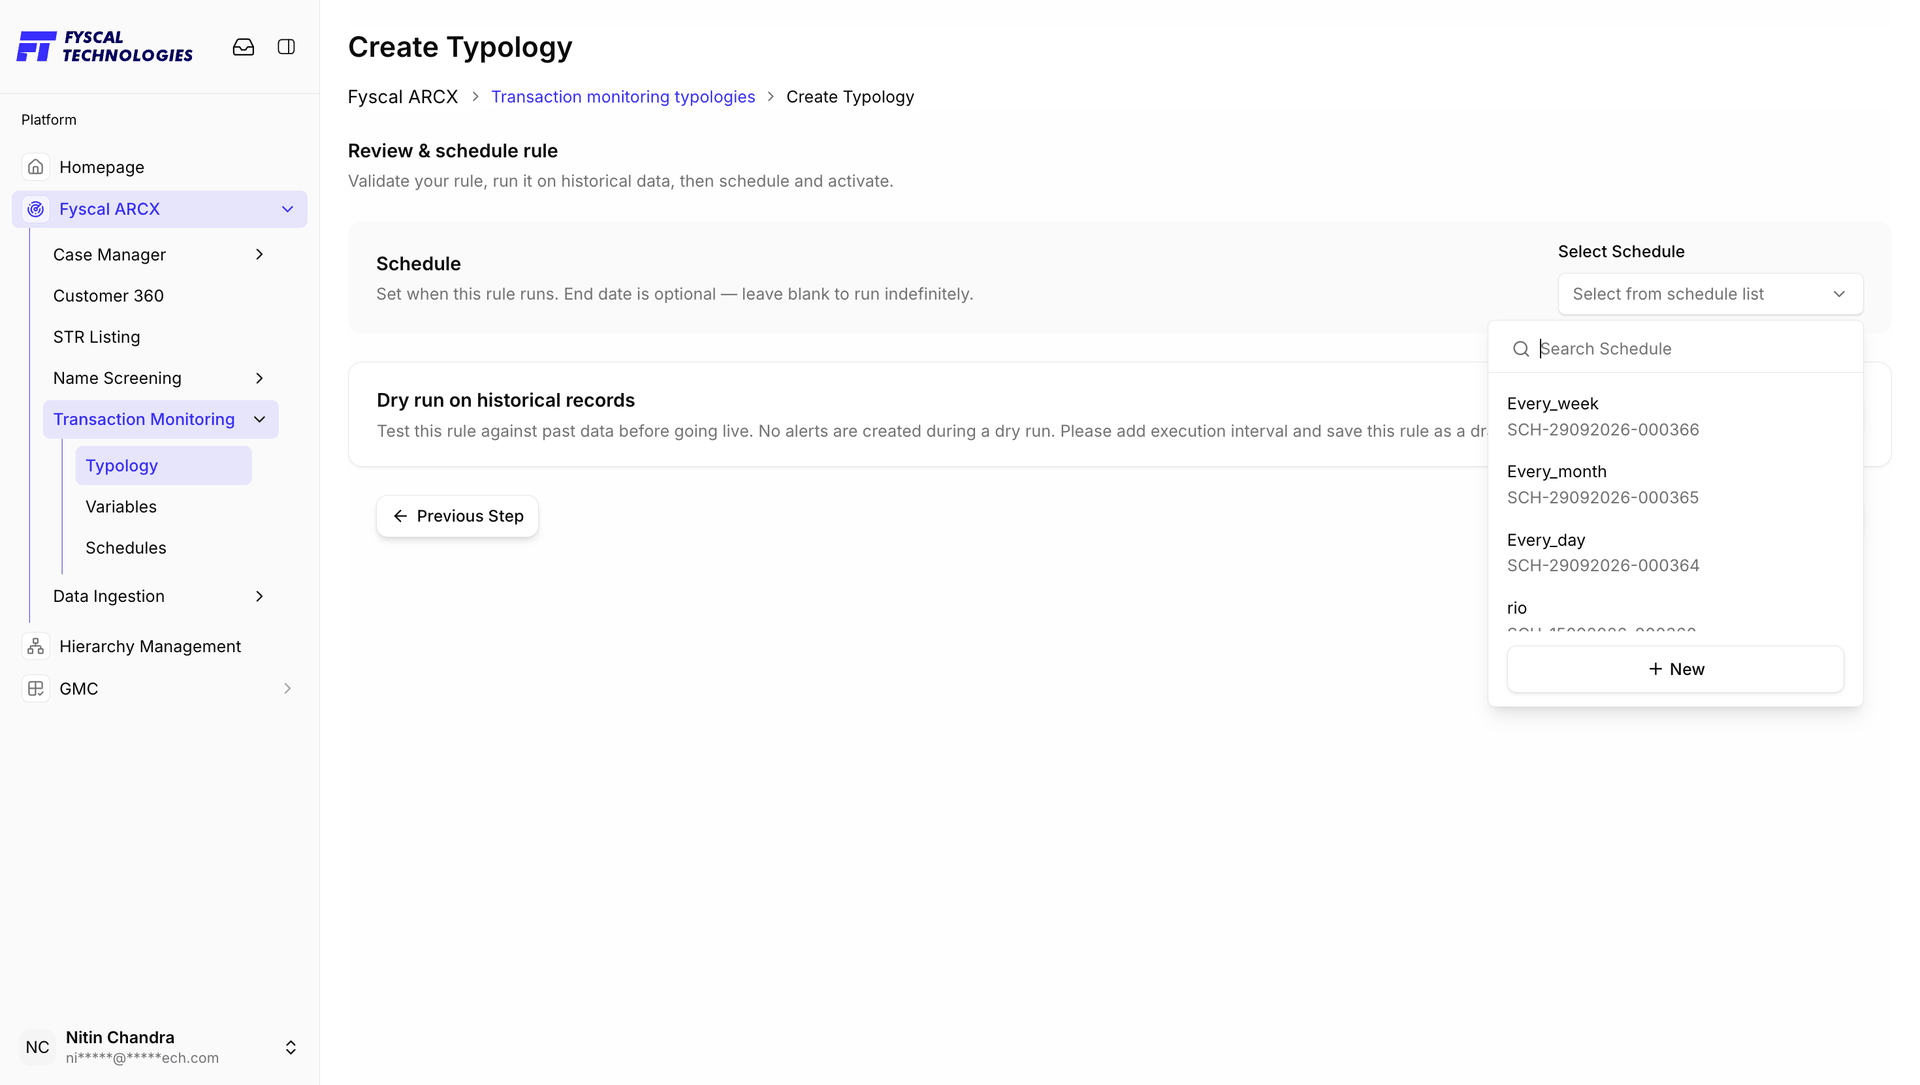
Step 2, Review & schedule rule, validates the rule, optionally runs it on historical data, then schedules it. Under Schedule you pick an existing schedule from a searchable list, or choose + New to define one.
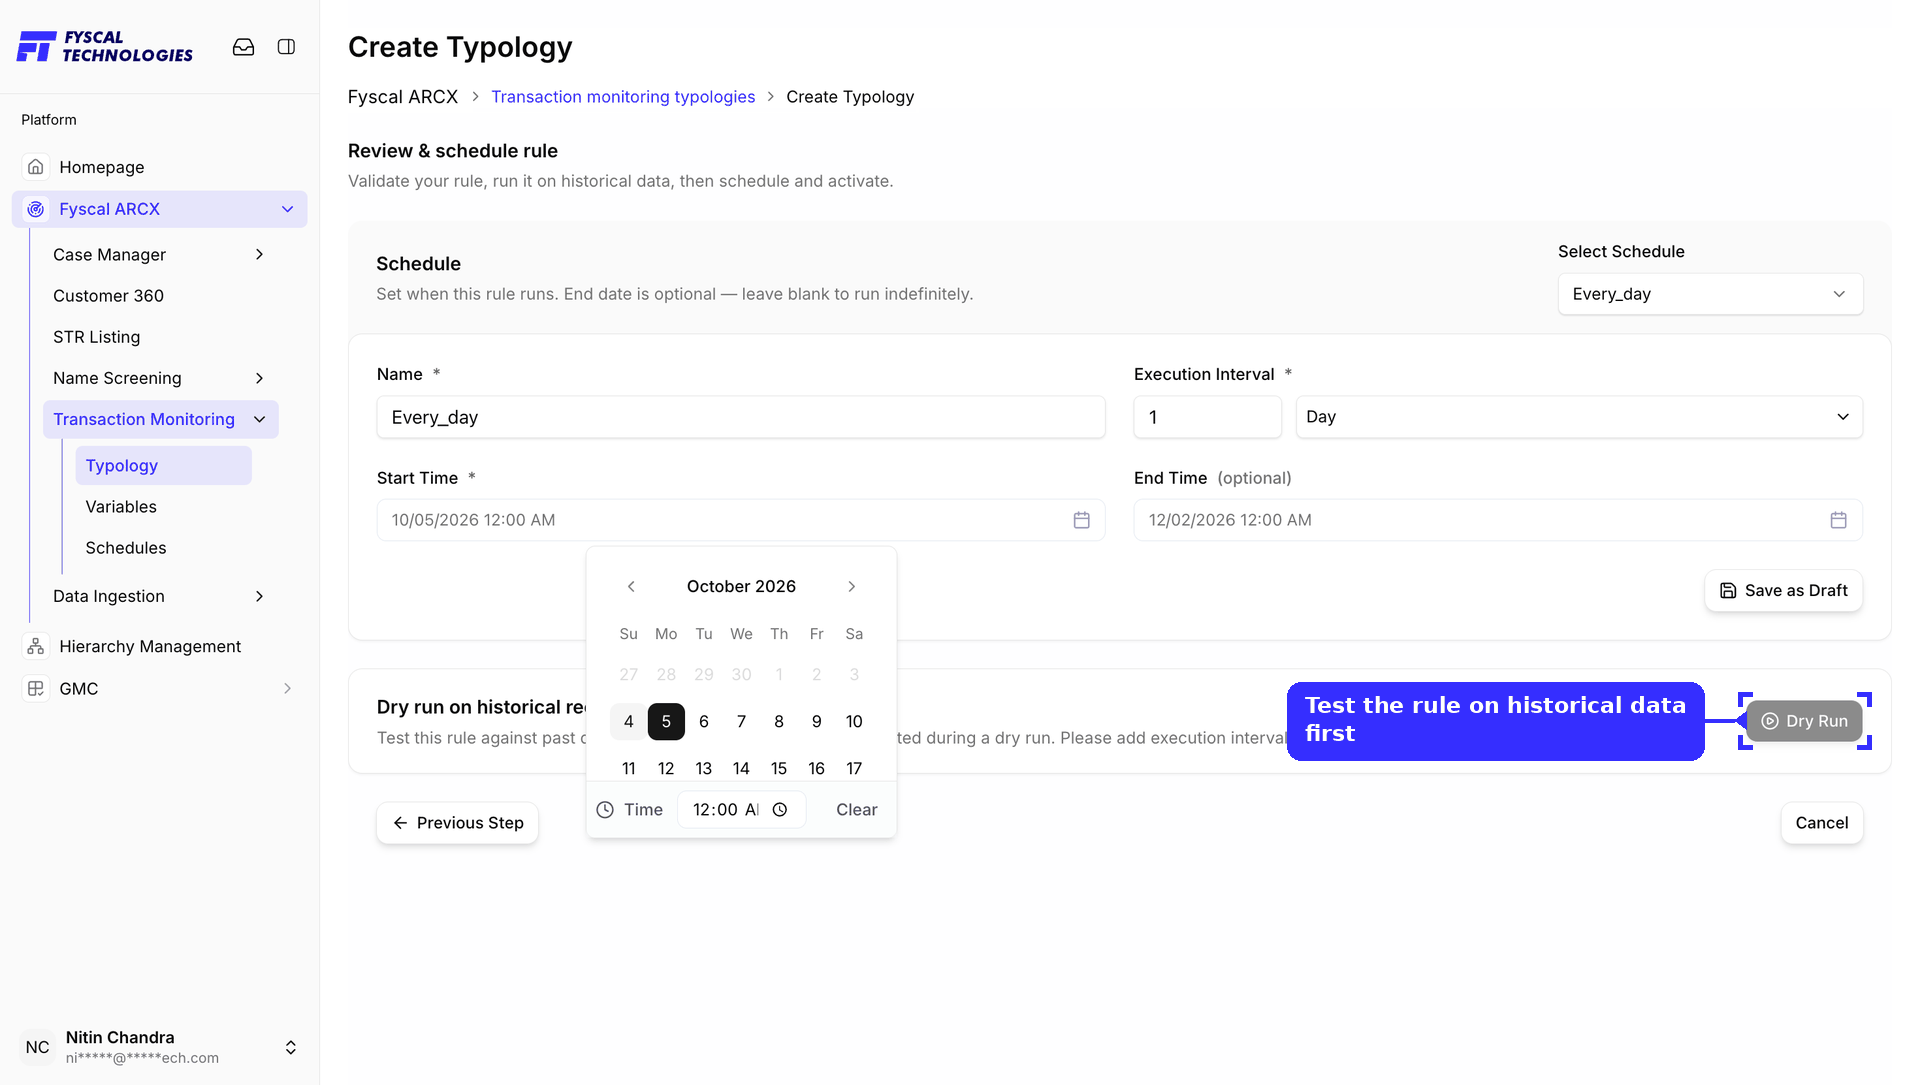
A new schedule needs a Name, an Execution Interval (a number and a unit, e.g. 1 Day), a Start Time and an optional End Time — leave the end blank to run indefinitely — and can be kept with Save as Draft. The Dry run on historical records panel below tests the rule against past data before it goes live; no alerts are created during a dry run, and the button becomes available once an execution interval is set and the rule is saved as a draft.
Update on a typology's detail page opens the same builder as + New, but headed Update Typology and pre-filled with the rule as it stands. In this example the form already holds the Typology Name (Brokerage_High-Value Activity Over 200K), a Typology type chip (Large Transaction (LT-05), removable with its ×), a Suppression Window of 0 hours, an empty Description, and Combine groups with set to AND. Group 1 shows its single condition: entity_txn_total_14d Greater Than Equal (>=) a Static Value of 200000 — meaning "total transaction value for this entity over the last 14 days is at least 200,000". + Add Condition and + Add Group extend the rule, + Variable (top right) creates a variable on the spot, and Next Step continues to the Review & schedule step.
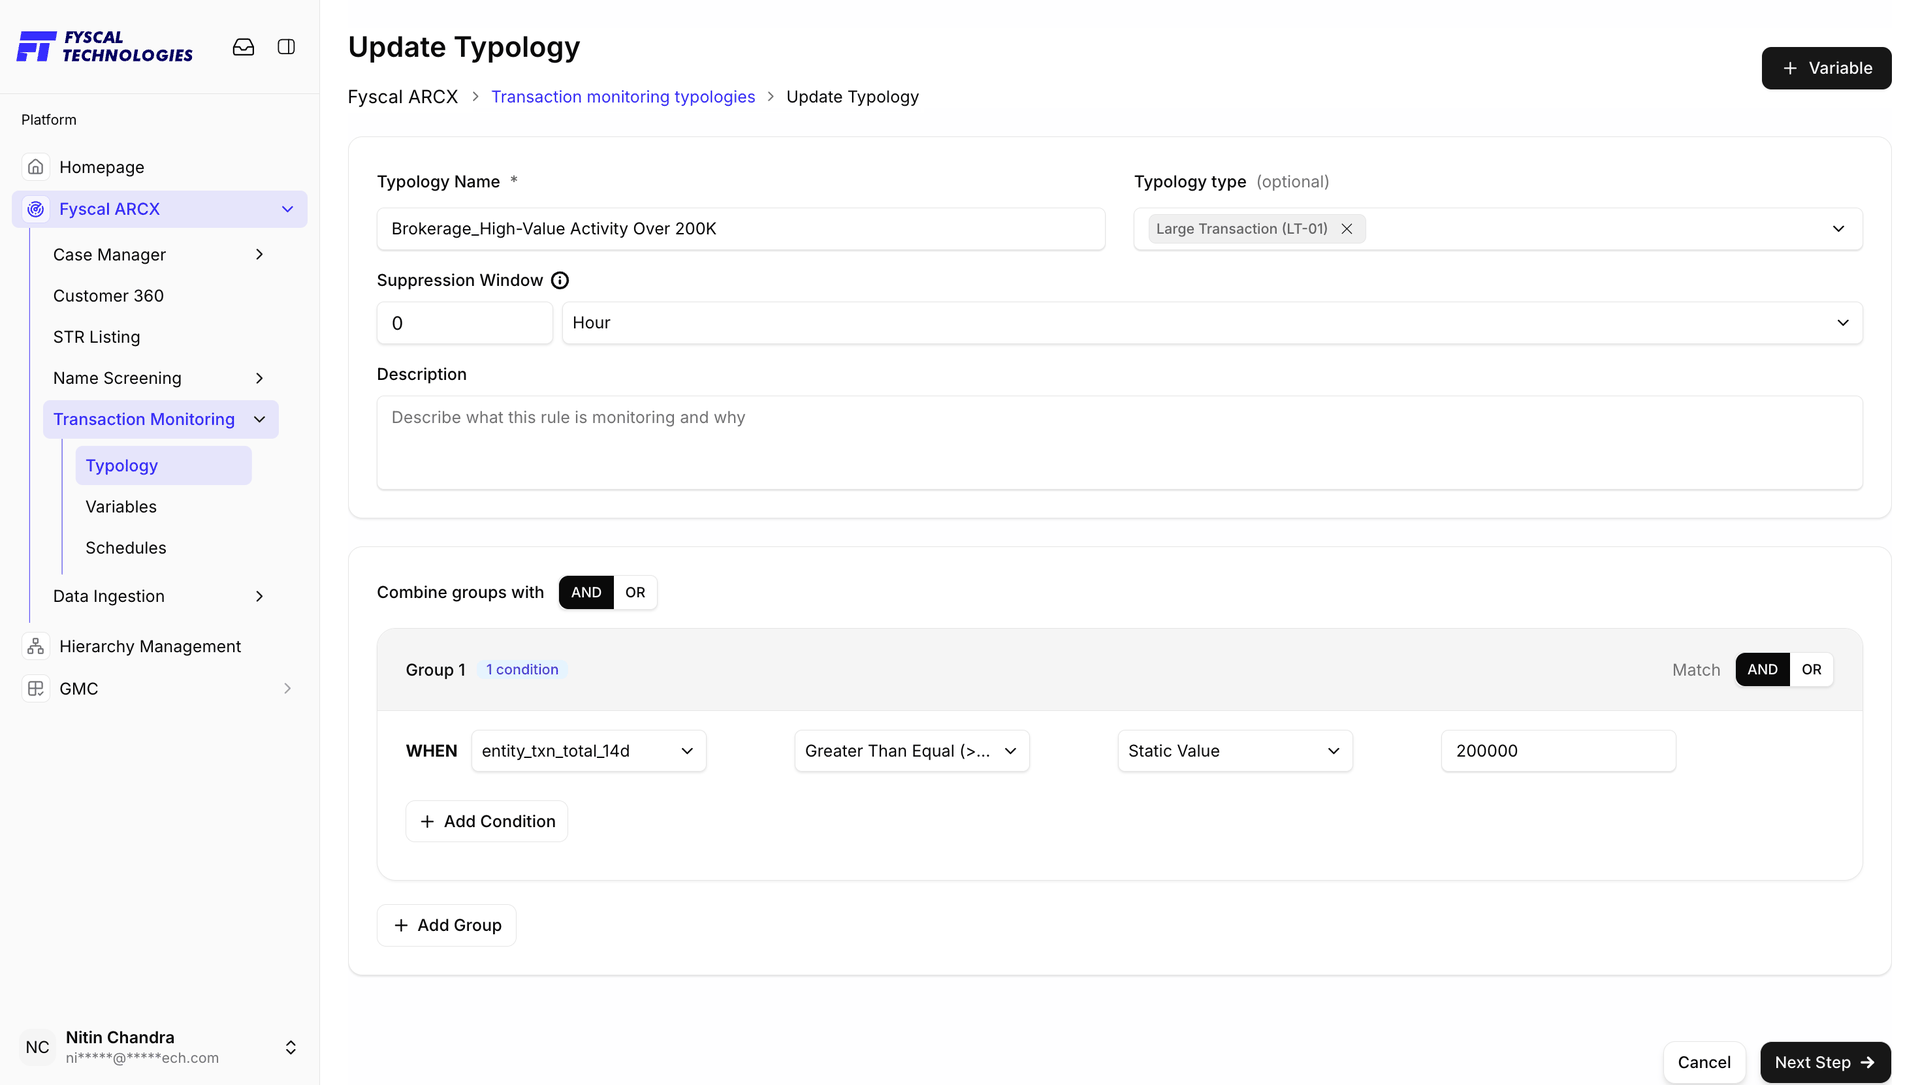
Use Duplicate Typology on the detail page instead when you want a variant of a rule — a different threshold or time window — without touching the original.
Variables are named calculations reused across rules — e.g. Count, Sum, Avg, Max, Min, Distinct Count.
Every variable ever created is listed with its Variable ID, Created date, and Last Updated date — the live example runs to 154 variables across 16 pages.
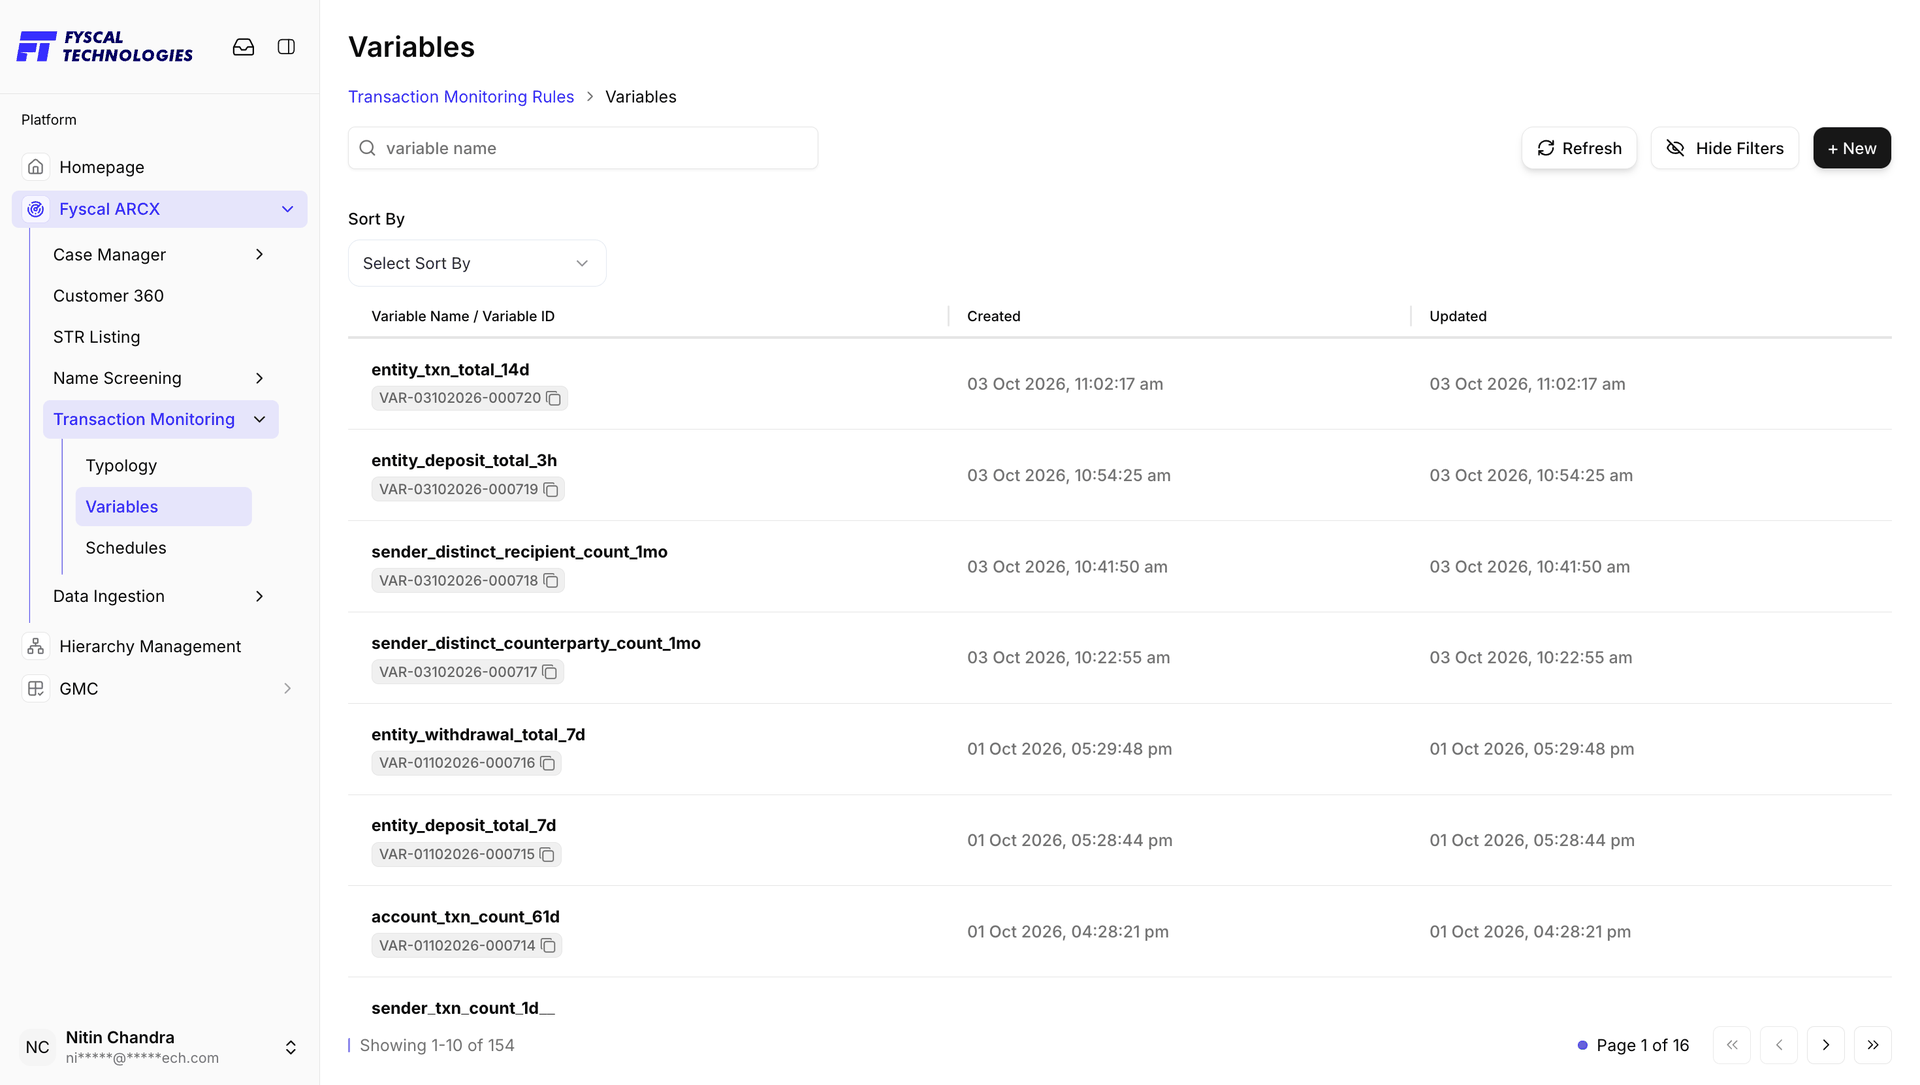
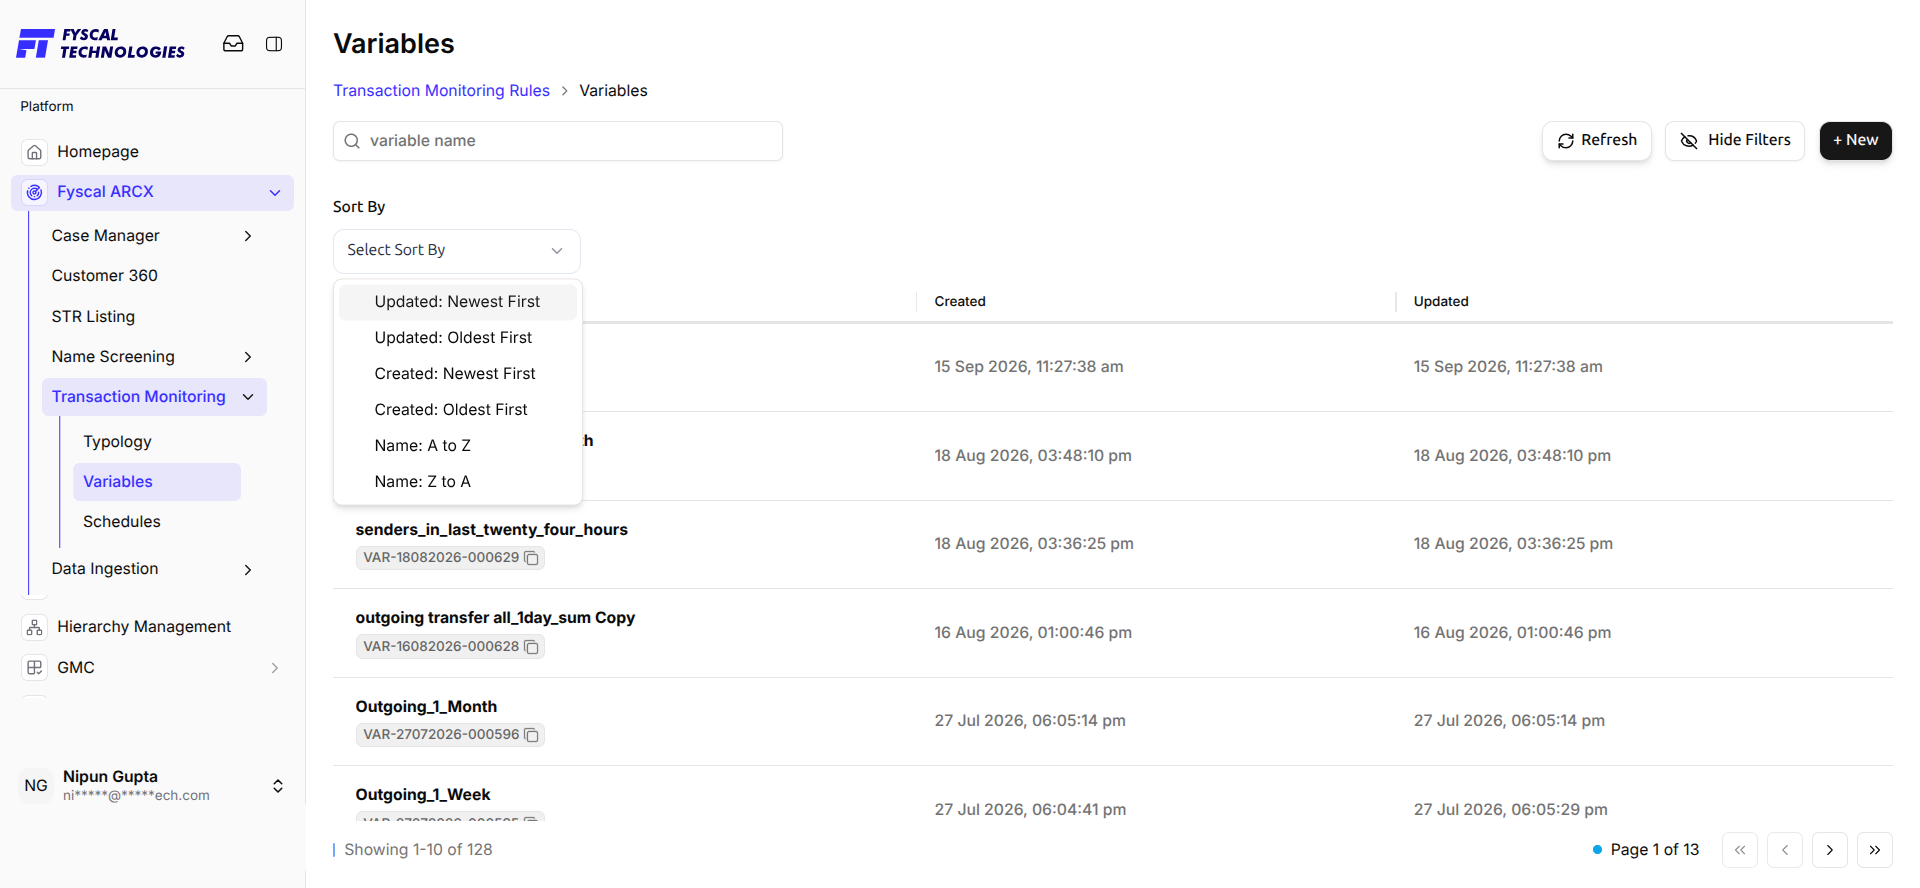
With this many variables, Sort By narrows things down fast.
Sort by Updated or Created (Newest or Oldest First), or alphabetically by Name (A to Z / Z to A).
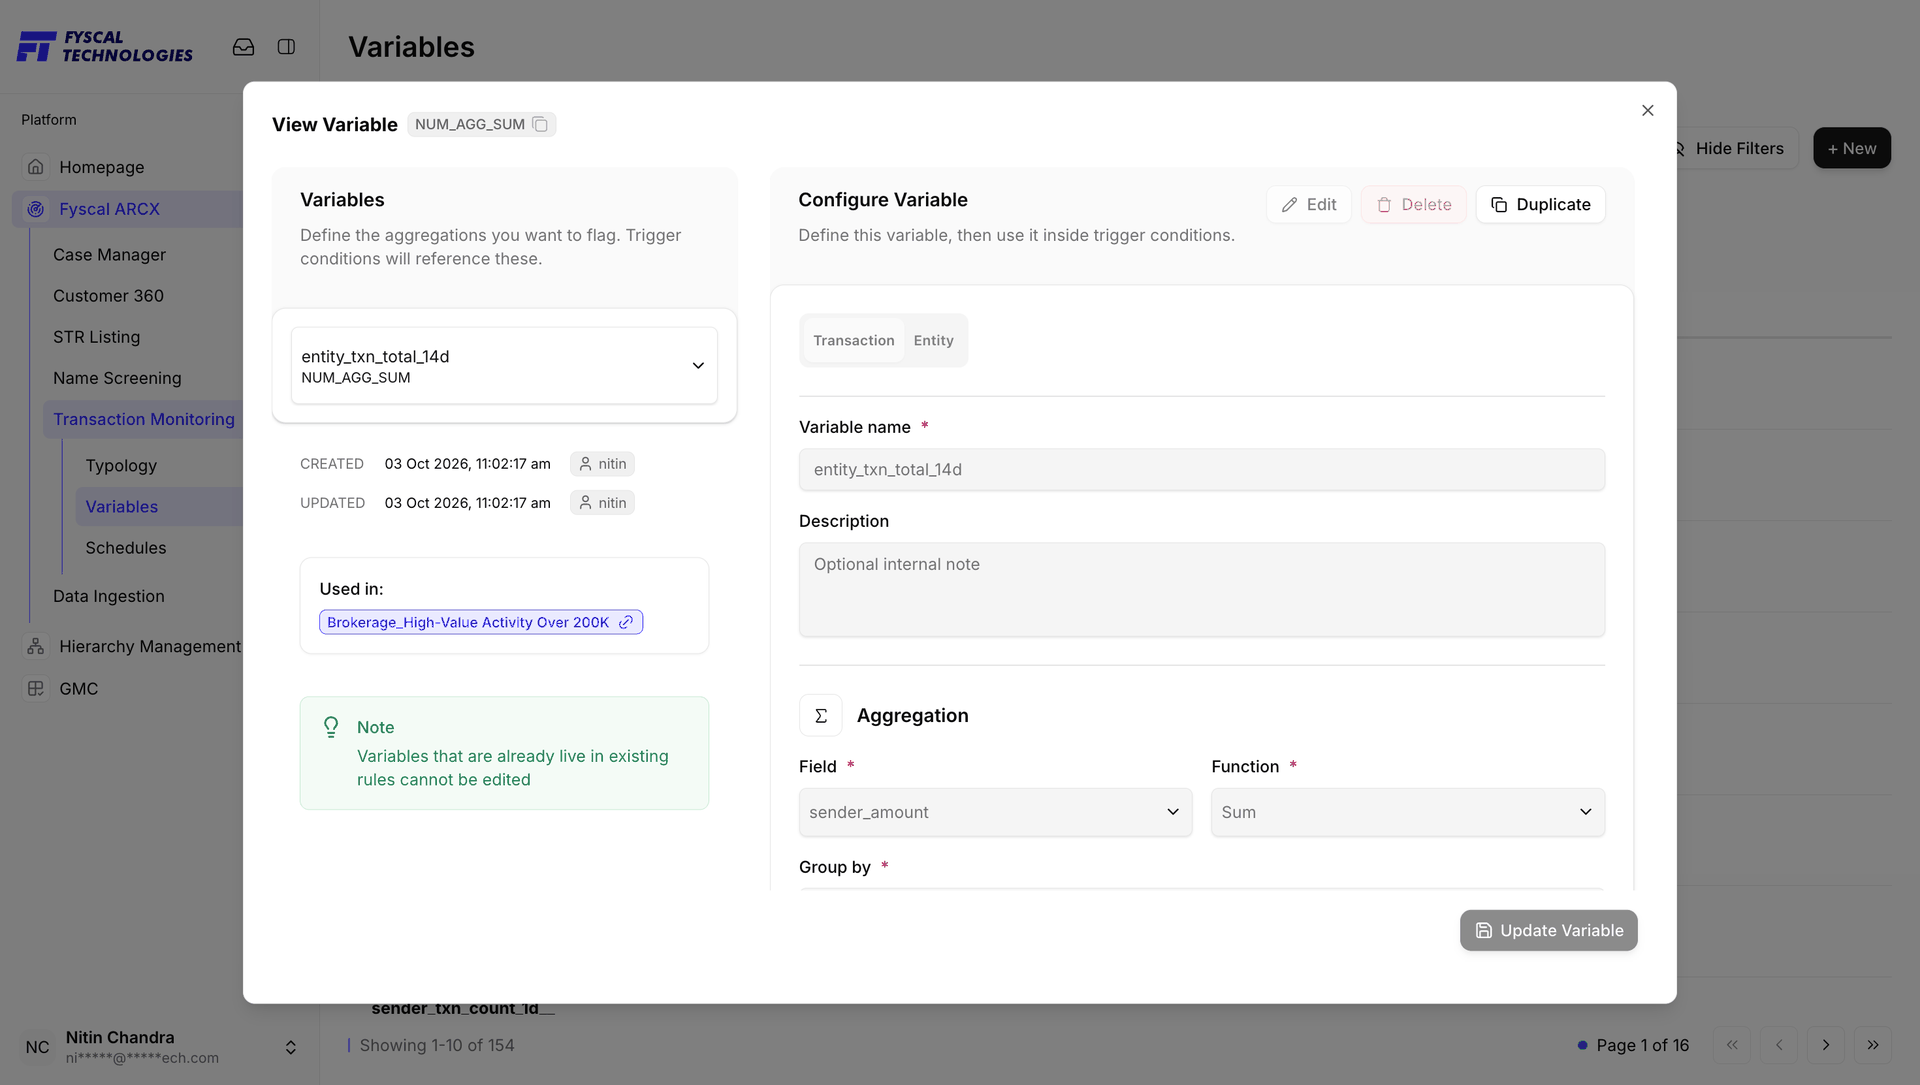
Click a variable to see where it is used.
Opening a variable shows a read-only View Variable dialog: its type, name, aggregation and the day it was created and updated, plus a Used in list of every rule that references it. Because of that, a note explains that variables that are already live in existing rules cannot be edited; Duplicate makes an editable copy instead.
Need a calculation that doesn't exist yet? + New builds one from scratch.
Pick Transaction or Entity, give the variable a Variable name and an optional description, then set its Aggregation — the Field to calculate on, the Function (e.g. Sum) and the Group by field. You can also start from an existing variable using the dropdown on the left.
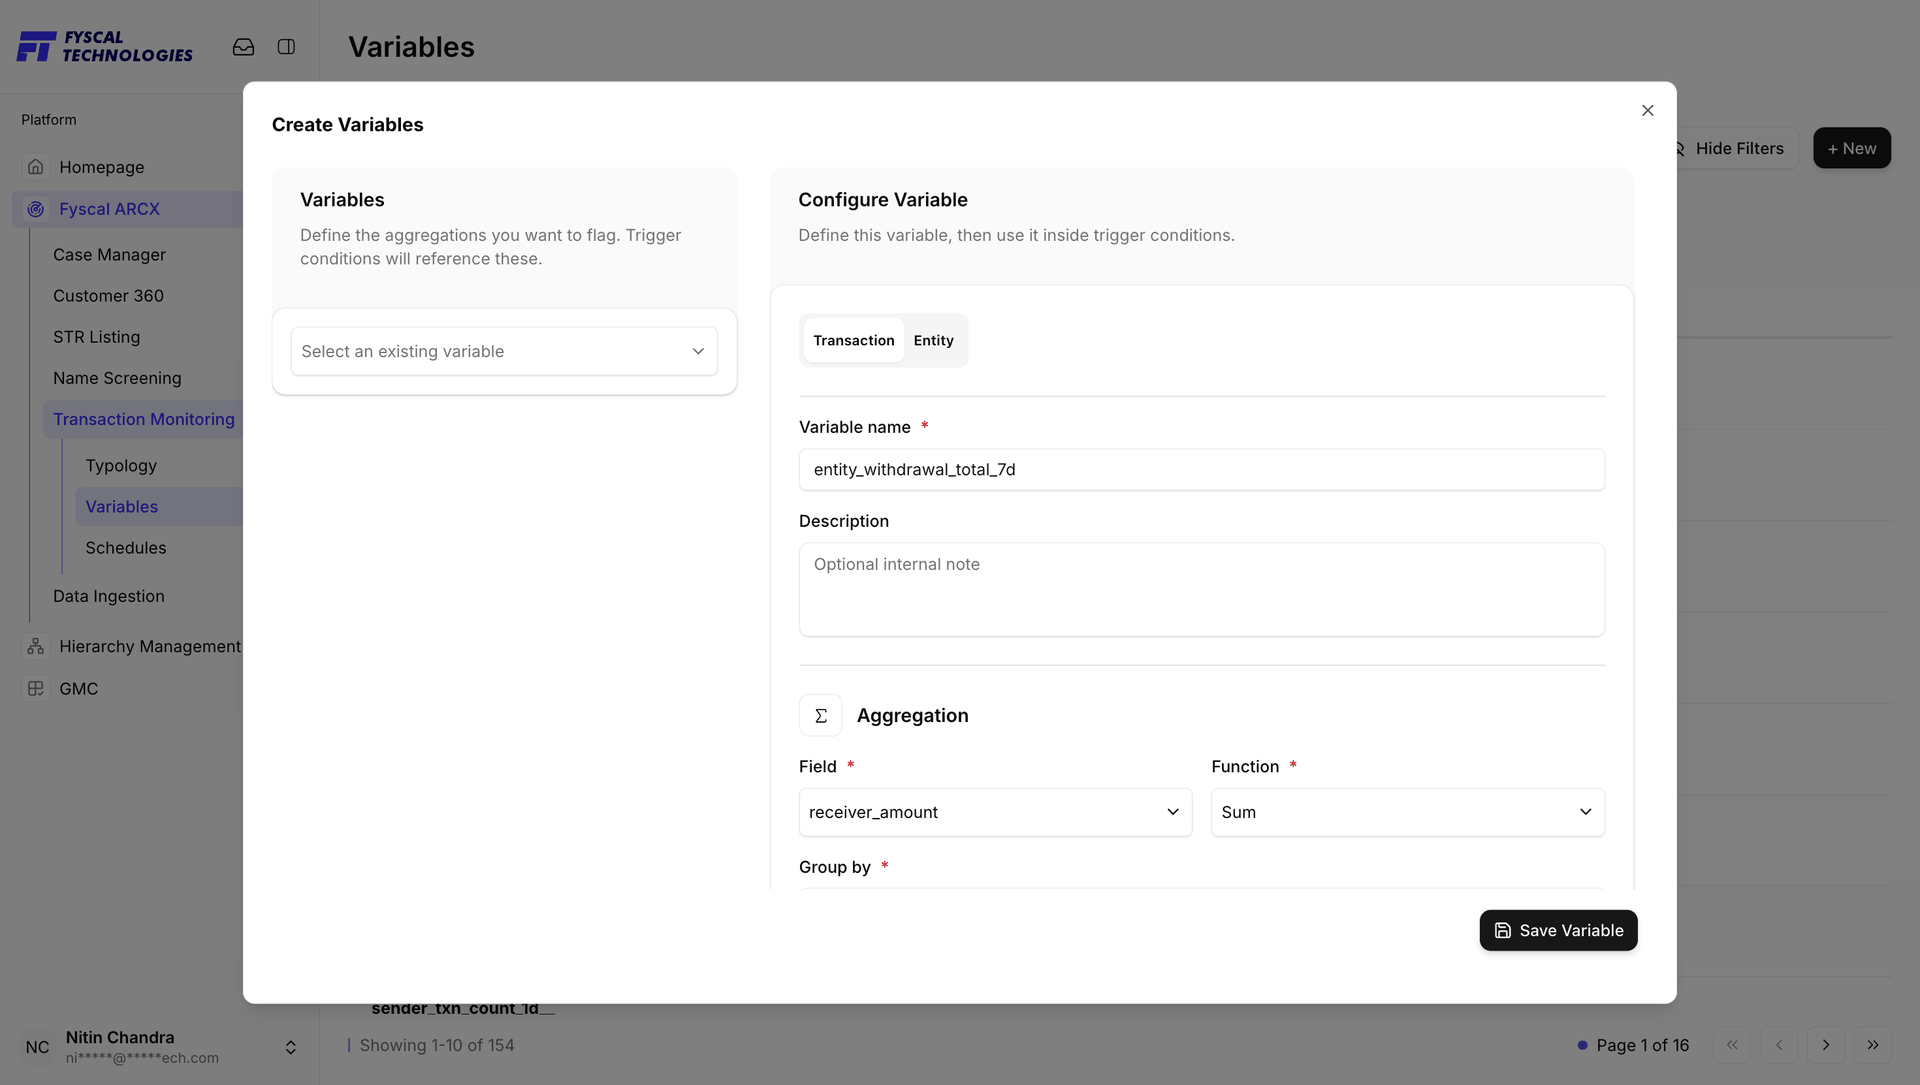
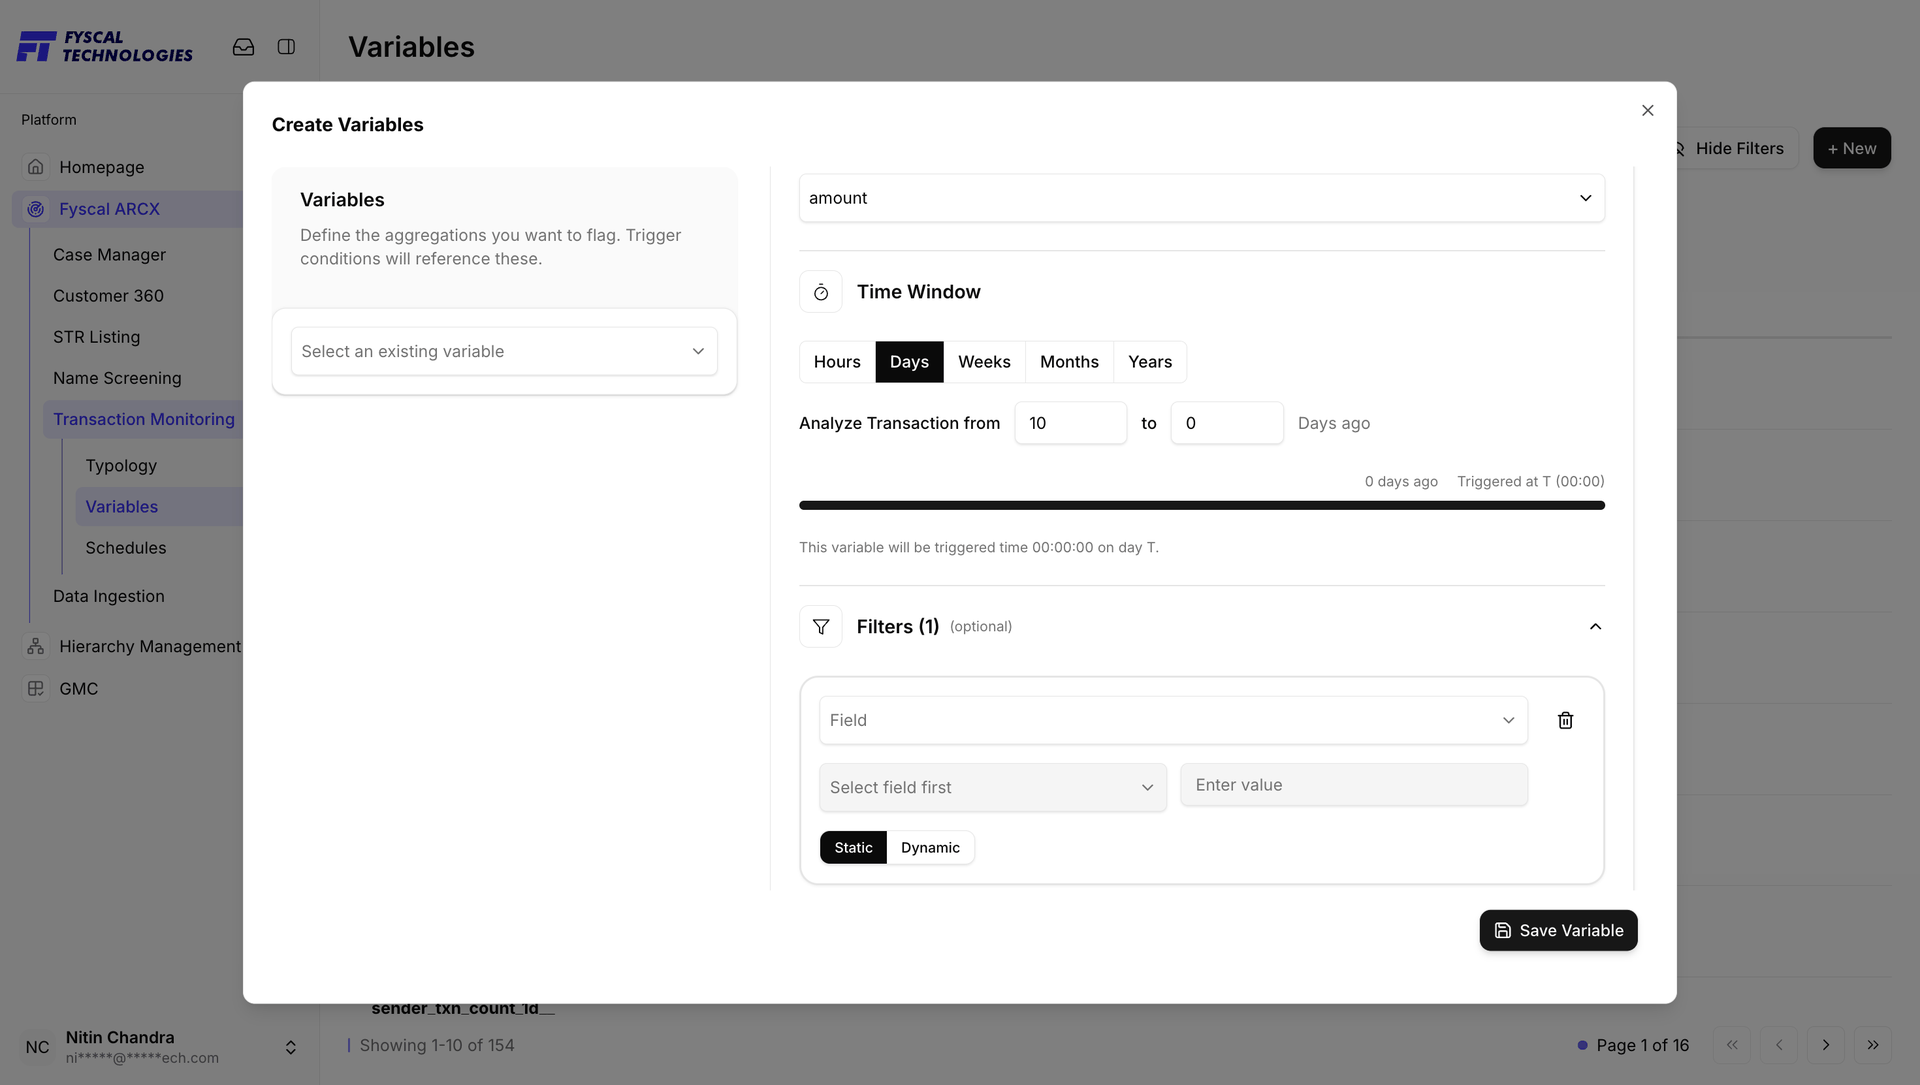
Further down, the Time Window is chosen in Hours, Days, Weeks, Months or Years, then Analyze Transaction from one number to another ago — a timeline underneath shows the span relative to the trigger time T. Optional Filters restrict the calculation to matching transactions: pick a Field, an operator and a value, set as Static (a fixed value) or Dynamic. Click Save Variable when done.
Building variables instead of repeating logic in every rule gives four benefits: Reusability (one calculation, many rules), Performance (compute once, reuse), Readability (a named variable reads better than the raw logic it represents), and Maintainability (change the definition once and every rule using it updates automatically).
Trigger conditions decide when alerts are created — e.g. count_sender_txns_1_week > 5, amount > 10000, country = 'High Risk'. AND requires all conditions in a group to be true; OR requires any one condition to be true. Each condition is a WHEN row: a variable, an operator (e.g. Greater Than (>), Equal (=), Between), and a value. The value can be a Static Value (fixed threshold), a Variable (calculated), or Ingested Data (a raw transaction field).
A Variable calculates a value; a Trigger Condition checks that value and decides whether to raise an alert. A variable on its own is just information — the trigger condition is what tells the system that information is suspicious.
Turns Execution Interval into a proper, reusable, named object instead of a setting buried inside one rule. A Schedule has its own Name, a numeric Execution Interval (e.g. 1 Week, 6 Hours), a Start Time, and an optional End Time — and it can be attached to a published rule or referenced by a rule still in draft, so the same schedule definition doesn't have to be rebuilt each time.
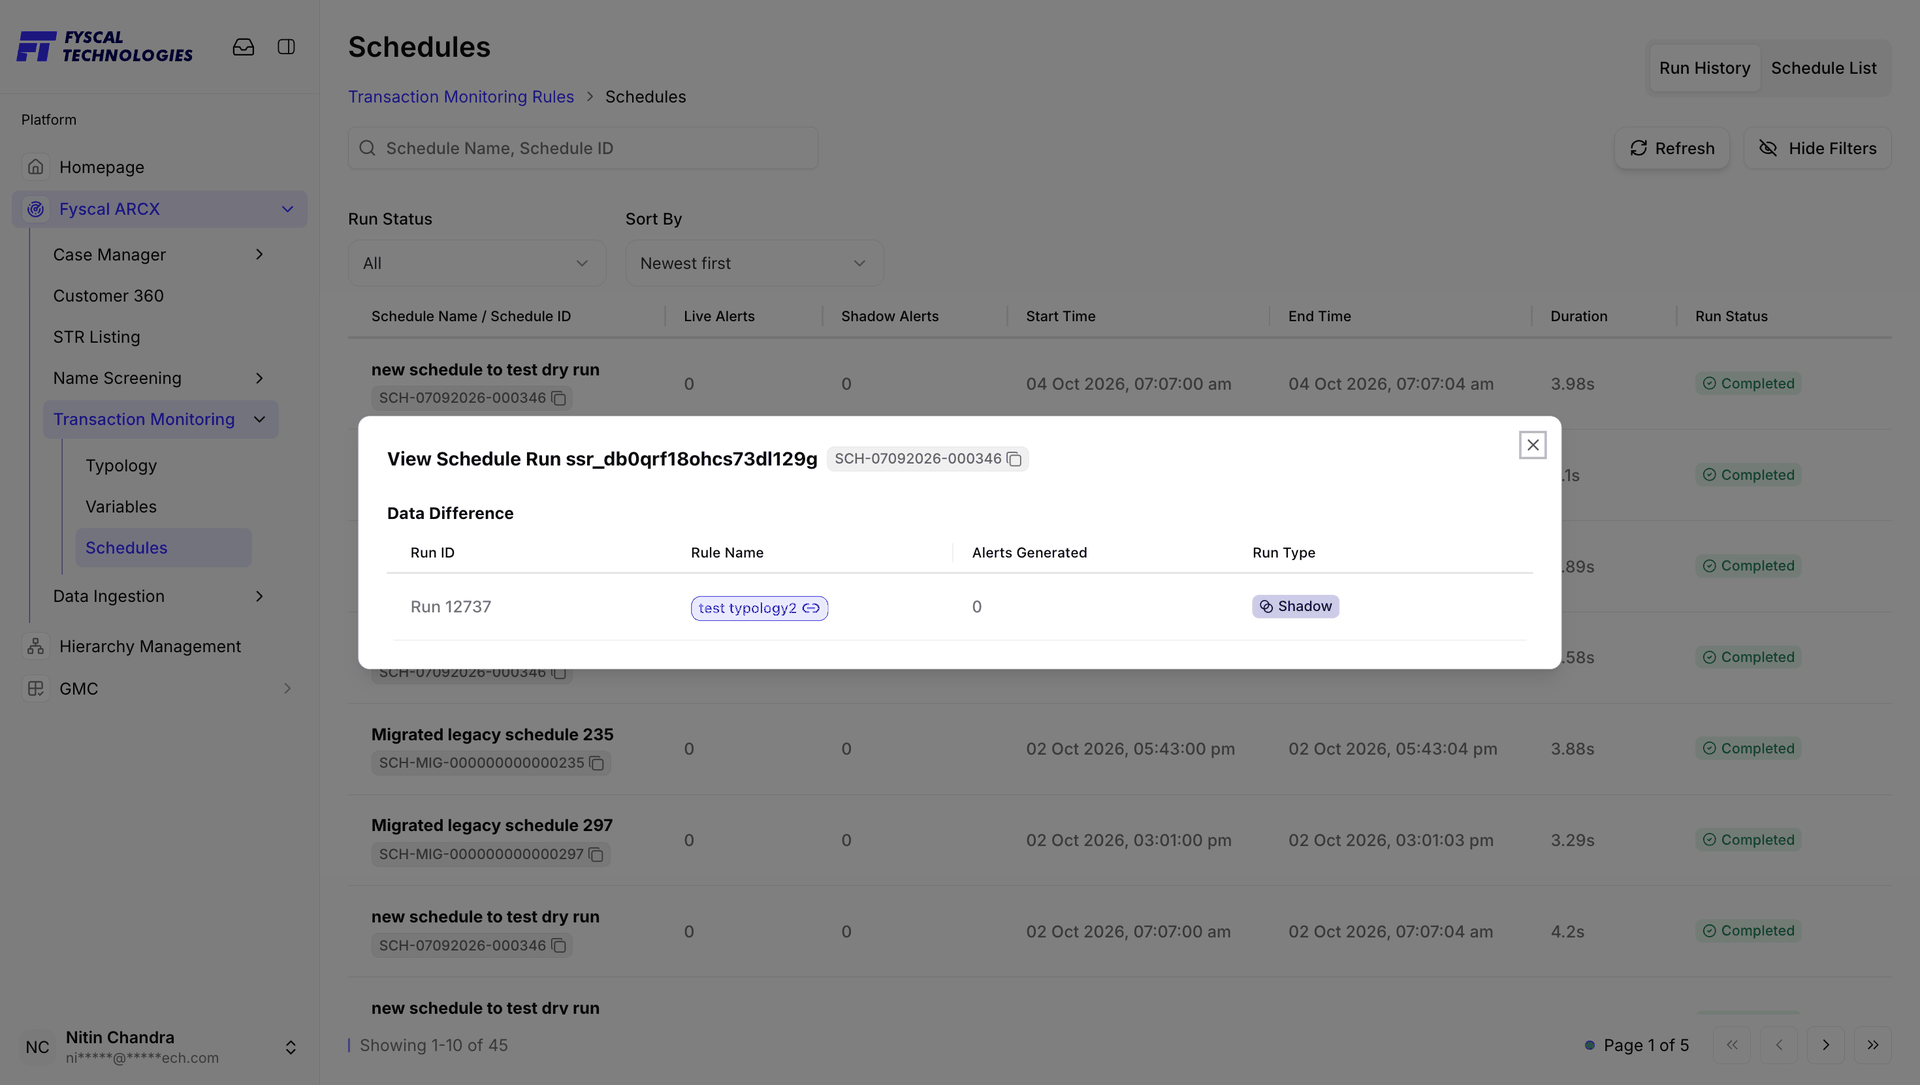
The screen has two tabs, Run History and Schedule List. Run History logs every individual execution of every schedule — Start Time, End Time, Duration, Run Status, and a Live Alerts / Shadow Alerts count split so you can see how many alerts a run produced on Published rules versus rules still in Shadow. Filter by Run Status or Sort By (Newest first), or search by schedule name or ID.
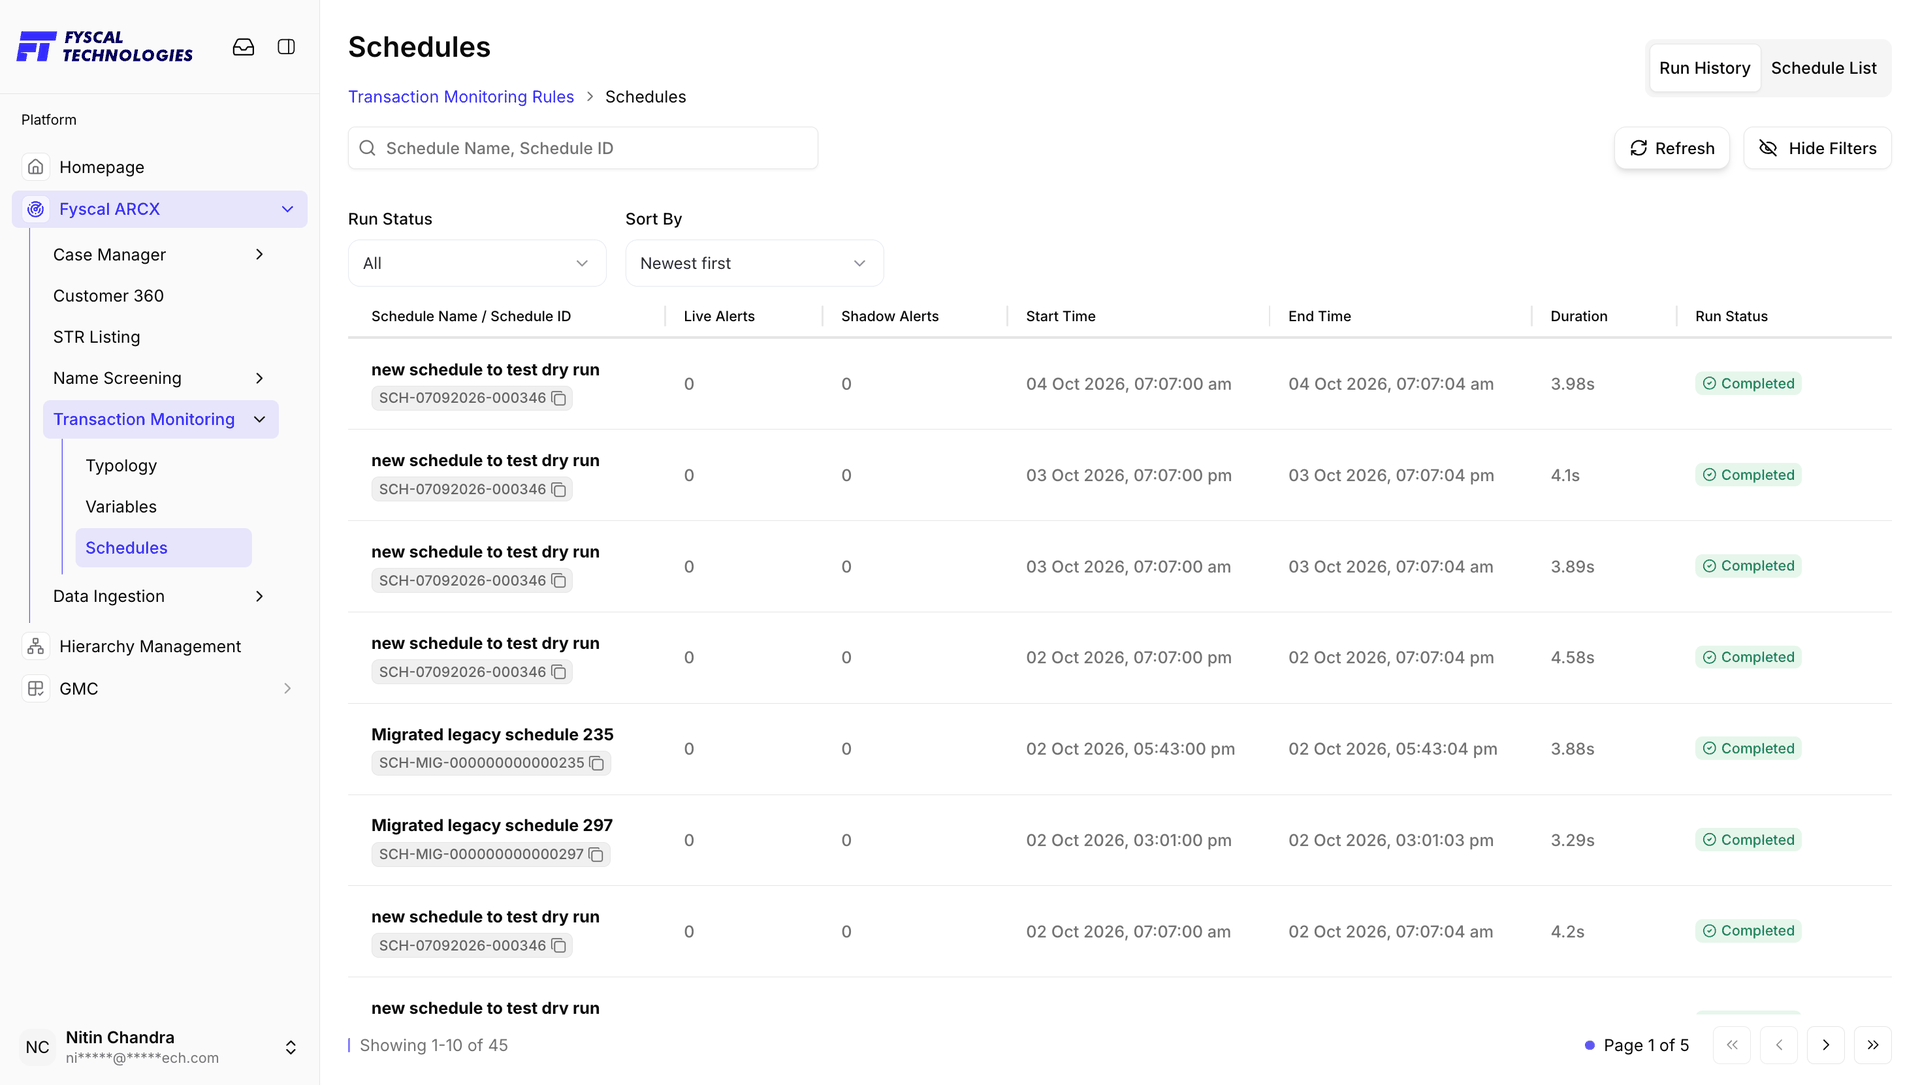
Clicking a run opens View Schedule Run, with a Data Difference table listing each rule the run executed — Run ID, Rule Name, Alerts Generated, and Run Type (for example Shadow).
The Schedule List shows every schedule that's ever been created, alongside:
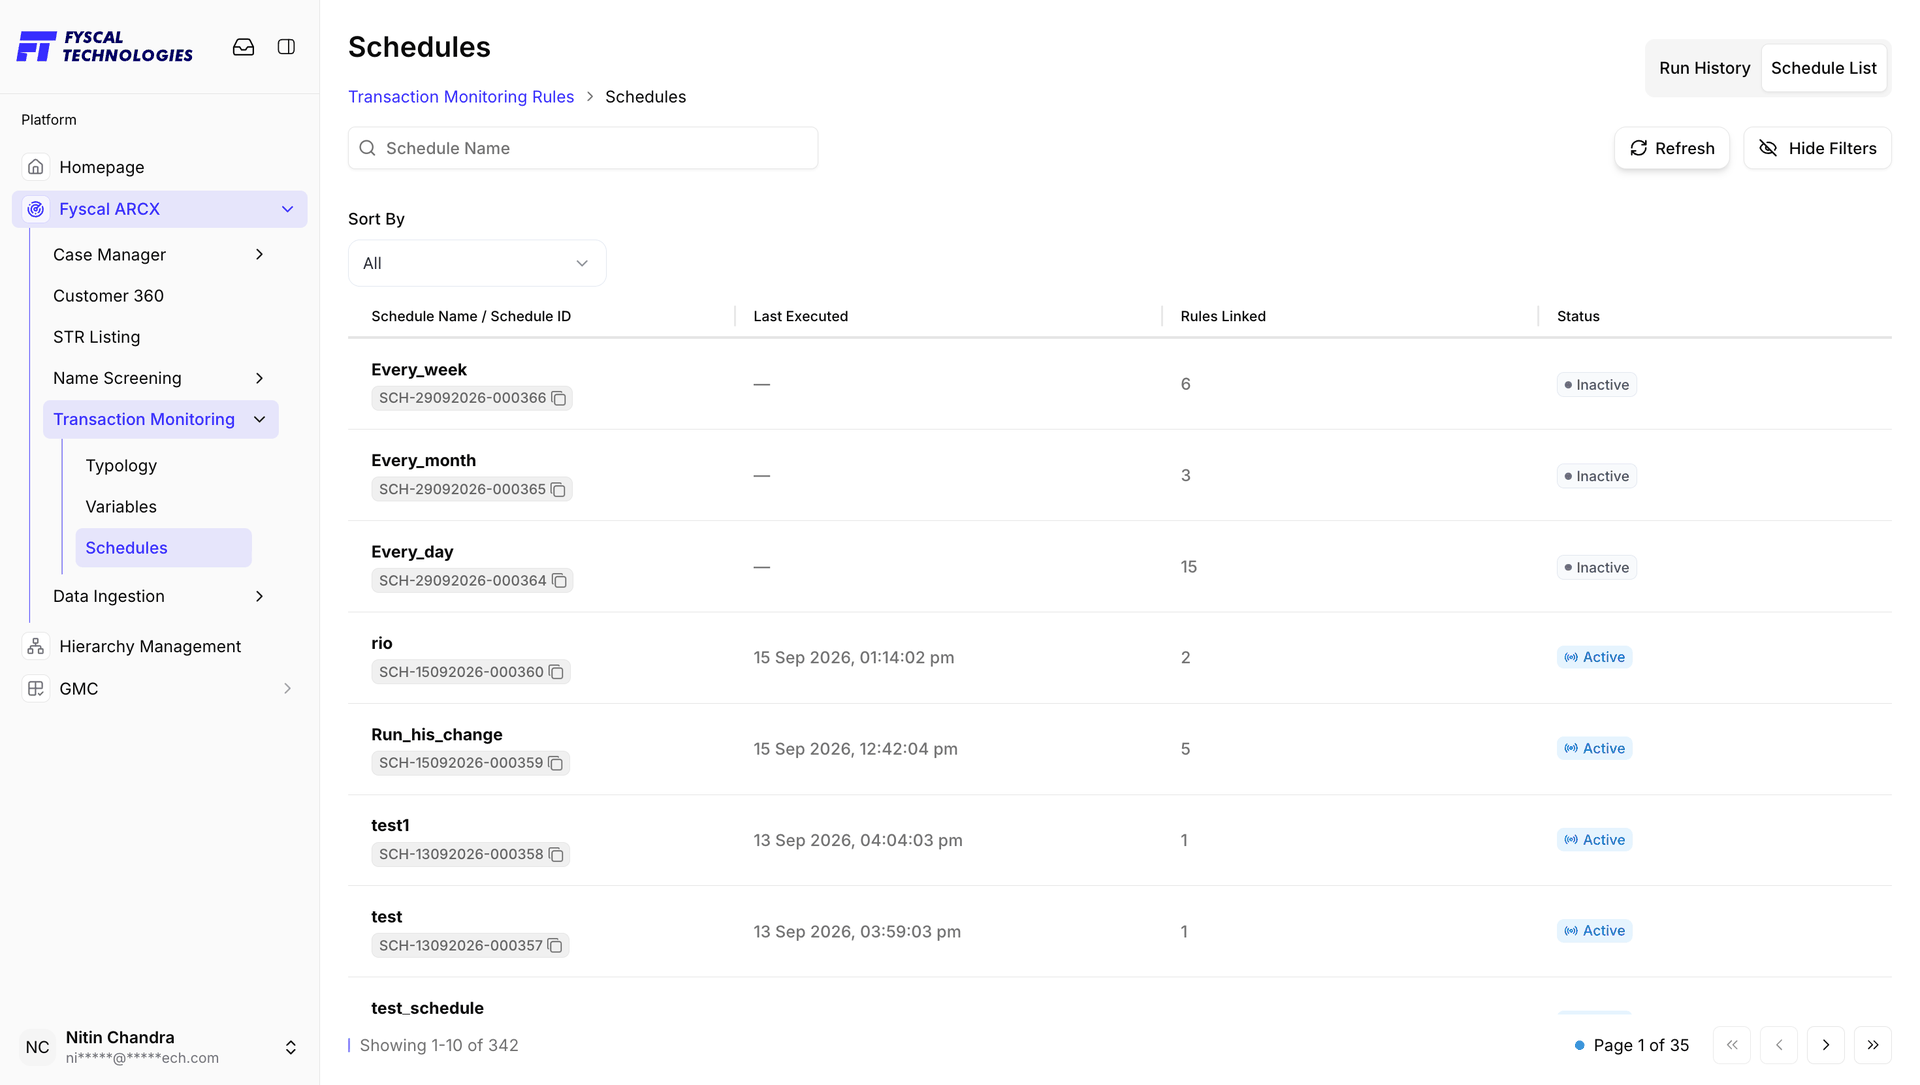
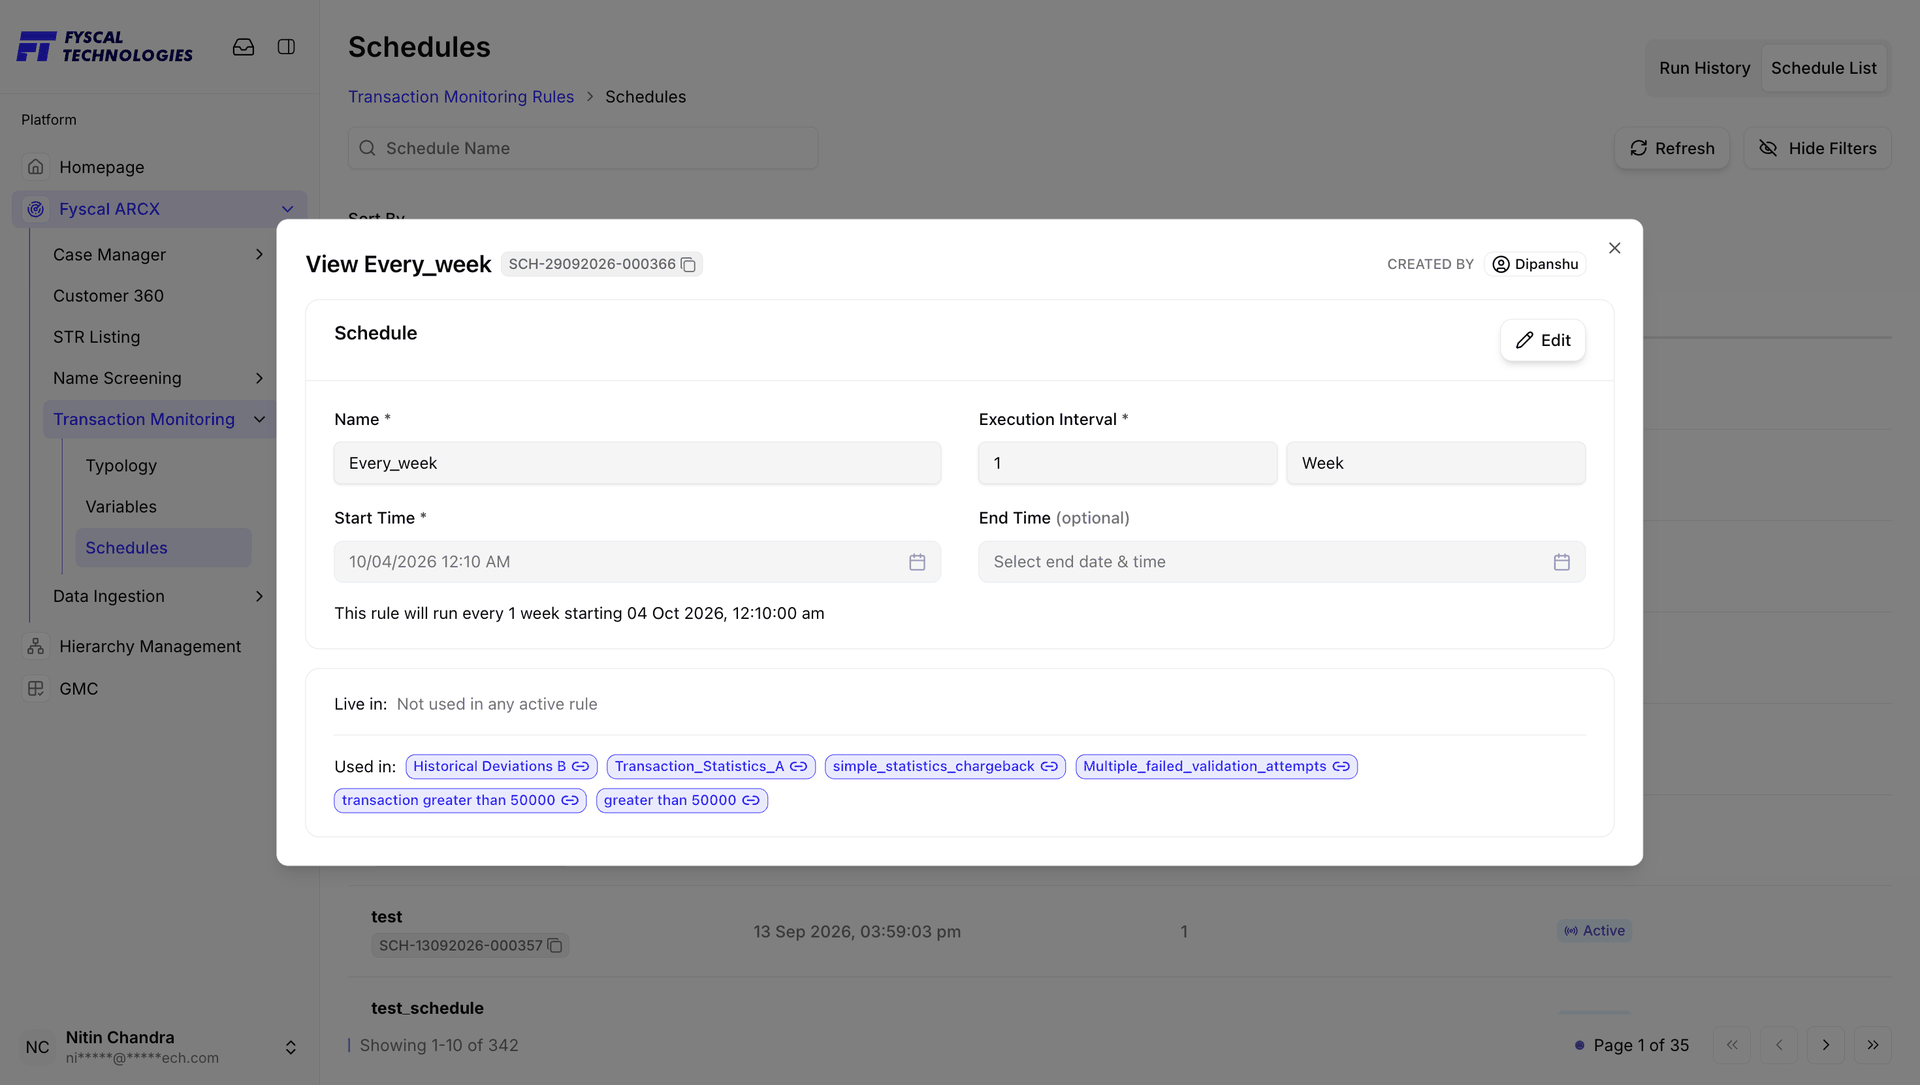
Clicking into a schedule opens its detail view — Name, Execution Interval, Start Time, End Time and a plain-language summary of when it runs — and shows exactly where it is being used:
Example variable: count_sender_txns_1_week — the count of transactions made by each
sender in the last 7 days. The engine calculates it once per sender, and every rule can reuse
it:
| Sender | Transactions in Last Week | Variable Value |
|---|---|---|
| A | 5 | count_sender_txns_1_week = 5 |
| B | 1 | count_sender_txns_1_week = 1 |
| C | 3 | count_sender_txns_1_week = 3 |
Real example — today is 10 Jul 2026. Sender A's transactions:
| Date | Amount |
|---|---|
| 09 Jul | ₹1,000 |
| 08 Jul | ₹2,000 |
| 05 Jul | ₹5,000 |
| 29 Jun | ₹8,000 |
| 20 Jun | ₹4,000 |
| Pattern | Variable | Trigger Condition |
|---|---|---|
| Amount-based | total_amount_1_day | total_amount_1_day > 100000 |
| Count-based | count_sender_txns_24_hours | count_sender_txns_24_hours > 10 |
| Country-based | — | country = 'High Risk' |
| Combined (AND) | amount, country, count_sender_txns_1_day | amount > 50000 AND country = 'High Risk' AND count_sender_txns_1_day > 3 |
A reference catalogue of every detection pattern available when building a Typology in Transaction Monitoring — organized by category, with what each pattern detects, when to reach for it, and a worked example.
This library doesn't introduce a new screen — it's the pattern reference behind the Condition Groups you assemble on the Create Typology screen. Every pattern below is built the same way: pick a Variable (or an ingested field), choose a comparison, and combine one or more conditions into Groups with AND/OR. What changes from pattern to pattern is which Variables and comparisons actually catch the behaviour you're trying to flag — that's what this reference is for.
Every pattern in the library falls into one of four broad families. A Typology can combine patterns from more than one family in the same rule — e.g. an Anomaly Detection condition AND'd with a Denylist check.
| Family | What It Catches | Typical Use |
|---|---|---|
| Anomaly Detection | Behaviour that breaks from an entity's own history — sudden activity, deviation from a rolling average, a field value never seen before | Dormant accounts reactivating, spending spikes, first-time countries or currencies |
| Structuring & Layering | Money movement shaped to mask its size or origin — split amounts, rapid pass-through, near-threshold values | Classic AML typologies: structuring, smurfing, layering, funnel accounts |
| Cardinality & Set Combination | Counts, sums, and repeated values across transactions, entities, or shared fields | Velocity limits, shared-device/shared-instrument detection, high-volume outliers |
| Denylist / Custom List | Direct matches against an organization-maintained list of known-bad values | Blocked IPs, prohibited jurisdictions, previously flagged identifiers |
These patterns compare an entity's current behaviour against its own recent history, rather than against a fixed threshold — useful when "normal" varies too much from customer to customer for a single static rule to work well.
| Typology | What It Detects | Best For |
|---|---|---|
| Dormant Activity | Sudden transacting after a period of inactivity, above a minimum amount | Reactivated accounts, sleeper accounts used for a single large movement |
| Historical Deviation — Trend | Recent activity that deviates from an entity's own rolling average by more than a set number of standard deviations | Spending pattern shifts that a fixed threshold would miss for both very small and very large accounts |
| Historical Deviation — Period Delta | Total activity in one period compared directly against total activity in a prior period | Simple before/after comparisons without needing a standard-deviation calculation |
| Newly Seen | A field value (country, currency, device, counterparty) appearing for an entity for the first time in a defined lookback | First-time-seen countries, currencies, or counterparties for an otherwise stable customer |
Variable sum_amount_1_day Trigger Condition
sum_amount_1_day > 5000 AND days_since_last_txn > 60 — an entity that
has been dormant for 60+ days suddenly moves more than $5,000 in a single day.
Variable distinct_count_country_12_weeks Trigger Condition
country NOT IN previous_countries_seen AND count_previous_txns >= 2 — an
entity with at least two prior transactions suddenly transacts from a country it has
never used before.
The core AML pattern family: money broken into pieces, passed through quickly, or held just under a reporting threshold to avoid detection.
| Typology | What It Detects | Best For |
|---|---|---|
| Entity-Pair Conduit | A pair of entities transacting a large volume between each other with the net flow close to zero | Two accounts used purely to move money back and forth, netting out to nothing |
| Structuring | A run of non-consecutive transactions with similar fiat values, clustered near a threshold | Classic structuring — many similar-sized transactions instead of one large one |
| Layering | A large inbound amount immediately re-split and sent out to multiple counterparties | Funds received then rapidly fragmented to obscure the trail |
| Pass-Through | Received and sent amounts that are nearly equal within a short window | Accounts acting as a conduit rather than a genuine end user |
| Pass-Through — Transferred Percent | A large percentage of received funds forwarded on to a single counterparty | Identifying a likely middleman or mule account |
| Transaction Funds Ratio | An unusually large share of received funds originating from one unexpected source relative to an entity's usual senders | A sudden, disproportionate reliance on one counterparty or region |
| Near-Threshold Statistics | Transactions whose average value sits just under a regulatory reporting threshold, combined with a minimum aggregate volume | Smurfing designed to stay under a specific reporting limit |
An entity makes 10 transactions in 24 hours valued at $5,000, $4,800, $5,000, $4,900,
$5,100, $4,999, $5,000, $5,099, $4,950, and $5,020 — all clustered just under a $5,500
internal review threshold. Trigger Condition:
count_similar_amount_txns_24h >= 8 AND stddev_amount_24h < 150.
An entity receives $150,000, then within the same 24-hour window sends $145,500 to one
counterparty and $4,500 to another. Trigger Condition:
sum_received_24h > 100000 AND sum_sent_24h / sum_received_24h > 0.9.
These patterns count things — transactions, distinct values, shared fields — rather than evaluating amounts directly. They're the workhorse of velocity-based monitoring.
| Typology | What It Detects | Best For |
|---|---|---|
| Same-Value Transactions | A number of transactions of an identical amount in a given window | Repeated small-value transactions, e.g. structured ATM withdrawals |
| Simple Count — Relative | A condition (e.g. a specific status) occurring in more than X% of an entity's transactions | High failure/chargeback rates relative to overall volume |
| Simple Entity Count | Raw count of transactions, instruments, currencies, cities, or IPs tied to one entity in a window | Velocity limits — too many transactions or too many distinct attributes in too little time |
| Simple Object Count — Entities/Instruments | A shared field (phone, email, IP, device ID) reused across multiple distinct entities or instruments | Detecting shared credentials across supposedly unrelated accounts |
| Simple Object Count — Transactions | A transactional field value repeated across an unusually high number of transactions | The same instrument or reference number appearing far more often than expected |
| Simple Statistics | Min/average/max/sum of a field crossing a fixed threshold | Straightforward volume or value thresholds |
| Simple Statistics with Count | A statistic threshold combined with a minimum transaction count in the same window | Avoiding false positives from a single large-but-legitimate transaction |
| Simple Statistics with Custom Field | A statistic evaluated against a value held in a custom data field rather than a standard transaction field | Thresholds tied to institution-specific data, e.g. declared net worth or loan limit |
| Top Transacting Entities | Entities ranking in the top N by sum or count of transactions over a period | Periodic review of the highest-volume accounts, regardless of a fixed threshold |
Variable count_shared_phone_entities Trigger Condition
count_shared_phone_entities > 1 — the same phone number is registered
against more than one customer profile.
Direct matches against a list your organization maintains — distinct from the LSEG-backed Watchlist used for sanctions and PEP screening in Name Screening. These lists live under Admin → Lists and can hold IPs, jurisdictions, or any other string value worth blocking on sight.
| Typology | What It Detects | Best For |
|---|---|---|
| Entity Denylist | An entity ID appearing on a maintained denylist | Directly blocking a known-bad customer or counterparty by identifier |
| Denylist String — Entities/Instruments | An entity or instrument field (typically IP) matching a denylisted string | Blocking traffic from known-suspicious IP ranges at the entity/instrument level |
| Denylist String — Events | Same matching logic applied at the individual event/transaction level | Catching a single suspicious event without waiting for a pattern to build |
| Country-Subdivision Denylist/Allowlist | Transactions originating from a denylisted (or not on an allowlisted) state/province | Jurisdiction-specific product restrictions, e.g. a product not licensed in a given state |
| Global IP Denylist | Transactions or logins from IPs on a centrally maintained fraud/abuse list | A baseline layer of protection that doesn't depend on the institution building its own IP list first |
Instead of evaluating one entity in isolation, a graph-based Typology looks for shared attributes — the same address, device, IP, or payment credential — connecting multiple, seemingly unrelated entities.
Three unrelated customer profiles all check out using the same stored card number — a graph-based Typology matching on instrument ID with a minimum of 3 entities flags the cluster in one alert rather than three separate ones.
Pre-shaped Typologies covering common fraud and scam patterns, built to be duplicated and tuned rather than written from scratch. Filter the Typology list by category to see all of them together.
| Template | Triggers When | Data Required |
|---|---|---|
| Spending Pattern Anomaly | Monthly spend exceeds 200% of the trailing 6-month average AND the count of distinct recipients grows by more than 300% over the same window | Transaction amounts, recipient identifiers |
| Romance Scam Keyword Match | A transaction note/description matches a romance-scam keyword list AND cumulative sent amount exceeds $1,000 in the review window | Transaction amounts and free-text notes/descriptions |
| Crypto Wallet Risk Assessment | A new crypto wallet is added, no prior wallet was added recently, the account is under 30 days old, AND an outbound transfer occurs within 24 hours | Wallet-added action event, account registration date, transaction amounts |
| Cross-Device Cash-Out | More than 10 daily logins, from more than 3 distinct IPs and more than 2 distinct devices, AND total withdrawals exceed $1,000 in the past week | Login events with IP, device ID, transaction amounts |
| Accelerated Withdrawal Monitor | Daily withdrawal amount exceeds 3× the prior month's daily average AND the trailing week's total exceeds 5× the prior month's total | Transaction amounts |
Five patterns purpose-built for ACH rails, where the fraud signature usually shows up in account-matching, validation behaviour, or duplicate submission rather than in amount alone.
| Typology | What It Detects | Data Required |
|---|---|---|
| Mismatched Account Information | Receiver name on an ACH transaction doesn't fuzzy-match the account holder's name on file | Sender/receiver entities, ACH-classified transaction type |
| ACH Risk Score | A model-derived score estimating the likelihood of an R10 (unauthorized) return crosses a set threshold | Sender/receiver entity, ACH-classified transaction type, an ACH risk-scoring model |
| Consortium-Flagged Originator/Receiver | Either party has been previously flagged as a bad actor in a shared industry consortium data set | Sender/receiver entities, ACH-classified transaction type |
| Multiple Failed Validation Attempts | Repeated failed prenote/micro-deposit validation attempts in a short window | Action events with status, mapped to the entity attempting validation |
| Suspicious Duplicate ACH Transactions | Two or more ACH transactions with the same sender, receiver, and amount submitted in a short window | Sender/receiver entities, ACH-classified transaction type |
Check-specific patterns need three fields ingested and mapped before they'll fire: Check Account Number, Check Routing Number, and Check Number.
| Typology | What It Detects |
|---|---|
| Check Matches Recent Suspicious Deposit | Deposit amount matches a recently flagged suspicious deposit — possible duplicate submission |
| Duplicate Check Number | The same check number presented more than once |
| Missing Check Number | A check transaction with no check number at all — a possible attempt to dodge detection entirely |
| Out-of-Sequence Check Number | A check number falling outside the account's expected numbering sequence |
| Stale Check | A check presented for clearing significantly later than expected |
| Typology | What It Detects | Best For |
|---|---|---|
| Aggregate Difference | The gap between total inbound and total outbound activity crossing a set threshold in a window | Jurisdiction-specific regulatory limits expressed as a net figure |
| Repeat Alert Escalation | An entity that has already accumulated a minimum number of prior alerts above a value threshold, triggering an escalation alert | Ensuring repeat offenders get elevated review rather than resetting to zero each time |
| Multiple Rule Occurrences | The same underlying Typology firing for an entity more than once within a set period | Use cases that need "has this happened before" as a condition, not just "is this happening now" |
| Insider Trading Pattern | A similar transaction (e.g. selling the same security) executed by two related users within a short window of each other | Detecting trades that closely follow an insider's own trade |
| Relative Transaction Amount Sequence | Two consecutive transactions where the second is a defined percentage of the first, within a set window; each side of the pair can carry its own embedded filter | Sell-at-a-loss patterns in securities or crypto |
| Simple Filters | Any direct field-level match — the broadest and most commonly used pattern type | Wide, straightforward matches that don't need a Variable at all, e.g. transaction type = wire AND counterparty on a prior-flagged list |
Starting points for common business models, grouped by the pattern family they draw from. Each pack assumes typical thresholds will be re-tuned to the institution's own data before going to Published status — validate every pack with Dry Run first.
| # | Base Pattern | Suggested Configuration |
|---|---|---|
| 1 | Dormant Activity | $3,000+ after 90+ days of dormancy |
| 2 | Dormant Activity | Any activity resuming after 90+ days of inactivity, regardless of amount |
| 3 | Structuring | Structured transactions between $5,000–$10,000, 3-day window |
| 4 | Structuring | Smurfed transactions between $3,000–$5,000, 1-week window |
| 5 | Simple Filters | Large single deposit ≥ $10,000 |
| 6 | Simple Filters | Risk-based review of all transactions over $100,000 |
| # | Base Pattern | Suggested Configuration |
|---|---|---|
| 1 | Simple Entity Count | More than 2 wire transactions in a 7-day window |
| 2 | Simple Entity Count | Monthly transaction count above a specified limit, evaluated every 5 days |
| 3 | Simple Entity Count | One remitter sending to 5+ distinct beneficiaries within 5 days |
| 4 | Simple Filters | Transfer type transaction exceeding $500 |
| 5 | Simple Filters | Card activation attempted more than 100 miles from the customer's address on file |
| 6 | Simple Filters | An authorized remittance transaction while a prior remittance for the same entity is still on hold |
| 7 | Simple Statistics | Total wire transaction value above $4,999 in a 7-day window |
| 8 | Simple Statistics | Debit-card chargeback value above $1,000 in a 7-day window |
| 9 | Simple Statistics | Debit-card refund value above $1,000 in a 7-day window |
| # | Base Pattern | Suggested Configuration |
|---|---|---|
| 1 | Simple Entity Count | More than 2 bank transfers in a 1-month window, evaluated every 5 days |
| 2 | Simple Entity Count | Weekly deposit count above a specified limit, evaluated daily |
| 3 | Simple Filters | Any transaction > $0 by a non-employee entity |
| 4 | Simple Filters | Any single transaction > $9,000 |
| 5 | Simple Filters | Single transaction > $200,000 |
| 6 | Near-Threshold Statistics | 10+ transactions in 5 days averaging $1,000–$3,000 with combined volume > $20,000, evaluated daily |
| 7 | Near-Threshold Statistics | 20+ transactions in 5 days averaging $0–$1,000 with combined volume > $20,000, evaluated daily |
| # | Base Pattern | Suggested Configuration |
|---|---|---|
| 1 | Simple Entity Count | Weekly transaction count above a specified limit, 2-week window |
| 2 | Simple Filters | A specific transaction type/amount combination exceeding a threshold |
| 3 | Dormant Activity | Any activity resuming after a long period of dormancy |
| 4 | Structuring | Similar fiat-value transactions, non-consecutive, 2-week window |
| 5 | Near-Threshold Statistics | Transactions clustered close to a regulatory threshold, 2-week window |
| # | Base Pattern | Suggested Configuration |
|---|---|---|
| 1 | Layering | Withdrawals exceeding 80% of deposits within 1 week, evaluated daily |
| 2 | Simple Entity Count | 15+ deposits/withdrawals monthly, evaluated every 5 days |
| 3 | Simple Entity Count | Abnormally large count of unique transactions in a 1-month window |
| 4 | Simple Entity Count | High-value activity above $200,000, 2-week window |
| 5 | Simple Statistics | Payments to overseas contractors of $100,000+ per month, evaluated every 3 days |
| 6 | Simple Statistics | Cash deposits totaling $10,000+ within a 3-day period, evaluated every 3 hours |
| 7 | Simple Statistics | Abnormally large unique-transaction count, evaluated monthly on a fixed day |
| # | Base Pattern | Suggested Configuration |
|---|---|---|
| 1 | Simple Statistics with Count | Transaction count between 5 and 100, 92-day window |
| 2 | Near-Threshold Statistics | Lending-specific volume/count statistics, 1-month window |
| 3 | Simple Entity Count | Withdrawals fanning out to multiple bank accounts, 1-month window |
| 4 | Simple Entity Count | P2P transfers from one bank account to multiple recipients within a month, evaluated every 5 days |
| 5 | Simple Entity Count | Any employee-linked transaction within a 92-day window |
| 6 | Simple Statistics with Count | Abnormal deposit volume and count, 1-month window |
| 7 | Simple Statistics with Count | Abnormal withdrawal volume and count, 1-month window |
| 8 | Simple Statistics with Count | Abnormal buy/sell volume and count, 1-month window |
| 9 | Near-Threshold Statistics | Transactions clustered near a regulatory threshold, 1-month window |
| 10 | Near-Threshold Statistics | Same pattern, 1-day window for faster detection |
| 11 | Near-Threshold Statistics | Same pattern, 5-day window |
| # | Base Pattern | Suggested Configuration |
|---|---|---|
| 1 | Dormant Activity | Dormant 100+ days, then activity above $5,000 |
| 2 | Historical Deviation — Trend | Last-3-months volume differing by more than 65% from the prior year, 1-month window |
| 3 | Historical Deviation — Period Delta | Deviation > 100% over the last 3 days vs. the prior 31 days |
| 4 | Layering | $10,000+ in deposits followed by a 90% withdrawal to a different beneficiary, 3-day window |
| 5 | Newly Seen | A newly seen sender instrument within the past 3 months |
| 6 | Simple Count — Relative | 10+ transactions over $1,000 to a same-surname receiver within 31 days, evaluated weekly |
| 7 | Simple Filters | ACH pulls onto debit rails where a fraud score sits in a defined mid-risk band, same-day hold |
| 8 | Simple Object Count — Transactions | A company's first-ever payroll run, evaluated near real time (10-min interval) |
| 9 | Simple Statistics with Count | Weekly check-deposit velocity |
| 10 | Structuring | Structuring within a 1-day period, evaluated every 2 hours |
| 11 | Near-Threshold Statistics | Transactions clustered near a regulatory threshold, 5-day window |
Imports watchlist and transaction data feeding screening and monitoring.
Runs scheduled bulk imports of core reference data — Customers, Accounts, and Transactions — keeping the rest of the platform populated with current records. Each file type runs as its own job on a shared schedule, and this screen is where you monitor completion, adjust timing, and dig into exactly what happened on any individual run. Recurring-job scheduling for batch processes across the platform, including Name Screening → Batch Screening, is configured from here — Batch Screening itself shows only the read-only history of past screening runs.
Start with the overview below. Across the top, the status bar always shows the current schedule in one line — useful for confirming what's actually configured without opening a settings screen. A job marked Inactive is paused rather than failing; Resume restarts it on that same schedule, and Change Schedule opens the schedule dialog.
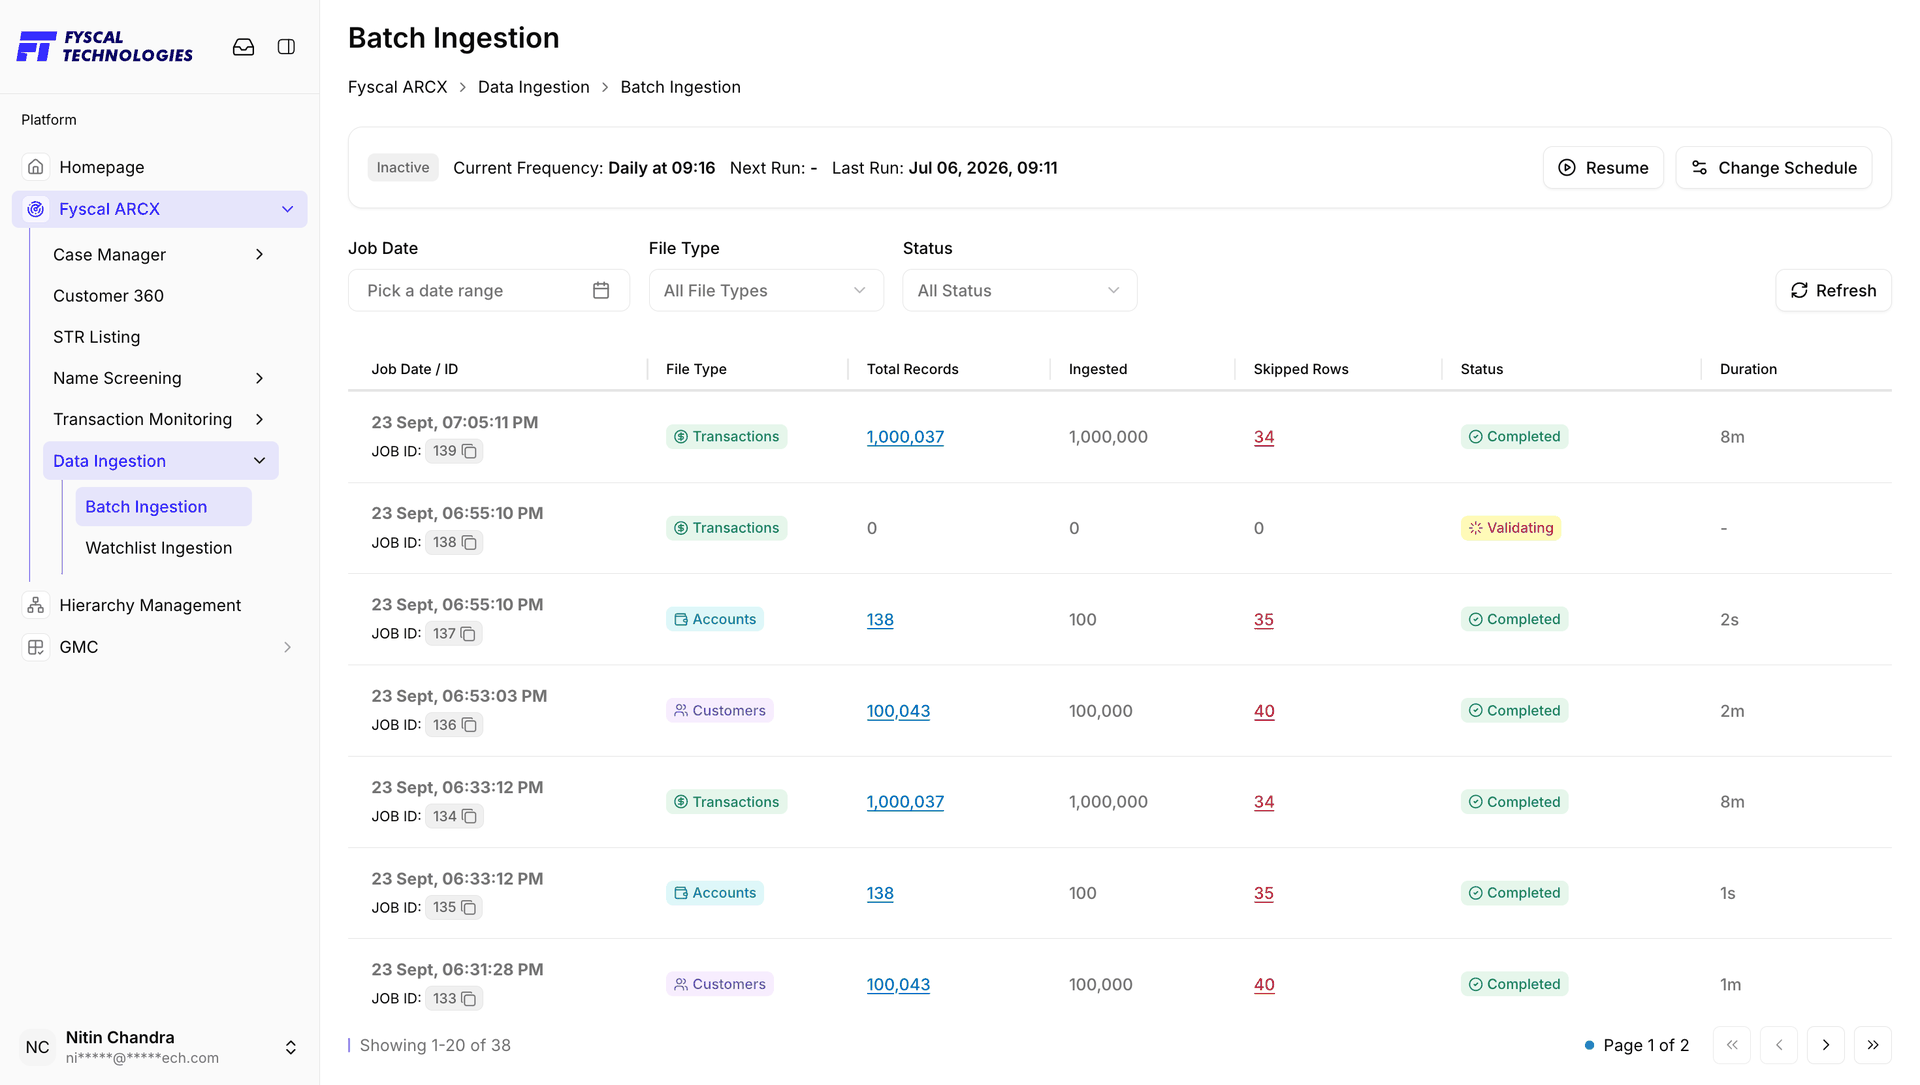
Click "Pick a date range" and a two-month calendar opens. Click a start day, then an end day, and the list filters down to jobs run inside that window.
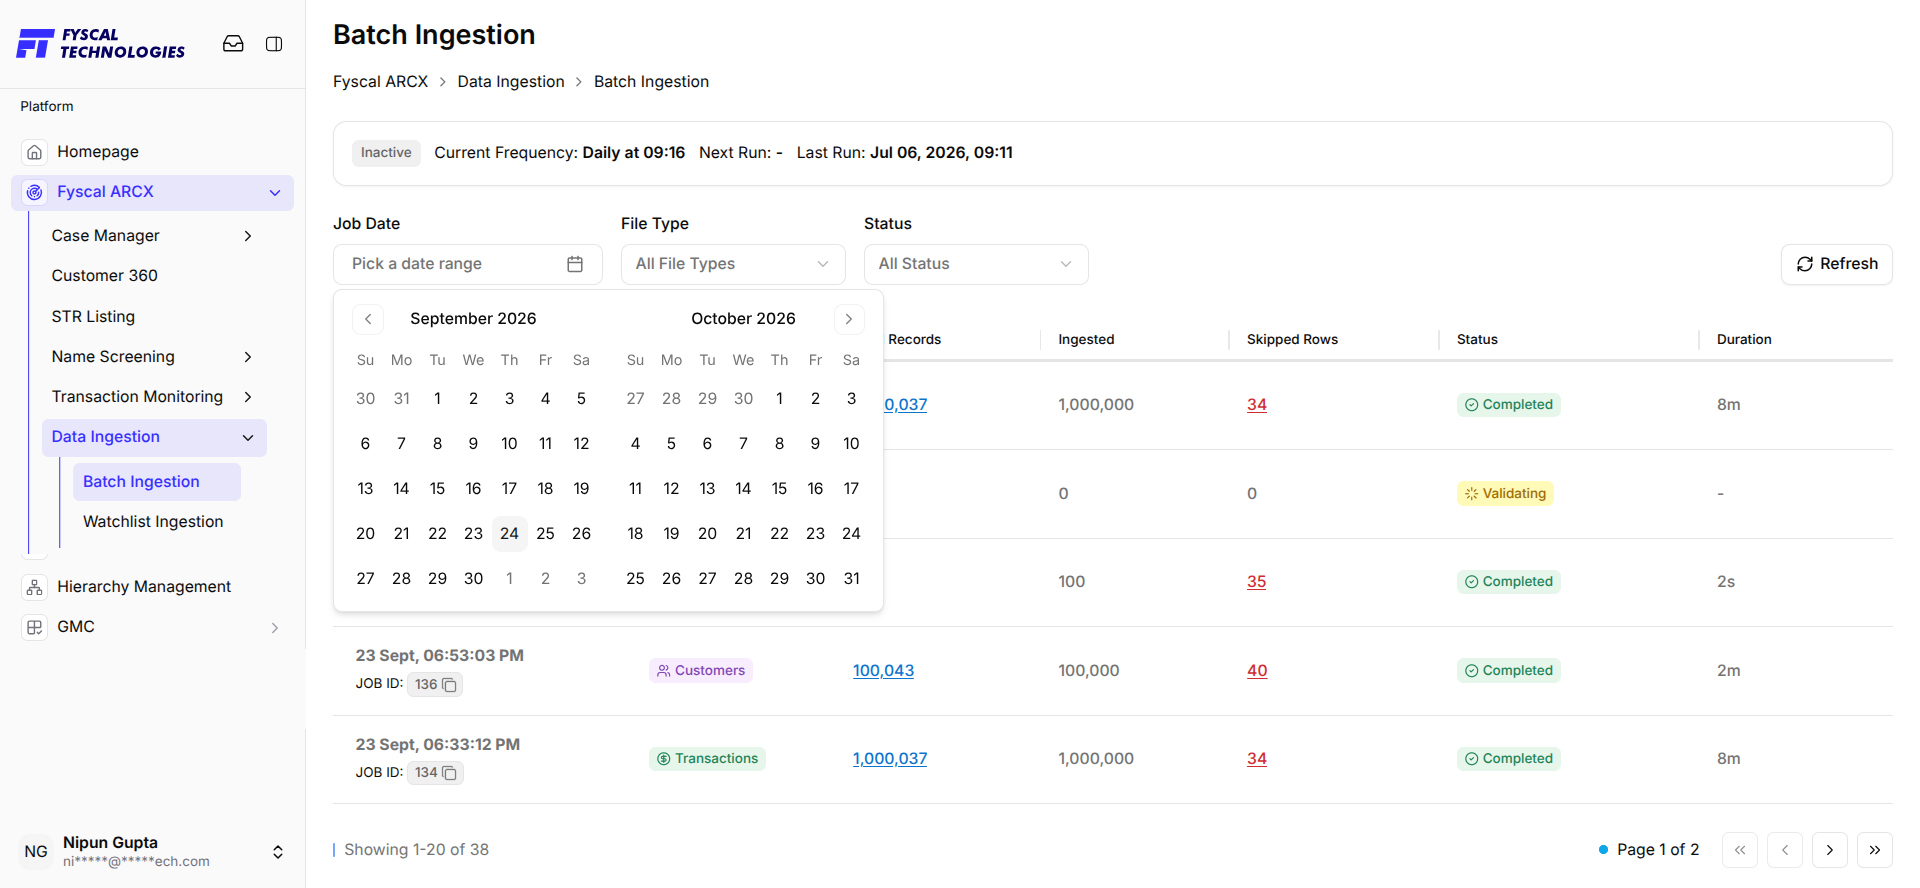
Looking for one dataset in particular? File Type narrows it down next.
Shows the three datasets Batch Ingestion handles — Customers, Accounts, and Transactions — each with the same icon used for that dataset throughout the job list.
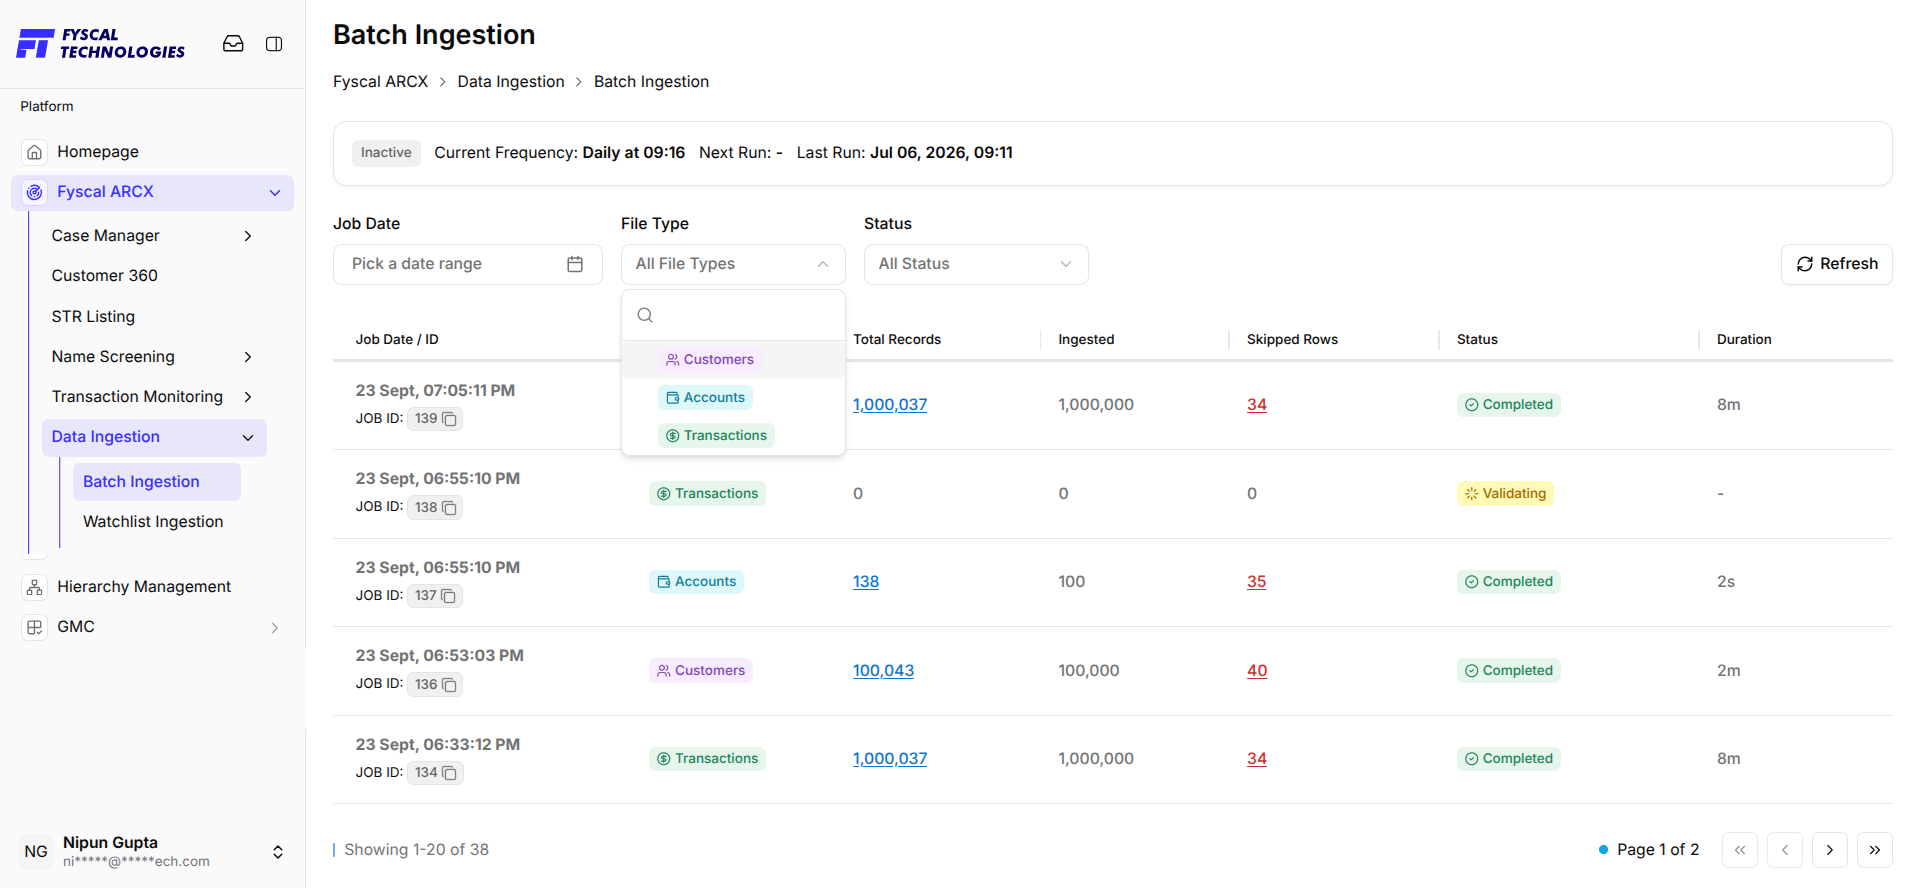
Only care about jobs in a particular lifecycle state? Status is the most detailed filter of the three.
Runs through every lifecycle state a job can be in, from queued (Init) and Validating through to a final state. No Valid Record and Partial Success sit alongside Completed and Failed, so a job that finished but skipped every row is easy to tell apart from one that failed outright, or one that's still mid-run (Ingesting).
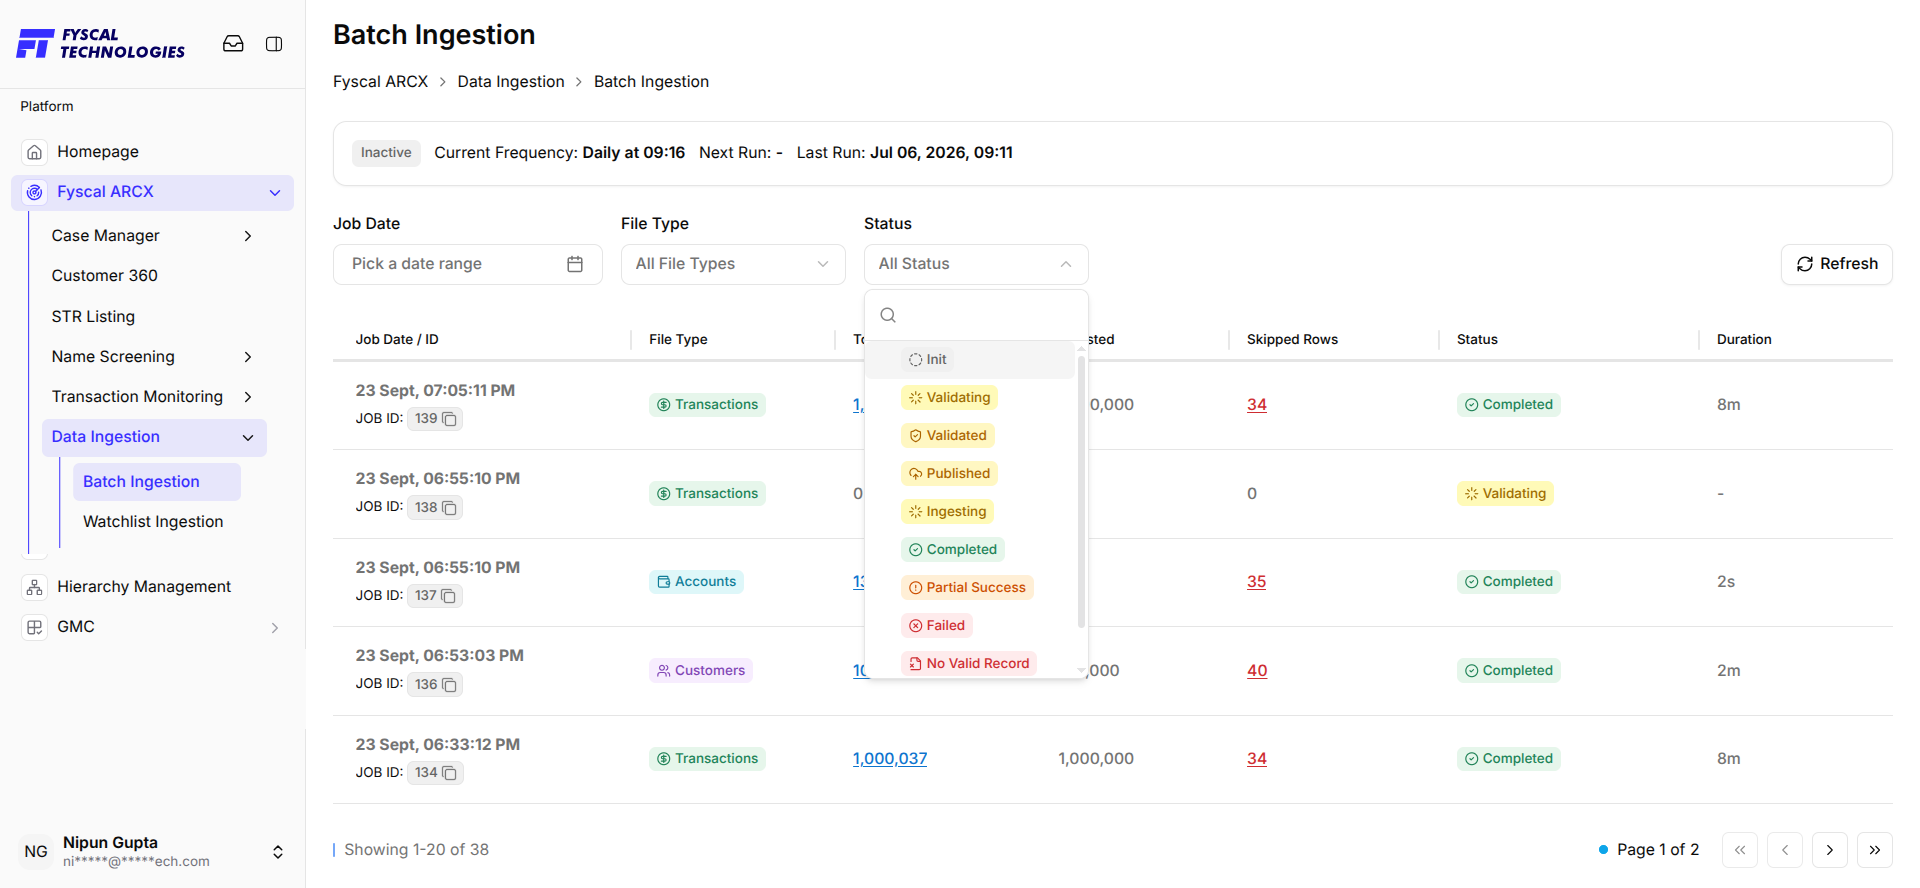
Filters covered — now for changing when the job itself runs.
Change Schedule opens the dialog below. It shows the current frequency and reminds you that any change — frequency, time, or timezone — takes effect after the next scheduled run. Set a New Frequency and up to 3 Runtimes per day (add or remove them as chips), and watch the Next Run Preview update live so you know exactly when the change will apply before you commit. Then click Review Changes.
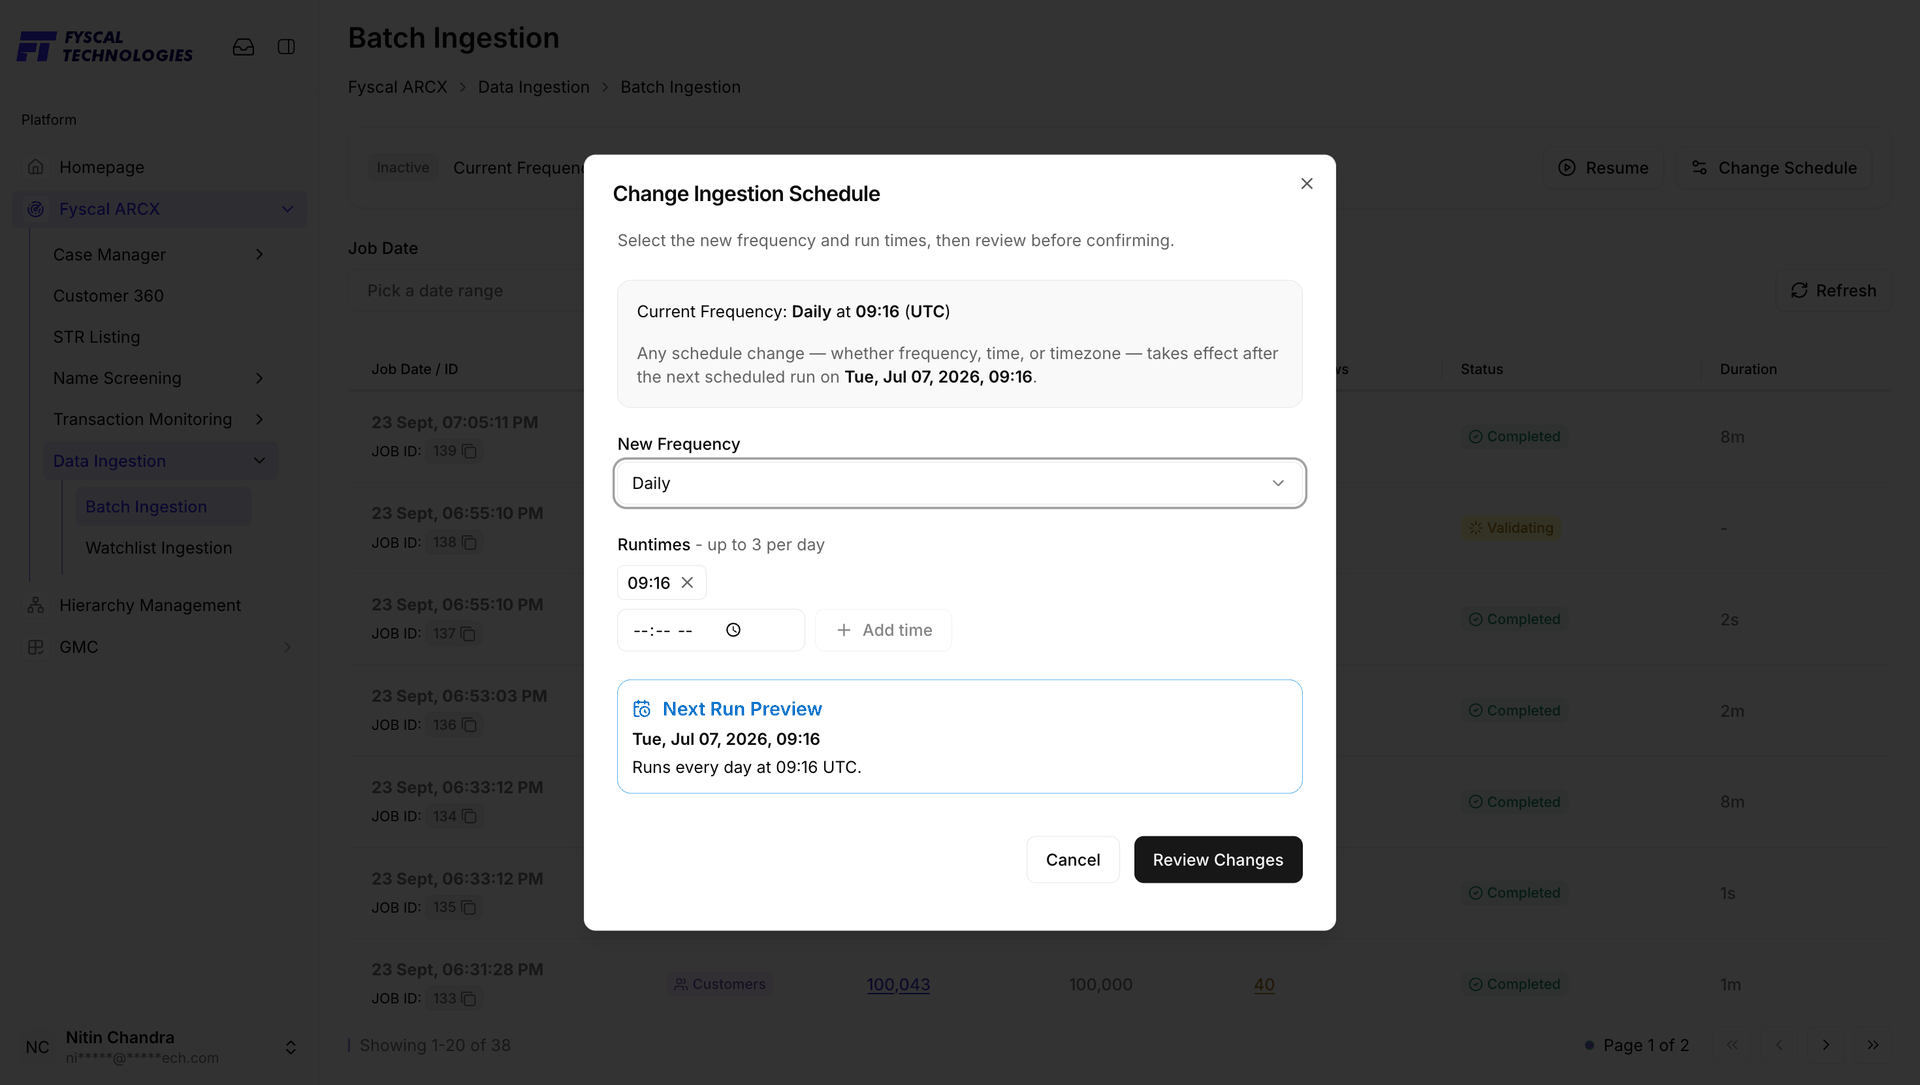
Review Changes moves to the plain-text summary below — the same change, laid out for a final check. Nothing here is editable; it exists purely so you confirm the new schedule before it's saved.
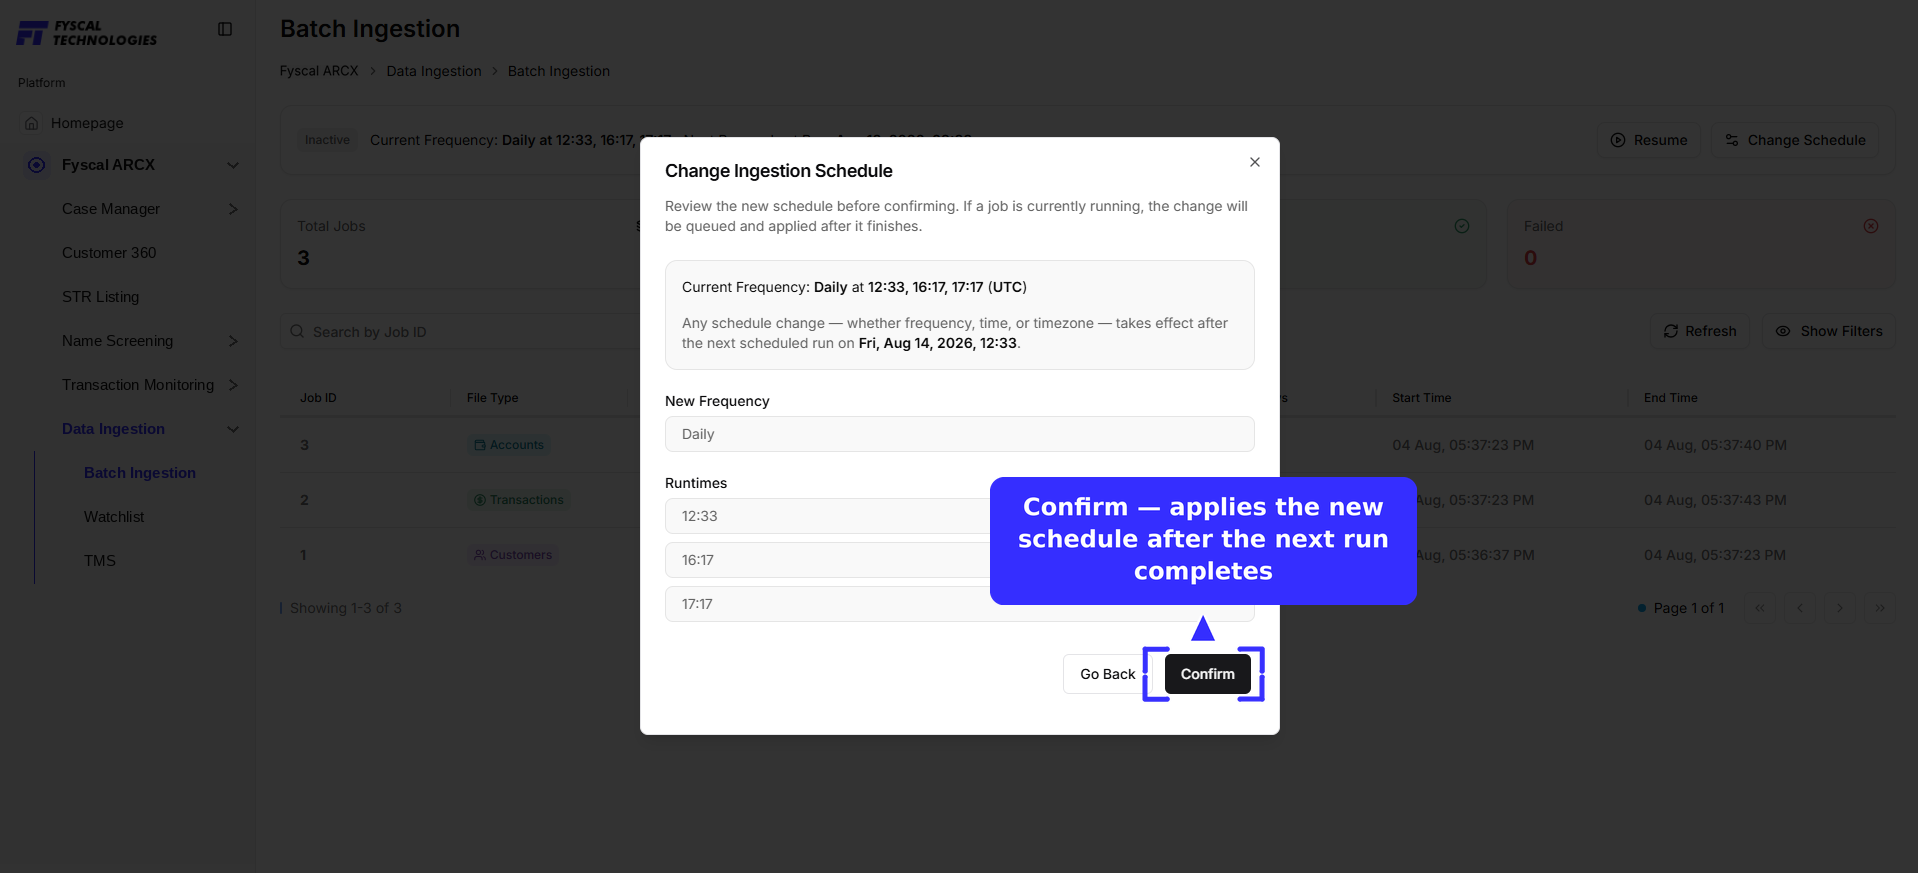
Clicking any completed row opens its Batch Ingestion Details: the Job ID with its status and file type, the Total Records, Ingested and Skipped Rows counts, the exact Started and Completed timestamps with Duration, and three file locations — Source File, Processed File, and Error File. The Error File is a folder path rather than a single downloadable CSV, since a run can produce more than one error file.
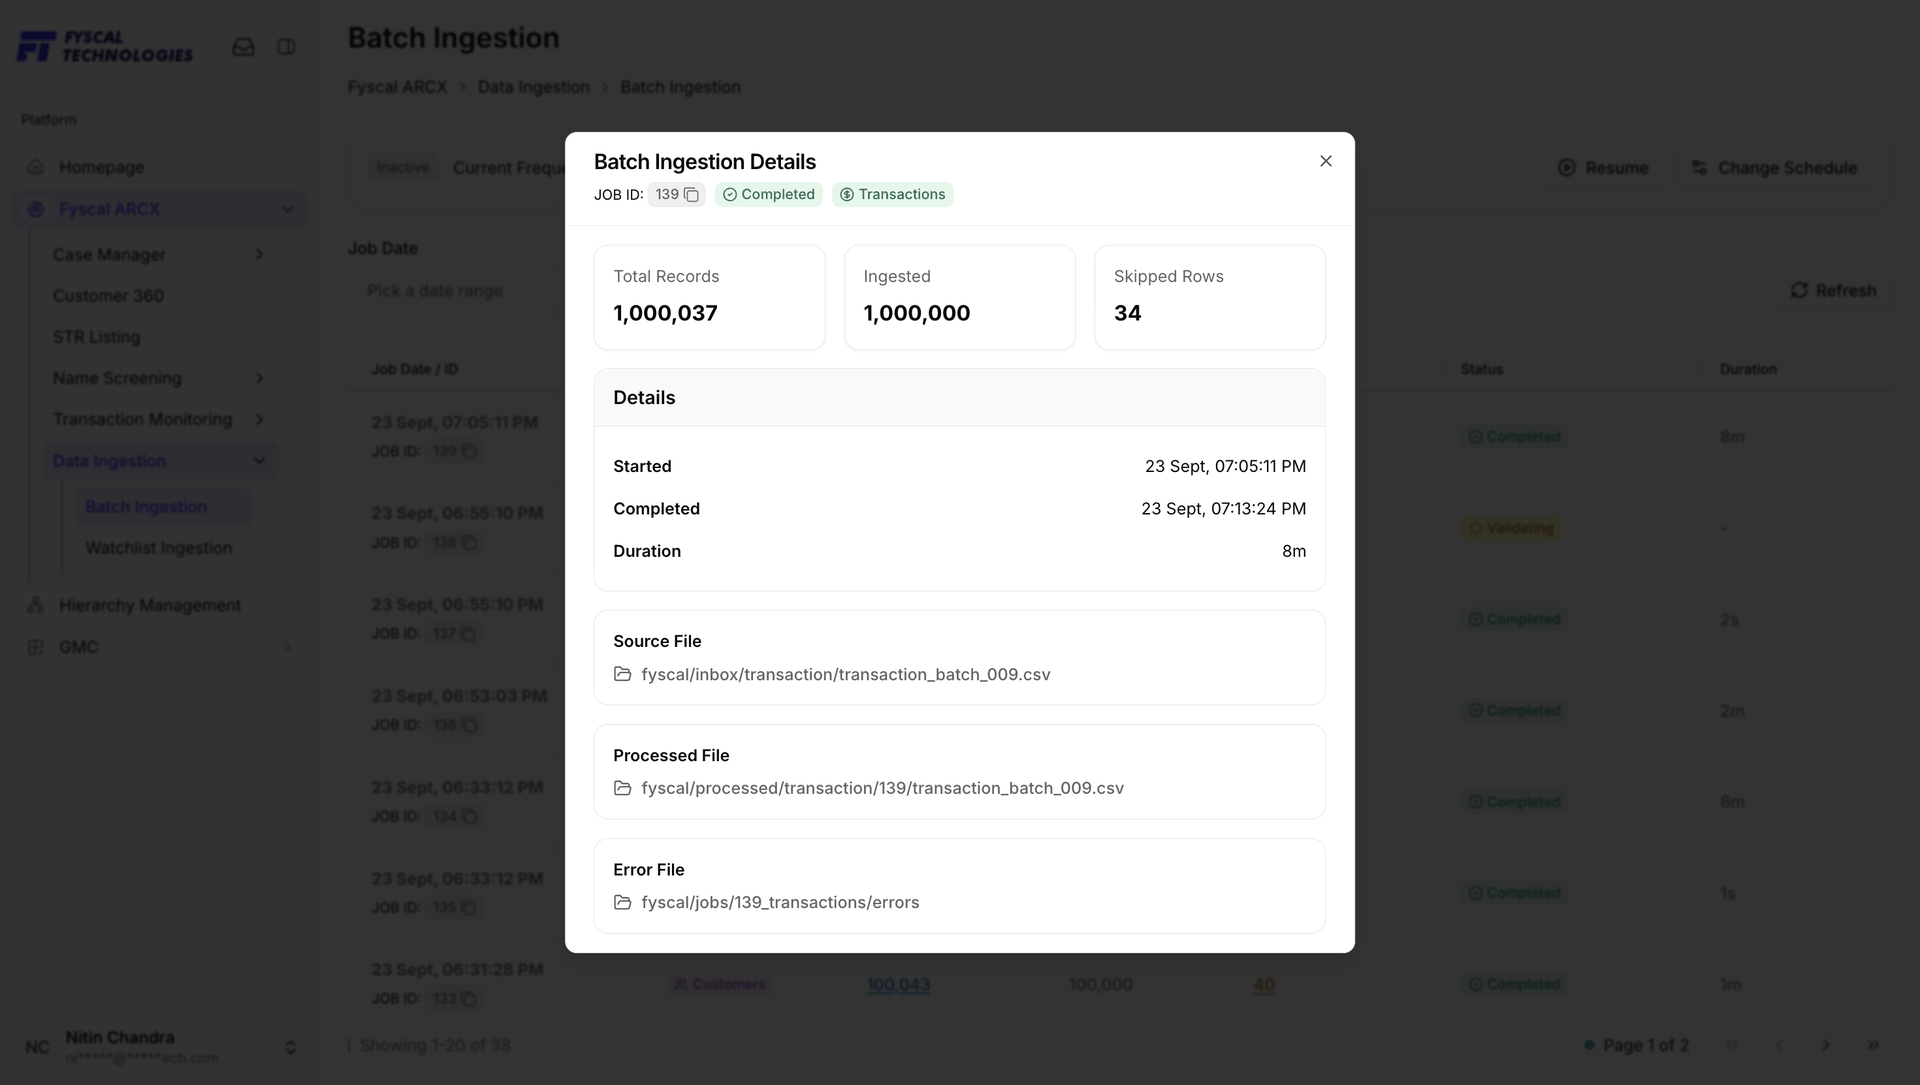
Provides a complete history of watchlist files ingested into the system, so users can monitor the status of each ingestion process, verify successful uploads, and review source, processing time, and records processed — helping ensure the latest watchlist data is available for customer screening.
File names tell you what kind of update was applied: delta files add or update watchlist records (the bulk of daily traffic — often thousands of rows), while deleted files remove records the provider has withdrawn. The provider files (source LSEG) arrive automatically on a schedule, and this screen is where you confirm each one actually completed rather than silently failing overnight. Files from the institution's own list appear with the source Internal Watchlist.
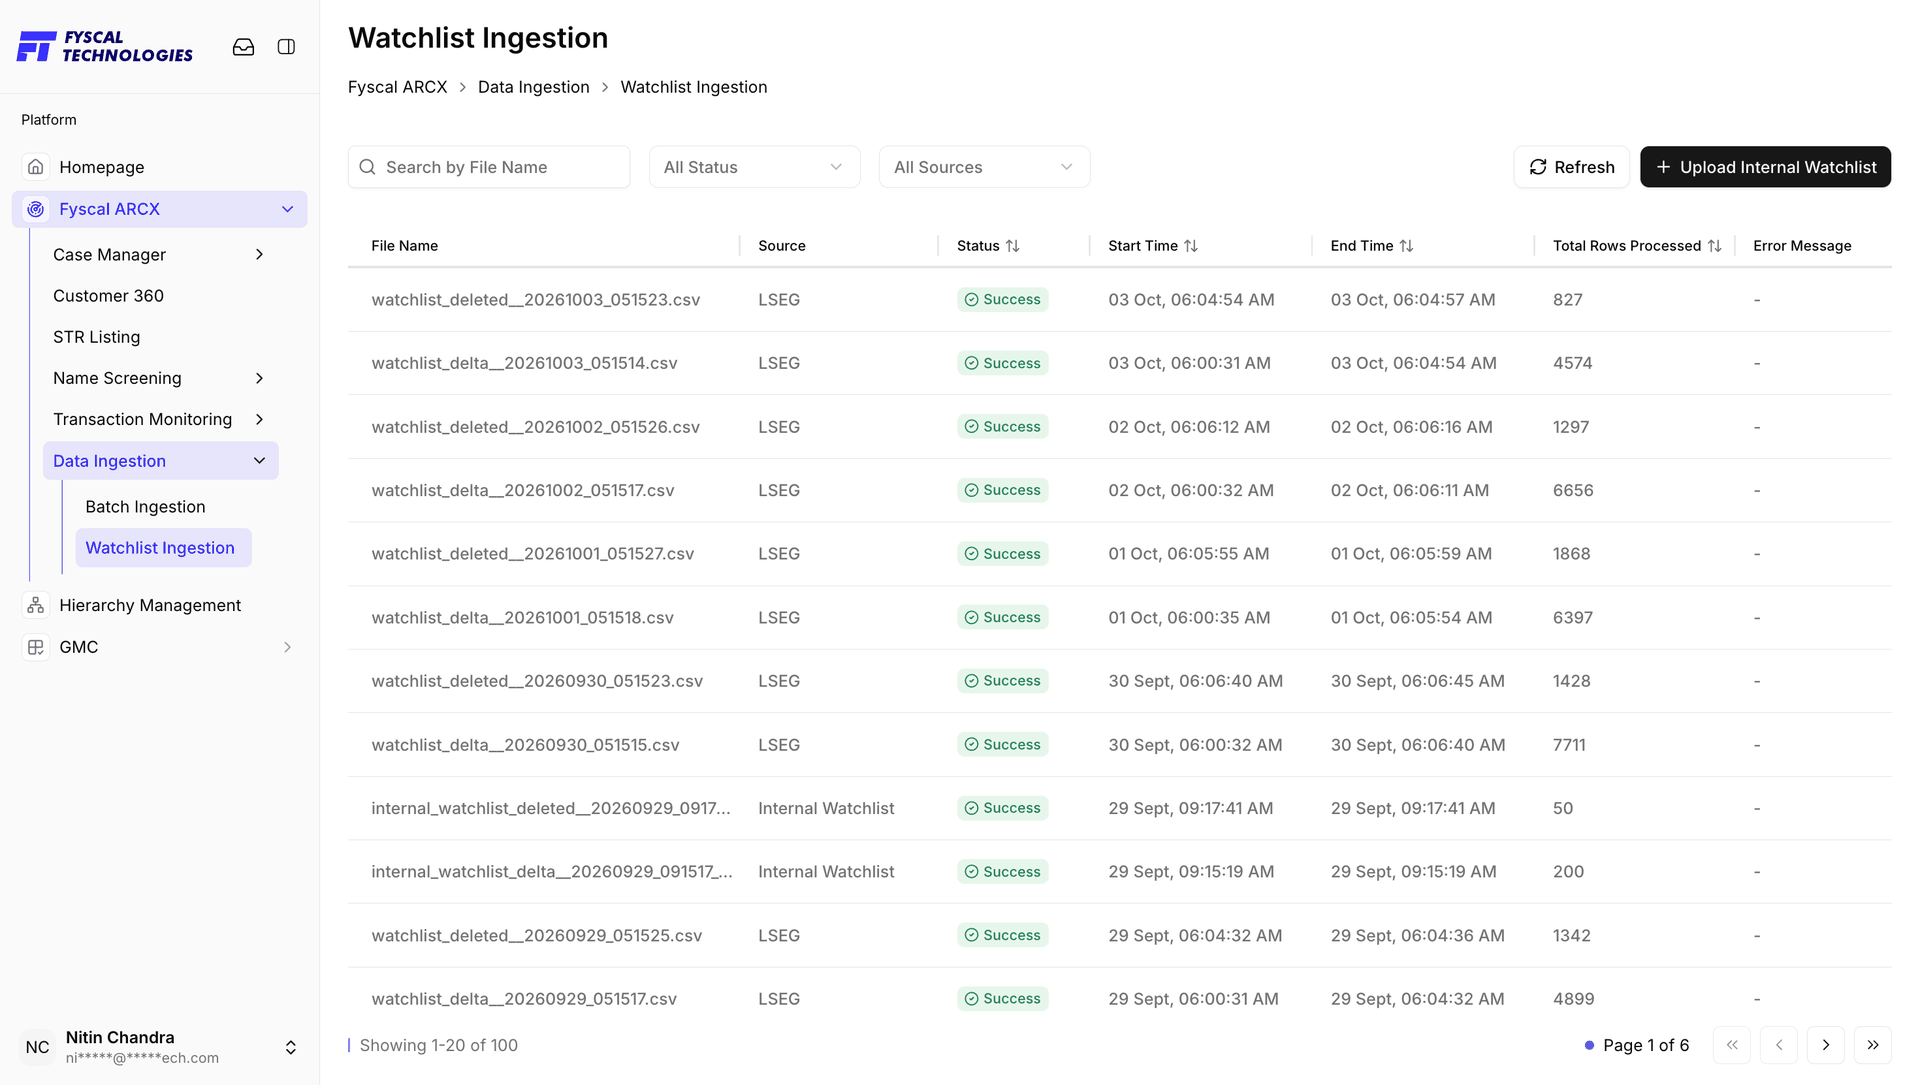
Upload Internal Watchlist lets you maintain the institution's own list (a Blacklist or Whitelist) without waiting for a provider file. Choose Add to Internal Watchlist or Delete from Internal Watchlist, then upload a CSV of customer records — each row needs a UID, entity details and a rationale. Download Sample gives a template to check your file against before uploading, and Upload & Add becomes available once a file is chosen. Only CSV files are supported.
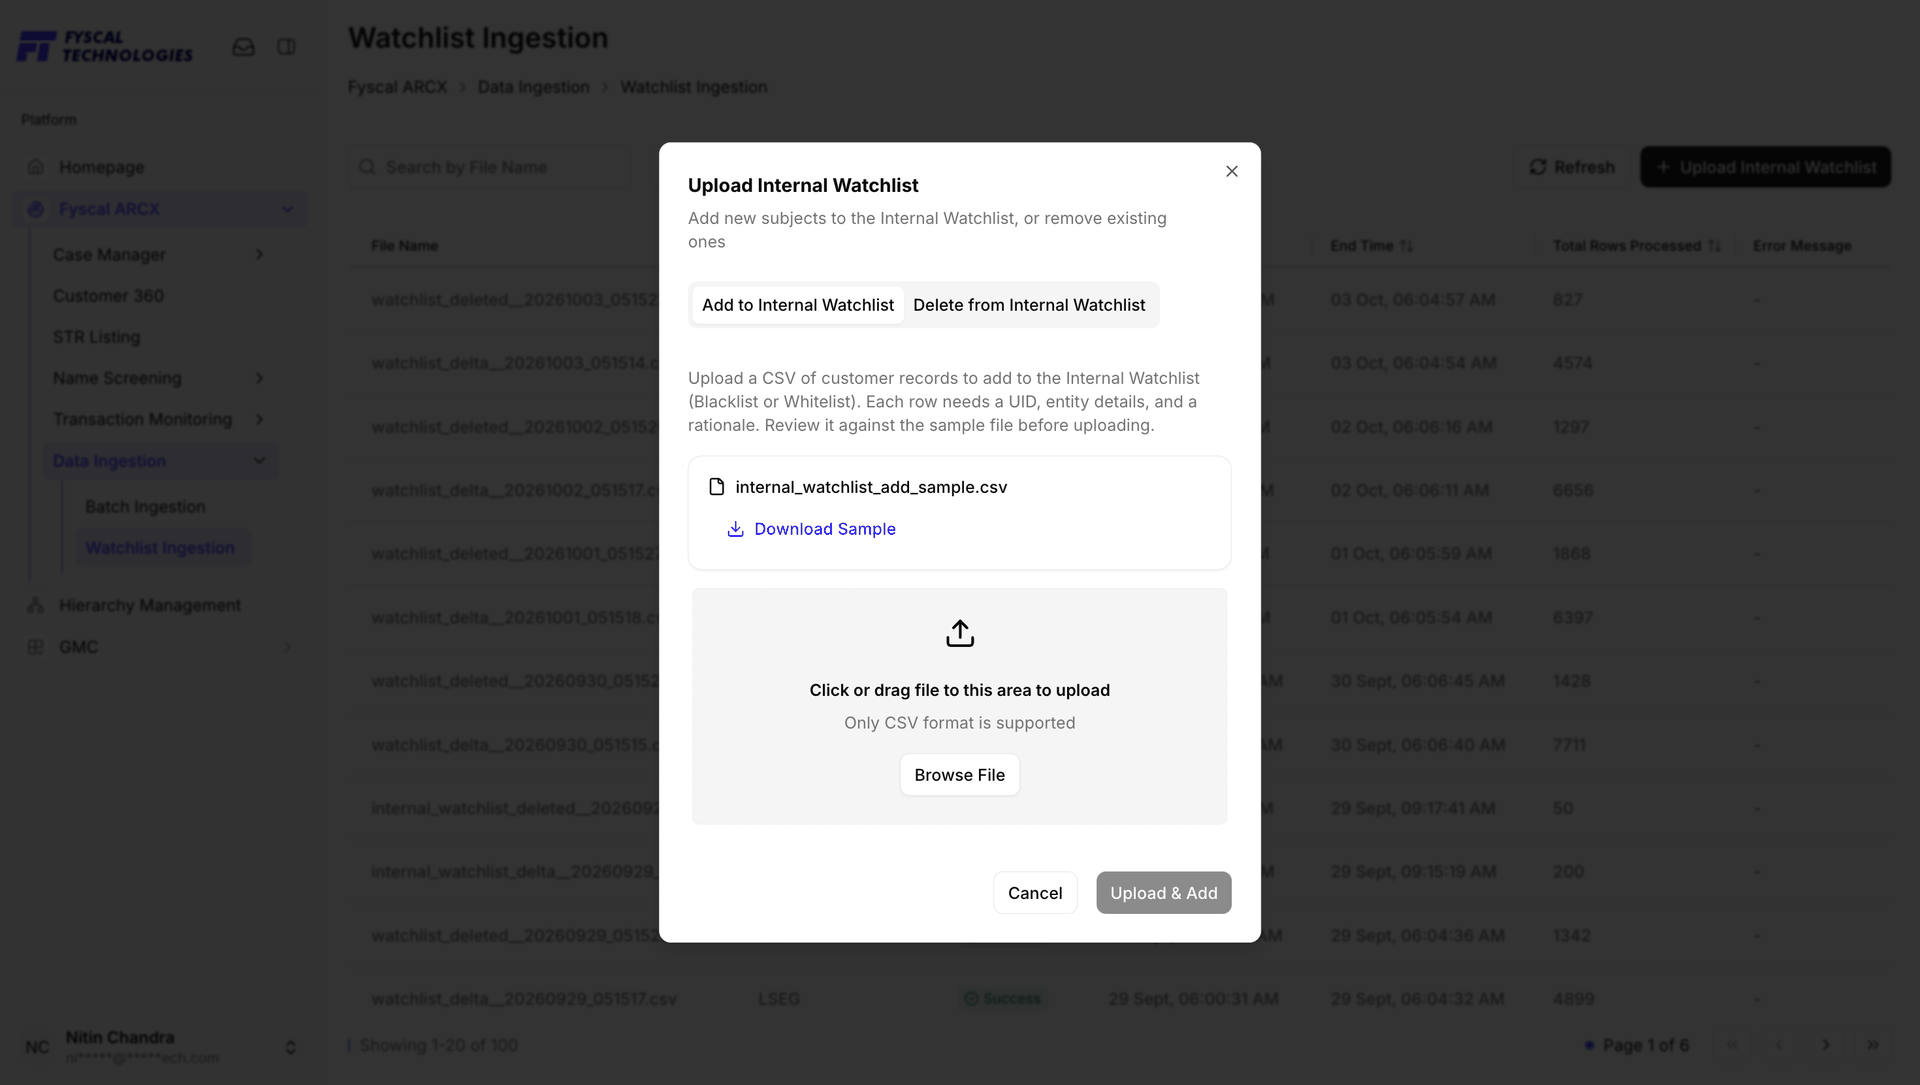
The platform-wide settings area — separate from the module-specific configuration screens covered elsewhere in this guide. Covers your own account, who can do what across the platform, and links out to the configuration screens elsewhere in this guide.
Controls who can see and do what across the platform, aligned to the roles introduced in Roles & Access:
Admin is also the hub that links out to every configuration screen covered elsewhere in this guide, rather than duplicating them:
Where the platform's hierarchy templates are listed and managed. A hierarchy template defines an organizational structure; this screen is where you find the existing templates, check their status, inspect one, and add a new one.
Hierarchy Management is its own item in the sidebar, alongside Fyscal ARCX and GMC. The list shows every template with its numeric ID, Name, who it was Created By, its Status, and when it was Created and last Updated. Status is Active, Inactive or Removed. Search by template ID or name, or open Show Filters; the table is paged (20 rows per page by default — 89 templates across 5 pages in this example), and each row has an Actions menu (⋮).
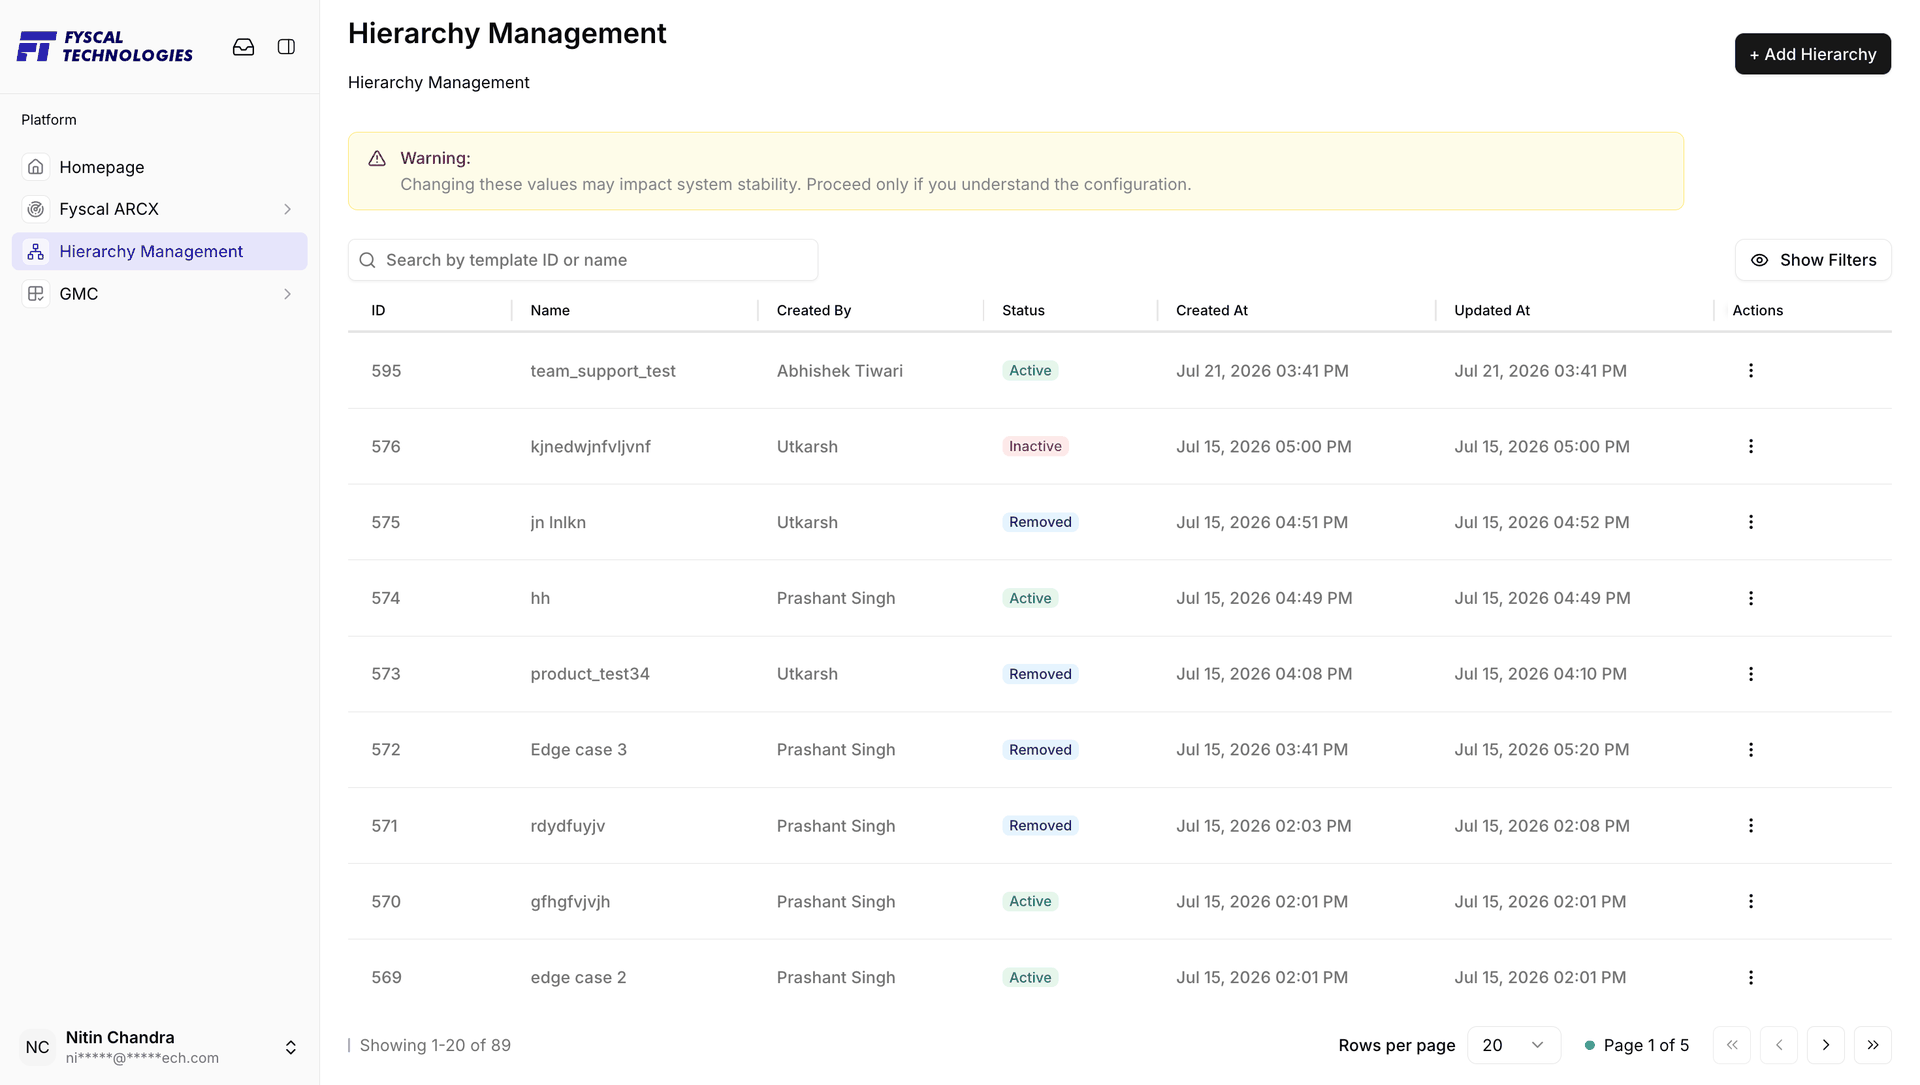
+ Add Hierarchy opens Add New Hierarchy Template. Enter a Name (required — e.g. "Sales Regional Hierarchy"), choose the Status (Active by default), and add an optional Description of what the template is for. Add stays disabled until a name is entered; Cancel closes the dialog without saving.
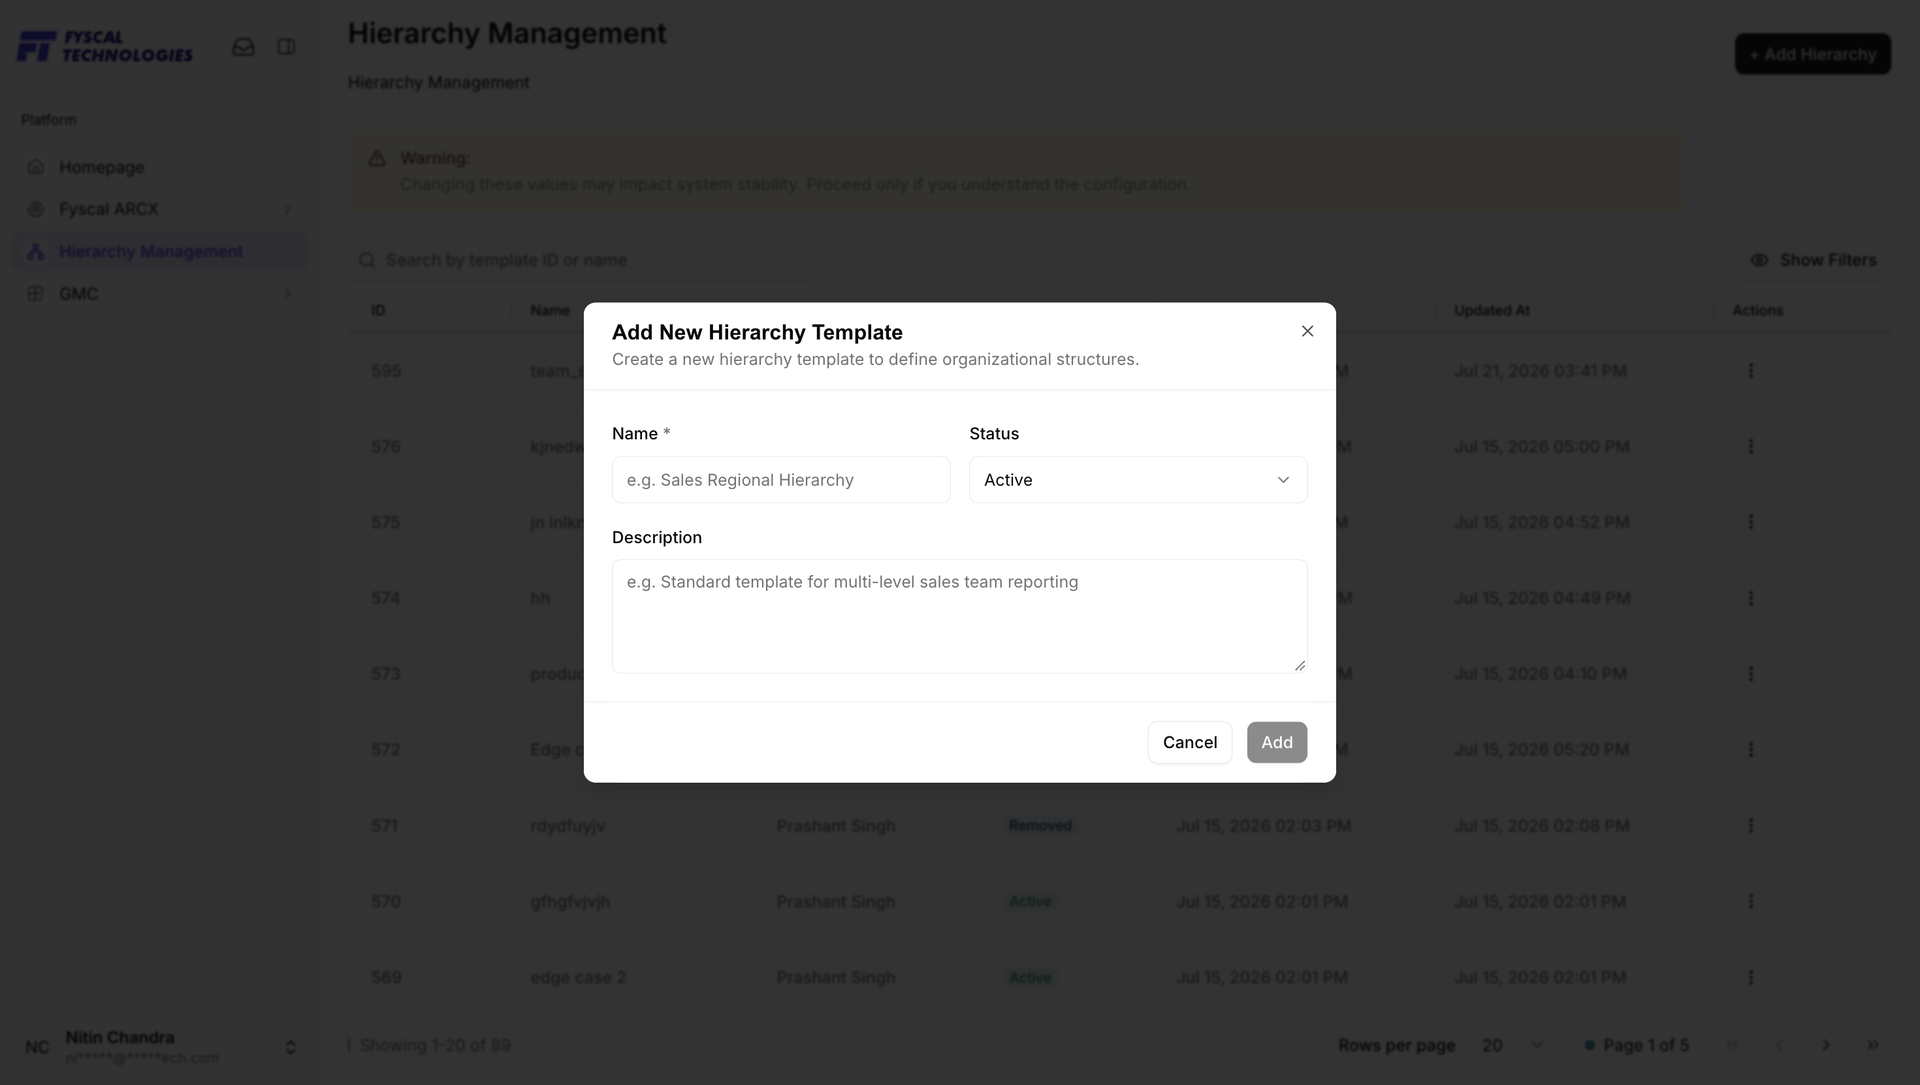
Choosing a template's view action from its Actions menu opens a read-only dialog listing its ID, User ID (the template's unique reference, in the form tmpl_…), Name, Description, Created By, Status, and the Created and Updated times. In the current build this dialog is titled View API Key.
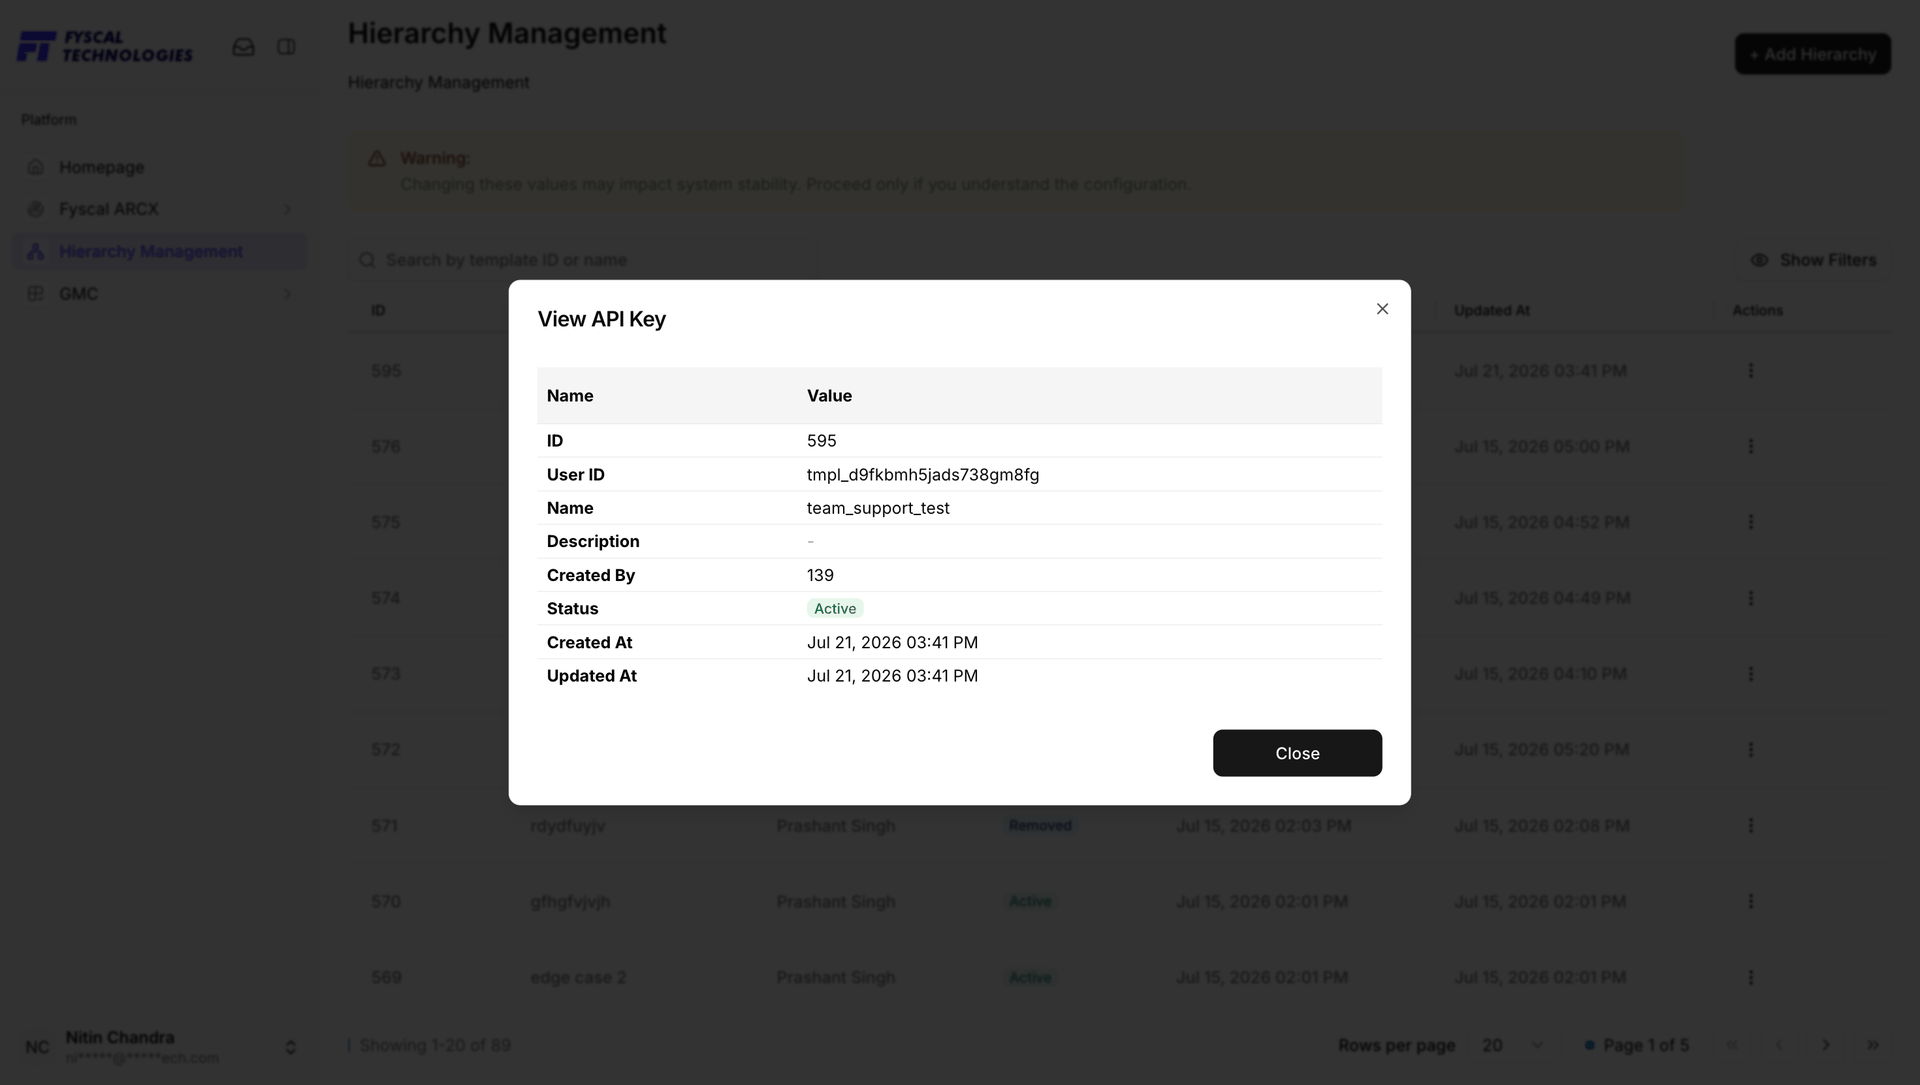
GMC holds the platform's activity configurations. Each activity names an action somewhere in the platform and sets the controls around it — how long it may take, when a warning is raised, how many approvals it needs, and which permissions allow someone to raise it (maker) and to approve it (checker).
GMC is its own item in the sidebar, alongside Fyscal ARCX and Hierarchy Management, and expands into Configs and Tickets. This page documents Configs.
The list shows each activity with its UID (a code beginning ACT_), its Name (for example "Create Account Constraint" or "Add Role"), its Section — the path of the part of the platform it belongs to, such as Fyscal ARCX/Name Screening…, Payments/Configs/… or Admin/Roles/… — the SLA (hrs), the Warning At (%) point, and its Status (Active or Inactive). Search by activity UID or name, or open Show Filters; the list is paged (51 activities across 3 pages in this example) and each row has an Actions menu (⋮).
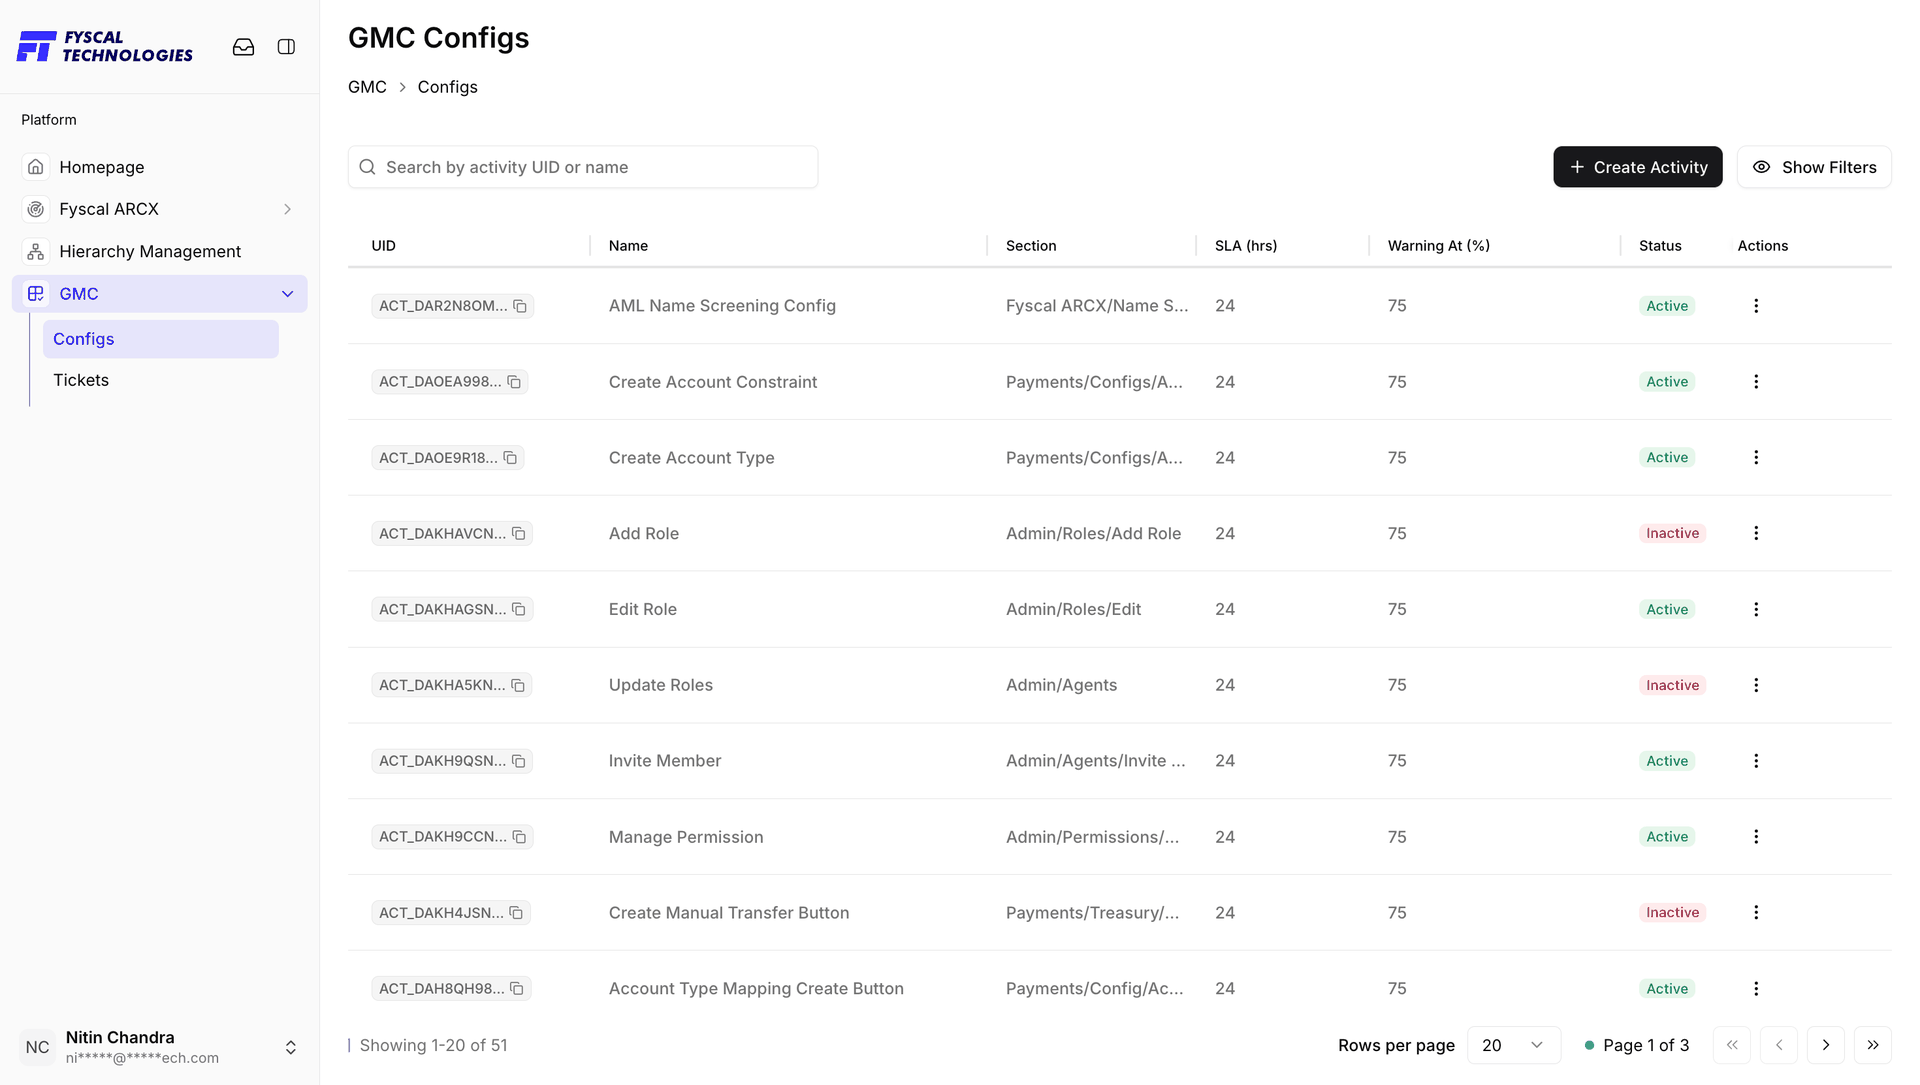
+ Create Activity opens a form in two parts. The first part names the activity and sets its timing:
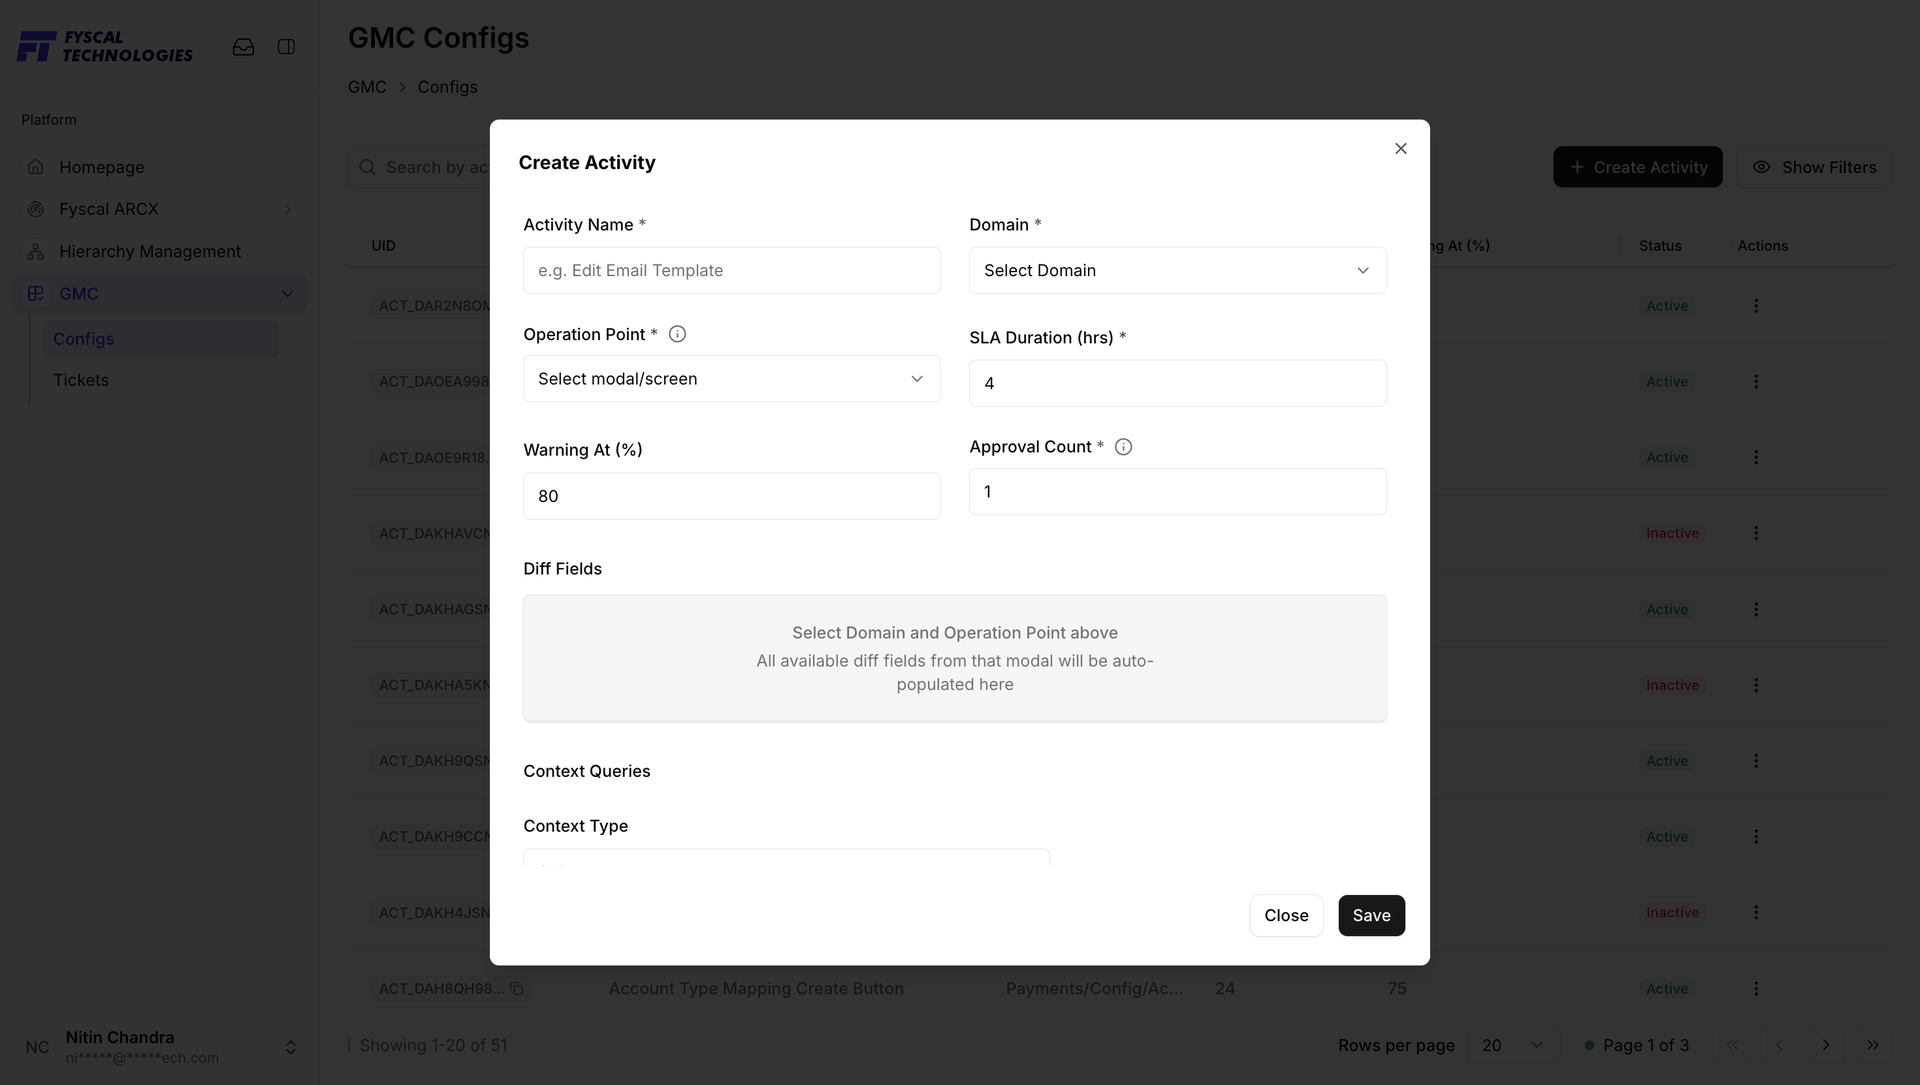
Scrolling down, the second part sets the context and the permissions: Context Queries (a Context Type, plus optional Pre-validation Hook and Abort Hook), and Assign Permissions, where a Maker Permission and a Checker 1 Permission are both required. Click Save to create the activity or Close to discard it.
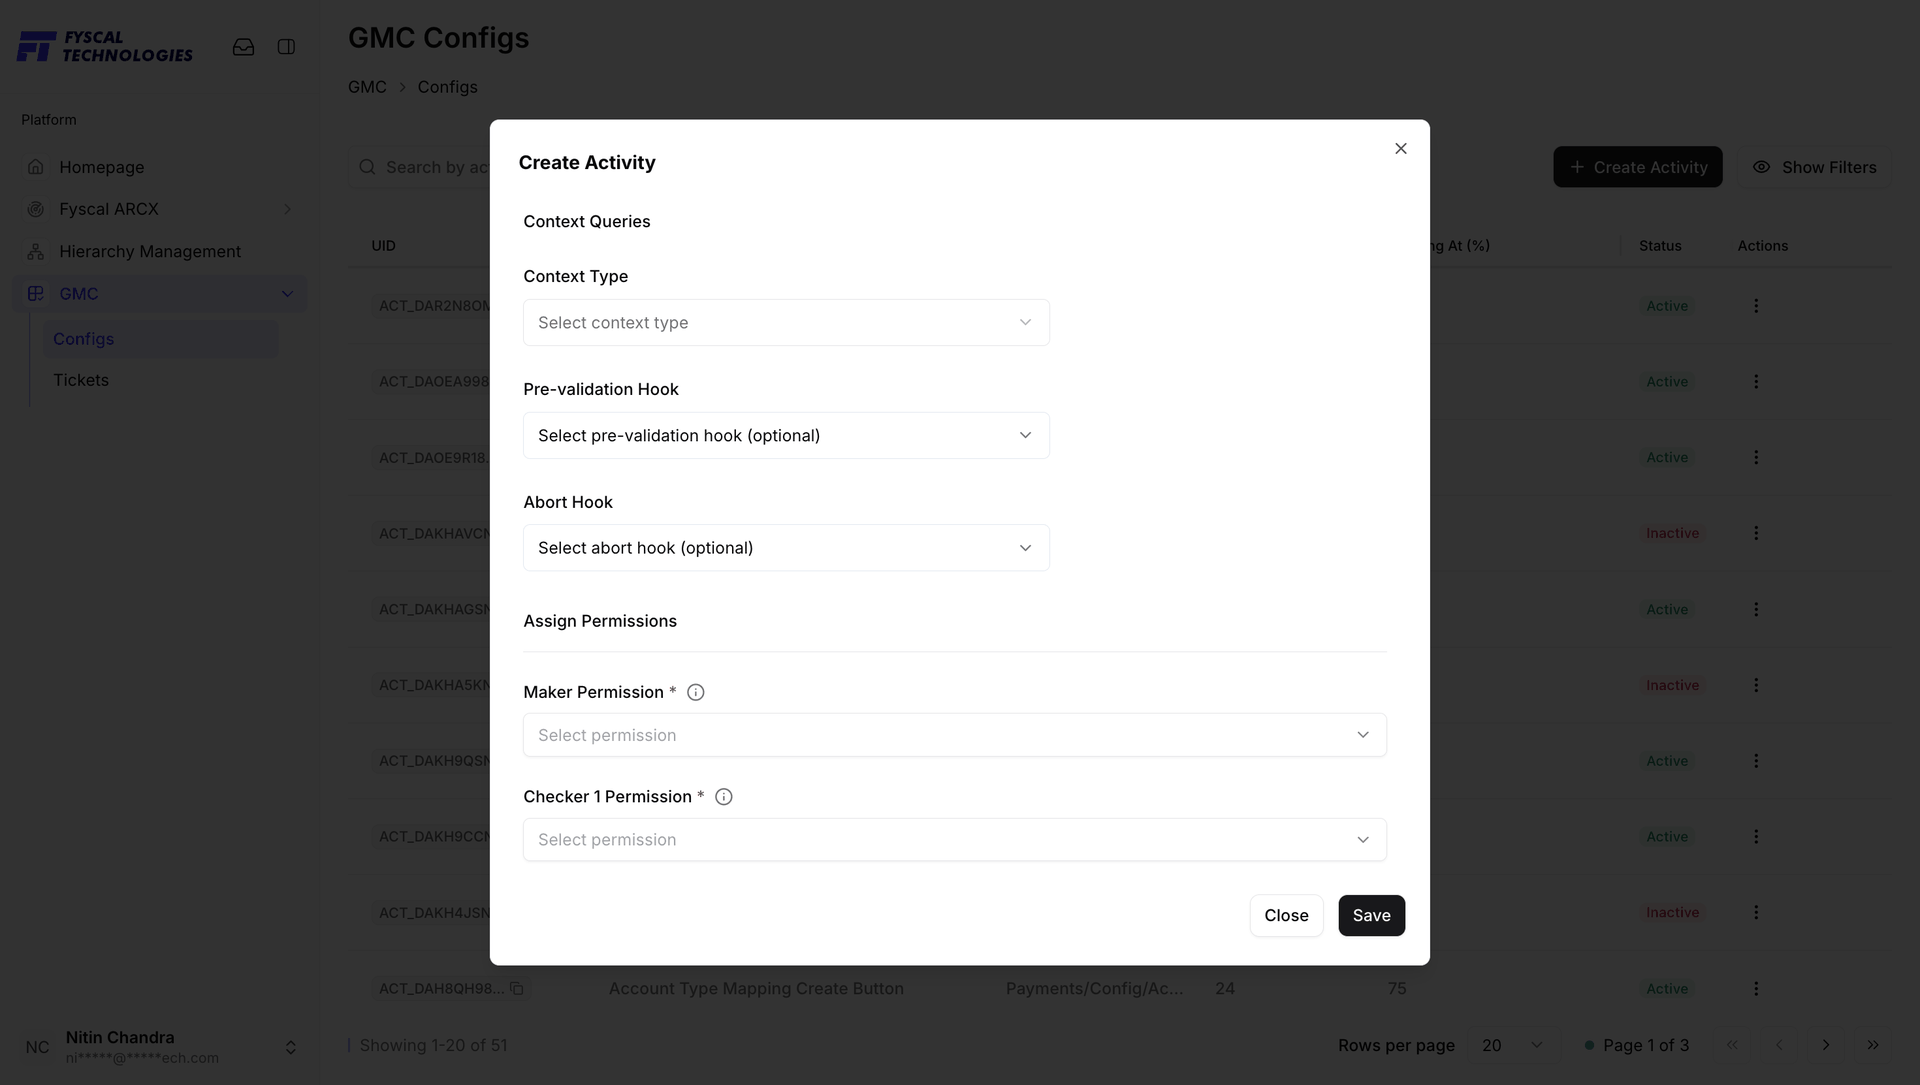
Everything that isn't specific to one module: answers to common questions, every AML and platform term defined once, and how to reach the support team when something needs a human.
Answers to the questions that come up most once teams are actually using the platform day to day, grouped by module.
What's the difference between an alert and a case?
An alert is the automated
signal Name Screening or Transaction Monitoring raises. A case is what that alert becomes once
it needs a human to actually look at it, document findings, and reach a disposition.
Who's allowed to close a case?
An analyst can close a case they own as a
False Match. Anything escalated as a True Match needs sign-off from a Compliance Officer or MLRO
before it's actually closed.
Can a case be reassigned partway through?
Yes — supervisors and officers can
reassign a case from the All Cases view, which is useful when someone's out or a queue needs
rebalancing.
Is everything done on a case actually logged?
Yes. Every status change, note,
and disposition is timestamped and attributed to the user who made it — that's the audit record
described in Case Lifecycle.
Why does an alert sit in the queue instead of becoming a case straight
away?
Not every alert warrants a full investigation — the Alerts queue is
the triage layer where an analyst does a quick first pass and either clears it, or escalates
it into a case.
Who can see alerts outside their own queue?
My Queue is scoped to the
logged-in analyst. Seeing everything — All Alerts, with the institution-wide stats bar — is
limited to Compliance Officers and supervisors.
What are alerts ranked upon?
Primarily the Score and the
SLA Deadline that follows from it. Every alert's match or risk score maps to a
severity band (Low, Medium, High, Very High) configured in Alert
Configuration, and each band carries its own SLA window — so a higher-scoring alert is
automatically given a tighter deadline than a lower-scoring one, regardless of which was
created first. Sorting the queue by SLA Deadline surfaces the alerts most at risk of breaching
their window first, which is the recommended way to work a busy queue.
Our alert volume feels too high — what actually helps?
That's usually a
configuration issue, not a triage issue — it means the severity bands or matching weightages in
Configuration need tightening, not that analysts need to work faster. Raise
it with a Configuration Admin.
What's the difference between a case and an STR?
The case is the internal
investigation file. The STR is the formal report that gets filed externally with the FIU once
that investigation confirms suspicious activity.
Who has to sign off before an STR is filed?
The MLRO, or another designated
Compliance Officer with filing authority — this is the "MLRO Approval" step in the Case
Lifecycle.
Can an STR be raised straight from an open case?
Yes — escalating a case
toward a filing is what creates its STR Listing entry; there's no separate form to fill in from
scratch.
What actually counts as a match if the spelling is slightly different?
That's
what Fuzzy matching is for — it's built to catch spelling variants and transliterations, not
just exact string matches. See Screening Configuration for how much weight
it carries in the score.
Can I screen a company as well as a person?
Yes — Entity Type on the Manual
Screening form supports both Individual and Organization.
If I mark a hit as a false positive, is that decision recorded anywhere?
Yes
— the disposition and the analyst's rationale are both logged against that screening record for
audit, the same as any other case disposition.
Who keeps the watchlists themselves up to date?
The data itself comes from
the provider (LSEG) via the scheduled ingestion jobs covered in Data
Ingestion — Configuration Admins manage the screening rules on top of it, not the
underlying list content.
Is there a way to test a new rule before it goes live?
Yes — that's exactly
what Dry Run is for: running the rule against historical data to see what it would have caught,
before it's published and starts generating real alerts.
Who's allowed to create or publish a rule?
Only users with Configuration
Admin permissions — it's kept separate from the analyst role deliberately, since a bad threshold
change affects every alert the rule generates afterward.
Does monitoring run in real time?
It runs on the rule's configured Execution
Interval — anywhere from near real-time to daily, depending on how the rule is set up — rather
than being instant for every rule by default.
What file formats does ingestion accept?
CSV, XML, and JSON are supported
natively, along with proprietary formats through custom connectors where needed.
What happens if a batch job partially fails?
Whatever rows did load
successfully are kept, and the failed rows are logged as errors for review — a partial failure
doesn't roll back the entire batch.
Who's responsible for data quality issues — us or the platform?
It's shared:
the source system owner is responsible for what's in the file, and the AML Platform Admin is
responsible for the mapping and validation rules that catch problems on the way in.
Terms used throughout this guide, in one place.
| Term | Definition |
|---|---|
| Case | The formal investigation record opened in Case Manager once an alert needs human review. |
| Delta Screening | A screening run that re-checks only the customers affected by a watchlist update, rather than the full customer base. |
| Dry Run | Running a transaction monitoring rule against historical data to see what it would have flagged, before publishing it live. |
| Escalation Path | The routing of an unresolved case or alert up to a supervisor. |
| False Match | A hit — on a screening match or a transaction rule — that turns out to be legitimate activity incorrectly flagged. |
| FIU (Financial Intelligence Unit) | The national agency that receives Suspicious Transaction Reports. |
| Fuzzy Matching | A name-matching technique that catches spelling variants and transliterations, not just exact matches. |
| Hierarchy | A named organizational structure, defined as a template in Hierarchy Management. |
| Ingestion Job | A single run of loading data — watchlist, transaction, or entity records — into the platform. |
| Maker-Checker | A dual-control process where one person prepares an action (e.g. a new rule) and a different person must approve it before it takes effect. |
| Mapping | The rules that define how fields in an incoming source file correspond to fields inside the platform. |
| MLRO (Money Laundering Reporting Officer) | The individual with the authority to approve and file an STR. |
| PEP (Politically Exposed Person) | Someone who holds — or is closely linked to someone who holds — a prominent public position, and therefore carries elevated AML risk. |
| Rule Engine | The configurable system behind Transaction Monitoring that evaluates transactions against variables and typologies. |
| Severity | The risk band assigned to an alert (Low, Medium, High, Very High), which drives its SLA deadline. |
| SLA (Service Level Agreement) | The maximum time allowed to action an alert or case before it's considered overdue. |
| Smurfing | Using multiple individuals to conduct several small transactions on behalf of one person or organization, keeping each transaction under reporting thresholds to avoid detection. |
| STR (Suspicious Transaction Report) | The formal report filed with the FIU once a case confirms suspicious activity. |
| Structuring | Deliberately breaking a single large transaction into multiple smaller ones to stay under a reporting threshold and avoid triggering mandatory reporting. |
| Triage | The first, quick review of a new alert to decide whether it needs to be escalated into a full case. |
| Typology | A named, predefined pattern of suspicious transaction behaviour — e.g. Structuring or Smurfing — that a monitoring rule is built to detect. |
| Validation | The checks applied during ingestion to confirm incoming data meets the platform's technical and business requirements. |
| Watchlist | The database of sanctioned, PEP, or otherwise high-risk individuals and entities that screening checks customers against. |
| Issue | Solution |
|---|---|
| Login failed | Verify credentials, or use Forgot Password |
| Ingestion job stuck in Processing | Check source feed, click Refresh, escalate to IT/Platform Admin |
| Screening returns no matches | Confirm watchlist ingestion completed successfully |
| Unexpected spike in alerts | Review recent weightage or rule threshold changes |
| Rule not triggering as expected | Run a Dry Run to validate conditions against historical data |
Tell us a little about what you're working on and the team will route you to the right person — typically within one business day.
Thank you for using Fyscal ARCX.
Version history for the Fyscal ARCX platform, newest first. For what each module actually does, see its own page in this guide.
A full reference catalogue for Transaction Monitoring rule-building — every detection pattern (Anomaly Detection, Structuring, Cardinality, Denylist, Graph-Based), pre-built Fraud/ACH/Check templates, and recommended Typology packs for Banking, Neobanking, Crypto, P2P, Brokerage, Lending, and General use cases. See Typology Library.
Transaction Monitoring Rules gets a new Schedules screen — named, reusable run schedules that attach to a rule (Live in) or a draft. AI Manager adds Case Copilot, a shared persona prompt, plus Expected Response — structured output fields, including enums, that every prompt can now define. See Schedules.
Agent Configuration and Prompt Configuration are now unified as two tabs — Prompt Config and Model Config — under a single AI Manager page, renamed from AI Agent Manager. Model Config adds a Temperature setting and full version history with one-click Restore; Prompt Config now tracks a revision count on every prompt. See Agentic Workflows.
Registers the AI model identity and the Role/Task/Description prompts behind AI Agent Manager's drafting, as two new configuration screens. See Agentic Workflows.
A full profile for every customer — KYC detail, linked accounts, and five activity tabs covering analytics, transactions, prior cases, screening, and STR history. See Customer 360.
Scheduled bulk imports for Customers, Accounts, and Transactions, with adjustable run schedules and a downloadable error report per job. See Data Ingestion.
Automated first-pass drafting for alerts and cases, so analyst review time goes toward judgement, not data-gathering. See Agentic Workflows.
Weightages for Name, Address, Citizenship, Gender, and Date of Birth are now easier to review at a glance. See Name Screening.
SLA Breached counts in Admin View now reconcile correctly with individual alert deadlines. See Alerts.
major.minor.patch: major releases introduce a new module, minor releases add capability to an existing module, and patch releases are fixes with no visible change to how a module works.